
rilldata/rill
rilldata/rill has 2,993 GitHub stars and 206 forks. GitHot measured +2 stars in 24 hours and +12 in 7 days. Last checked 2026-11-11 07:39 UTC. Last push 2026-11-02.
The fastest business intelligence tool for humans and agents.
측정된 스타 증가
- in 24h
- +2
- in 7 days
- +12
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original

Agent-first, human-friendly business intelligence


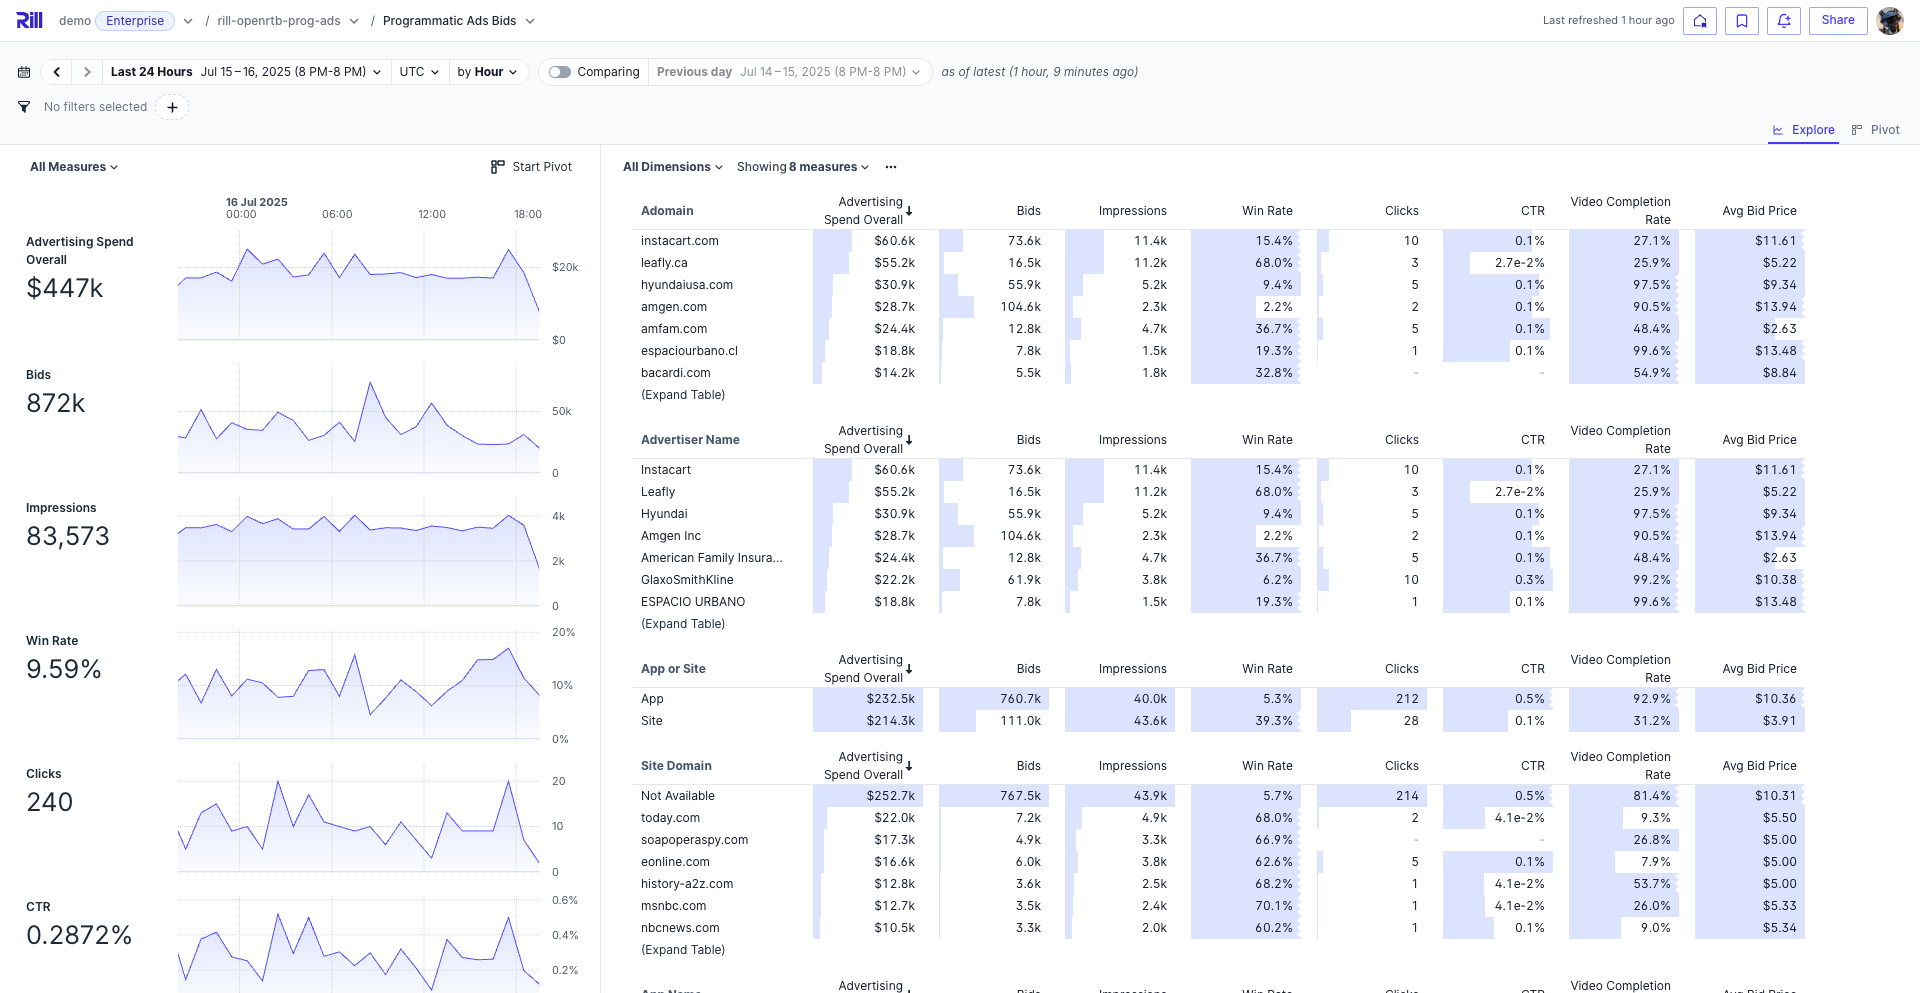
Rill is the fastest BI tool for humans and agents, powered by OLAP engines like ClickHouse and DuckDB.
Get Started
curl https://rill.sh | sh        # install
rill start my-project            # create a project and open the UI
Scaffold a project with agent context
Use rill init to scaffold a project interactively:
➜ rill init
? Project name my-rill-project
? OLAP engine duckdb
? Agent instructions claude

Created a new Rill project at ~/my-rill-project
Added Claude instructions in .claude and .mcp.json

Success! Run the following command to start the project:

  rill start my-rill-project
Why Rill?
- Build with agents — BI-as-code (YAML + SQL) means coding agents like Claude Code and Cursor can author projects, dashboards, and security policies end-to-end
- Semantic layer — Single source of truth for dimensions, measures, and time grains — defined in YAML, generating SQL at query time against your OLAP engine
- Explore with agents — Conversational BI lets business users query metrics in natural language; the MCP server connects AI agents directly to your semantic layer
- Real-time performance — Sub-second queries at any scale; ClickHouse for billions of rows, DuckDB for smaller datasets and fast iteration
- Embeddable — Dashboards, APIs, and agent interfaces you can ship in your product
Capabilities
Rill Developer (local)
- Connectors — S3, GCS, databases, and 20+ sources
- OLAP Engines — Managed ClickHouse or DuckDB included, or connect an external engine (ClickHouse Cloud, Druid, Pinot, MotherDuck)
- SQL Models — Transform raw data with SQL, join models together
- Data Profiling — Instant column stats and distributions
- Incremental Ingestion — Load only new data on each run to keep large datasets current without full refreshes
- Semantic Layer — Dimensions, measures, and time grains in YAML
- Row Access Policies — Per-user, per-group data access control
- Local Dashboards — Preview and explore dashboards locally
Rill Cloud
- Deploy — Git-backed, versioned deployments — push with
rill deployor connect a repo for automatic CI/CD - Explore & Canvas Dashboards — Interactive dashboards, embeddable in your product
- Conversational BI — Ask questions in natural language
- MCP Server — Connect Claude, ChatGPT, or any AI agent to your metrics
- Custom APIs & Embedding — Expose metrics via REST or embed dashboards
- Alerts & Reports — Threshold alerting, code-defined or UI-defined
How It Works
Define everything in code — models, metrics, dashboards — and Rill handles the rest.
1. Connect data — models/events.yaml
type: model
connector: duckdb
materialize: true

sql: |
  select * from read_parquet('gs://rilldata-public/auction_data.parquet')
2. Define metrics — metrics/events_metrics.yaml
version: 1
type: metrics_view
model: events
timeseries: timestamp

dimensions:
  - name: country
    column: country
  - name: device
    column: device_type

measures:
  - name: total_events
    expression: count(*)
  - name: revenue
    expression: sum(price * quantity)
    description: Total revenue
3. Create a dashboard — dashboards/events_explore.yaml
type: explore

display_name: "Events Dashboard"
metrics_view: events_metrics

dimensions: "*"
measures: "*"
4. Deploy
rill deploy # push to Rill Cloud
Your metrics view is immediately queryable on Rill Cloud — add YAML files to configure dashboards, alerts, and custom APIs.
Learn More
Getting Started with Rill Developer • Exploring Data with Rill • Data Talks on the Rocks • Agentic Analytics with Claude Code and Rill
Examples
| Example | Description | Links |
|---|---|---|
| Programmatic Ads | Bidstream data for pricing and campaign performance | GitHub · Demo |
| Cost Monitoring | Cloud infra merged with customer data | GitHub · Demo |
| GitHub Analytics | Contributor activity and commit patterns | GitHub · Demo |
Or explore a live embedded dashboard.
Community

Contributing
We welcome contributions! See our Contributing Guide to get started.
관련 프로젝트 살펴보기
Asabeneh/30-Days-Of-Python
30 Days of Python 프로그래밍 챌린지는 Python 프로그래밍 언어를 30일 동안 배우기 위한 단계별 가이드입니다. 이 챌린지는 100일 이상 걸릴 수 있습니다. 자신의 속도에 맞춰 진행하세요. 다음 동영상도 도움이 될 수 있습니다: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 스타grafana/grafana
개방적이고 조합 가능한 옵저버빌리티 및 데이터 시각화 플랫폼입니다. Prometheus, Loki, Elasticsearch, InfluxDB, Postgres 등 여러 소스의 메트릭, 로그, 트레이스를 시각화합니다.
77,830 스타redis/redis
실시간 데이터 기반 애플리케이션을 구축하는 개발자에게 Redis는 가장 선호되고, 가장 빠르며, 기능이 가장 풍부한 캐시, 데이터 구조 서버이자 문서 및 벡터 쿼리 엔진입니다.
77,395 스타apache/superset
Apache Superset는 데이터 시각화 및 데이터 탐색 플랫폼입니다.
75,473 스타