
noahshinn/reflexion
noahshinn/reflexion has 3,414 GitHub stars and 338 forks. GitHot measured 0 stars in 24 hours and +24 in 7 days. Last checked 2026-11-09 16:37 UTC. Last push 2025-01-14.
[NeurIPS 2023] Reflexion: 언어적 강화 학습을 사용하는 언어 에이전트
측정된 스타 증가
- in 24h
- 0
- in 7 days
- +24
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original[NeurIPS 2023] Reflexion: Language Agents with Verbal Reinforcement Learning
This repo holds the code, demos, and log files for Reflexion: Language Agents with Verbal Reinforcement Learning by Noah Shinn, Federico Cassano, Edward Berman, Ashwin Gopinath, Karthik Narasimhan, Shunyu Yao.
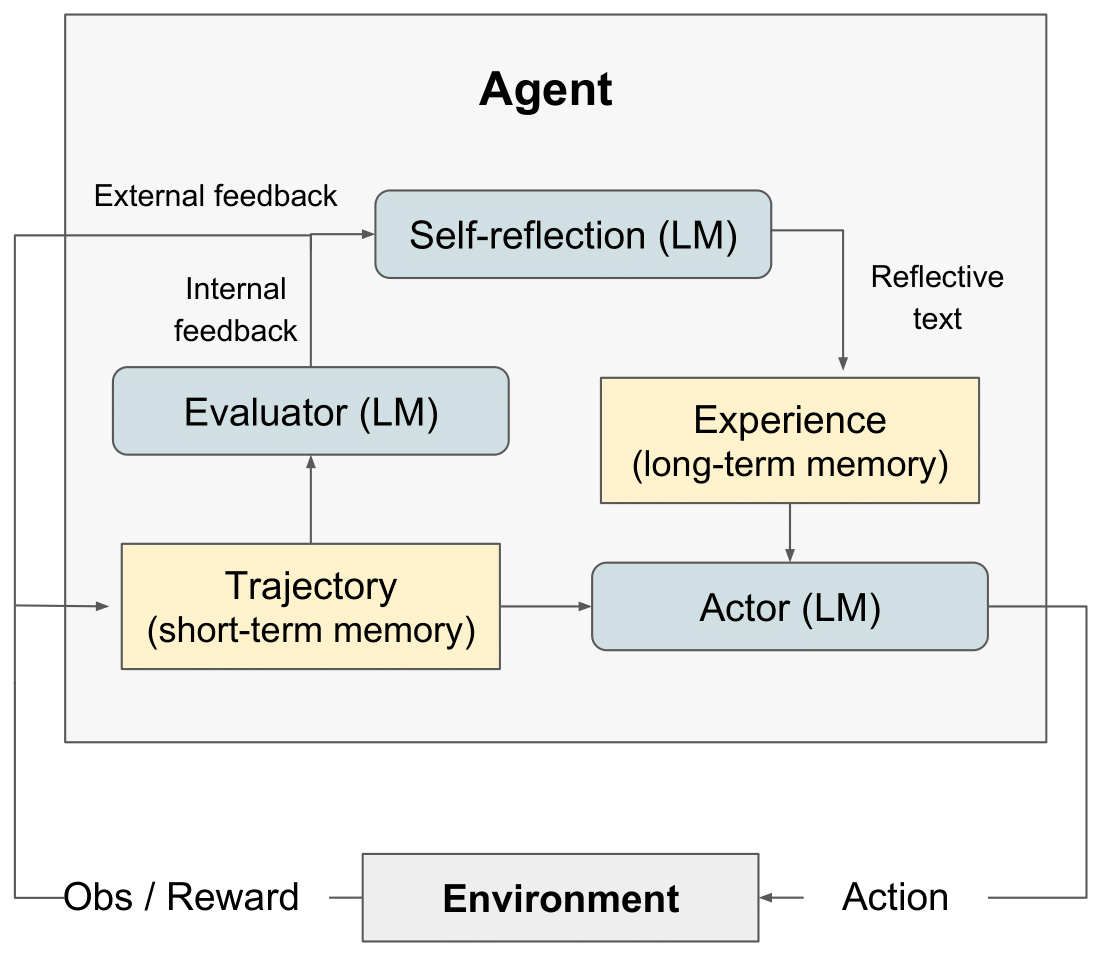
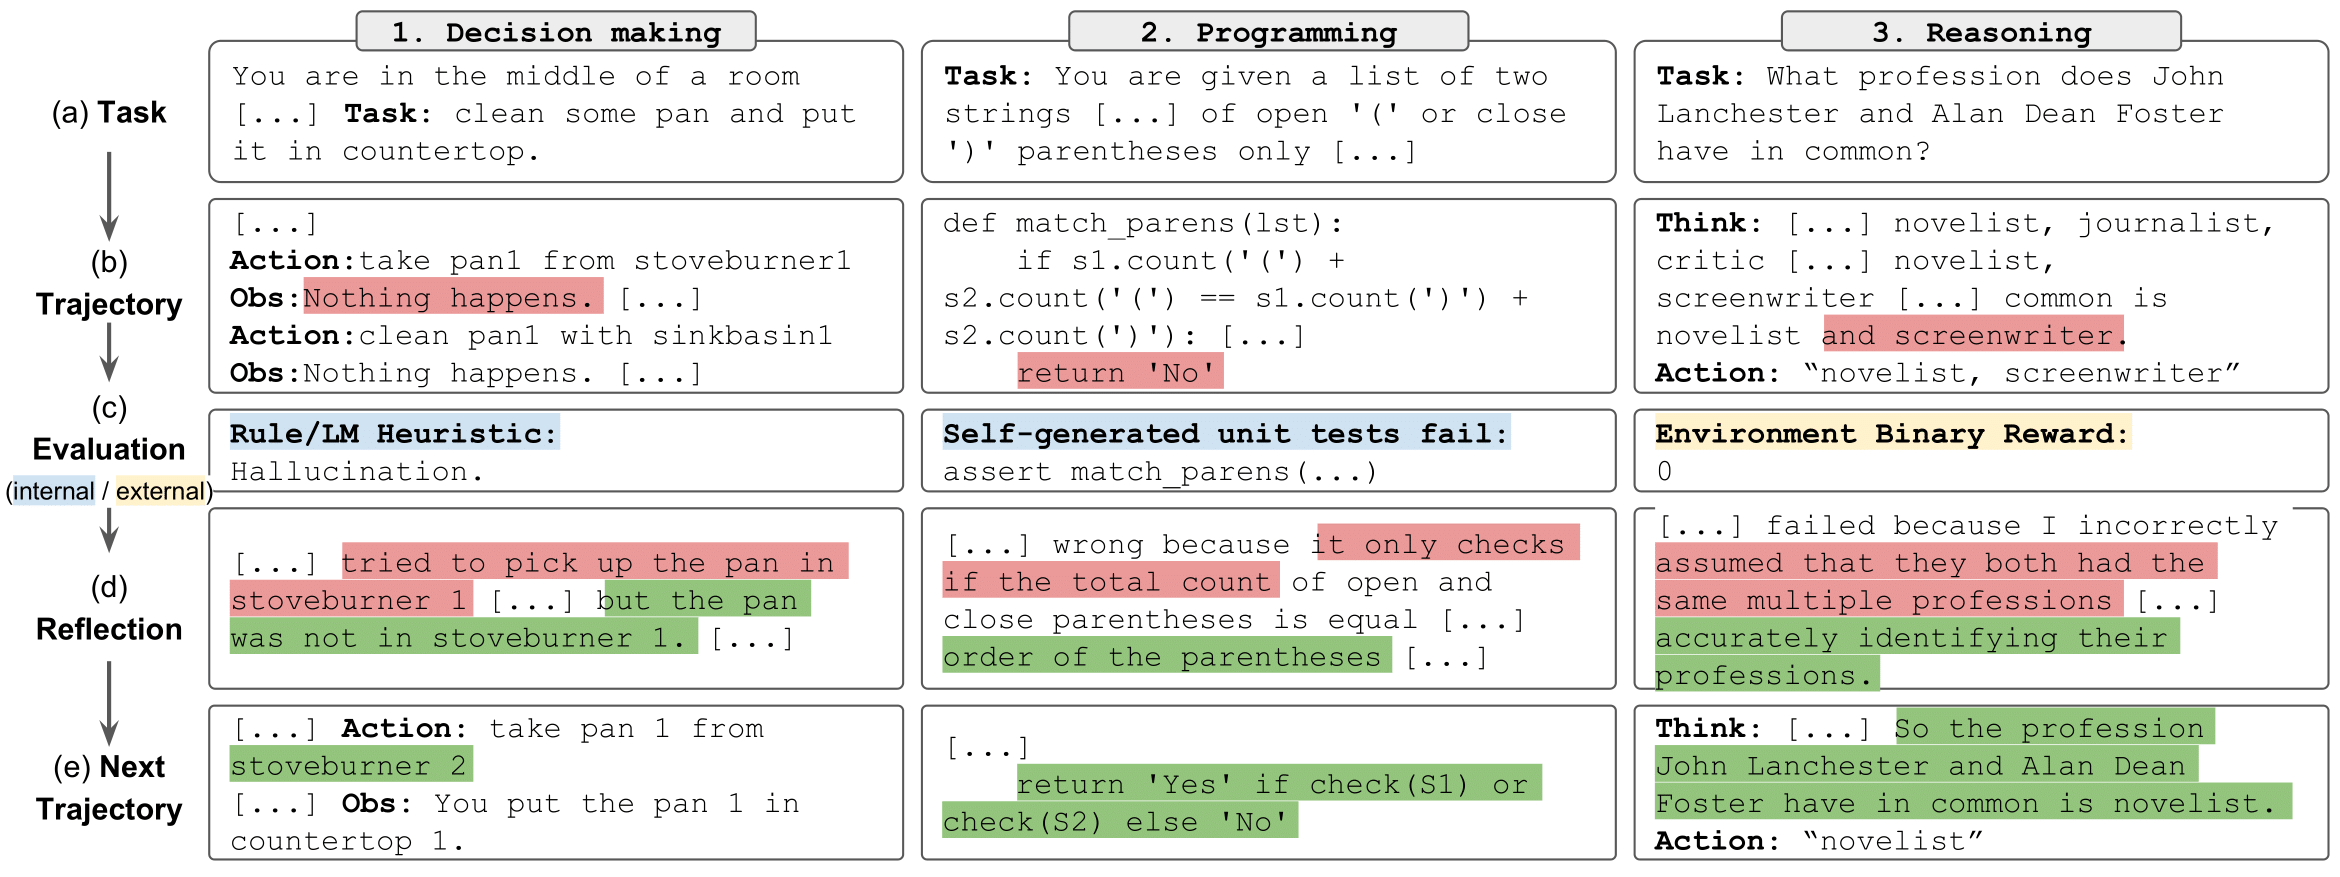
We have released the LeetcodeHardGym here
To Run: reasoning (HotPotQA)
We have provided a set of notebooks to easily run, explore, and interact with the results of the reasoning experiments. Each experiment consists of a random sample of 100 questions from the HotPotQA distractor dataset. Each question in the sample is attempted by an agent with a specific type and reflexion strategy.
Setup
To get started:
- Clone this repo and move to the HotPotQA directory:
git clone https://github.com/noahshinn/reflexion && cd ./hotpotqa_runs
- Install the module dependencies into your environment:
pip install -r requirements.txt
- Set
OPENAI_API_KEYenvironment variable to your OpenAI API key:
export OPENAI_API_KEY=<your key>
Agent Types
Agent type is determined by the notebook you choose to run. The available agent types include:
ReAct- ReAct AgentCoT_context- CoT Agent given supporting context about the questionCoT_no_context- CoT Agent given no supporting context about the question
The notebook for each agent type is located in the ./hotpot_runs/notebooks directory.
Reflexion Strategies
Each notebook allows you to specify the reflexion strategy to be used by the agents. The available reflexion strategies, which are defined in an Enum, include:
ReflexionStrategy.NONE- The agent is not given any information about its last attempt.ReflexionStrategy.LAST_ATTEMPT- The agent is given its reasoning trace from its last attempt on the question as context.ReflexionStrategy.REFLEXION- The agent is given its self-reflection on the last attempt as context.ReflexionStrategy.LAST_ATTEMPT_AND_REFLEXION- The agent is given both its reasoning trace and self-reflection on the last attempt as context.
To Run: decision-making (AlfWorld)
Clone this repo and move to the AlfWorld directory
git clone https://github.com/noahshinn/reflexion && cd ./alfworld_runs
Specify the run parameters in ./run_reflexion.sh.
num_trials: number of iterative learning steps
num_envs: number of task-environment pairs per trial
run_name: the name for this run
use_memory: use persisting memory to store self-reflections (turn off to run a baseline run)
is_resume: use logging directory to resume a previous run
resume_dir: the logging directory from which to resume the previous run
start_trial_num: if resume run, then the trial number of which to start
Run the trial
./run_reflexion.sh
The logs will be sent to ./root/<run_name>.
Another Note
Due to the nature of these experiments, it may not be feasible for individual developers to rerun the results as GPT-4 has limited access and significant API charges. All runs from the paper and additional results are logged in ./alfworld_runs/root for decision-making, ./hotpotqa_runs/root for reasoning, and ./programming_runs/root for programming
Other Notes
Check out the original implementation here
Read one of the original blog posts here
Check out an Appl implementation here.
Check out an interesting type-prediction implementation here: OpenTau
For all questions, contact [email protected]
Cite
@misc{shinn2023reflexion,
      title={Reflexion: Language Agents with Verbal Reinforcement Learning},
      author={Noah Shinn and Federico Cassano and Edward Berman and Ashwin Gopinath and Karthik Narasimhan and Shunyu Yao},
      year={2023},
      eprint={2303.11366},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}
관련 프로젝트 살펴보기
affaan-m/ECC
에이전트 실행·제어 프레임워크를 위한 성능 최적화 시스템. Claude Code, Codex, Opencode, Cursor 등을 위한 스킬, 본능, 메모리, 보안, 연구 우선 개발을 제공합니다.
300,313 스타NousResearch/hermes-agent
당신과 함께 성장하는 에이전트
262,134 스타multica-ai/andrej-karpathy-skills
Andrej Karpathy가 관찰한 LLM 코딩의 함정을 바탕으로 Claude Code의 동작을 개선하는 단일 CLAUDE.md 파일입니다.
231,460 스타firecrawl/firecrawl
웹과 그 너머의 데이터로 AI 에이전트를 강화합니다. 초지능을 위한 라이브러리를 구축하고 있습니다. 🔥
200,178 스타