
lambdasec/frame
lambdasec/frame has 84 GitHub stars and 13 forks. GitHot measured +31 stars in 24 hours and +32 in 7 days. Last checked 2026-11-08 19:48 UTC. Last push 2026-11-02.
Sound static analysis and LLM reasoning, in one security agent
What you can do
- Dependencies, by reachability: lockfiles of 11 ecosystems plus C/C++ and vendored copies, matched against OSV offline, ranked by whether attacker data actually reaches the vulnerable function, with upgrades Frame plans, applies and verifies against your tests, plus licence policy, SBOM and VEX.
- Secrets, including git history: credential-named values and 15 providers' key formats (AWS, GitHub, Stripe, OpenAI, and more), in code and in every commit the history ever added, with optional live verification against the provider's own API so a real leak is told from a test fixture.
- Containers: OS packages read from an image's layers (Debian, Ubuntu, Alpine, RHEL and more) and matched against the distributions' own advisories.
- AI applications: prompt injection, model output reaching a sink, and MCP servers, including hidden instructions in tool metadata that the person approving the tool cannot see, mapped to the OWASP LLM Top 10.
측정된 스타 증가
- in 24h
- +31
- in 7 days
- +32
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original
The sound, open SAST for modern apps: code, dependencies, secrets, infrastructure and AI, in one tool




Frame finds vulnerabilities by following attacker data through your code, across functions, files and layers, and proves each finding with a solver instead of pattern-matching. One open tool covers what a modern app needs scanned: the code, its dependencies, its secrets, its infrastructure and its AI calls. It runs offline, and the same soundness that keeps false alarms down lets it prove a fix actually removed the bug.
Where a team runs Semgrep for code, Snyk or Endor Labs for dependencies, gitleaks for secrets and checkov for infrastructure, Frame is one tool that does all of it, proves what it reports, and stays free and local. It is a genuine alternative to Semgrep, Snyk, Endor Labs, Veracode and ZeroPath: open where they are closed, sound where they pattern-match, and complete where they cover one layer. The numbers are in Benchmarks.
What Frame scans
- Code, across files, in five languages: Python, JavaScript/TypeScript, Java, C# and C/C++. A request that enters a controller and reaches a query three files away is one finding, not a lead. 80+ vulnerability classes, from SQL injection and SSRF to IDOR and C/C++ memory safety, each proved by taint or by the separation logic engine. 70+ framework packs (Flask, Django, Spring, ASP.NET, Express, and more), plus your own stack in one TOML file.
- Dependencies, by reachability: lockfiles of 11 ecosystems plus C/C++ and vendored copies, matched against OSV offline, ranked by whether attacker data actually reaches the vulnerable function, with upgrades Frame plans, applies and verifies against your tests, plus licence policy, SBOM and VEX.
- Secrets, including git history: credential-named values and 15 providers' key formats (AWS, GitHub, Stripe, OpenAI, and more), in code and in every commit the history ever added, with optional live verification against the provider's own API so a real leak is told from a test fixture.
- Infrastructure as code: Kubernetes against the Pod Security Standards (matching the admission controller's own evaluator), Dockerfiles as BuildKit parses them, Terraform as HCL evaluates it (AWS, Azure, Google Cloud), and CloudFormation with its intrinsic functions. Every policy is decided with Z3, and what depends on values the files do not give is reported as undecided, not guessed.
- Containers: OS packages read from an image's layers (Debian, Ubuntu, Alpine, RHEL and more) and matched against the distributions' own advisories.
- AI applications: prompt injection, model output reaching a sink, and MCP servers, including hidden instructions in tool metadata that the person approving the tool cannot see, mapped to the OWASP LLM Top 10.
Why it is different
- Sound, not pattern-based: findings are proved by a solver (its own separation logic engine on Z3: entailment, frame inference, bi-abduction, countermodels), so there are fewer false alarms and a fix can be proved to remove the bug.
- Open rules and advisories, as data: framework packs and the full advisory database ship as versioned public datasets,
lambdasec/frame-kbandlambdasec/frame-advisories(rebuilt daily), updated between releases and pinnable for air-gapped CI. Nothing in them runs. - Built for the AI-coding era: scan only what changed, baseline what you accept, and
verifythat a fix removed the bug; a GitHub Action, a pre-commit hook, and an MCP server for Claude Code, Codex, Cursor and other coding agents. - Runs on open models, local or hosted: an optional LLM layer adds recall for business-logic and authorization flaws, triages, and proposes fixes the sound core then verifies; it works with any OpenAI-compatible model, including on-device.
Quick start
pip install "frame-security[scan]"
frame scan src/
A three-file Flask app, where the request enters in app.py and the query runs in services/orders.py:
# shop/app.py
@app.route("/orders")
def list_orders():
    customer = request.args.get("customer", "")
    return jsonify(orders.for_customer(customer))

# shop/services/orders.py
def for_customer(name):
    cur.execute("SELECT * FROM orders WHERE customer = '" + name.strip() + "'")
$ frame scan benchmarks/exemplars/quickstart --root benchmarks/exemplars/quickstart
1. [CRITICAL] 🔴 sql_injection
   Location: benchmarks/exemplars/quickstart/shop/services/orders.py:8:4
   Description: Tainted data from 'customer' flows to sql sink
   CWE: CWE-89
   Data flow: shop/app.py:11 -> shop/services/orders.py::for_customer(name)
...
Scanned 4 files: 2 findings (2 critical)
Use a placeholder query, or wrap the value in int(), and the finding goes away.
For dependencies (advisories come from lambdasec/frame-advisories, cached once, then offline):
frame kb pull --advisories            # cache the advisories once (then everything runs offline)
frame deps --vulns                    # vulnerable dependencies, and whether your code calls the vulnerable function
frame deps --vulns --apply --relock   # upgrade, re-lock, report what is left
frame scan . --sca                    # attacker data reaching a vulnerable function, at the call site
For secrets, infrastructure and a repo inventory:
frame scan . --verify-secrets         # credentials in code, checked live against the provider
frame history .                        # credentials anywhere in the git history
frame iac .                            # Kubernetes, Dockerfiles, Terraform, CloudFormation (or frame scan . --iac)
frame inventory .                      # languages, frameworks, dependencies, IaC, containers, AI SDKs, MCP tools
Benchmarks
| Benchmark | What it measures | Frame | Comparison |
|---|---|---|---|
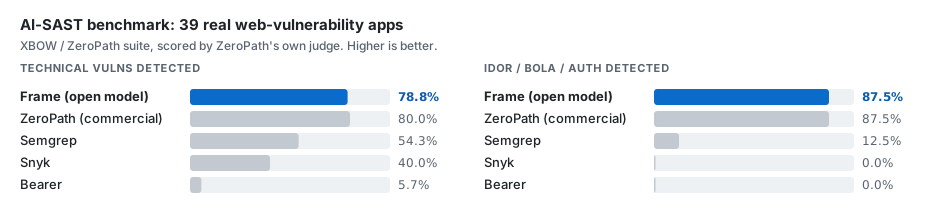
| XBOW / ZeroPath | AI-SAST on 39 web-vuln apps | detect 78.8%, FP 26.3% | ZeroPath 80% / 25%, Semgrep 54% / 45% |
| Endor Labs corpus | 193 vulns in 5 production apps | recall 0.67, precision 0.51 | Semgrep 0.52 / 0.40 |
| RealVuln IDOR/BOLA | Broken authorization, 4 real apps | 6/8 found, precision 1.00 | 0 false positives on safe controls |
| CVE-Bench | Detect, exploit, fix on 10 live CVEs | 5 / 4 / 4 of 10 | each stage verified on a live target |
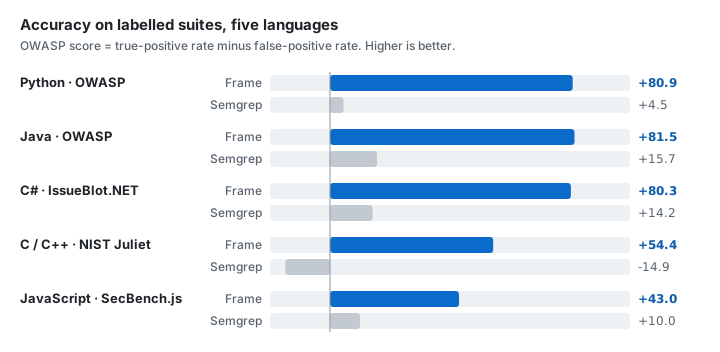
| SusVibes | 181 real-CVE Python pairs | recall 0.14, precision 0.56 | Semgrep 0.06 / 0.55 |
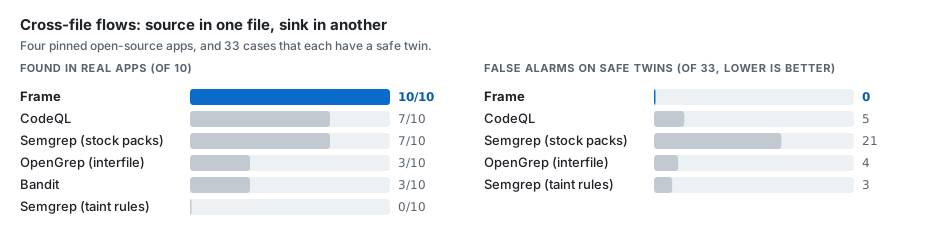
| Cross-file exemplars | Hand-labelled precision on 4 real apps | 98% | CodeQL 95% |
Methods and every suite, including SL-COMP for the engine, are in benchmarks/README.md.
Documentation
| Usage | Scanning, GitHub Action, pre-commit hook and MCP server, baselines and verify, secrets and git history, suppressions, configuration, every command and flag, environment variables, Python API |
| Dependencies | Supported ecosystems, advisories, reachability, upgrade plans, code mitigation, licences, SBOM, VEX, container images, CI |
| Coverage | Cross-file resolution per language, supported frameworks, writing a pack, every vulnerability class |
| Secrets | Hardcoded credentials by name and by provider format, git-history scanning, live verification |
| AI app security | Prompt injection, model output as taint, MCP tools and tool-metadata attacks, the OWASP LLM Top 10 |
| Infrastructure as code | Kubernetes, Dockerfiles, Terraform and CloudFormation, how close they are to Kubernetes, BuildKit and HCL, writing policies, how Z3 decides them |
| AI layer | Detect, triage, exploit and fix with any OpenAI-compatible model, including on-device |
| Separation logic engine | The prover under the scanner: capabilities, syntax, CLI, Python API, SL-COMP results |
| Roadmap | What is built, and what is next: precision polish, data growth, and autonomous pentesting |
| Examples | Runnable walkthroughs with real output: dependencies end to end, mitigations, adapting to a breaking upgrade, secrets, Kubernetes, AI apps and MCP servers |
| Exemplars | The quickstart app, a vulnerable and safe app per framework, and the cross-file comparison |
| Open datasets | Framework packs and spec tables, lambdasec/frame-kb; the OSV advisory database rebuilt daily, lambdasec/frame-advisories |
Contributing
pip install -e ".[dev]"
python -m pytest tests/ -n auto
ruff check frame tests benchmarks
CLAUDE.md is the engineering map of the codebase. To add a framework, write a pack under frame/sil/packs/data/<language>/ and a vulnerable/safe app pair under benchmarks/exemplars/frameworks/; the fixture test checks both.
License
관련 프로젝트 살펴보기
trimstray/the-book-of-secret-knowledge
영감을 주는 목록, 매뉴얼, 치트시트, 블로그, 팁, 원라이너, CLI/웹 도구 등을 모은 컬렉션.
257,046 스타Hack-with-Github/Awesome-Hacking
해커, 펜테스터, 보안 연구자를 위한 다양한 Awesome 목록 모음.
125,014 스타swisskyrepo/PayloadsAllTheThings
웹 애플리케이션 보안과 모의 침투 테스트/CTF에 유용한 페이로드 및 우회 방법 목록.
82,508 스타caddyserver/caddy
빠르고 확장 가능한 멀티플랫폼 HTTP/1-2-3 웹 서버이며, 자동 HTTPS를 지원합니다
78,910 스타