
huggingface/picotron
huggingface/picotron has 2,347 GitHub stars and 209 forks. GitHot measured 0 stars in 24 hours, +7 in 7 days, and +9 in 15 days. Last checked 2026-11-21 16:43 UTC. Last push 2025-08-26.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- +7
- in 15 days
- +9
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
교육용으로 설계된 미니멀한 4D 병렬 분산 학습 프레임워크
학습README.md
Originalpicotron
In the spirit of NanoGPT, we created Picotron: The minimalist & most-hackable repository for pre-training Llama-like models with 4D Parallelism (Data, Tensor, Pipeline, Context parallel). It is designed with simplicity and educational purposes in mind, making it an excellent tool for learning and experimentation.
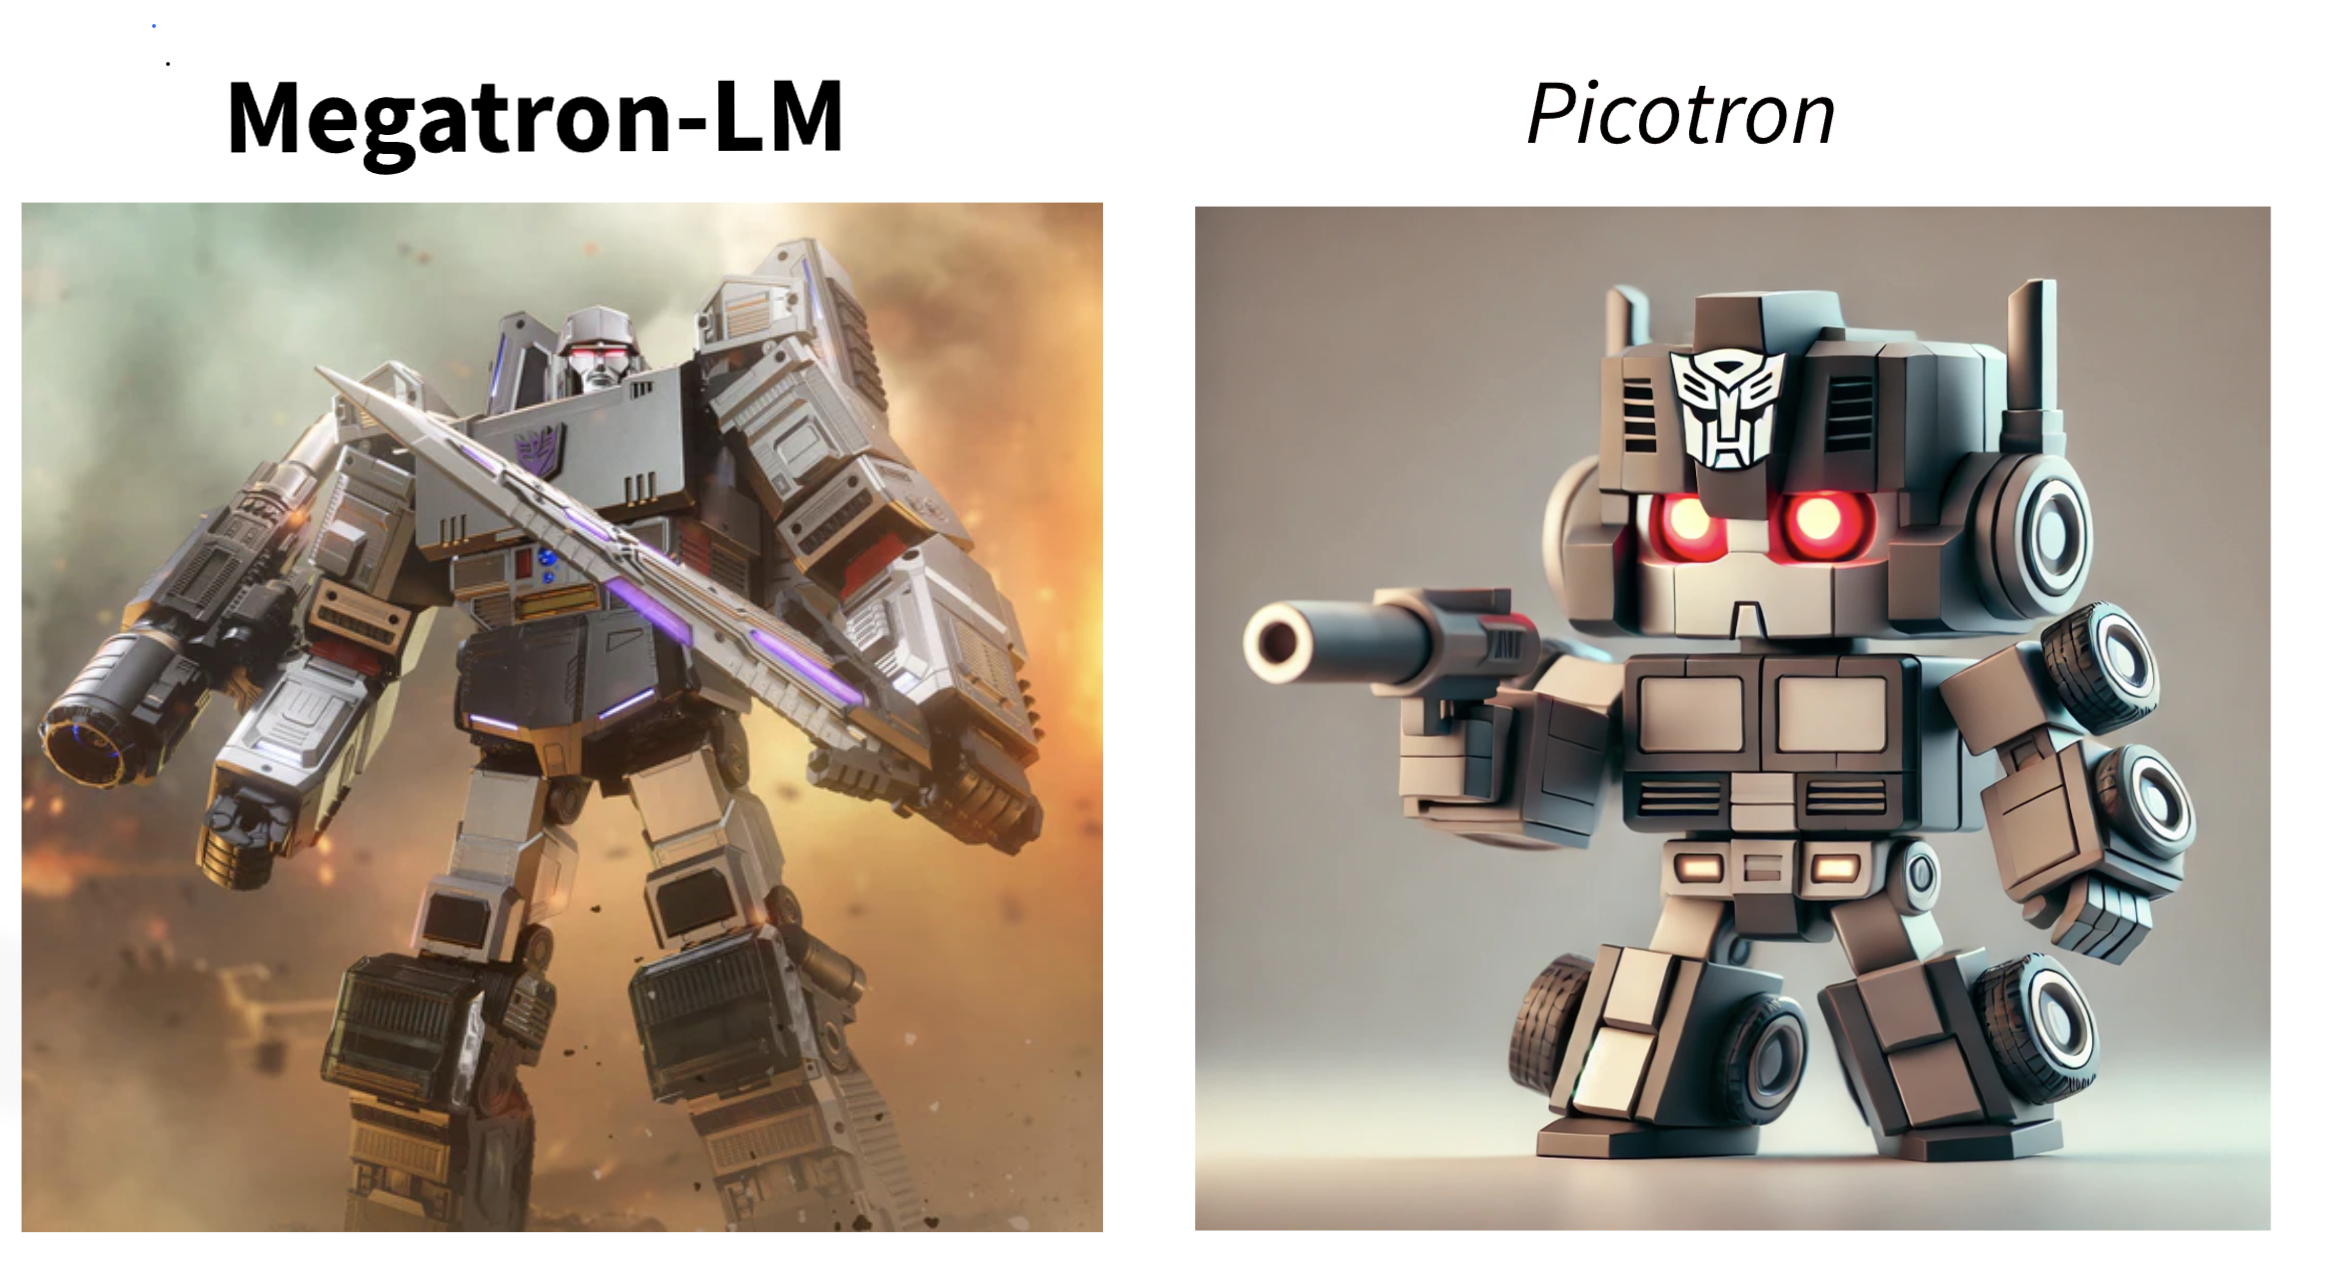
The code itself is simple and readable:
train.py,model.pyand[data|tensor|pipeline|context]_parallel.pyare all under 300 lines of code.Performance is not the best but still under active development. We observed 38% MFU on a LLaMA-2-7B model using 64 H100 GPUs and nearly 50% MFU on the SmolLM-1.7B model with 8 H100 GPUs. Benchmarks will come soon
Compared to Nanotron, Picotron is primarily for educational purposes, helping people quickly get familiar with all the techniques in distributed training
Tutorial videos
- A step by step tutorial on how to build Picotron distributed training framework form scratch:
Install
pip install -e .
Quick start
Get a HF token here to download models from HuggingFace
GPU
# To create a config file in json format under tmp by default
python create_config.py --out_dir tmp --exp_name llama-1B --dp 8 --model_name HuggingFaceTB/SmolLM-1.7B --num_hidden_layers 15  --grad_acc_steps 32 --mbs 4 --seq_len 1024 --hf_token <HF_TOKEN>

# Locally
torchrun --nproc_per_node 8 train.py --config tmp/llama-1B/config.json

# 3D Parallelism
python create_config.py --out_dir tmp --dp 4 --tp 2 --pp 2 --pp_engine 1f1b --exp_name llama-7B --model_name meta-llama/Llama-2-7b-hf  --grad_acc_steps 32 --mbs 4 --seq_len 1024 --hf_token <HF_TOKEN>

# Slurm
python submit_slurm_jobs.py --inp_dir tmp/llama-7B --qos high --hf_token <HF_TOKEN>
CPU (expect it to be slow)
# 3D Parallelism on CPU
python create_config.py --out_dir tmp --exp_name llama-1B-cpu --dp 2 --tp 2 --pp 2 --pp_engine 1f1b --model_name HuggingFaceTB/SmolLM-1.7B --num_hidden_layers 5  --grad_acc_steps 2 --mbs 4 --seq_len 128 --hf_token <HF_TOKEN> --use_cpu

# Locally
torchrun --nproc_per_node 8 train.py --config tmp/llama-1B-cpu/config.json
Citation
If you use Picotron, please cite it as:
@misc{zhao2025picotron,
  author = {Haojun Zhao and Ferdinand Mom},
  title = {Picotron: Distributed training framework for education and research experimentation},
  year = {2025},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/huggingface/picotron}}
}
Acknowledgements
관련 프로젝트 살펴보기
불러오는 중…