
erezsh/Preql
erezsh/Preql has 631 GitHub stars and 13 forks. GitHot measured 0 stars in 24 hours and +1 in 7 days. Last checked 2026-11-12 23:13 UTC. Last push 2022-08-17.
An interpreted relational query language that compiles to SQL.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- +1
- in 15 days
- 업데이트 지연
- in 1 month
- 업데이트 지연
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original
Preql is an interpreted, relational programming language, that specializes in database queries.
It is designed for use by data engineers, analysts and data scientists.
Preql's main objective is to provide an alternative to SQL, in the form of a high-level programming language, with first-class functions, modules, strict typing, and Python integration.
How does it work?
Preql code is interpreted and gets compiled to SQL at runtime. This way, Preql gains the performance and abilities of SQL, but can also operate as a normal scripting language.
Currently supported dialects are:
- Postgres
- MySQL
- Sqlite
- BigQuery
- More... (planned)
For features that are database-specific, or aren't implemented in Preql, there is a SQL() function that provides a convenient escape hatch to write raw SQL code.
Main Features
- Modern syntax and semantics
- Interpreted, everything is an object
- Strong type system with gradual type validation and duck-typing
- Compiles to SQL
- Python and Pandas integration
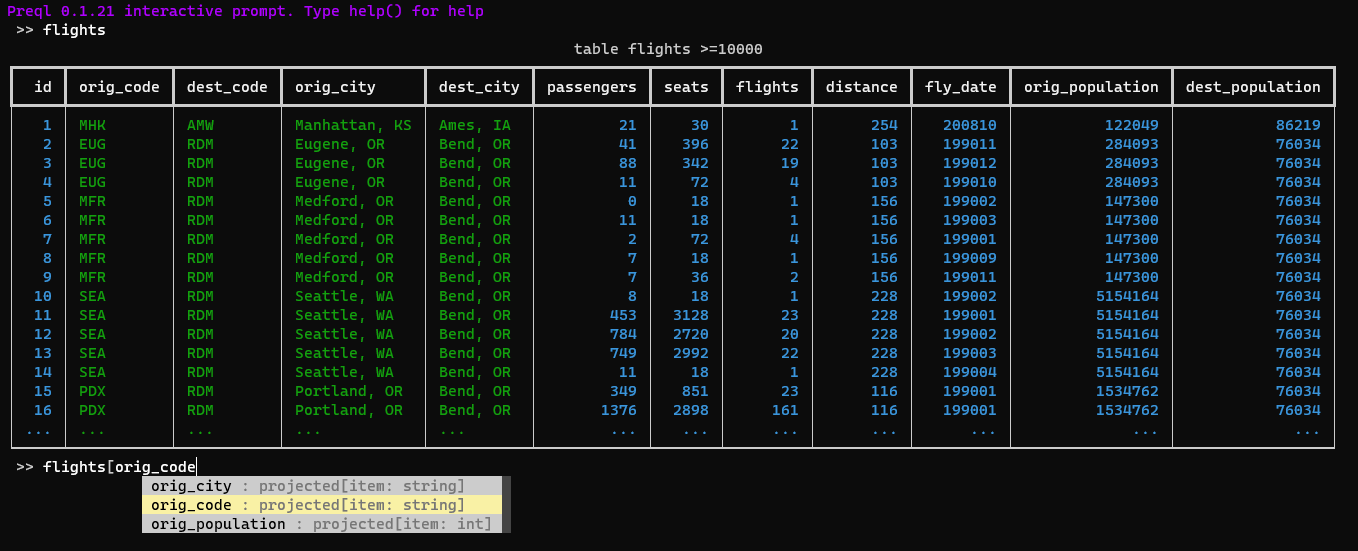
- Interactive shell (REPL) with auto-completion
- Runs on Jupyter Notebook
Note: Preql is still work in progress, and isn't yet recommended for use in production.

Learn More
Check out the online demo:

Get started
Simply install via pip:
pip install -U preql
Then just run the interpreter:
preql
Requires Python 3.6+
Quick Example
// Declare a new table
table Continent {
    name: string
    area: int       // km²
    population: int
}

// Initialize the table, by inserting rows
new Continent("Africa", 30370000, 1287920000)
new Continent("Antarctica", 14000000, 4490)
new Continent("Asia", 44579000, 4545133000)
new Continent("Europe", 10180000, 742648000)
new Continent("North America", 24709000, 587615000)
new Continent("South America", 17840000, 428240000)
new Continent("Australia", 8600000, 41261000)

// Print the continents, ordered by density
print Continent {
    ...                         // Include existing fields
    density: population / area  // Create new a field

} order{^density}

// Print the total land area
print "Total land area:", sum(Continent{area}), "km²"

//  ========================= Output ==========================

                              table  =7
┏━━━━┳━━━━━━━━━━━━━━━┳━━━━━━━━━━┳━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━┓
┃ id ┃ name          ┃     area ┃ population ┃               density ┃
┡━━━━╇━━━━━━━━━━━━━━━╇━━━━━━━━━━╇━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━┩
│  3 │ Asia          │ 44579000 │ 4545133000 │     101.9568182328002 │
│  4 │ Europe        │ 10180000 │  742648000 │      72.9516699410609 │
│  1 │ Africa        │ 30370000 │ 1287920000 │     42.40763911755021 │
│  6 │ South America │ 17840000 │  428240000 │    24.004484304932735 │
│  5 │ North America │ 24709000 │  587615000 │    23.781415678497712 │
│  7 │ Australia     │  8600000 │   41261000 │     4.797790697674419 │
│  2 │ Antarctica    │ 14000000 │       4490 │ 0.0003207142857142857 │
└────┴───────────────┴──────────┴────────────┴───────────────────────┘

Total land area: 150278000 km²
In the background, this table was generated by executing the following compiled SQL code (reformatted):
-- Continent {..., density: population / area} order{ ^density }
WITH subq_1(id, name, area, population, density) AS (
    SELECT id, name, area, population, (CAST(population AS float) / area) AS density
    FROM Continent
    ORDER BY density DESC)
SELECT * FROM subq_1
See more examples in the examples folder.
Interactive Environment
License
Preql uses an “Interface-Protection Clause” on top of the MIT license.
See: LICENSE
In simple words, it's free for personal use. Also, it can be used for any commercial or non-commercial purpose, as long as your product doesn't base its value on exposing the Preql language itself to your users. Read more
관련 프로젝트 살펴보기
Asabeneh/30-Days-Of-Python
30 Days of Python 프로그래밍 챌린지는 Python 프로그래밍 언어를 30일 동안 배우기 위한 단계별 가이드입니다. 이 챌린지는 100일 이상 걸릴 수 있습니다. 자신의 속도에 맞춰 진행하세요. 다음 동영상도 도움이 될 수 있습니다: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,673 스타grafana/grafana
개방적이고 조합 가능한 옵저버빌리티 및 데이터 시각화 플랫폼입니다. Prometheus, Loki, Elasticsearch, InfluxDB, Postgres 등 여러 소스의 메트릭, 로그, 트레이스를 시각화합니다.
77,876 스타redis/redis
실시간 데이터 기반 애플리케이션을 구축하는 개발자에게 Redis는 가장 선호되고, 가장 빠르며, 기능이 가장 풍부한 캐시, 데이터 구조 서버이자 문서 및 벡터 쿼리 엔진입니다.
77,485 스타apache/superset
Apache Superset는 데이터 시각화 및 데이터 탐색 플랫폼입니다.
75,509 스타