
Rudrabha/Lip2Wav
Rudrabha/Lip2Wav has 716 GitHub stars and 155 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-22 06:36 UTC. Last push 2023-07-06.
What you can do
- First work to generate intelligible speech from only lip movements in unconstrained settings.
- Sequence-to-Sequence modelling of the problem.
- Dataset for 5 speakers containing 100+ hrs of video data made available! [Dataset folder of this repo]
- Complete training code and pretrained models made available.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
This is the repository containing codes for our CVPR, 2020 paper titled "Learning Individual Speaking Styles for Accurate Lip to Speech Synthesis"
학습README.md
OriginalUpdate: In case you are looking for Wav2Lip, it is in https://github.com/Rudrabha/Wav2Lip
Lip2Wav
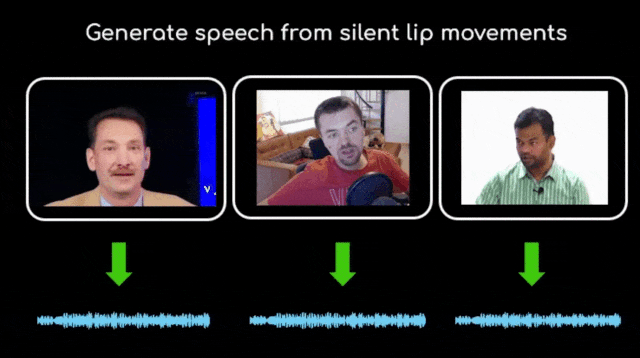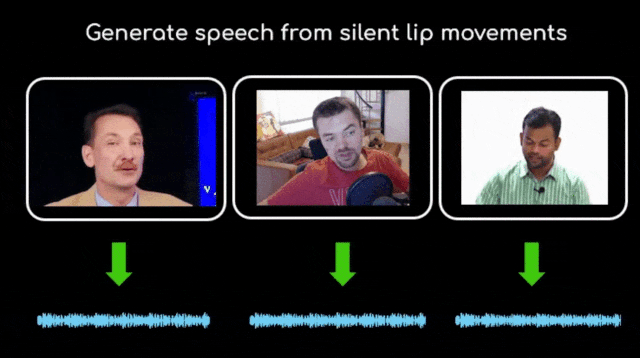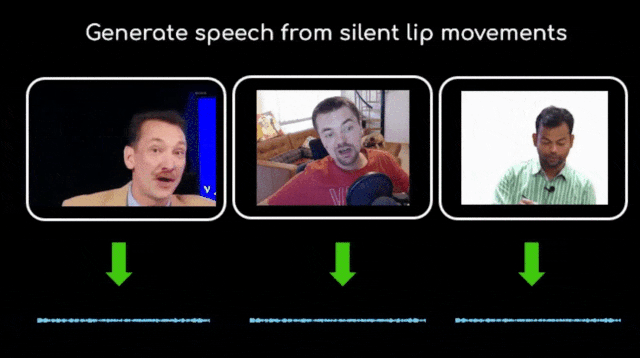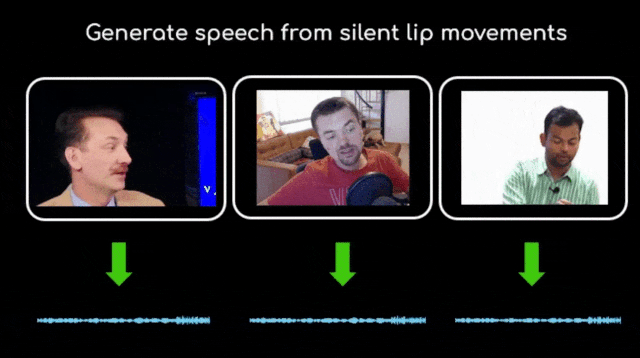
Generate high quality speech from only lip movements. This code is part of the paper: Learning Individual Speaking Styles for Accurate Lip to Speech Synthesis published at CVPR'20.
[Paper] | [Project Page] | [Demo Video]
Recent Updates
- Dataset and Pre-trained models for all speakers are released!
- Pre-trained model for multi-speaker word-level Lip2Wav model trained on the LRW dataset is released! (multispeaker branch)
Highlights
- First work to generate intelligible speech from only lip movements in unconstrained settings.
- Sequence-to-Sequence modelling of the problem.
- Dataset for 5 speakers containing 100+ hrs of video data made available! [Dataset folder of this repo]
- Complete training code and pretrained models made available.
- Inference code to generate results from the pre-trained models.
- Code to calculate metrics reported in the paper is also made available.
You might also be interested in:
:tada: Lip-sync talking face videos to any speech using Wav2Lip: https://github.com/Rudrabha/Wav2Lip
Prerequisites
Python 3.7.4(code has been tested with this version)- ffmpeg:
sudo apt-get install ffmpeg - Install necessary packages using
pip install -r requirements.txt - Face detection pre-trained model should be downloaded to
face_detection/detection/sfd/s3fd.pth. Alternative link if the above does not work.
Getting the weights
| Speaker | Link to the model |
|---|---|
| Chemistry Lectures | Link |
| Chess Commentary | Link |
| Hardware-security Lectures | Link |
| Deep-learning Lectures | Link |
| Ethical Hacking Lectures | Link |
Downloading the dataset
The dataset is present in the Dataset folder in this repository. The folder Dataset/chem contains .txt files for the train, val and test sets.
data_root (Lip2Wav in the below examples)
├── Dataset
|	├── chess, chem, dl (list of speaker-specific folders)
|	|    ├── train.txt, test.txt, val.txt (each will contain YouTube IDs to download)
To download the complete video data for a specific speaker, just run:
sh download_speaker.sh Dataset/chem
This should create
Dataset
├── chem (or any other speaker-specific folder)
|	├── train.txt, test.txt, val.txt
|	├── videos/		(will contain the full videos)
|	├── intervals/	(cropped 30s segments of all the videos)
Preprocessing the dataset
python preprocess.py --speaker_root Dataset/chem --speaker chem
Additional options like batch_size and number of GPUs to use can also be set.
Generating for the given test split
python complete_test_generate.py -d Dataset/chem -r Dataset/chem/test_results \
--preset synthesizer/presets/chem.json --checkpoint <path_to_checkpoint>

#A sample checkpoint_path  can be found in hparams.py alongside the "eval_ckpt" param.
This will create:
Dataset/chem/test_results
├── gts/  (cropped ground-truth audio files)
|	├── *.wav
├── wavs/ (generated audio files)
|	├── *.wav
Calculating the metrics
You can calculate the PESQ, ESTOI and STOI scores for the above generated results using score.py:
python score.py -r Dataset/chem/test_results
Training
python train.py <name_of_run> --data_root Dataset/chem/ --preset synthesizer/presets/chem.json
Additional arguments can also be set or passed through --hparams, for details: python train.py -h
License and Citation
The software is licensed under the MIT License. Please cite the following paper if you have use this code:
@InProceedings{Prajwal_2020_CVPR,
author = {Prajwal, K R and Mukhopadhyay, Rudrabha and Namboodiri, Vinay P. and Jawahar, C.V.},
title = {Learning Individual Speaking Styles for Accurate Lip to Speech Synthesis},
booktitle = {The IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
month = {June},
year = {2020}
}
Acknowledgements
The repository is modified from this TTS repository. We thank the author for this wonderful code. The code for Face Detection has been taken from the face_alignment repository. We thank the authors for releasing their code and models.
관련 프로젝트 살펴보기
불러오는 중…