
OpenGVLab/VideoMamba
OpenGVLab/VideoMamba has 1,133 GitHub stars and 92 forks. GitHot measured 0 stars in 24 hours, -1 in 7 days, and +1 in 15 days. Last checked 2026-11-19 11:03 UTC. Last push 2024-07-06.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- -1
- in 15 days
- +1
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
[ECCV2024] VideoMamba: State Space Model for Efficient Video Understanding
창작 및 미디어README.md
Original:snake:VideoMamba
VideoMamba: State Space Model for Efficient Video Understanding
Kunchang Li, Xinhao Li, Yi Wang, Yinan He, Yali Wang, Limin Wang and Yu Qiao


Update
- :warning: 2024/03/25:
The current video models are fine-tuned without layer decay due to the bug, which may help to improve the performances as in MAE. We have fixed the bug but do not plan to retrain them.We have applied it for VideoMamba-M but it does not help. - 2024/03/13: Fix some bugs and add :hugs:HF model links.
- :fire: 2024/03/12: All the code and models are released.
Introduction
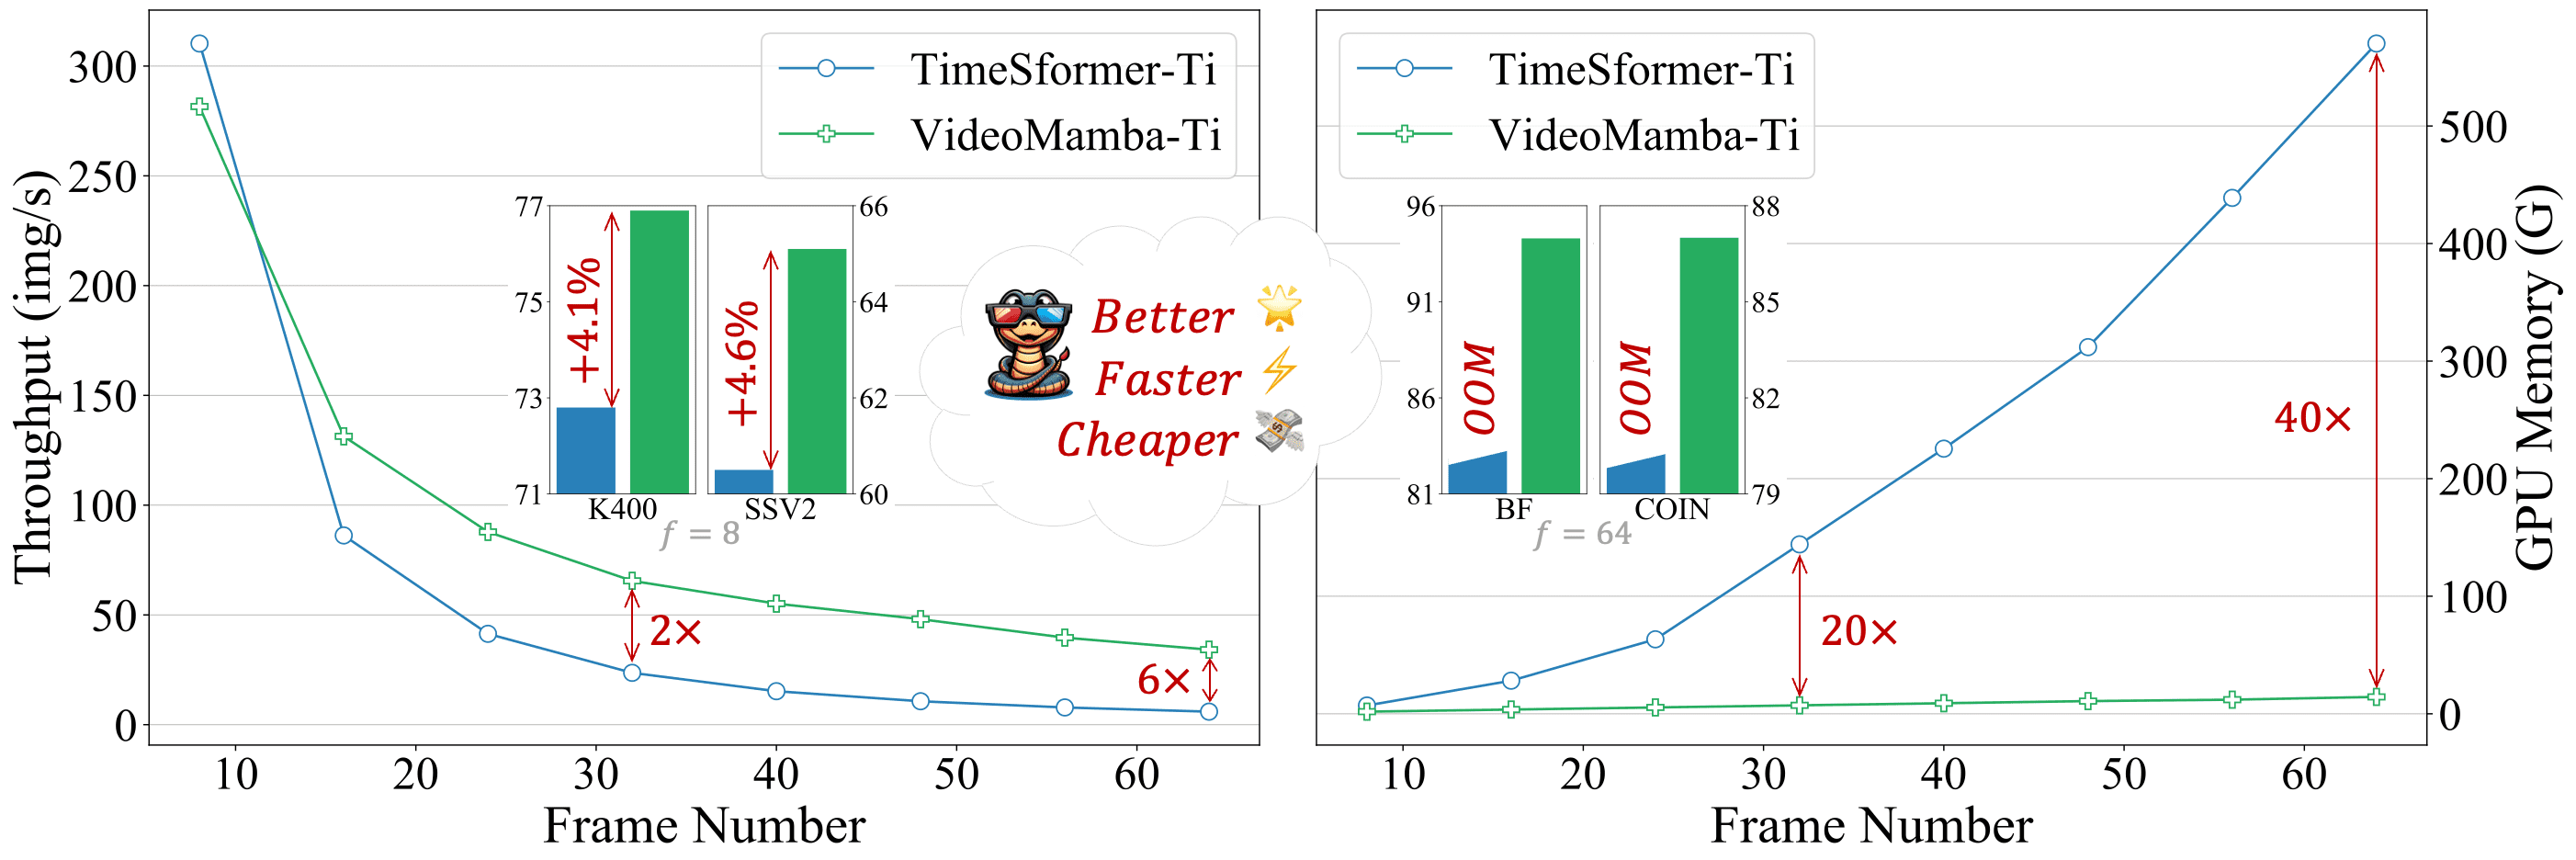
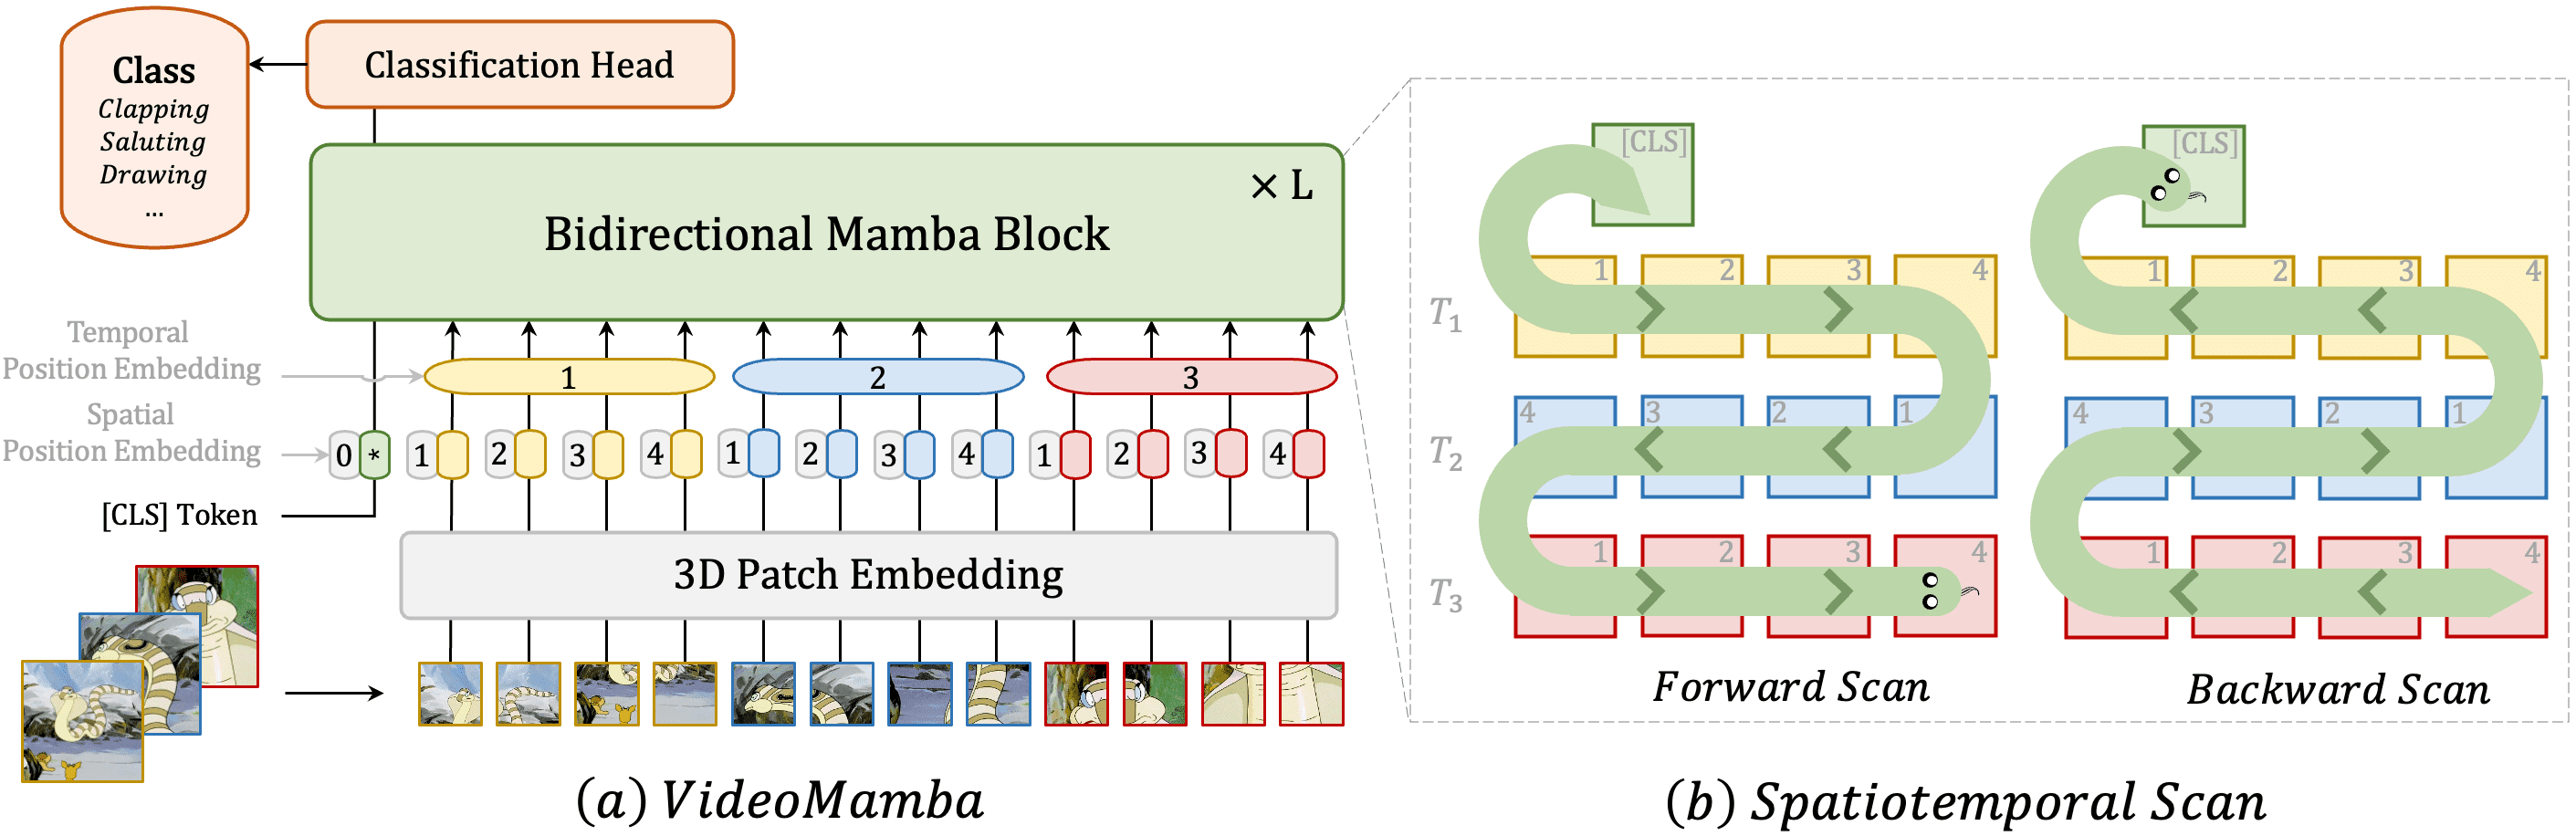 Addressing the dual challenges of local redundancy and global dependencies in video understanding, this work innovatively adapts the Mamba to the video domain. The proposed VideoMamba overcomes the limitations of existing 3D convolution neural networks and video transformers. Its linear-complexity operator enables efficient long-term modeling, which is crucial for high-resolution long video understanding. Extensive evaluations reveal VideoMamba's four core abilities: (1) Scalability in the visual domain without extensive dataset pretraining, thanks to a novel self-distillation technique; (2) Sensitivity for recognizing short-term actions even with fine-grained motion differences; (3) Superiority in long-term video understanding, showcasing significant advancements over traditional feature-based models; and (4) Compatibility with other modalities, demonstrating robustness in multi-modal contexts. Through these distinct advantages, VideoMamba sets a new benchmark for video understanding, offering a scalable and efficient solution for comprehensive video understanding.
Cite
If you find this repository useful, please use the following BibTeX entry for citation.
@misc{li2024videomamba,
      title={VideoMamba: State Space Model for Efficient Video Understanding},
      author={Kunchang Li and Xinhao Li and Yi Wang and Yinan He and Yali Wang and Limin Wang and Yu Qiao},
      year={2024},
      eprint={2403.06977},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
License
This project is released under the Apache 2.0 license
Acknowledgement
This repository is built based on UniFormer, Unmasked Teacher and Vim repository.