
OpenGVLab/VideoMAEv2
OpenGVLab/VideoMAEv2 has 836 GitHub stars and 91 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-19 16:24 UTC. Last push 2024-10-08.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 기록 수집 중
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
[CVPR 2023] VideoMAE V2: Scaling Video Masked Autoencoders with Dual Masking
창작 및 미디어README.md
Original[CVPR 2023] Official Implementation of VideoMAE V2
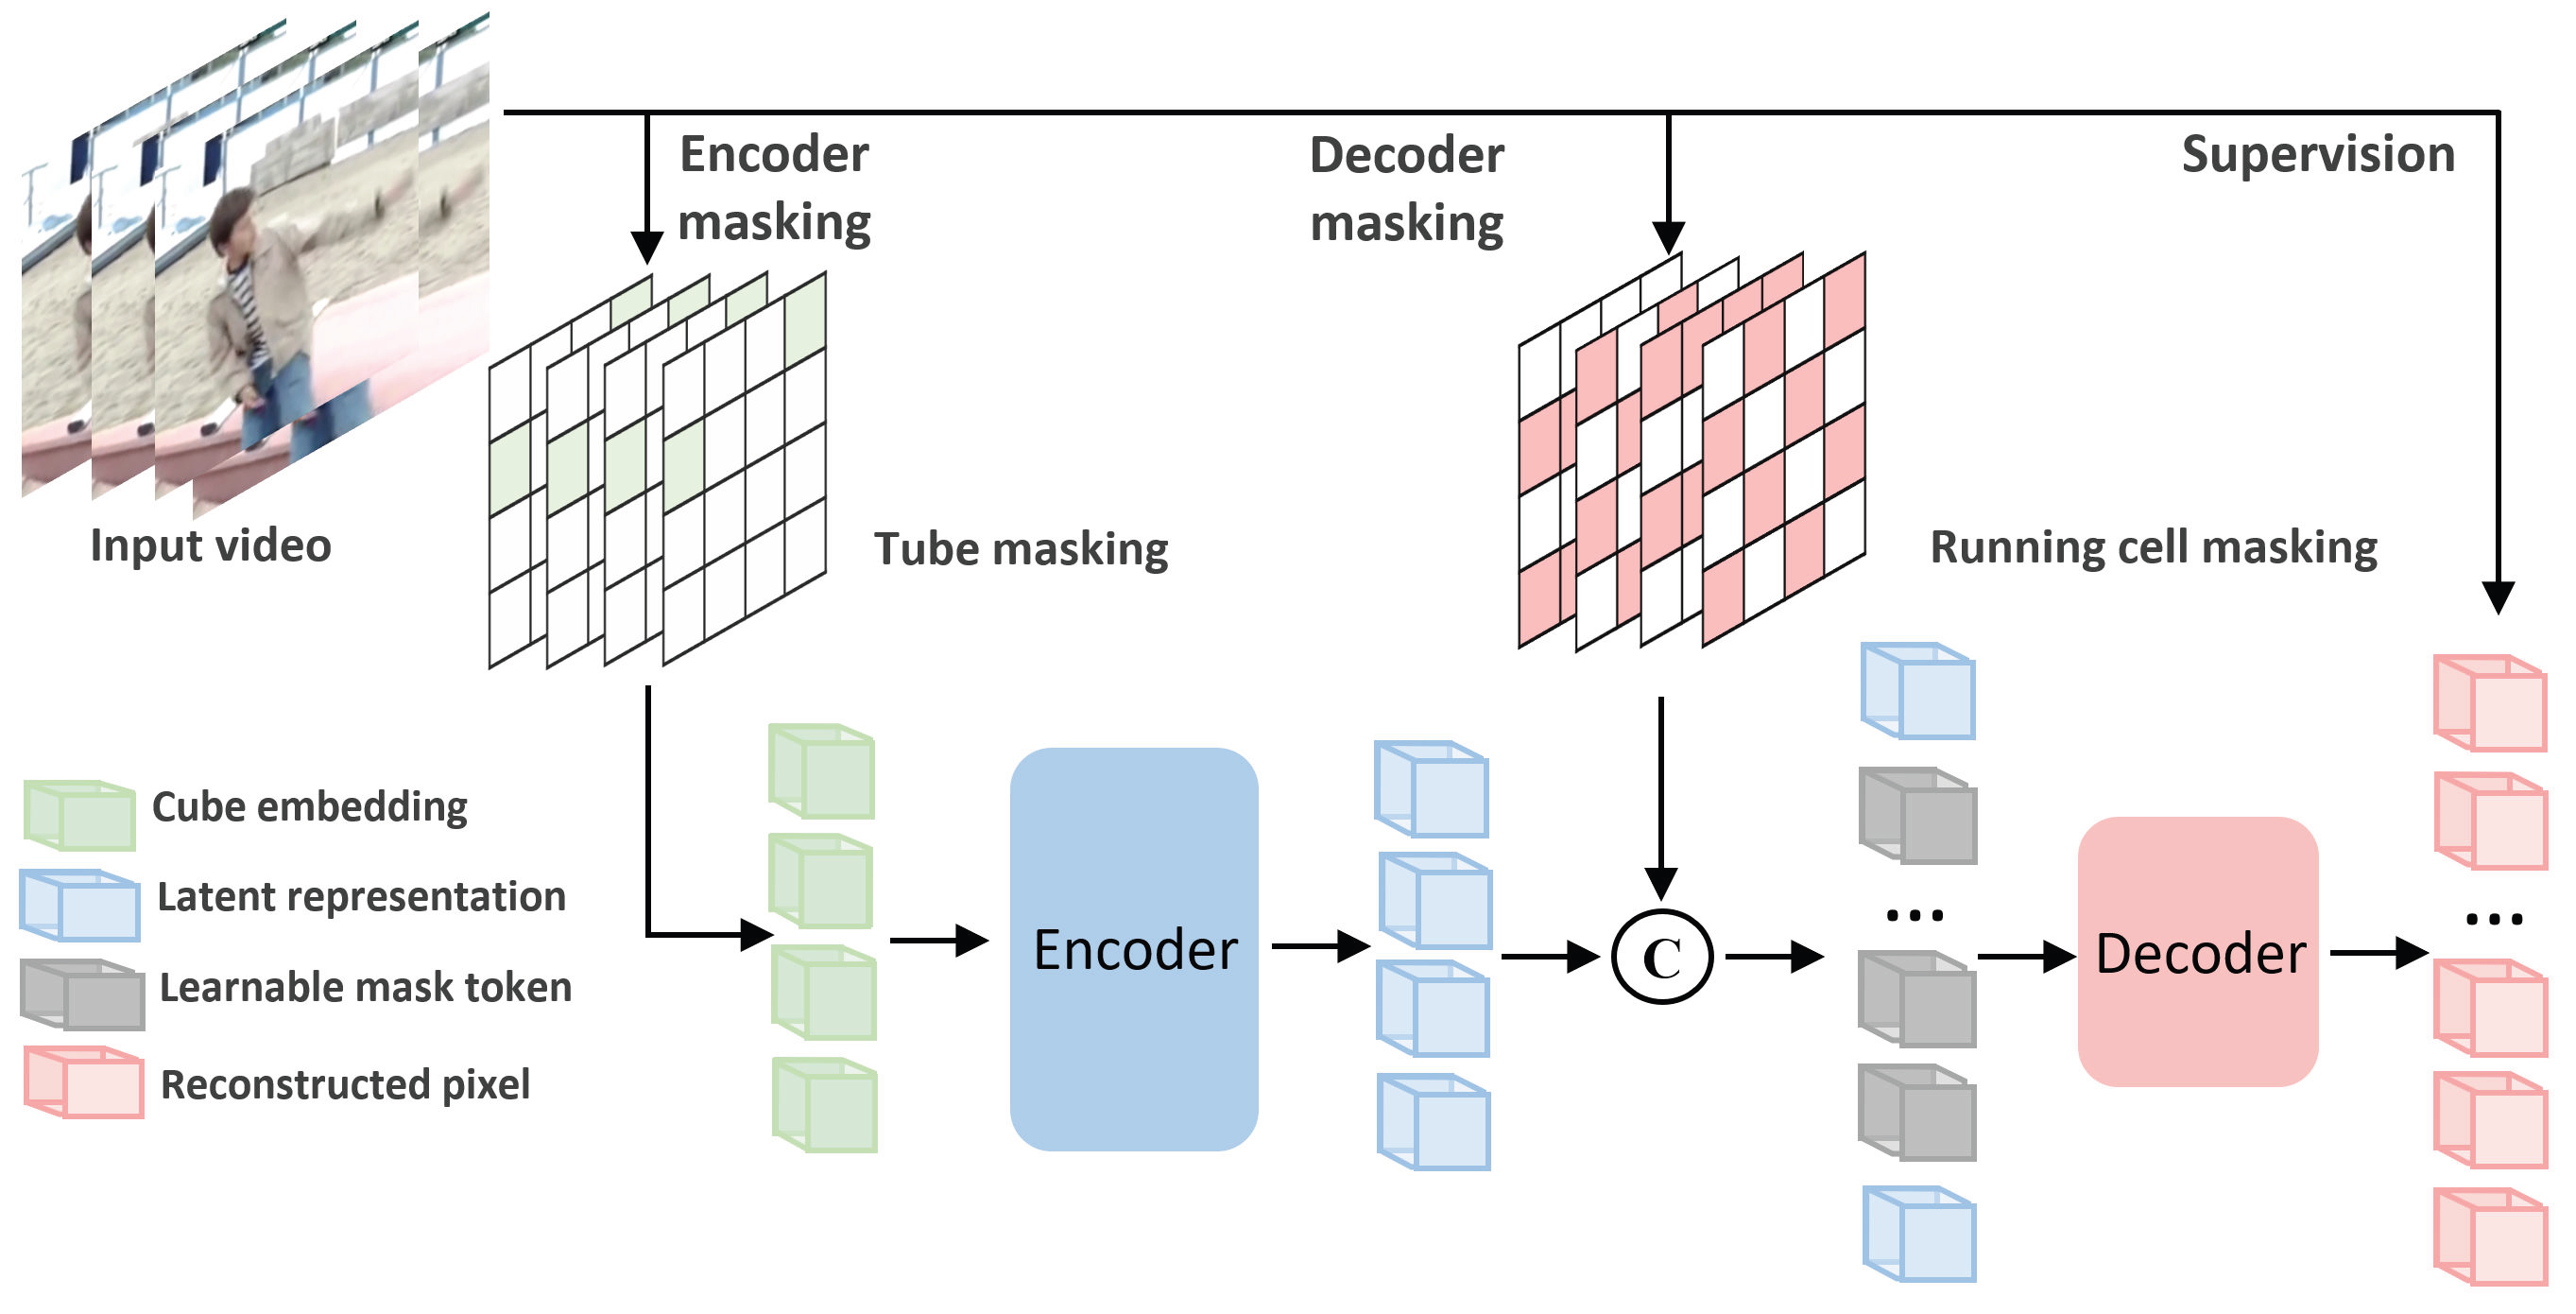


VideoMAE V2: Scaling Video Masked Autoencoders with Dual Masking
Limin Wang, Bingkun Huang, Zhiyu Zhao, Zhan Tong, Yinan He, Yi Wang, Yali Wang, and Yu Qiao
Nanjing University, Shanghai AI Lab, CAS
News
[2024.09.19] Checkpoints have been migrated to Hugging Face. You can obtain weights from VideoMAEv2-hf.
[2023.05.29] VideoMAE V2-g features for THUMOS14 and FineAction datasets are available at TAD.md now.
[2023.05.11] We have supported testing of our distilled models at MMAction2 (dev version)! See PR#2460.
[2023.05.11] The feature extraction script for TAD datasets has been released! See instructions at TAD.md.
[2023.04.19] ViT-giant model weights have been released! You can get the download links from MODEL_ZOO.md.
[2023.04.18] Code and the distilled models (vit-s & vit-b) have been released!
[2023.04.03] Code and models will be released soon.
Model Zoo
We now provide the model weights in MODEL_ZOO.md. We have additionally provided distilled models in MODEL_ZOO.
| Model | Dataset | Teacher Model | #Frame | K710 Top-1 | K400 Top-1 | K600 Top-1 |
|---|---|---|---|---|---|---|
| ViT-small | K710 | vit_g_hybrid_pt_1200e_k710_ft | 16x5x3 | 77.6 | 83.7 | 83.1 |
| ViT-base | K710 | vit_g_hybrid_pt_1200e_k710_ft | 16x5x3 | 81.5 | 86.6 | 85.9 |
Installation
Please follow the instructions in INSTALL.md.
Data Preparation
Please follow the instructions in DATASET.md for data preparation.
Pre-training
The pre-training instruction is in PRETRAIN.md.
Fine-tuning
The fine-tuning instruction is in FINETUNE.md.
Citation
If you find this repository useful, please use the following BibTeX entry for citation.
@InProceedings{wang2023videomaev2,
    author    = {Wang, Limin and Huang, Bingkun and Zhao, Zhiyu and Tong, Zhan and He, Yinan and Wang, Yi and Wang, Yali and Qiao, Yu},
    title     = {VideoMAE V2: Scaling Video Masked Autoencoders With Dual Masking},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
    month     = {June},
    year      = {2023},
    pages     = {14549-14560}
}

@misc{videomaev2,
      title={VideoMAE V2: Scaling Video Masked Autoencoders with Dual Masking},
      author={Limin Wang and Bingkun Huang and Zhiyu Zhao and Zhan Tong and Yinan He and Yi Wang and Yali Wang and Yu Qiao},
      year={2023},
      eprint={2303.16727},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}