
FlashML-org/FreeToken
FlashML-org/FreeToken has 16,824 GitHub stars and 1,656 forks. GitHot measured +29 stars in 24 hours and +1,443 in 7 days. Last checked 2026-11-08 12:49 UTC. Last push 2026-11-07.
FreeToken은 데이터센터 규모의 모델 서빙을 데스크톱으로 제공합니다. 대규모 모델을 로컬에서 빠르고 효율적으로 실행할 수 있습니다.
측정된 스타 증가
- in 24h
- +29
- in 7 days
- +1,443
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original
| Download | Paper | Developer Slack | Community Discord | Community WeChat |
Unlock datacenter-class intelligence on the hardware you already own — Run 290B+ frontier MoE models locally on your gaming PC at blistering interactive speeds.
About
FreeToken is an edge-native Mixture-of-Experts (MoE) serving engine designed for running frontier-scale open-weight models on personal and consumer hardware. It treats heterogeneous edge resources—GPUs, CPUs, host memory, and interconnects—as a unified, elastic inference platform. Its core features include:
- Fast Edge-Native Runtime: Provides efficient MoE serving with bandwidth-adaptive CPU–GPU co-execution ($q^\star$ policy), full-layer double-buffered prefill streaming, global LRU expert caching, graph-compatible execution, and the FTW fast weight format.
- Semantic-Aware Caching: Features semantic anchor checkpoints for recurrent state and KV caches, allowing agentic context edits (e.g., tool calls, thinking blocks) to avoid redundant context recomputation.
- Elastic Memory Management: Supports dynamic, runtime VRAM re-allocation between expert caches and KV memory without engine restarts or weight reloading.
- Broad MoE & Ecosystem Support: Supports frontier open-weight MoE models (e.g., DeepSeek-V4-Flash, Qwen3.6-35B-A3B, GLM-5.2) across various parameter scales and quantization formats (e.g., MXFP4, NVFP4, FP8, BF16, GGUF), with Anthropic/OpenAI-compatible APIs for seamless integration with real-world coding and tool-calling agents (e.g., Codex, Claude Code, OpenCode, OpenClaw, DeepSeek Harness).
- Diverse Consumer Hardware: Scales across consumer laptops, gaming desktops, and workstation GPUs, with native support for NVIDIA RTX 30, RTX 40, and RTX 50 series GPUs.
Getting Started
Desktop app
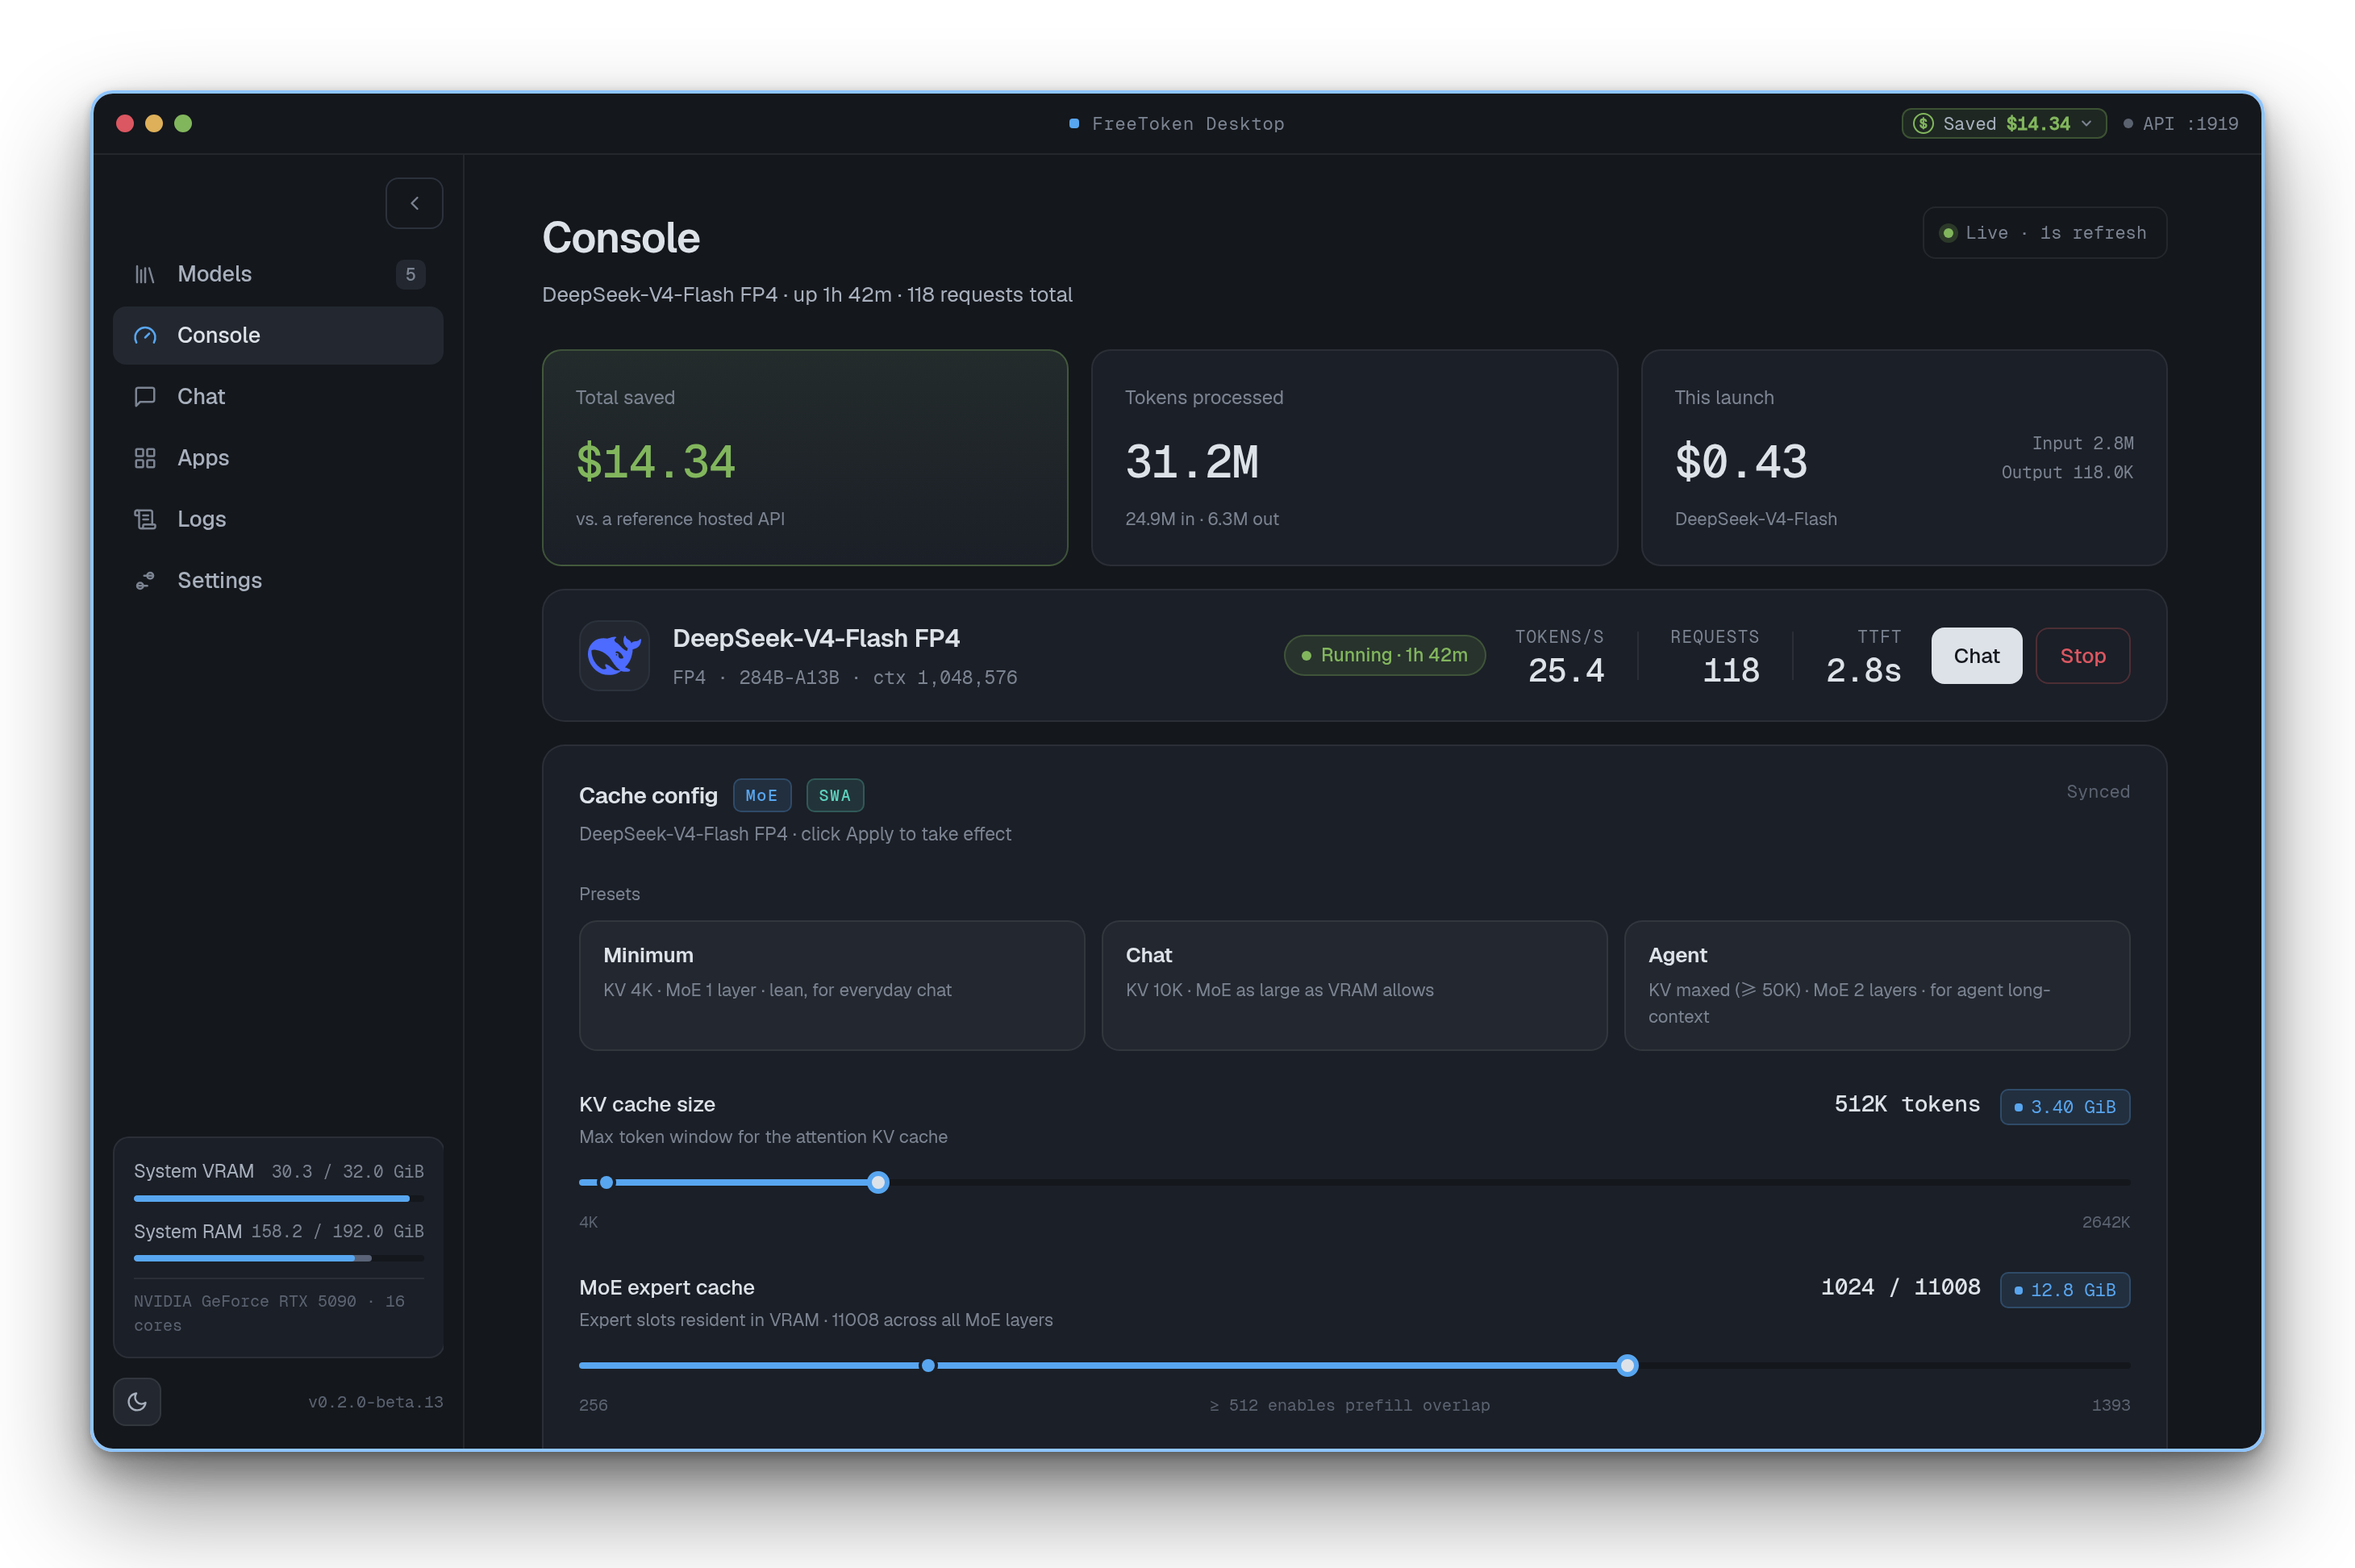
Download FreeToken for Windows or Linux at flashml.ai. It sets the engine up for you and gives you a GUI for running models, chatting, and tuning the engine.
CLI
Install FreeToken with uv (recommended) or pip:
uv pip install "freetoken[accel]"
Or build from source:
git clone https://github.com/FlashML-org/FreeToken.git && cd FreeToken
uv venv && source .venv/bin/activate
uv pip install -e ".[accel]"
For More details:
- Install FreeToken
- Quick start
- Supported models
- CLI reference
- Repairing old FTW checkpoints
- Diagnosing a checkpoint that fails to load
Citation
If you use FreeToken for your research, please cite our paper:
@article{yang2026freetoken,
  title={FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution},
  author={Yang, Shuo and Fan, Xiaoze and Pan, Melissa and Xi, Haocheng and Wang, Zhe and Sun, Shanlin and Keutzer, Kurt and Han, Song and Zaharia, Matei and Xu, Chenfeng and Stoica, Ion},
  journal={arXiv preprint arXiv:2608.16157},
  year={2026}
}
Acknowledgment
FreeToken was deeply inspired by mini-sglang, and learned the design and reused code from the following projects: SGLang, vLLM, FlashInfer, flash-linear-attention, LightLLM and llama.cpp.