
ByteDance-Seed/Seed-Thinking-v1.5
ByteDance-Seed/Seed-Thinking-v1.5 has 812 GitHub stars and 19 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-21 07:19 UTC. Last push 2025-06-09.
측정된 스타 증가
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
소개
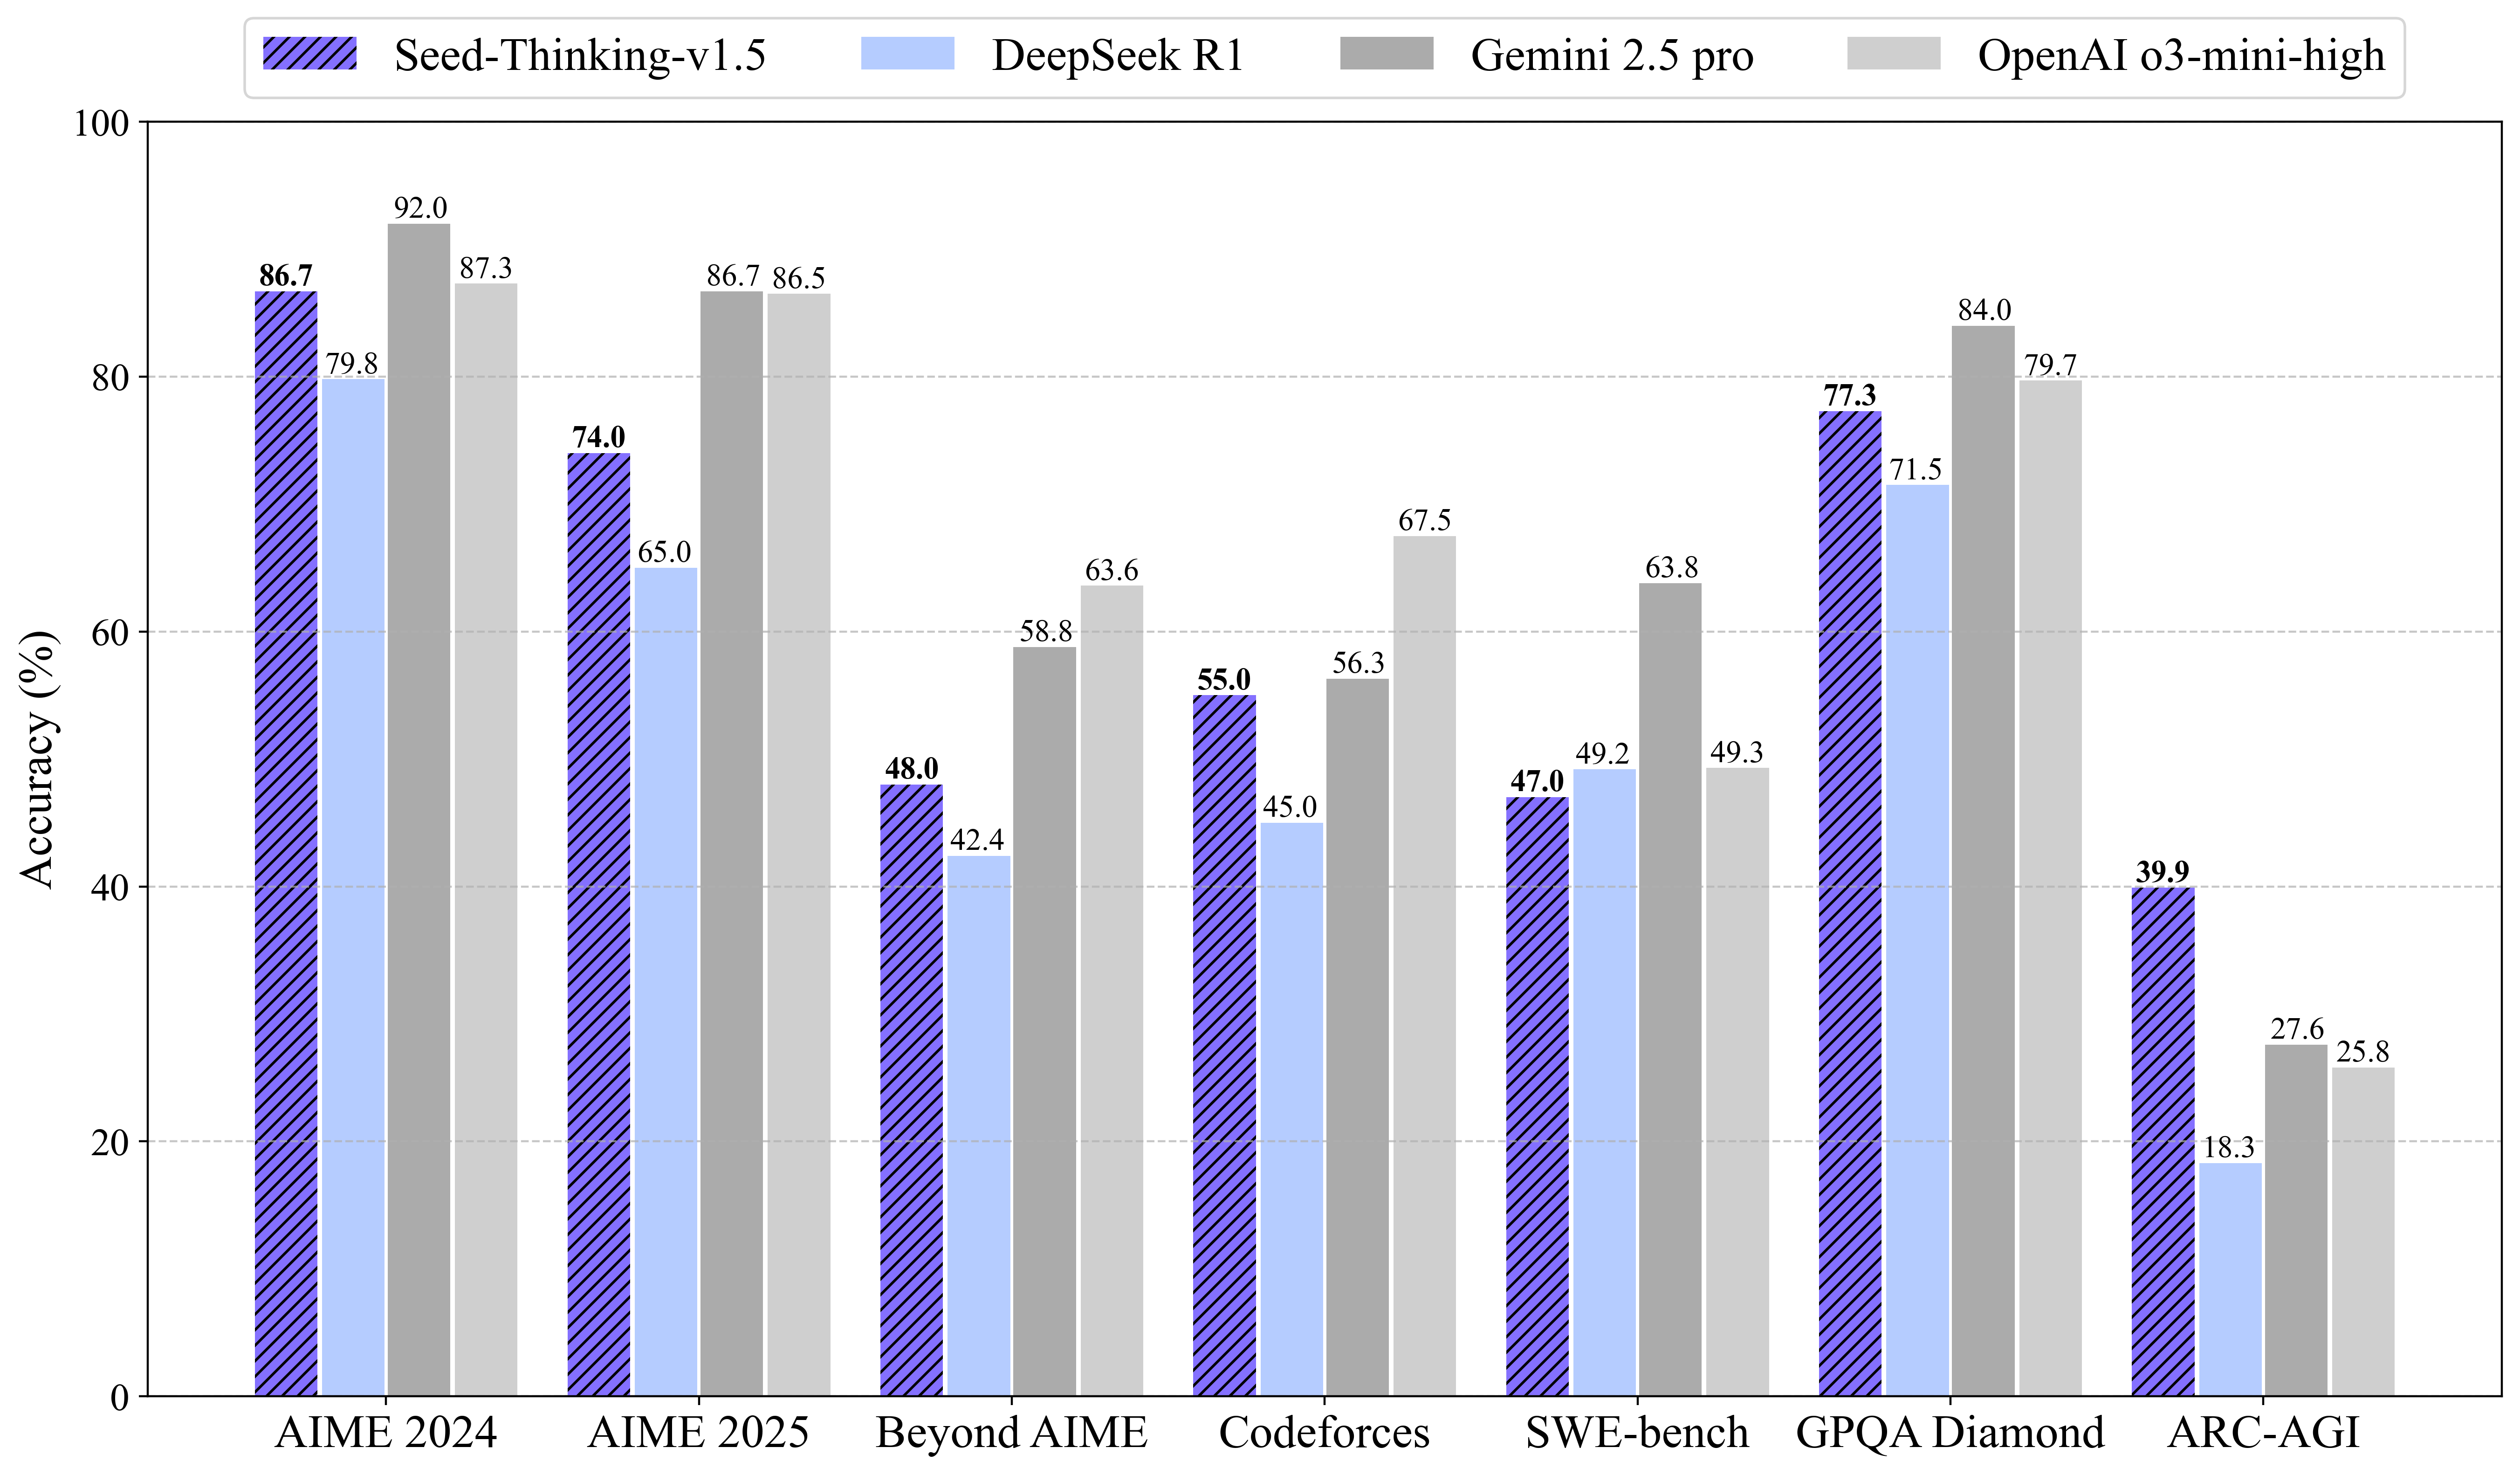
We introduce Seed-Thinking-v1.5, capable of reasoning through thinking before responding, resulting in improved performance on a wide range of benchmarks. Seed-Thinking-v1.5 achieves 86.7 on AIME 2024, 55.0 on Codeforces and 77.3 on GPQA, demonstrating excellent reasoning abilities in STEM and coding. Beyond reasoning tasks, the method demonstrates notable generalization across diverse domains. For instance, it surpasses DeepSeek R1 by 8% in win rate on non-reasoning tasks, indicating its broader applicability. Compared to other state-of-the-art reasoning models, Seed-Thinking-v1.5 is a Mixture-of-Experts (MoE) model with a relatively small size, featuring 20B activated and 200B total parameters. As part of our effort to assess generalized reasoning, we develop two internal benchmarks, BeyondAIME and Codeforces, both of which will be publicly released to support future research.
개발 도구README.md
OriginalSeed-Thinking-v1.5: Advancing Superb Reasoning Models with Reinforcement Learning
We introduce Seed-Thinking-v1.5, capable of reasoning through thinking before responding, resulting in improved performance on a wide range of benchmarks. Seed-Thinking-v1.5 achieves 86.7 on AIME 2024, 55.0 on Codeforces and 77.3 on GPQA, demonstrating excellent reasoning abilities in STEM and coding. Beyond reasoning tasks, the method demonstrates notable generalization across diverse domains. For instance, it surpasses DeepSeek R1 by 8% in win rate on non-reasoning tasks, indicating its broader applicability. Compared to other state-of-the-art reasoning models, Seed-Thinking-v1.5 is a Mixture-of-Experts (MoE) model with a relatively small size, featuring 20B activated and 200B total parameters. As part of our effort to assess generalized reasoning, we develop two internal benchmarks, BeyondAIME and Codeforces, both of which will be publicly released to support future research.
Technical Details
Full technical details can be found in our technical report.
Full Results
We present the evaluation results across diverse tasks spanning mathematics, coding, science, and general knowledge domains.
| Benchmark | Seed-Thinking-v1.5 | DeepSeek R1 | OpenAI o3-mini | Grok 3 Beta | Gemini 2.5 pro |
|---|---|---|---|---|---|
| Mathematics | |||||
| AIME 2025 | 74.0% | 65.0% | 86.5% | 77.3% | 86.7% 🏆 |
| AIME 2024 | 86.7% | 79.8% | 87.3% | 83.9% | 92.0% 🏆 |
| Beyond AIME | 48.0% | 42.4% | 63.6% 🏆 | - | 58.8% |
| Science | |||||
| GPQA diamond | 77.3% | 71.5% | 79.7% | 80.2% | 84.0% 🏆 |
| SuperGPQA | 62.1% | 60.5% | 52.2% | 62.8% | 65.3% 🏆 |
| MMLU-PRO | 87.0% 🏆 | 85.6% | 82.4% | 84.6% | 86.3% |
| Code | |||||
| Codeforces avg@8 | 36.3% | 32.0% | 50.9% 🏆 | - | 40.3% |
| Codeforces pass@8 | 55.0% | 45.0% | 67.5% 🏆 | - | 56.3% |
| LiveCodeBench v5 | 64.9% | 64.3% | 74.1% 🏆 | 70.6% | 70.4% |
| Aider Polyglot | 54.2% | 56.9% | 68.6% | - | 74.0% 🏆 |
| Agentic Coding | |||||
| SWE-bench verified | 47.0% | 49.2% | 49.3% | - | 63.8% 🏆 |
| SWE-bench verified* | 47.0% | 46.2% | 44.5% | - | 63.8% 🏆 |
| Logic reasoning | |||||
| ARC-AGI | 39.9% 🏆 | 18.3% | 25.8% | 31.9% | 27.6% |
| Factuality | |||||
| SimpleQA | 12.9% | 30.1% | 13.8% | 43.6% | 52.9% 🏆 |
| Instruction | |||||
| Collie | 73.1% | 34.2% | 87.6% 🏆 | 33.6% | 62.5% |
| IFEval | 87.4% | 86.1% | 93.7% 🏆 | 83.4% | 91.5% |
* Results from our internal sandbox, which may differ from the reported results due to inconsistencies in the testing environment.