
ArroyoSystems/arroyo
ArroyoSystems/arroyo has 5,078 GitHub stars and 386 forks. GitHot measured +3 in 7 days. Last checked 2026-11-11 07:01 UTC. Last push 2026-11-10.
Distributed stream processing engine in Rust
측정된 스타 증가
- in 24h
- 업데이트 지연
- in 7 days
- +3
- in 15 days
- 기록 수집 중
- in 1 month
- 기록 수집 중
서로 겹치는 기간의 순증가량이며 일별 합계가 아닙니다. 측정값이 없으면 비워 둡니다. 스타는 관심도를 나타내며 품질을 보장하지 않습니다.
README.md
Original
Getting started | Docs | Discord | Website


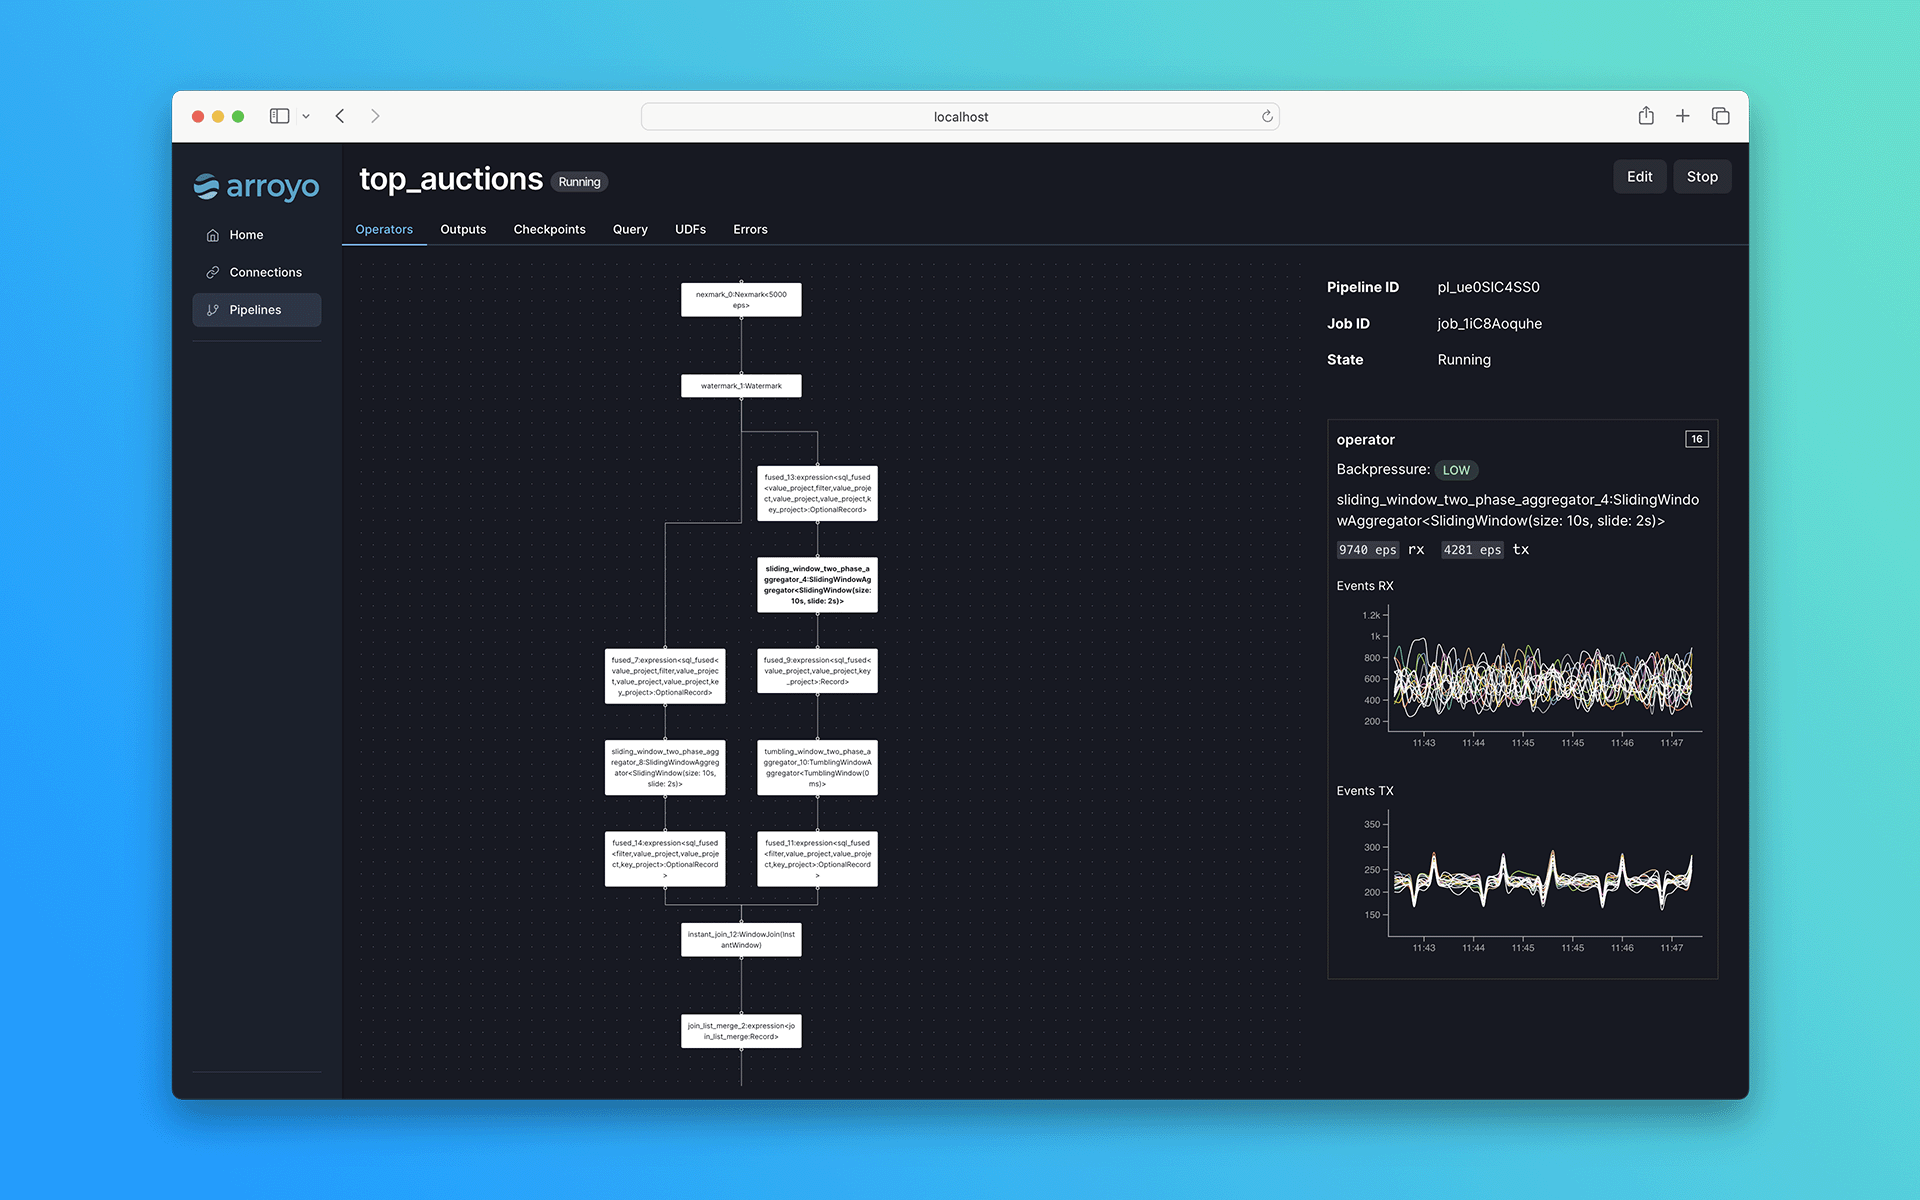
Arroyo is a distributed stream processing engine written in Rust, designed to efficiently perform stateful computations on streams of data. Unlike traditional batch processing, streaming engines can operate on both bounded and unbounded sources, emitting results as soon as they are available.
In short: Arroyo lets you ask complex questions of high-volume real-time data with subsecond results.
Features
🦀 SQL streaming pipelines
🚀 Scales up to millions of events per second
🪟 Stateful operations including windows and joins
🔥State checkpointing for fault-tolerance and recovery of pipelines
🕒 Time-oriented stream processing via the Dataflow model
🔌 A wide variety of connectors, including Kafka and Iceberg
Use cases
Some example use cases include:
- Detecting fraud and security incidents
- Real-time product and business analytics
- Real-time ingestion into your data warehouse or data lake
- Real-time ML feature generation
Why Arroyo
There are already a number of existing streaming engines out there, including Apache Flink, Spark Streaming, and Kafka Streams. Why create a new one?
- Serverless operations: Arroyo pipelines are designed to run in modern cloud environments, supporting seamless scaling, recovery, and rescheduling
- High performance SQL: SQL is a first-class concern, with consistently excellent performance
- Designed for non-experts: Arroyo cleanly separates the pipeline APIs from its internal implementation. You don't need to be a streaming expert to build real-time data pipelines.
Installing
Arroyo ships as a single binary. You can install it locally on MacOS using Homebrew
brew install arroyosystems/tap/arroyo
or on MacOS or Linux with this script:
curl -LsSf https://arroyo.dev/install.sh | sh
or you can download a binary for your platform from the releases page.
Once you have Arroyo installed, start a cluster with
$ arroyo cluster
You can also run a cluster in Docker, with
docker run -p 5115:5115 \
      ghcr.io/arroyosystems/arroyo:latest
Then, load the Web UI at http://localhost:5115.
For a more in-depth guide, see the getting started guide.
Once you have Arroyo running, follow the tutorial to create your first real-time pipeline.
Cloudflare Pipelines
If you don't want to self-host, Arroyo is available as a fully-managed solution on the Cloudflare Developer Platform: Cloudflare Pipelines, now available in beta. Currently, stateless pipelines ingesting into R2 are supported, and we'll be expanding to stateful pipelines in the near future.
Developing Arroyo
We love contributions from the community! See the developer setup guide to get started, and reach out to the team on discord or create an issue.
Community
- Discord — support and project discussion
- GitHub issues — bugs and feature requests
- Arroyo Blog — updates from the Arroyo team
관련 프로젝트 살펴보기
Asabeneh/30-Days-Of-Python
30 Days of Python 프로그래밍 챌린지는 Python 프로그래밍 언어를 30일 동안 배우기 위한 단계별 가이드입니다. 이 챌린지는 100일 이상 걸릴 수 있습니다. 자신의 속도에 맞춰 진행하세요. 다음 동영상도 도움이 될 수 있습니다: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 스타grafana/grafana
개방적이고 조합 가능한 옵저버빌리티 및 데이터 시각화 플랫폼입니다. Prometheus, Loki, Elasticsearch, InfluxDB, Postgres 등 여러 소스의 메트릭, 로그, 트레이스를 시각화합니다.
77,830 스타redis/redis
실시간 데이터 기반 애플리케이션을 구축하는 개발자에게 Redis는 가장 선호되고, 가장 빠르며, 기능이 가장 풍부한 캐시, 데이터 구조 서버이자 문서 및 벡터 쿼리 엔진입니다.
77,395 스타apache/superset
Apache Superset는 데이터 시각화 및 데이터 탐색 플랫폼입니다.
75,473 스타