
OUI-Master-Database
Ringmast4r
149スター
MAC address manufacturer lookup database combining IEEE, Nmap, Wireshark and HDM Mac-Tracker, with downloadable formats and a browser lookup. https://ringmast4r.github.io/OUI-Master-Database/
データベース、分析、SQL、データエンジニアリングのプロジェクトを比較できます。
Ringmast4r
MAC address manufacturer lookup database combining IEEE, Nmap, Wireshark and HDM Mac-Tracker, with downloadable formats and a browser lookup. https://ringmast4r.github.io/OUI-Master-Database/

rogerpadilla
JSON-native TypeScript ORM for Bun, Browsers, Edge, Node, Workers

Ronitsabhaya75
Streams changes from a FoundationDB directory to a Kafka topic using FDB's native CDC. See Proposal.md for scope and design.

rosedblabs
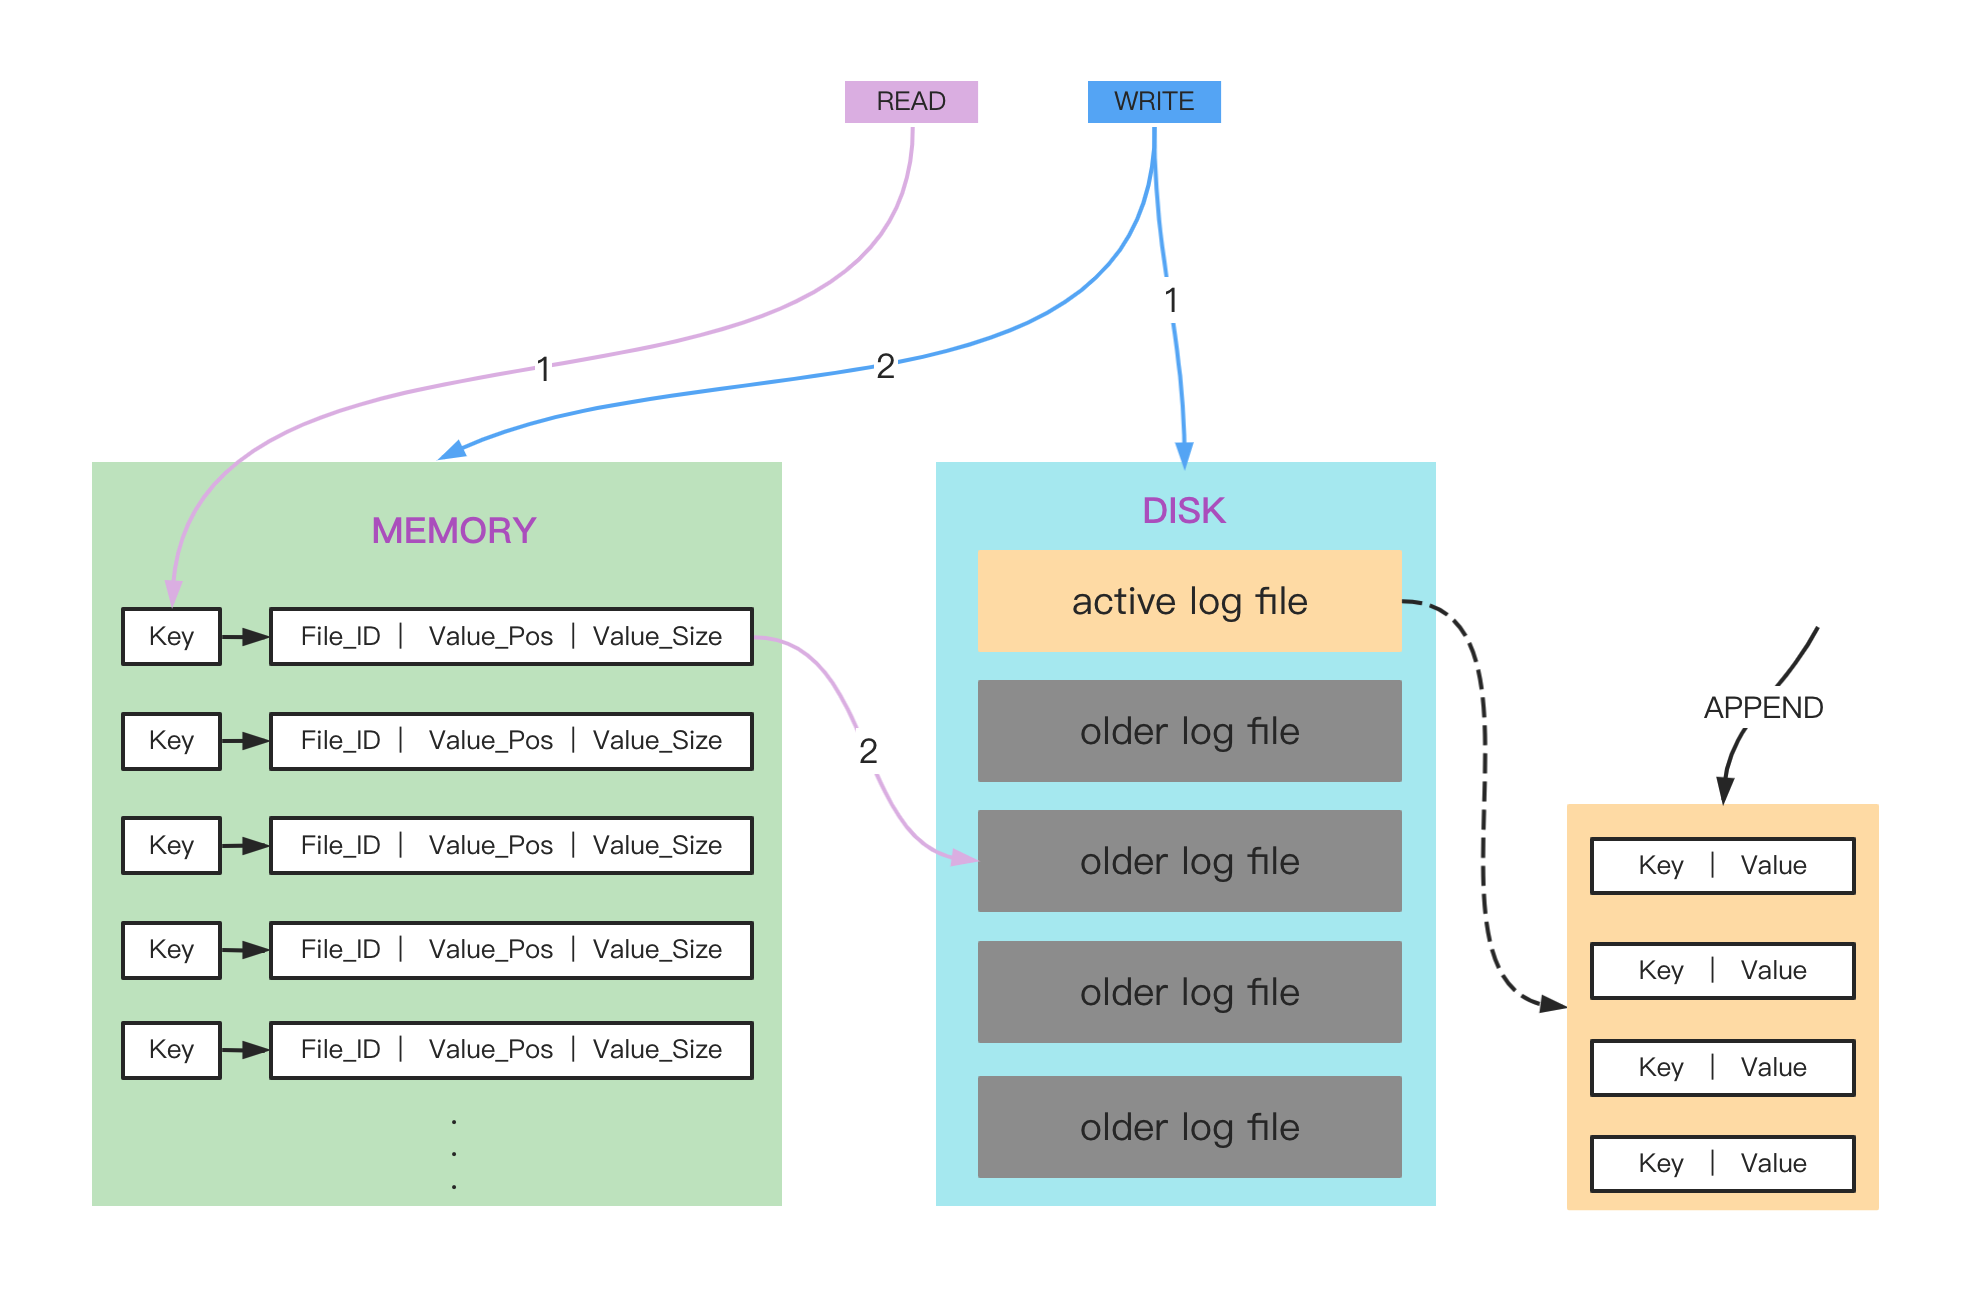
Lightweight, fast and reliable key/value storage engine based on Bitcask.

RyanJHamby
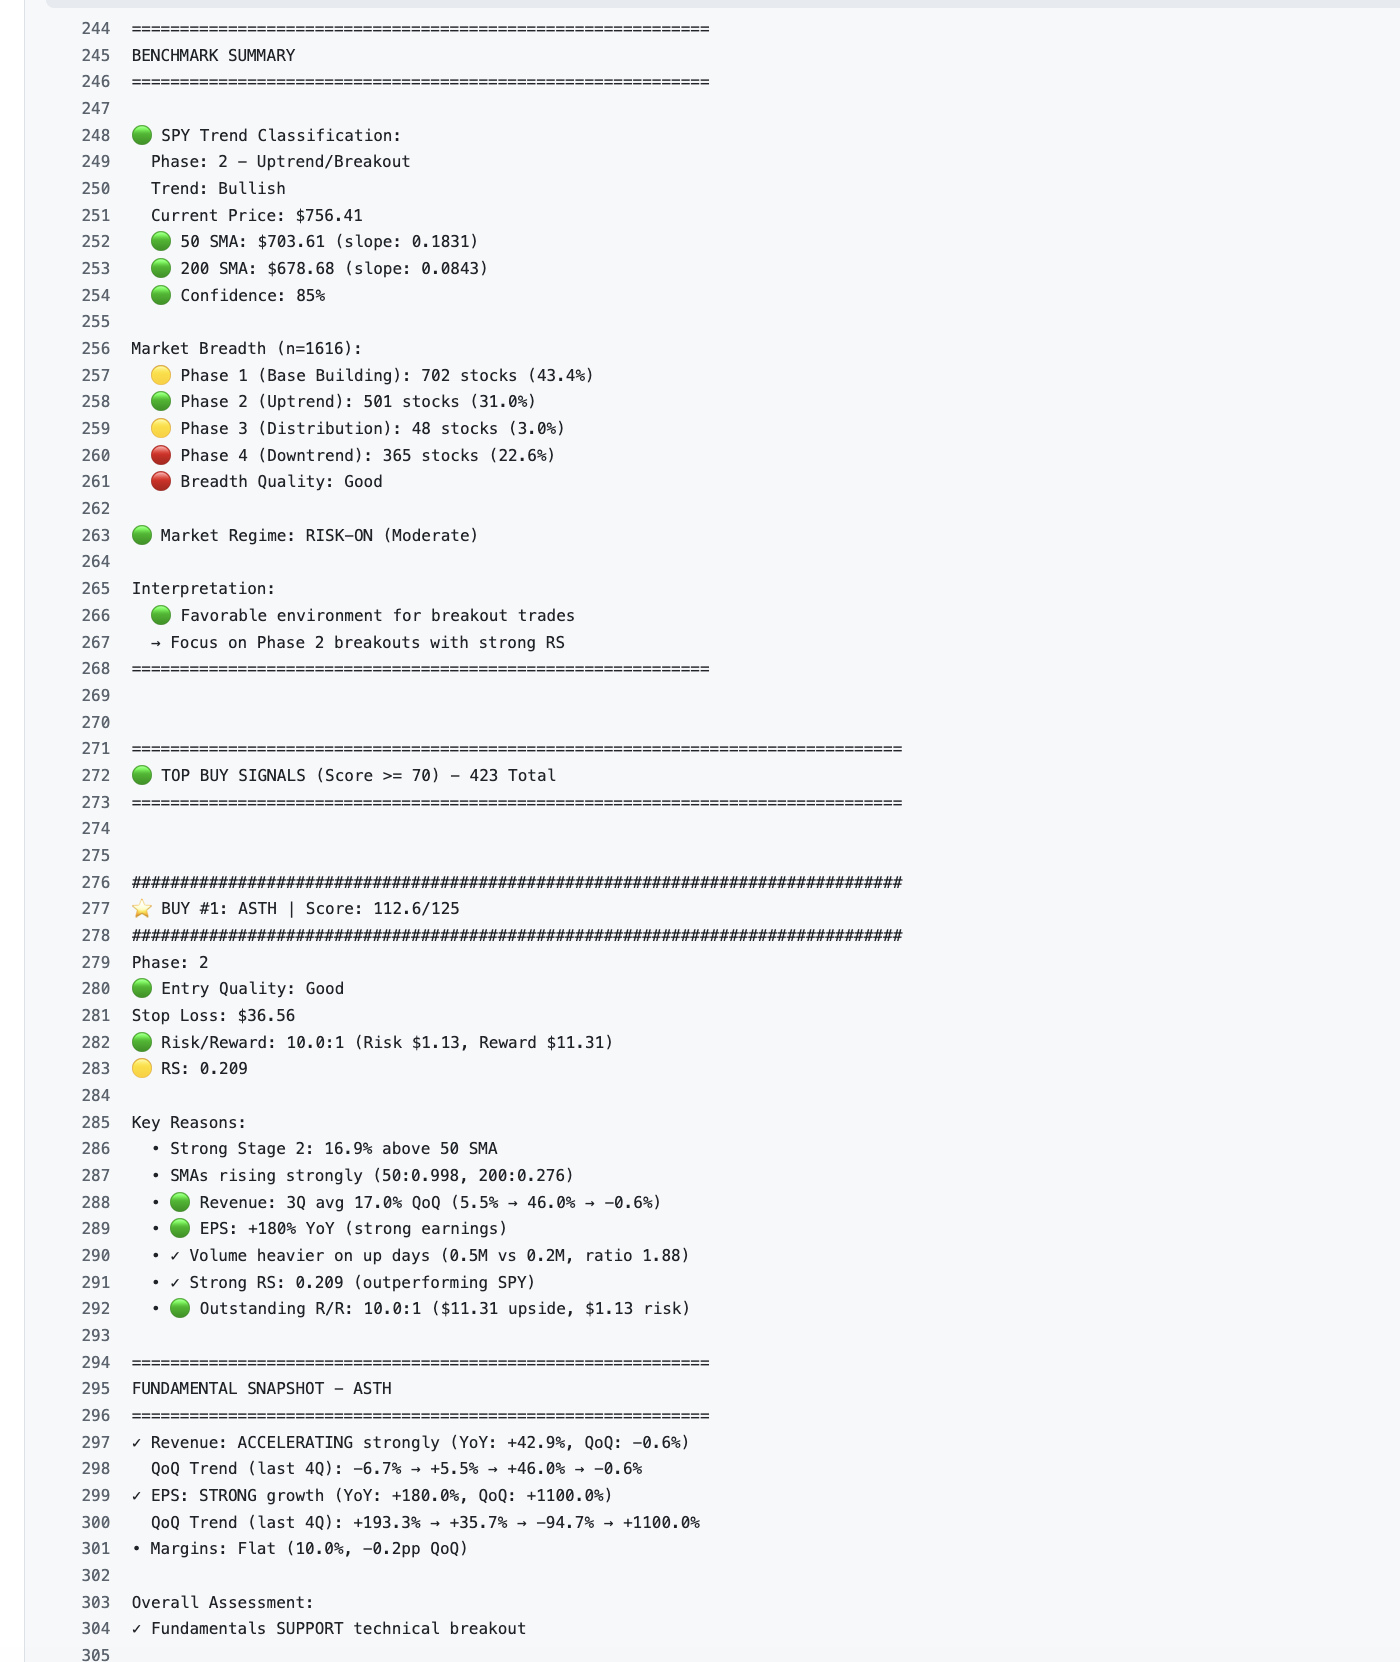
Automated stock screener scanning 3,800+ stocks daily for confirmed Stage 2 uptrends passing 8 strict criteria. Features: smart caching (74% fewer API calls), market regime filtering, automated stop-loss calculation, and GitHub Actions automation. Follows Mark Minervini's Trend Template.

scriptella

Scriptella is an open source ETL (Extract-Transform-Load) and script execution tool written in Java.

SecureWithUmer
Exploit-Index : The Ultimate CVE Proof of Concept (PoC) & Exploit Database. A zero-API, high-performance aggregator for 0days, vulnerabilities, and Threat Intelligence. Replacing manual searches for elite SOC teams, DevSecOps, and Bug Bounty Hunters.

SpaceCell
Fast, minimal, and ergonomic zero-copy Apache Arrow tabular data implementation in Rust, with PyO3, Python bindings, NdArray, XArray, shared-memory and low-latency SIMD for data-engineering and columnar workloads. Bridge to Polars and Arrow-rs over FFI effortlessly.
SpaceCell
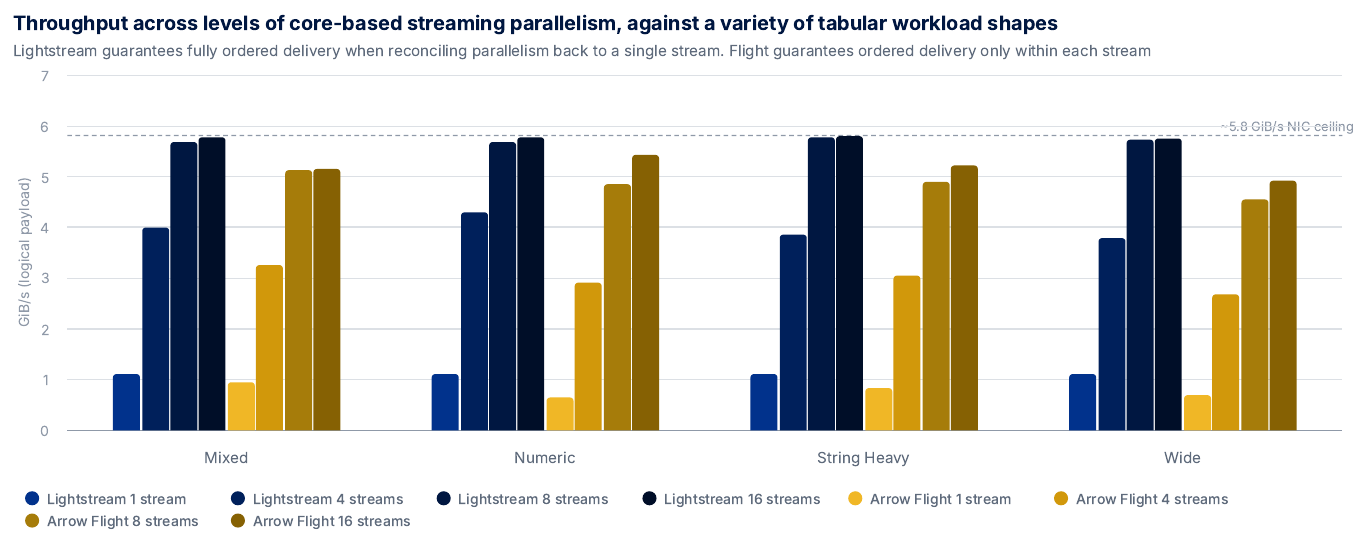
Fast data transport : Apache Arrow, Protobuf and Message Pack data on the one stream. Measured faster than Arrow Flight on all open benchmarks. HTTP, TCP, QUIC, Websocket, Webtransport, Stdio, UDS, all interchangeable, with 64-byte SIMD compatibilty maintained over the network and to/from disk via custom Arrow Mmap and Parquet Readers and Writers

sqlstack-io
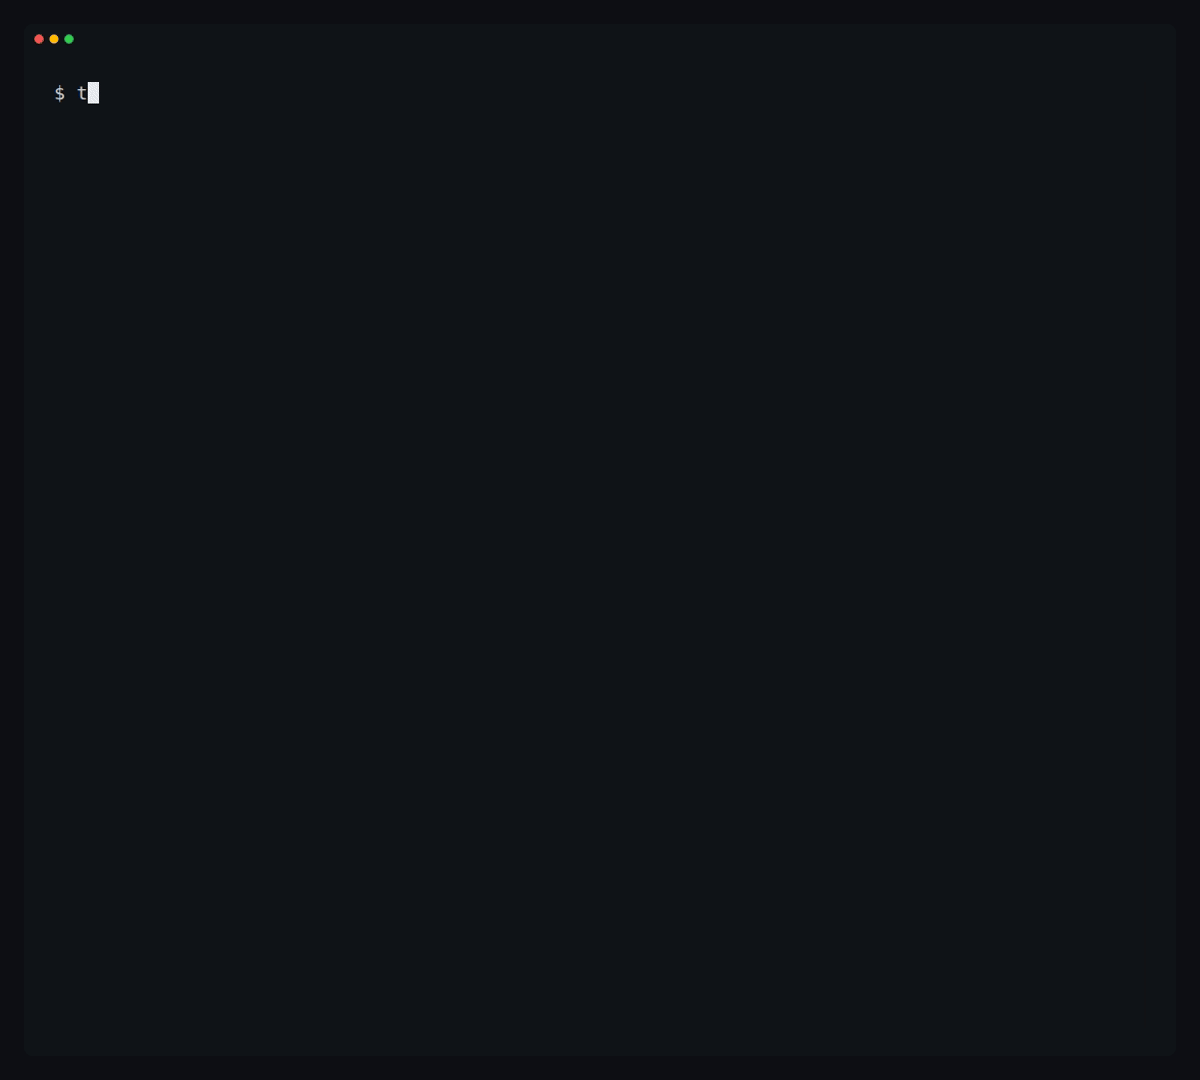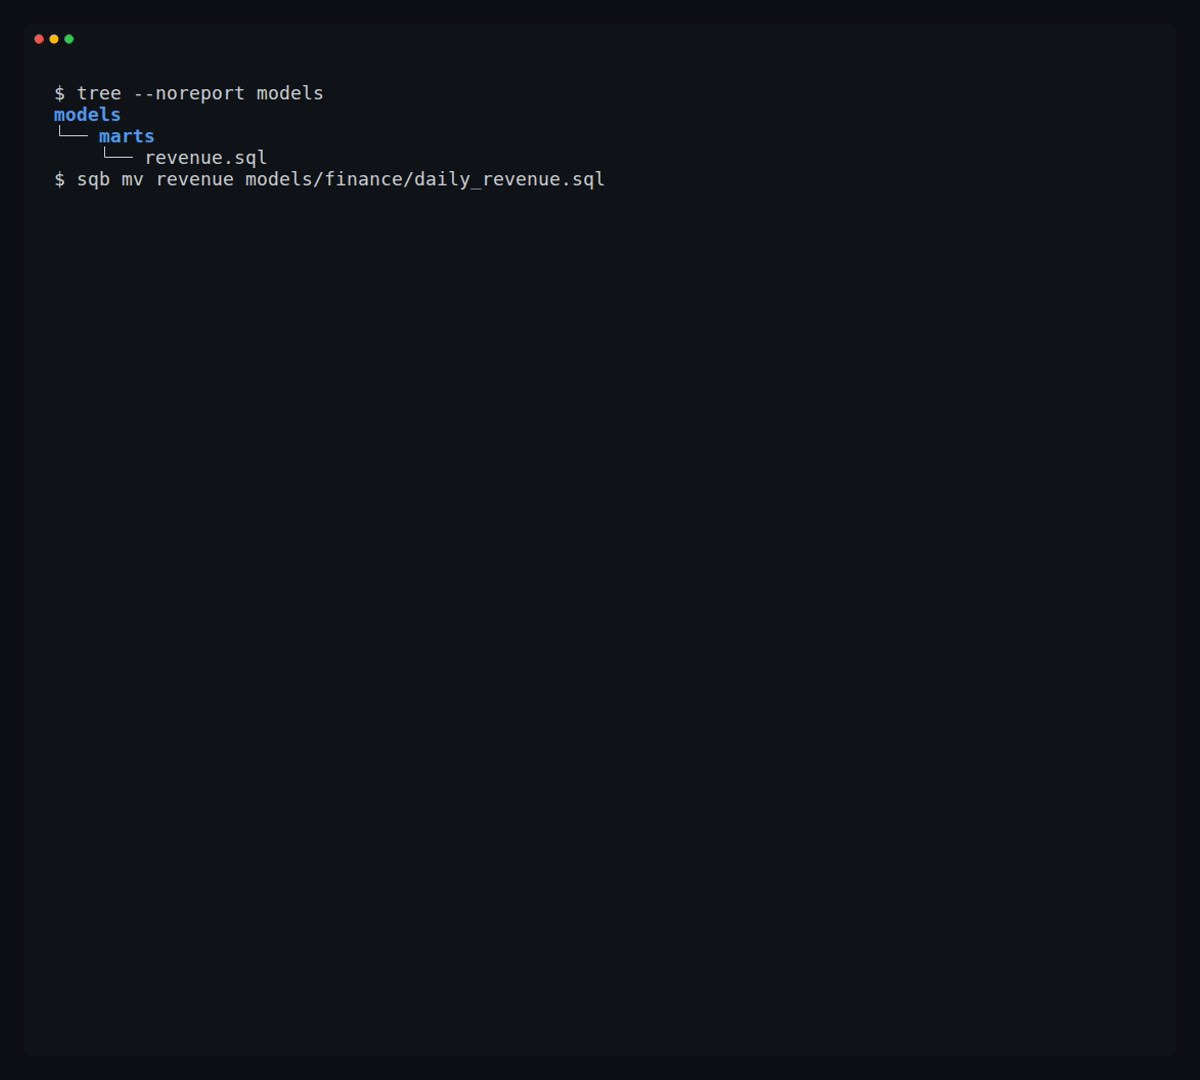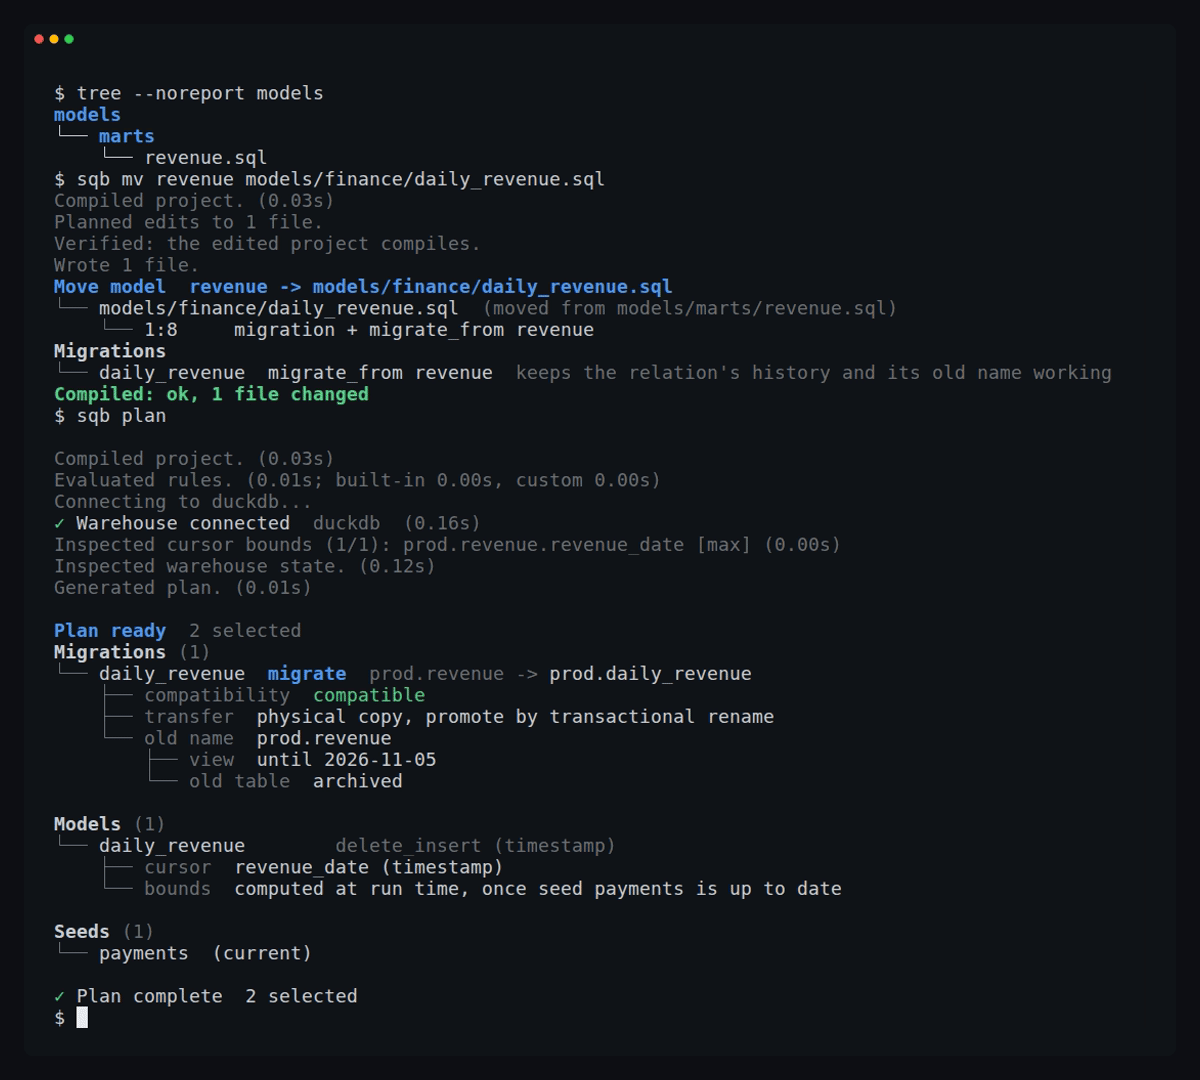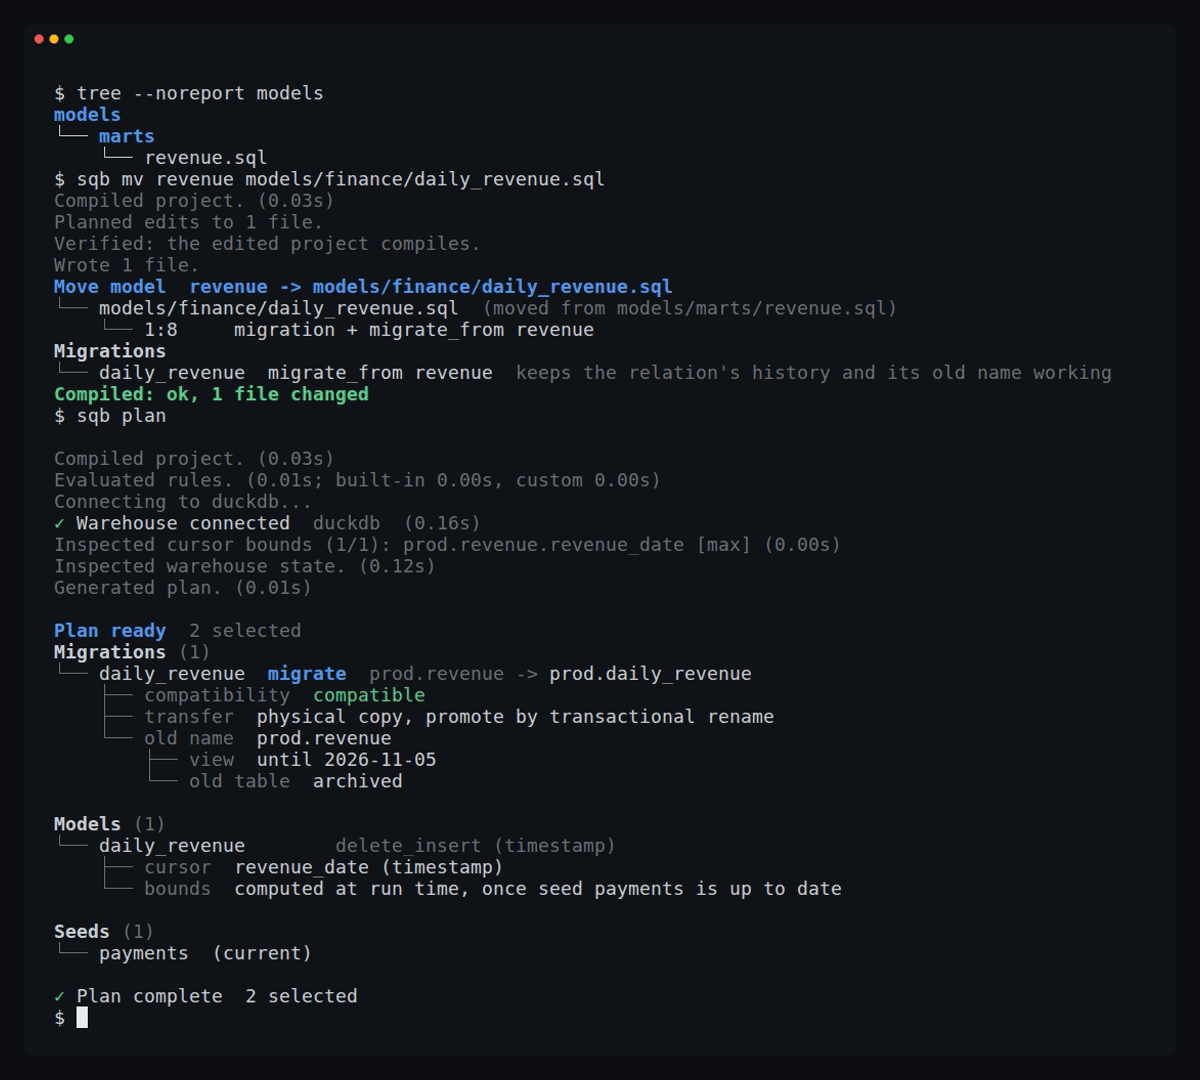
SQL transformation framework with custom compile-time checks, end-to-end testing and safe renames that keep your table history.

Srlion
Easily connect to MySQL in Garry's Mod using Rust binary!

stimulsoft
Stimulsoft Reports.JS is a reporting tool for Node.js and JavaScript applications.

superfly
FUSE-based file system for replicating SQLite databases across a cluster of machines

surrealdb
SurrealDB SDK for Python

tabsdata
Agentic data engineering built on Pub/Sub for Tables. Discover, publish, transform and consume data as versioned tables with lineage, with an AI agent doing the assembly and the engineer approving.

tempoxyz
tidx indexes Tempo chain data into a hybrid PostgreSQL + ClickHouse architecture for fast point lookups (OLTP) and lightning-fast analytics (OLAP).

terbed
An open-source, lightweight, and blazing-fast financial machine learning library built with Numba. Process raw trades, generate advanced bars, features, and labels for quantitative research.

thedataquarry
Journeys between the two worlds of Python 🐍 and Rust 🦀

ThisTakou
Automated User-Agent database for 100+ browsers on 100+ operating systems. Updated every 5 minutes via GitHub Actions. Weighted by real-world popularity, grouped by OS and browser, with a cumulative ALL/ folder of unique agents.

tidwall
BuntDB is an embeddable, in-memory key/value database for Go with custom indexing and geospatial support

tosun-si
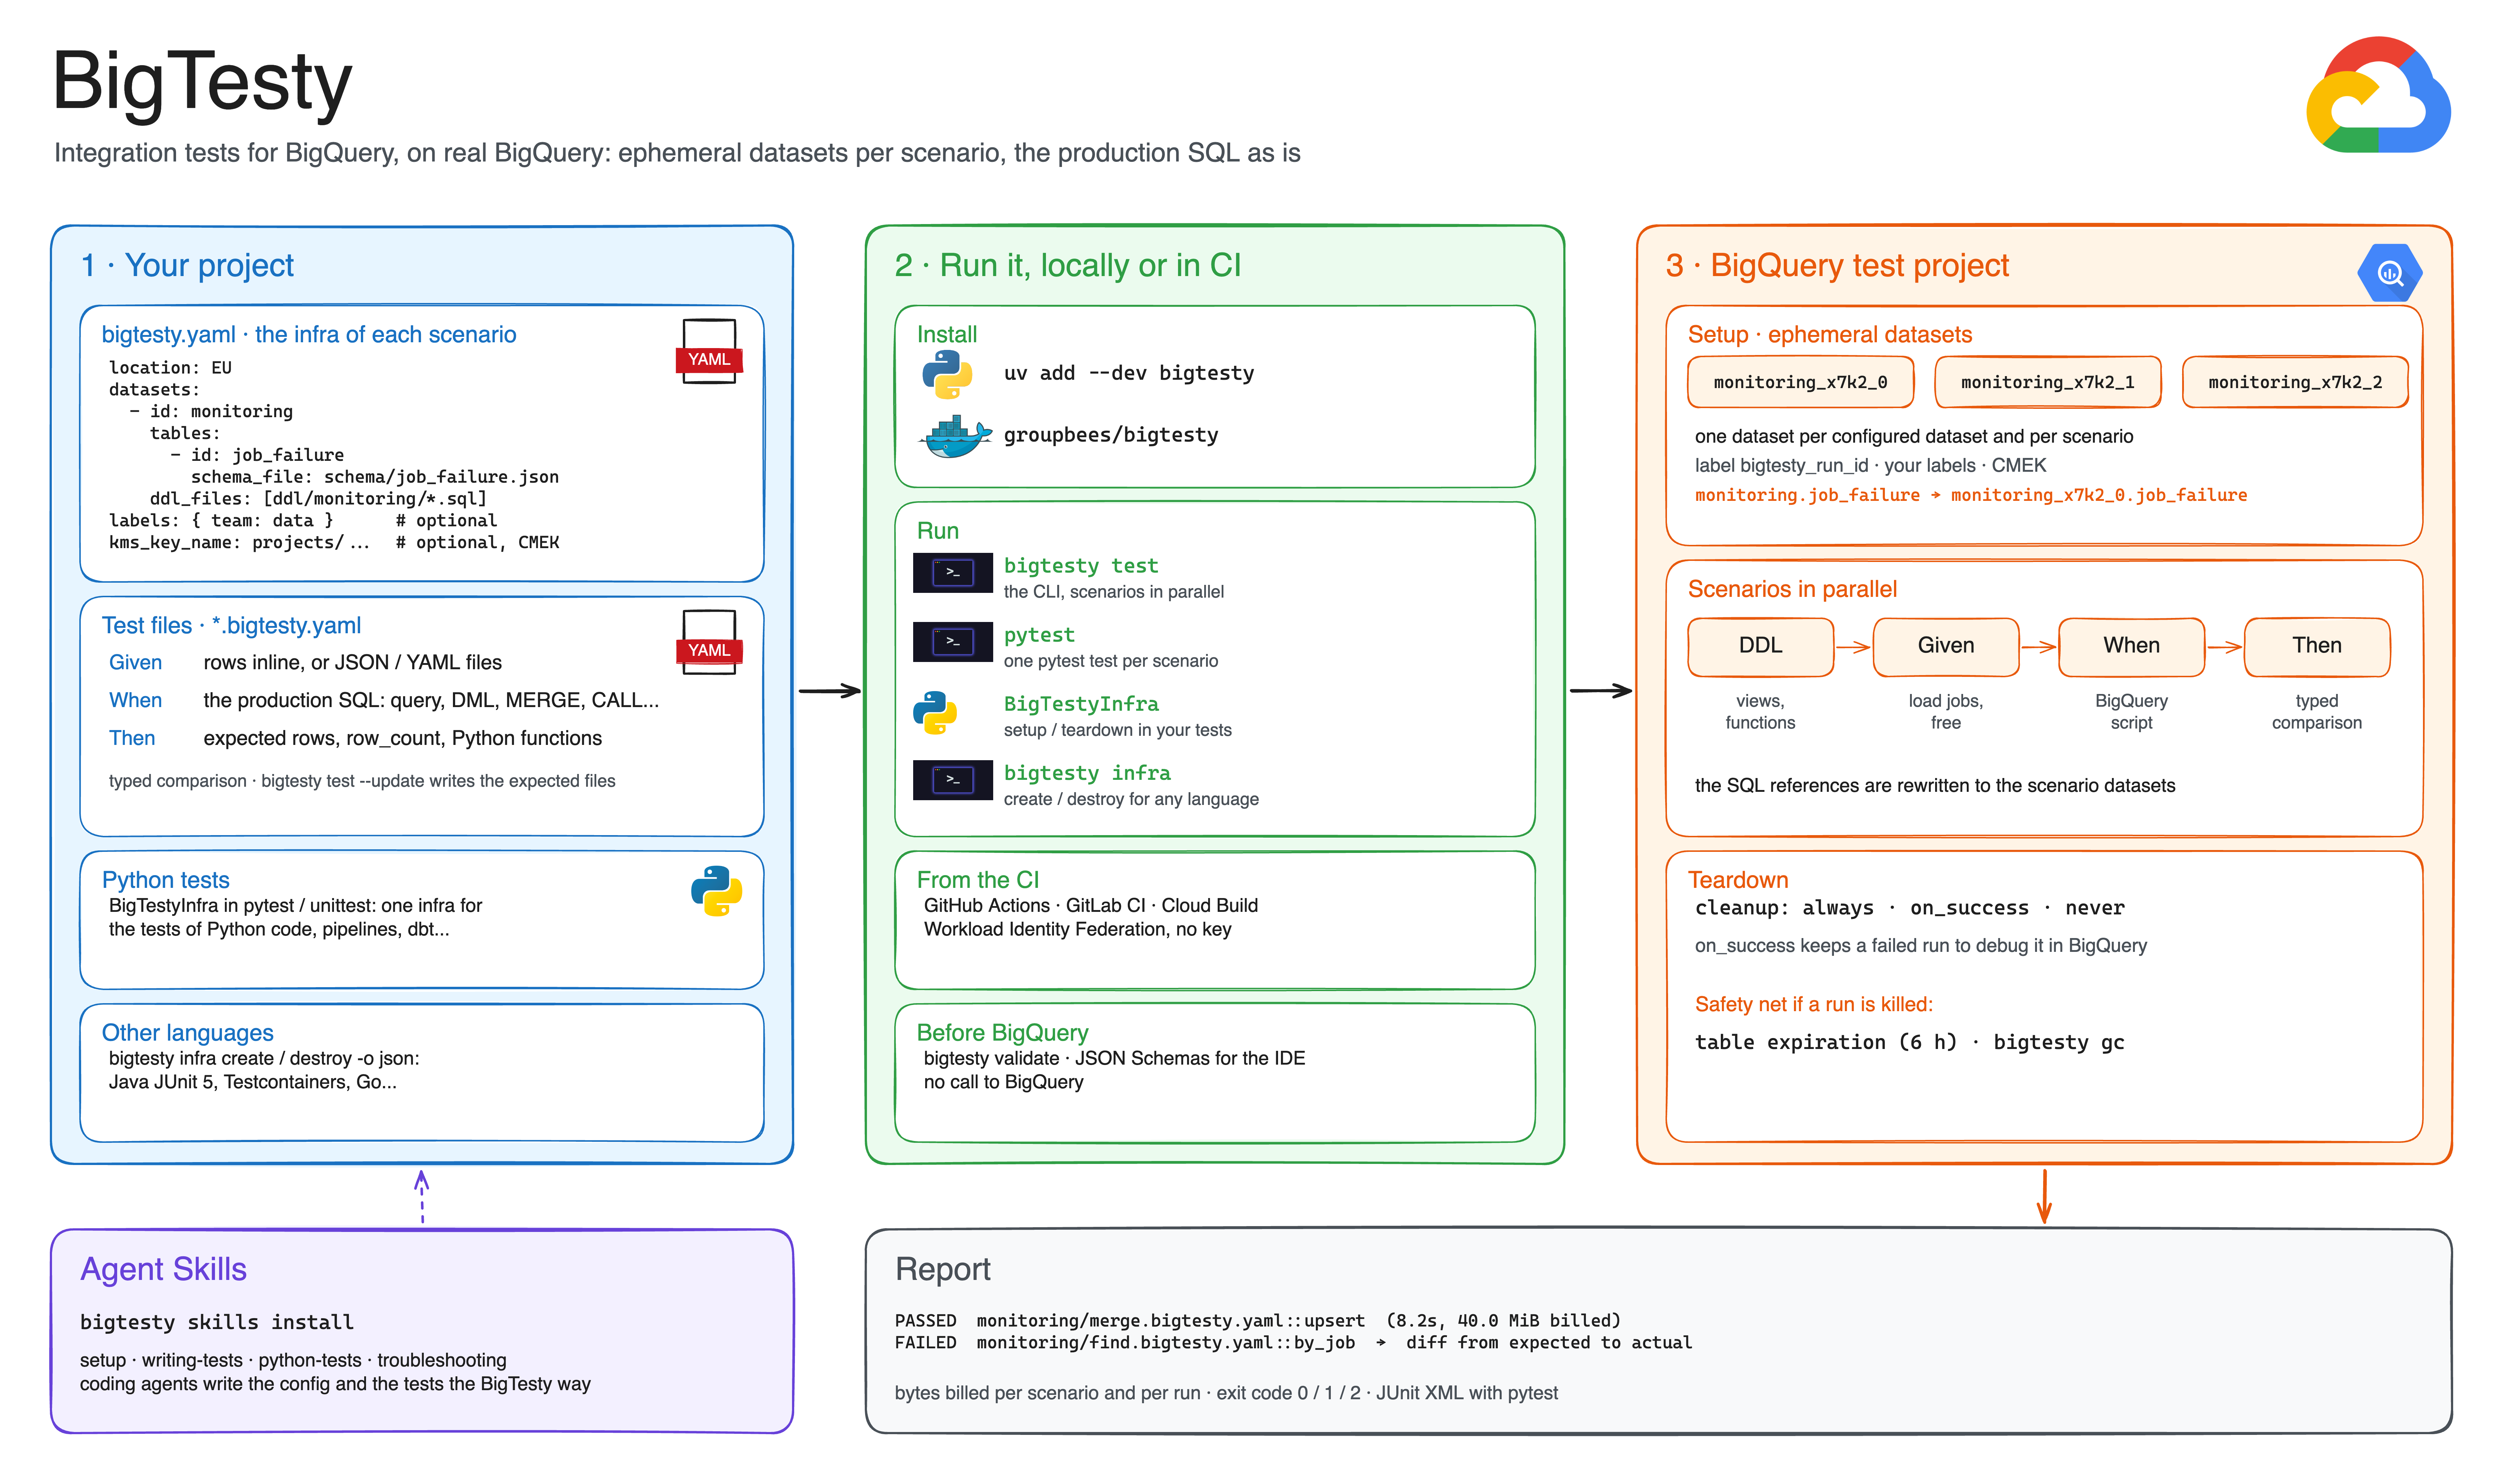
Integration tests for BigQuery SQL, on the real engine and ephemeral datasets: YAML, pytest and any language.

trilogy-data
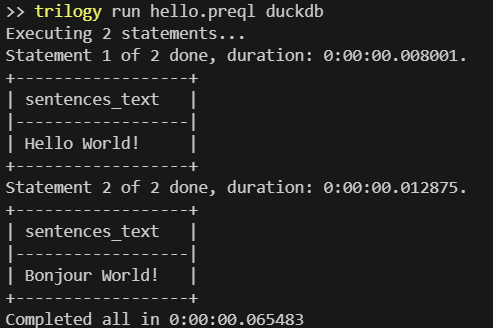
Can we improve the best language for data analytics? Strongly typed, composable, cross-engine SQL. More declarative and expressive, safer, and simpler for humans and agents.

turing-db
TuringDB high performance in-memory column-oriented graph database engine

Victor-Kipruto-Rop
Built a scalable cloud ETL pipeline using Python, PostgreSQL, Pandas, and Docker to efficiently process, clean, and load over 1.6 million records with optimized batch processing, fault tolerance, and automated data validation.