
vaexio/vaex has 8,518 GitHub stars and 601 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and +2 in 15 days. Last checked 2026-11-21 01:06 UTC. Last push 2026-11-06.
できること
- Remote DataFrames (documentation coming soon)
- Integration into Jupyter and Voila for interactive notebooks and dashboards
- Machine Learning without (explicit) pipelines
計測したスター増加
- 24時間
- 0
- 7日間
- 0
- 15日間
- +2
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
Python、機械学習、可視化、大規模な表形式データの探索に対応する、毎秒10億行を処理できるアウトオブコア型のApache Arrow/NumPyハイブリッドDataFrame 🚀
機械学習README.md
オリジナル

What is Vaex?
Vaex is a high performance Python library for lazy Out-of-Core DataFrames
(similar to Pandas), to visualize and explore big tabular datasets. It
calculates statistics such as mean, sum, count, standard deviation etc, on an
N-dimensional grid for more than a billion (10^9) samples/rows per
second. Visualization is done using histograms, density plots and 3d
volume rendering, allowing interactive exploration of big data. Vaex uses
memory mapping, zero memory copy policy and lazy computations for best
performance (no memory wasted).
Installing
With pip:
$ pip install vaex
Or conda:
$ conda install -c conda-forge vaex
For more details, see the documentation
Key features
Instant opening of Huge data files (memory mapping)
HDF5 and Apache Arrow supported.

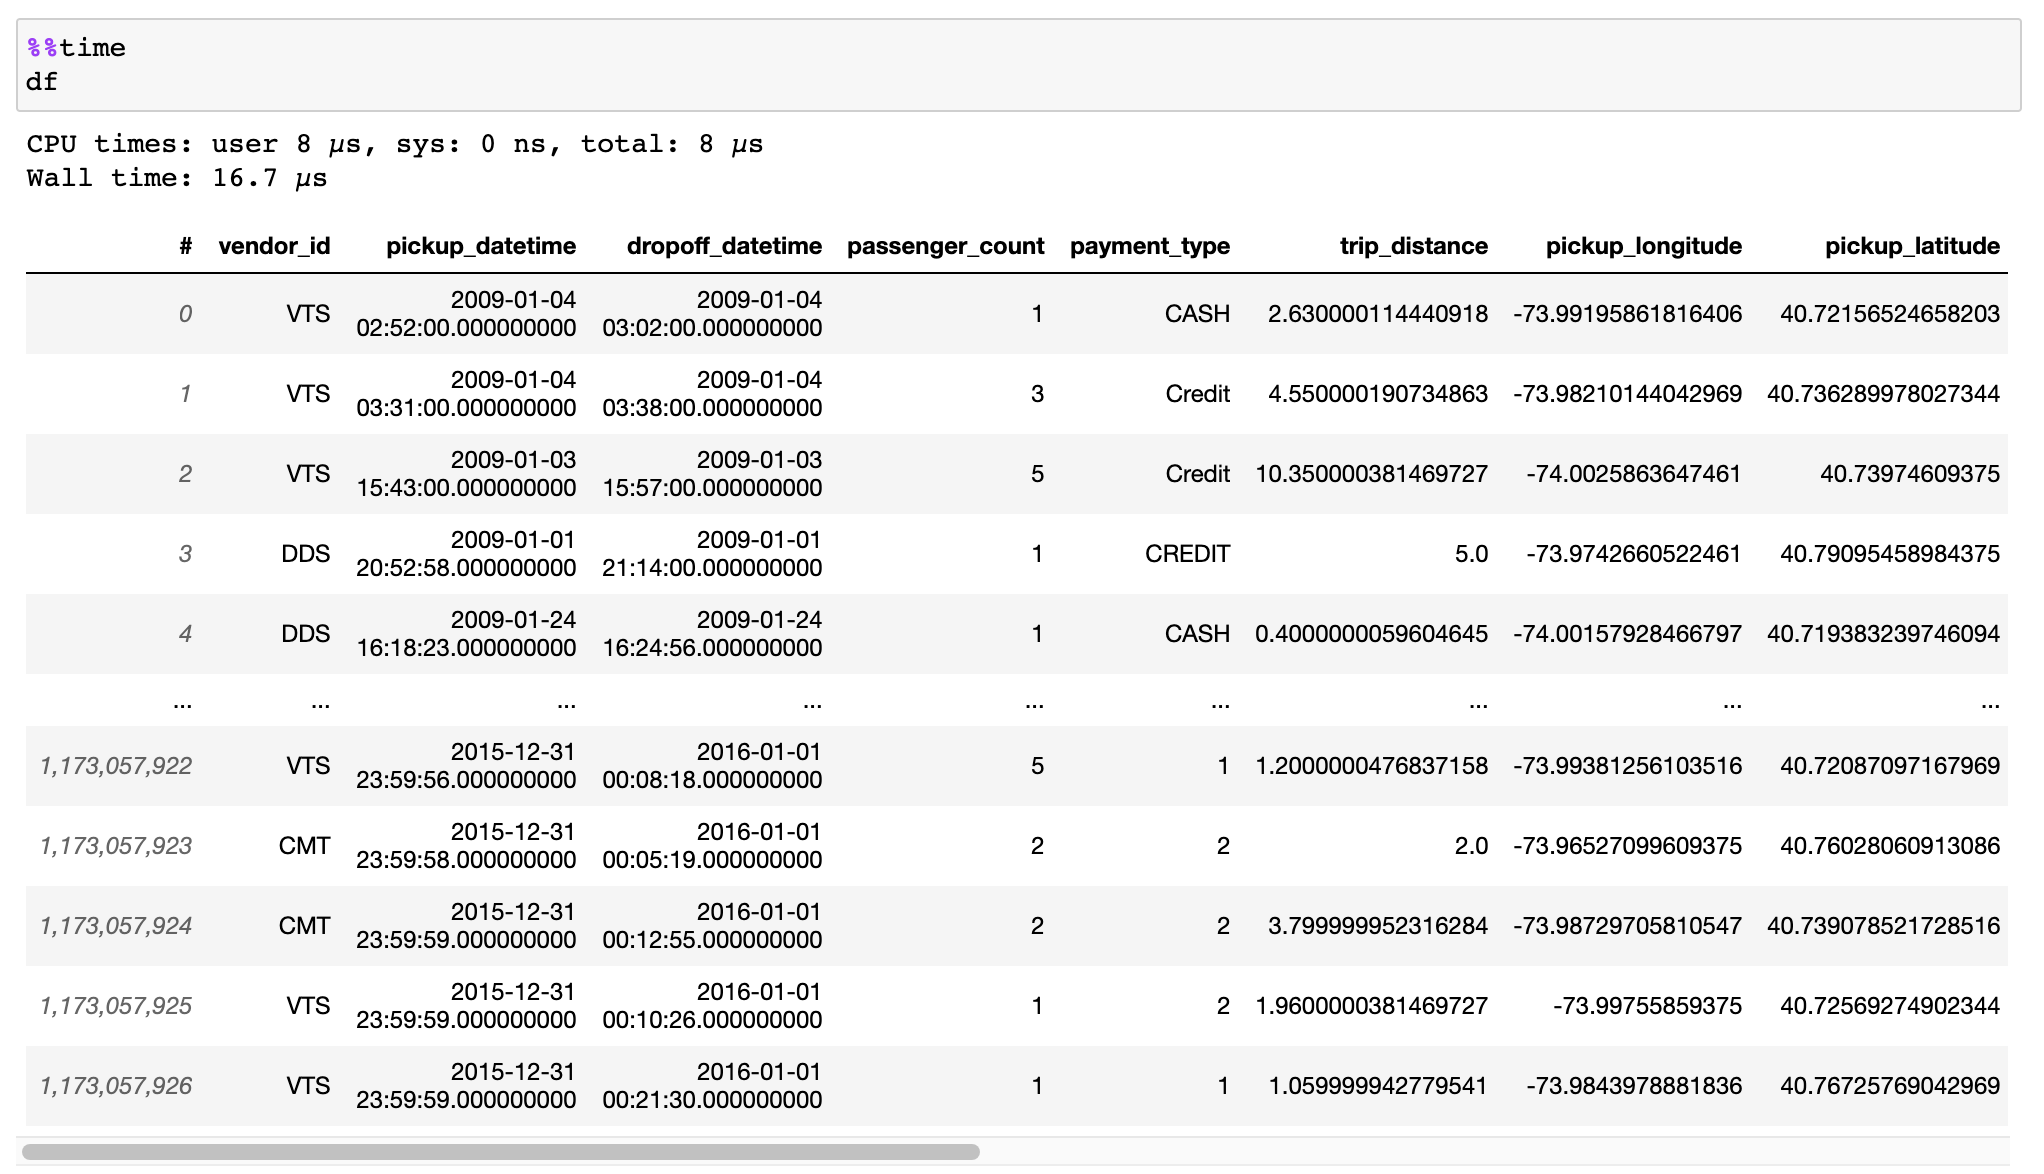
Read the documentation on how to efficiently convert your data from CSV files, Pandas DataFrames, or other sources.
Lazy streaming from S3 supported in combination with memory mapping.

Expression system
Don't waste memory or time with feature engineering, we (lazily) transform your data when needed.
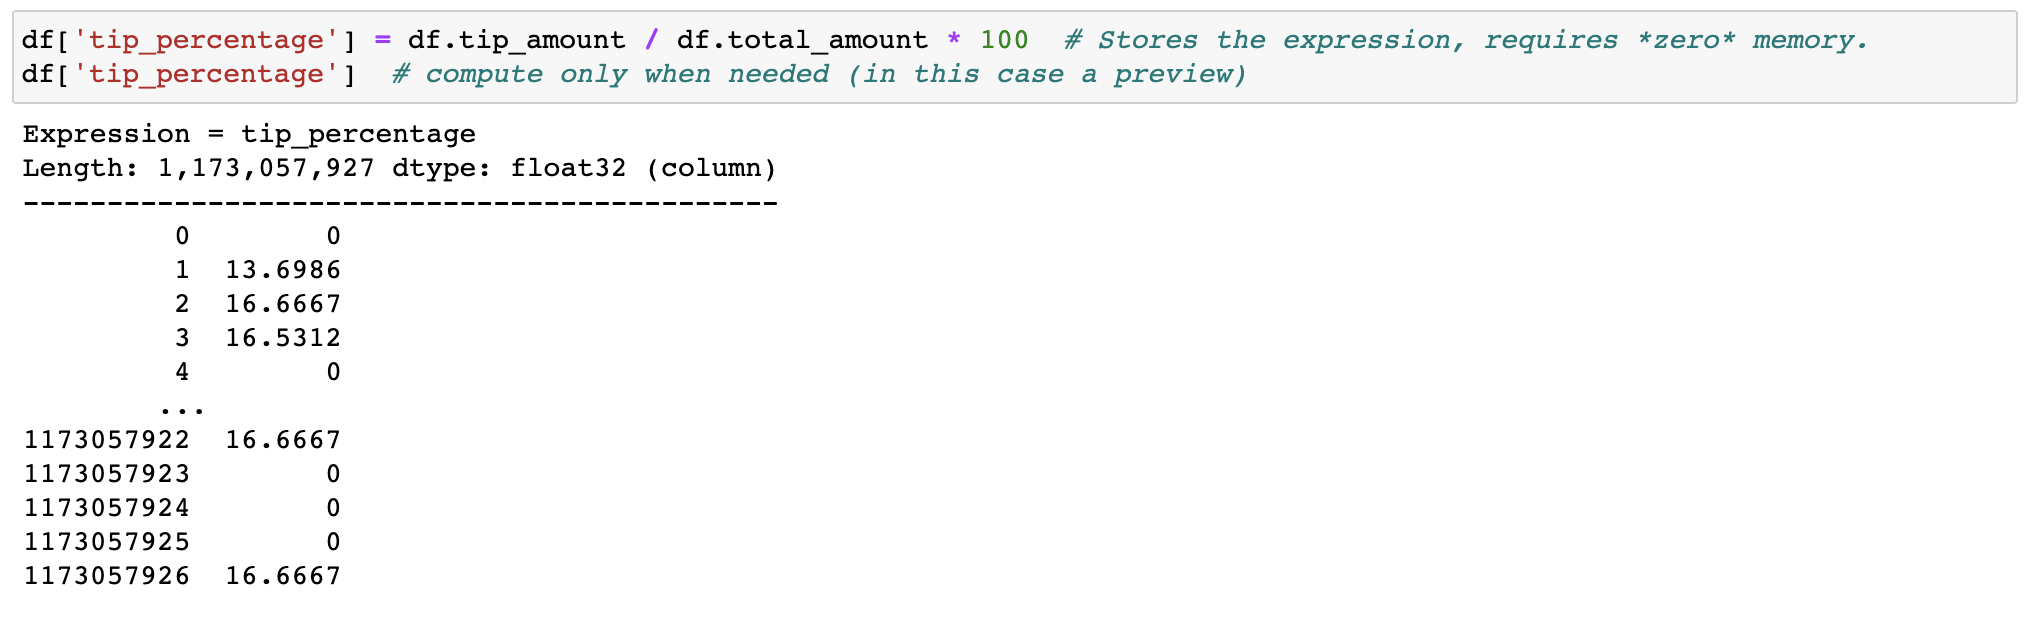
Out-of-core DataFrame
Filtering and evaluating expressions will not waste memory by making copies; the data is kept untouched on disk, and will be streamed only when needed. Delay the time before you need a cluster.

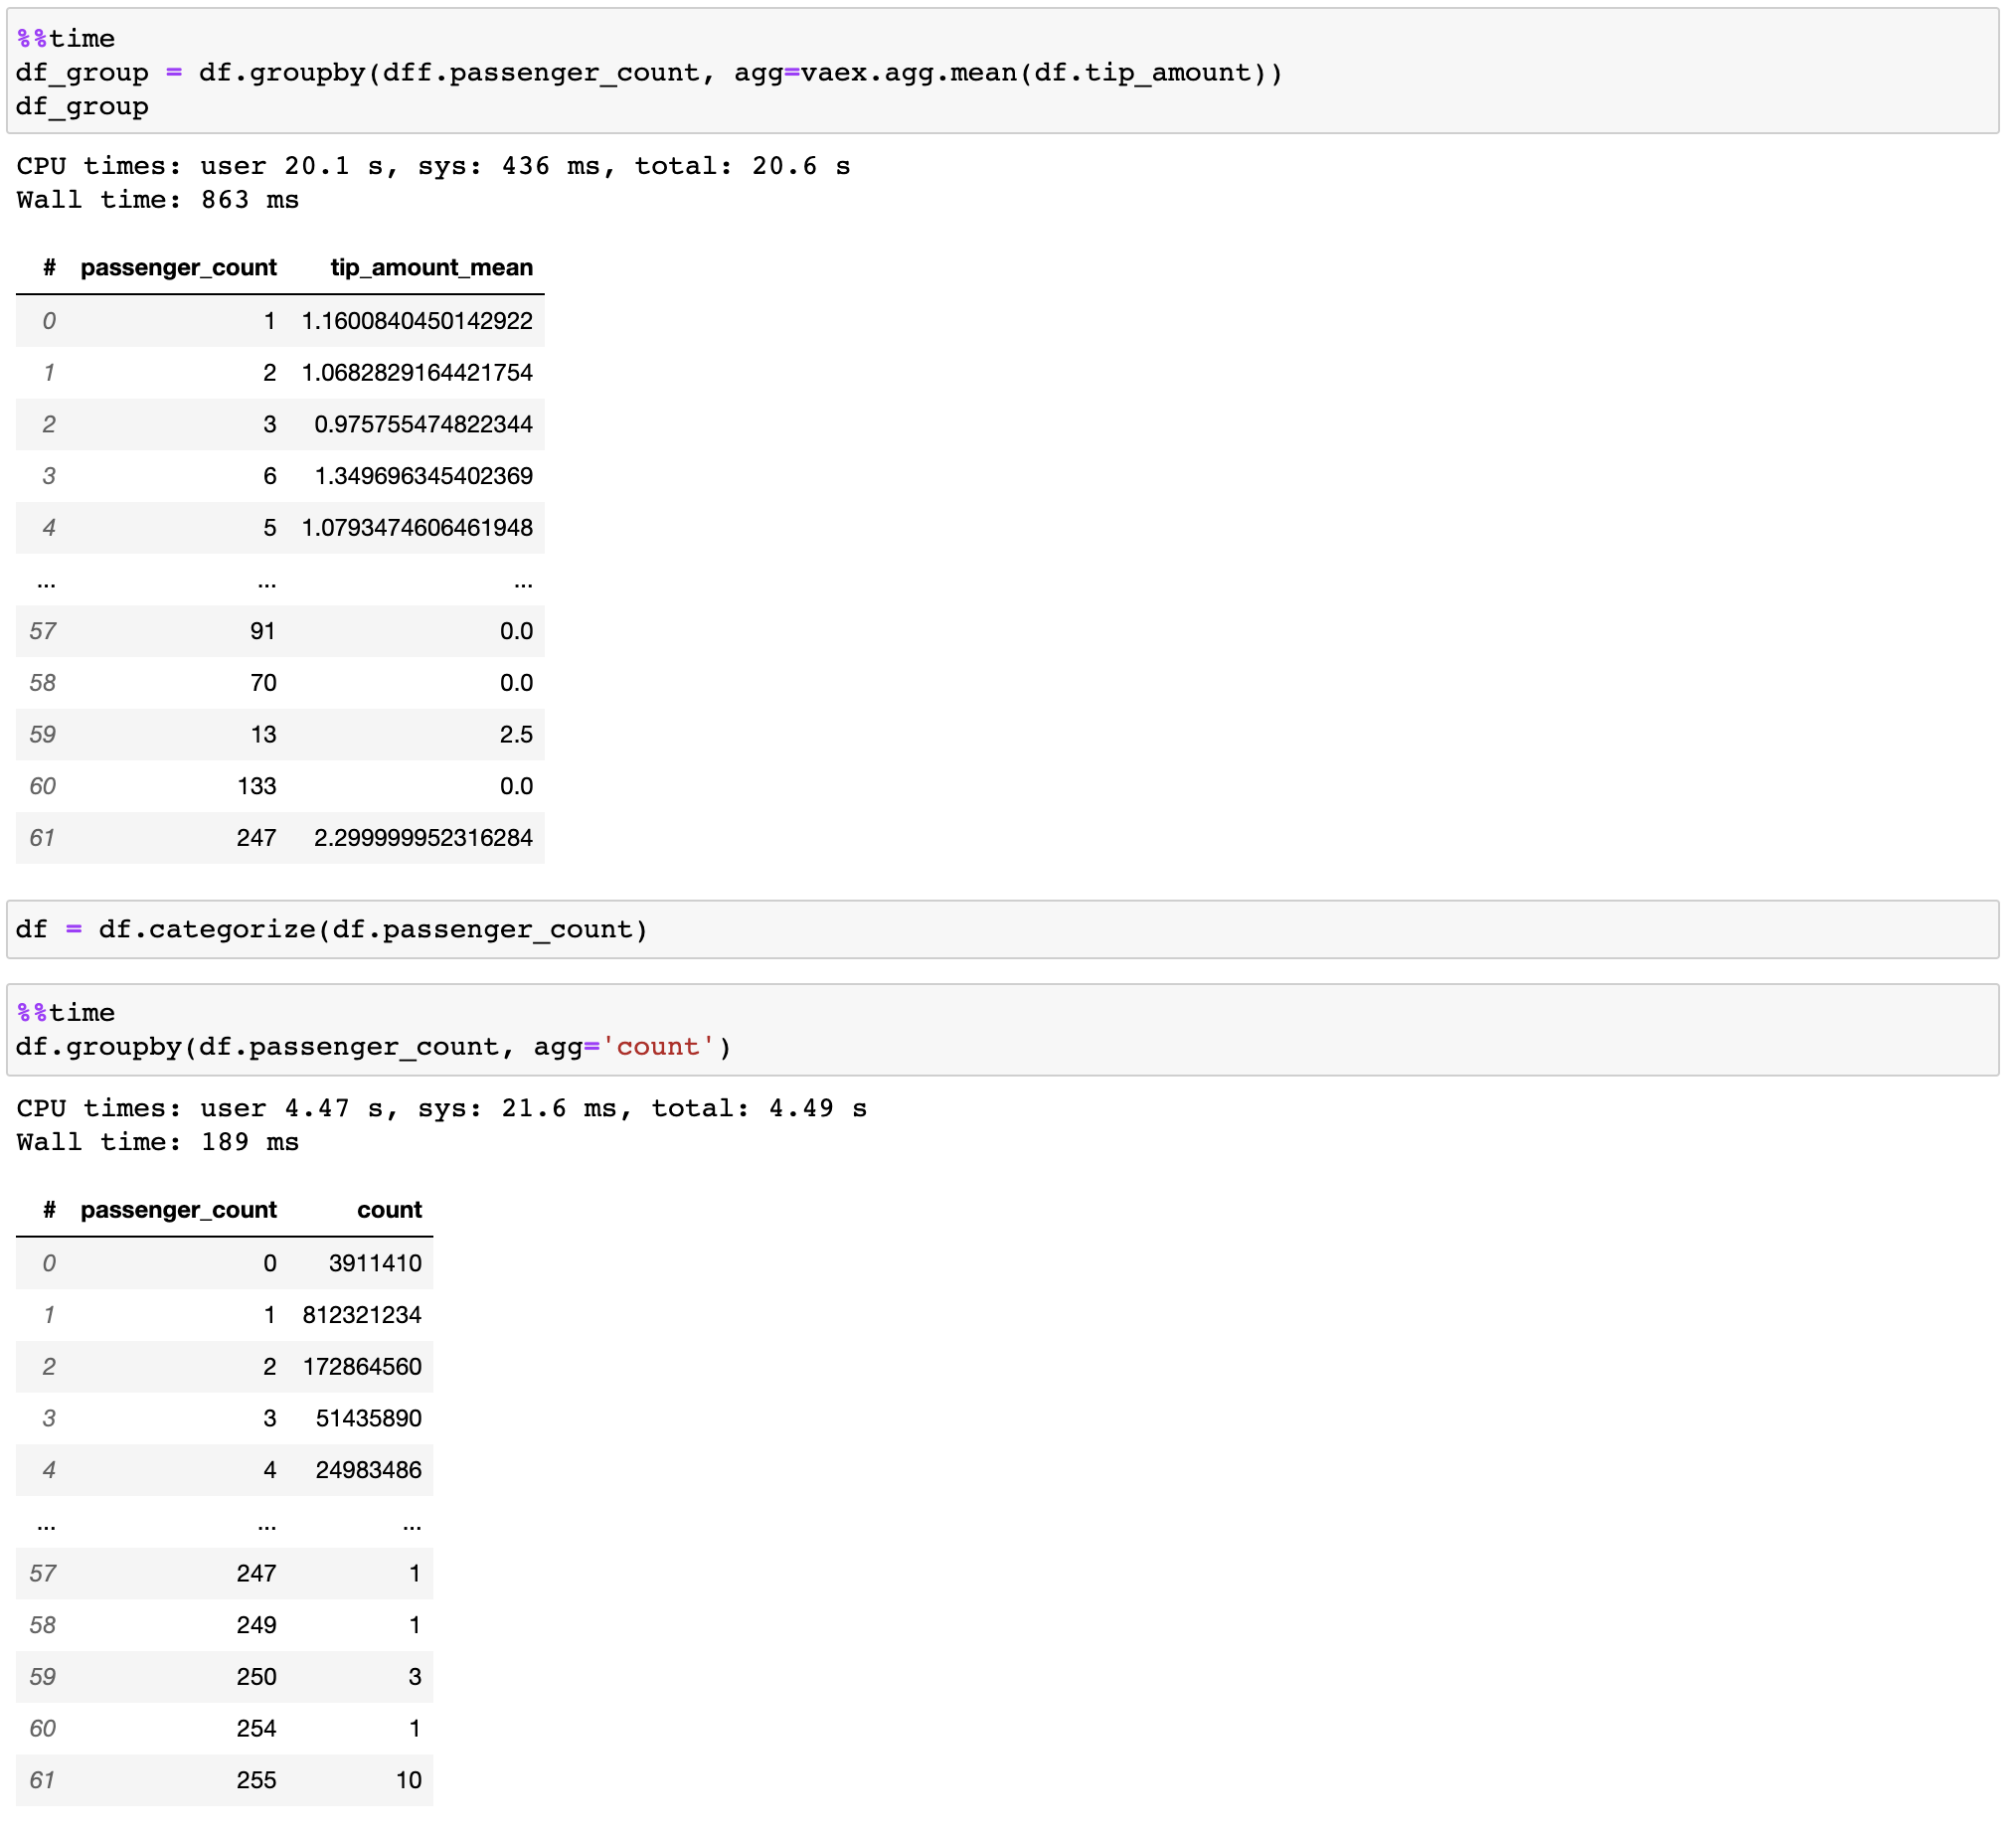
Fast groupby / aggregations
Vaex implements parallelized, highly performant groupby operations, especially when using categories (>1 billion/second).
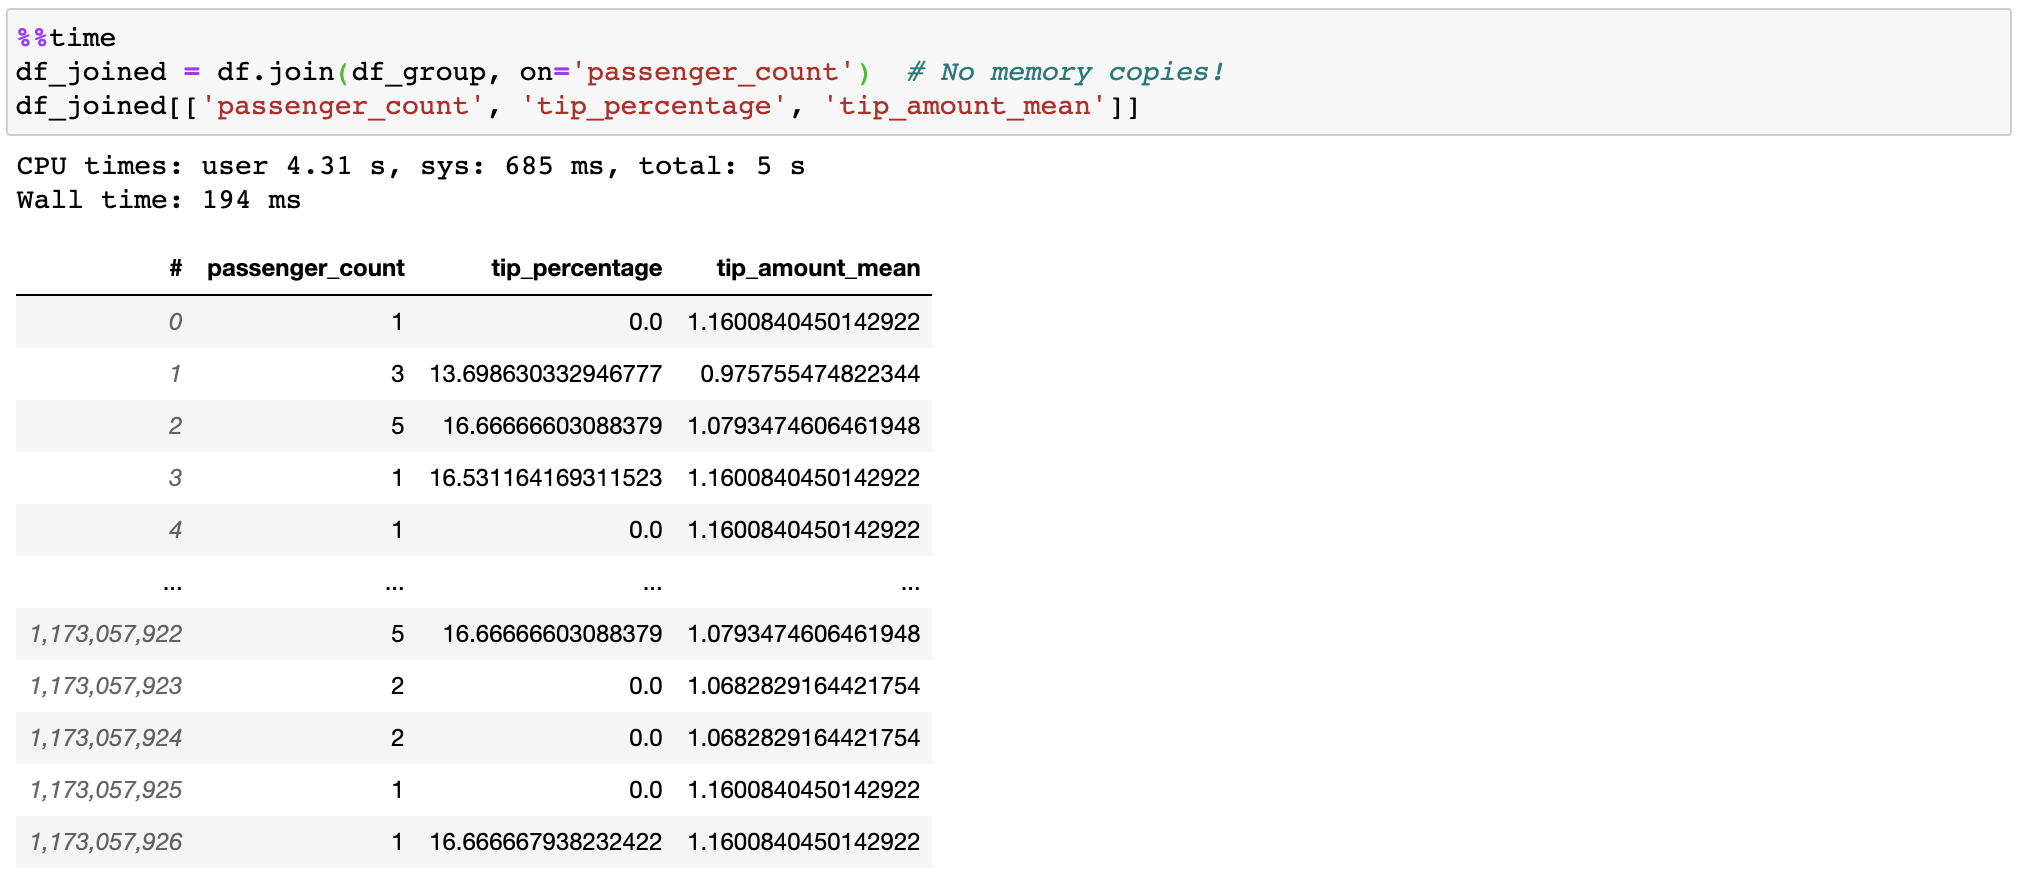
Fast and efficient join
Vaex doesn't copy/materialize the 'right' table when joining, saving gigabytes of memory. With subsecond joining on a billion rows, it's pretty fast!
More features
- Remote DataFrames (documentation coming soon)
- Integration into Jupyter and Voila for interactive notebooks and dashboards
- Machine Learning without (explicit) pipelines
Contributing
See contributing page.
Slack
Join the discussion in our Slack channel!
Learn more about Vaex
Articles
- Beyond Pandas: Spark, Dask, Vaex and other big data technologies battling head to head (includes benchmarks)
- 7 reasons why I love Vaex for data science (tips and tricks)
- ML impossible: Train 1 billion samples in 5 minutes on your laptop using Vaex and Scikit-Learn
- How to analyse 100 GB of data on your laptop with Python
- Flying high with Vaex: analysis of over 30 years of flight data in Python
- Vaex: A DataFrame with super strings - Speed up your text processing up to a 1000x
- Vaex: Out of Core Dataframes for Python and Fast Visualization - 1 billion row datasets on your laptop
Watch our more recent talks:
Contact us for data science solutions, training, or enterprise support at https://vaex.io/