
starlake-ai/starflow
starlake-ai/starflow has 219 GitHub stars and 29 forks. GitHot measured 0 stars in 24 hours, +2 in 7 days, and +2 in 15 days. Last checked 2026-11-21 19:18 UTC. Last push 2026-11-19.
計測したスター増加
- 24時間
- 0
- 7日間
- +2
- 15日間
- +2
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
Declarative text based tool for data analysts and engineers to extract, load, transform and orchestrate their data pipelines.
データREADME.md
オリジナル
Starflow
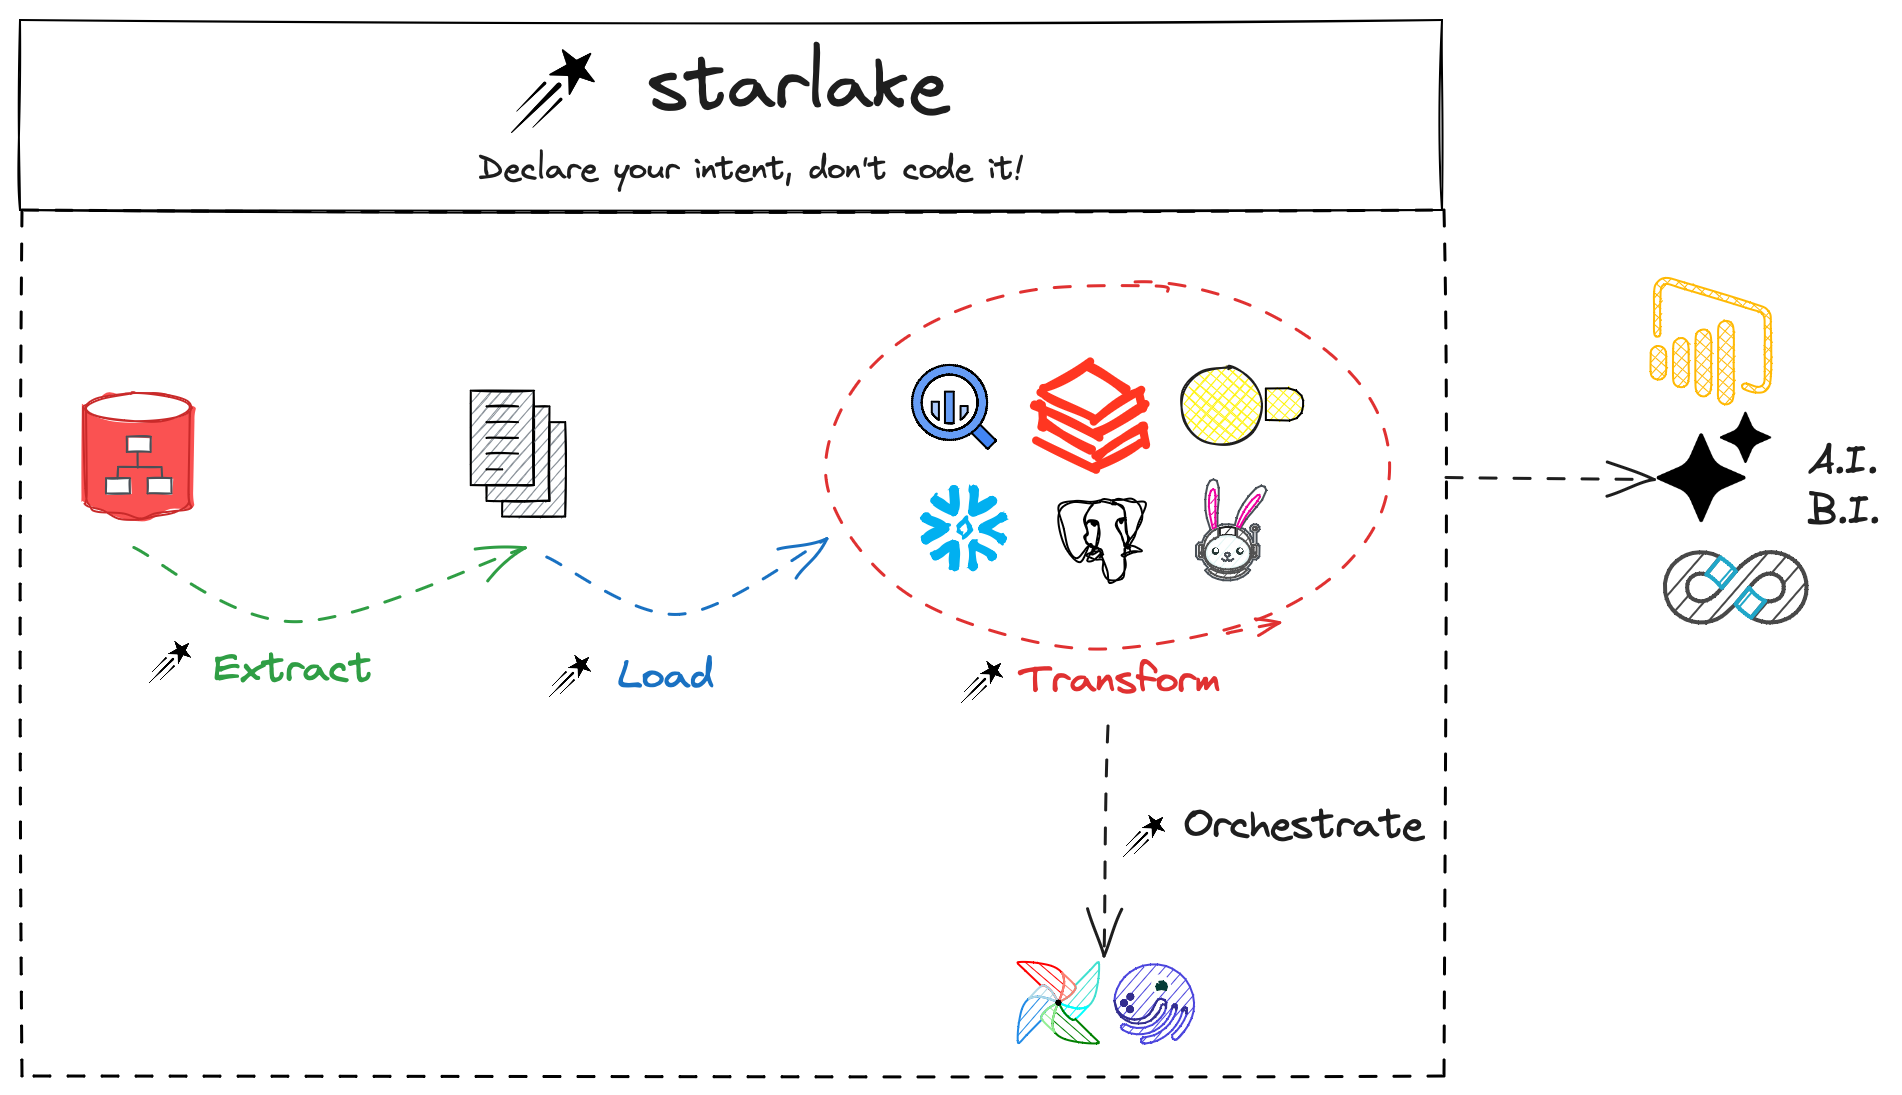
Declarative data pipelines by Starlake: Extract. Load. Transform. Orchestrate.


Documentation • Installation • Discord • VS Code Extension • Starlake Skills • Data Stacks • Contributing
Test on your laptop. Ship to your warehouse. Same SQL, same YAML, no rewrite.
Starflow is a declarative Extract · Load · Transform · Orchestrate engine: describe what your pipeline does in YAML and plain SQL, and Starflow works out how: schemas, merges, quality checks, lineage, and the DAGs to run it all.
And because it transpiles your warehouse SQL to DuckDB, the whole pipeline, loads included, runs and tests locally in seconds. Engine choice becomes an environment variable, not a replatforming program.
A pipeline in 30 seconds
Describe the table once: file pattern, merge strategy, validation:
# metadata/load/crm/customers.sl.yml
table:
  pattern: "customers.*.csv"              # files landing in your incoming folder
  metadata:
    writeStrategy:
      type: UPSERT_BY_KEY_AND_TIMESTAMP   # incremental merge, no MERGE SQL to write
      key: [id]
      timestamp: signup
  attributes:
    - name: id
      type: string
      required: true
    - name: signup
      type: timestamp
    - name: email
      type: string                        # or one of your own semantic types, validated at load time
Then let Starflow do the engineering:
starlake bootstrap                        # scaffold a project
starlake load                             # infer, validate and merge into your warehouse
starlake transform --name kpi.revenue     # run SQL with the right MERGE/INSERT logic
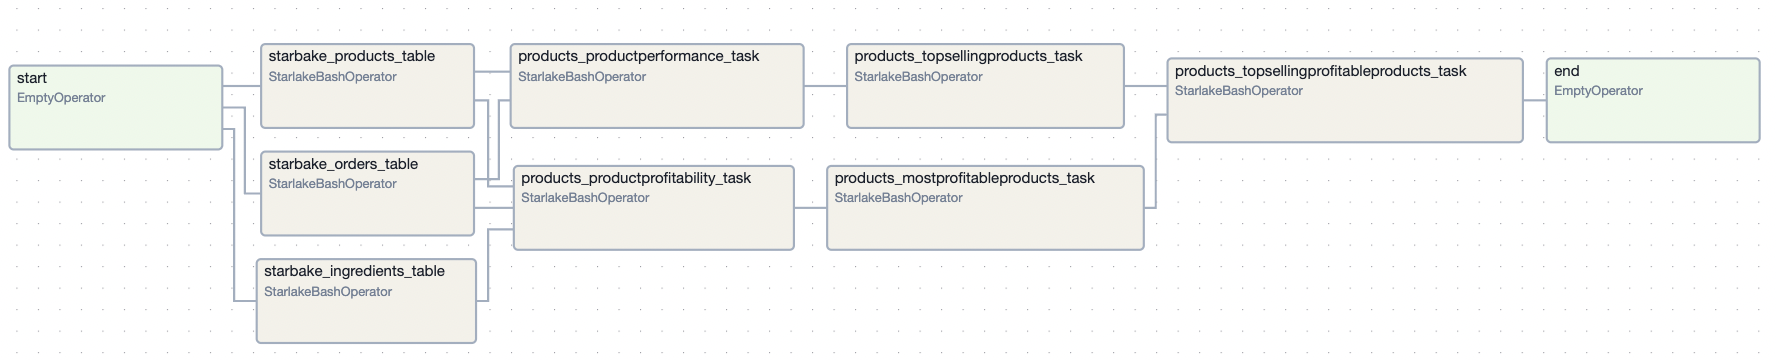
The Airflow DAG above was generated from the SQL dependencies. Nobody wrote it.
Test locally. Run anywhere.
Your transforms are written for BigQuery or Snowflake. Starflow transpiles them to DuckDB, so the whole pipeline runs on your laptop. No dev warehouse. No waiting. No bill.
A test is just a folder: the input you feed in, the output you expect back.
metadata/tests/transform/sales_kpi/byseller_kpi/test1/
├── sales.orders.csv        # input fixture
├── sales.customers.json    # input fixture
└── _expected.csv           # what the transform must produce
starlake test                                  # every load and transform, on local DuckDB
starlake test --transform --domain sales_kpi   # just this one
starlake test --site                           # HTML report with coverage
- No SQL rewriting: your warehouse dialect is transpiled, not reimplemented by hand.
- Loads are tested too: parsing, type validation, merge strategy and rejected rows, not just SQL.
- One project, any engine:
SL_ENV=DUCKDBon the laptop,SL_ENV=BQin production. Same YAML, same SQL.
Why teams pick Starflow
- Local-first: the full pipeline runs on DuckDB in CI and on your laptop, on your warehouse in production, from one codebase.
- Config, not code: YAML and plain SQL replace bespoke ETL scripts and orchestration glue.
- Any source, any warehouse, any orchestrator: files, JDBC databases and Kafka into BigQuery, Snowflake, Redshift, DuckDB, PostgreSQL, Delta Lake or Iceberg, scheduled on Airflow, Dagster or Snowflake Tasks with generated DAGs.
- Quality and lineage built in: expectations run at load time, and table- and column-level lineage falls out of your SQL automatically.
- Privacy by declaration: column-level encryption, row- and column-level security policies applied from the same YAML.
- AI-assistant-ready: MCP-based Starlake Skills teach Claude Code and GitHub Copilot to build and debug pipelines with you.
Quick Start
macOS / Linux:
bash <(curl -sL https://starlake.ai/setup.sh)
Windows (PowerShell):
Invoke-Expression (Invoke-WebRequest -Uri "https://raw.githubusercontent.com/starlake-ai/starflow/master/distrib/setup.ps1" -UseBasicParsing).Content
Docker:
docker run -it starlakeai/starlake:latest starlake bootstrap
The product is Starflow; the CLI keeps its historical name
starlake.
For pre-built production-ready data stacks, see Starlake Pragmatic Data Stacks.
How it works
1. Extract
Pull data from any JDBC source with a few lines of YAML:
extract:
  connectionRef: "pg-adventure-works-db"
  jdbcSchemas:
    - schema: "sales"
      tables:
        - name: "salesorderdetail"
          partitionColumn: "salesorderdetailid"  # parallel extraction
          timestamp: salesdatetime               # incremental
2. Load
Point Starflow at your files: it infers schemas, validates every row against the declared types and expectations, and applies the merge strategy you declared. Malformed lines are quarantined into an audit trail and a replay file instead of failing the load.
3. Transform
Write plain SQL; Starflow wraps it in the correct MERGE/INSERT/OVERWRITE logic for your warehouse:
SELECT
  productid,
  SUM(unitprice * orderqty) AS total_revenue
FROM salesorderdetail
GROUP BY productid
ORDER BY total_revenue DESC
transform:
  tasks:
    - name: most_profitable_products
      writeStrategy:
        type: "UPSERT_BY_KEY_AND_TIMESTAMP"
        timestamp: order_date
        key: [productid]
4. Orchestrate
Starflow extracts the dependencies between your loads and transforms and generates the DAGs. Reference built-in templates for Airflow, Dagster, or Snowflake Tasks in your YAML. No custom DAG code required.
Supported platforms
| Category | Supported |
|---|---|
| Warehouses | BigQuery, Snowflake, Redshift, DuckDB, PostgreSQL, Spark/Hive |
| Lake Formats | Delta Lake, Apache Iceberg, Parquet |
| File Formats | CSV/DSV, JSON, XML, Fixed-width, Parquet |
| Orchestrators | Airflow (v2 & v3), Dagster, Snowflake Tasks |
| Streaming | Kafka |
| Cloud Storage | GCS, S3, Azure Blob, HDFS, Local |
IDE & AI support
The Starlake VS Code Extension brings Starflow into your editor: schema inference, SQL transformations, ER diagrams, lineage visualization, and workflow orchestration without leaving VS Code.
It ships with Starlake Skills, MCP-based skills that give AI coding assistants like Claude Code and GitHub Copilot deep knowledge of the platform, so your assistant builds, debugs, and optimizes pipelines using Starflow best practices.
Community & documentation
- Discord: questions, feedback and release news. Join us
- Docs: guides, concepts, and the full configuration reference at docs.starlake.ai
- Contributing: see the Contributing Guide and Code of Conduct
License
Apache License 2.0. See LICENSE for details.
関連プロジェクトを探す
読み込み中…