
sagawrr/react-native-nitro-vision-kit has 58 GitHub stars and 0 forks. Star changes are not measured yet. Last checked 2026-11-13 16:07 UTC. Last push 2026-11-11.
できること
- removeBackground Subject cutout — trim, export PNG/JPEG, optional mask classifyImage Ranked labels — offline on both platforms readText OCR — Latin / CJK / Devanagari on Android; Vision on iOS 18+ analyzeImage All three from a single decode Cutout and OCR results live on the native side until you export them. Call dispose() when done.
- supportsBackgroundRemoval - Cutouts available
- backgroundRemovalUnavailableReason - Why not
- supportsImageClassification - Labels available
計測したスター増加
- 24時間
- 履歴を収集中
- 7日間
- 履歴を収集中
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
On-device subject cutouts, image labels, and OCR for React Native. Apple Vision (iOS) · Google ML Kit (Android). Built with Nitro Modules.
機械学習README.md
オリジナル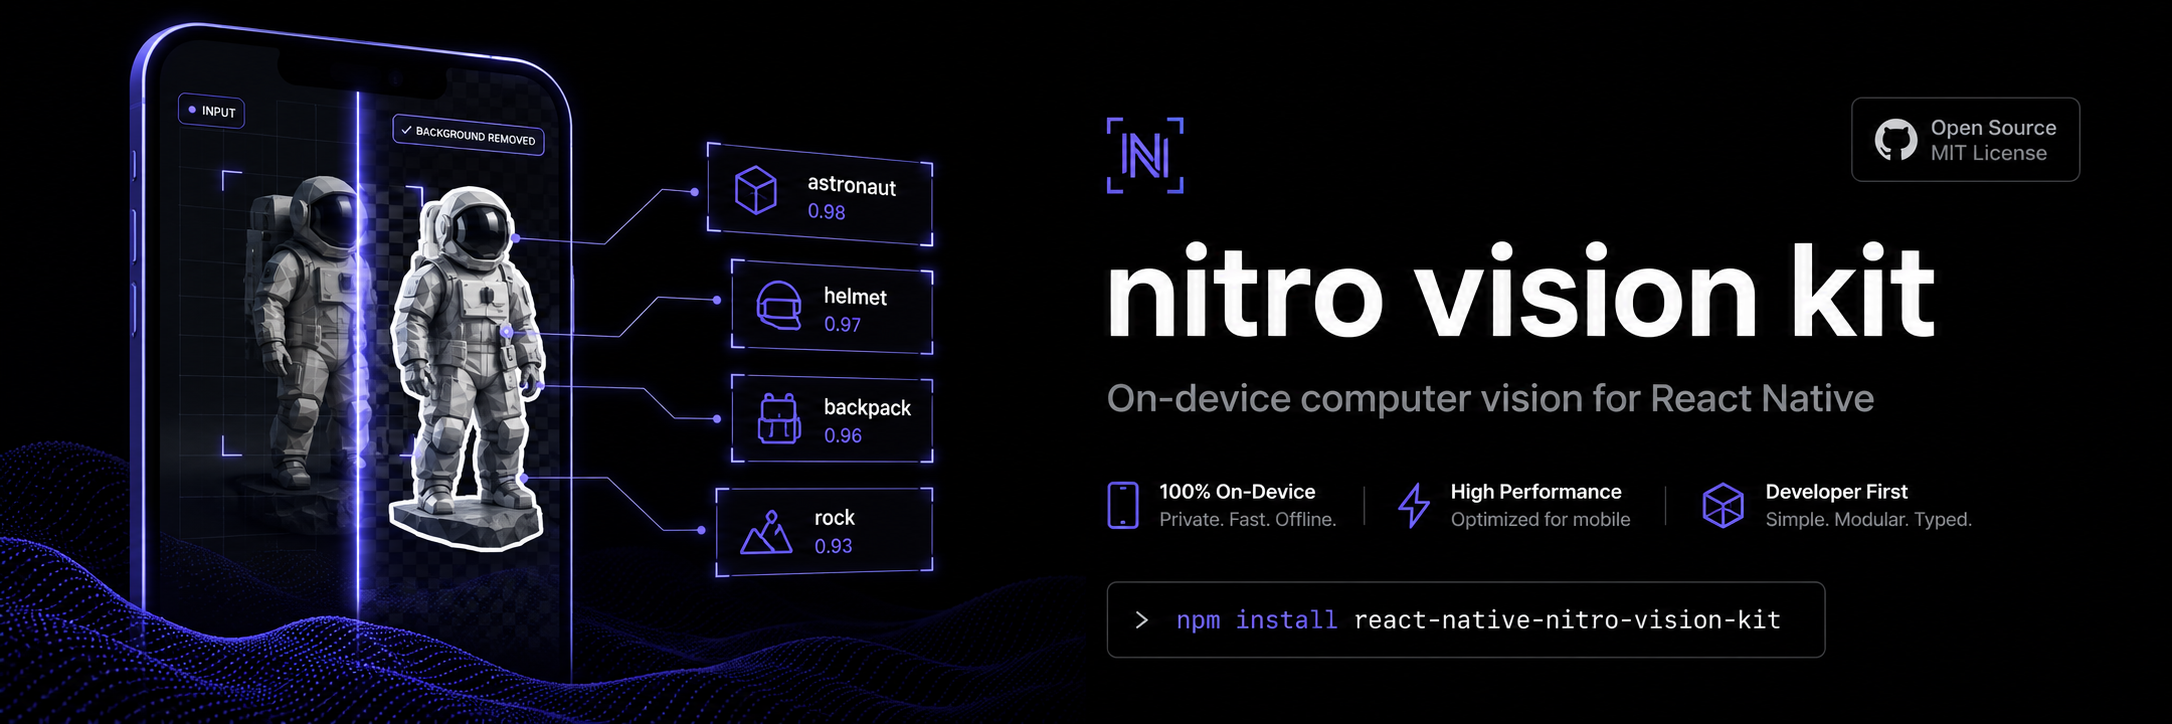


Cutouts · Labels · OCR — Vision on iOS, ML Kit on Android, built with Nitro Modules.
Features
removeBackgroundSubject cutout — trim, export PNG/JPEG, optional mask classifyImageRanked labels — offline on both platforms readTextOCR — Latin / CJK / Devanagari on Android; Vision on iOS 18+ analyzeImageAll three from a single decode Cutout and OCR results live on the native side until you export them. Call dispose() when done.
|
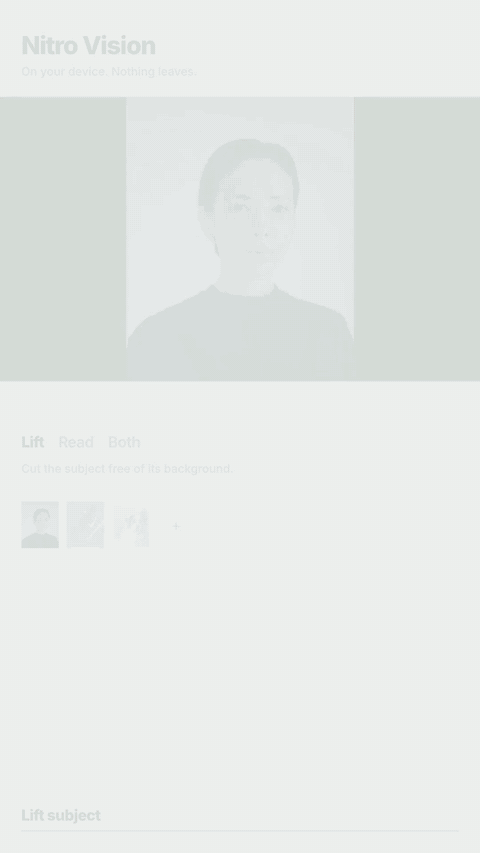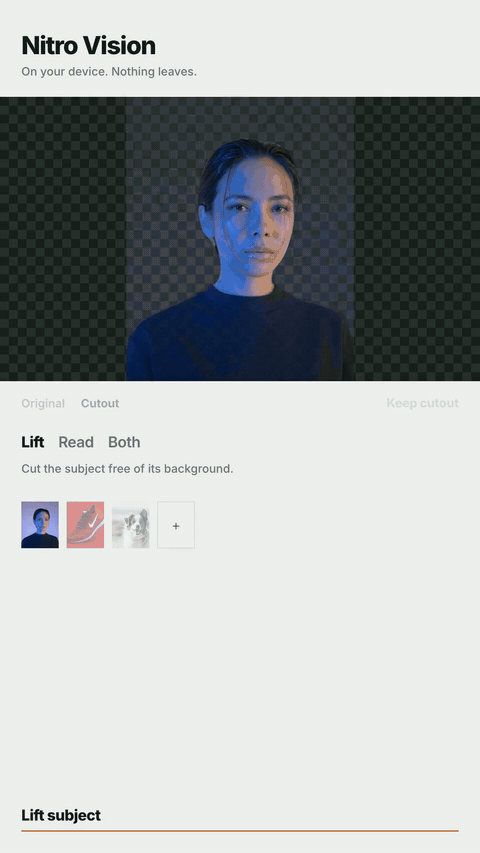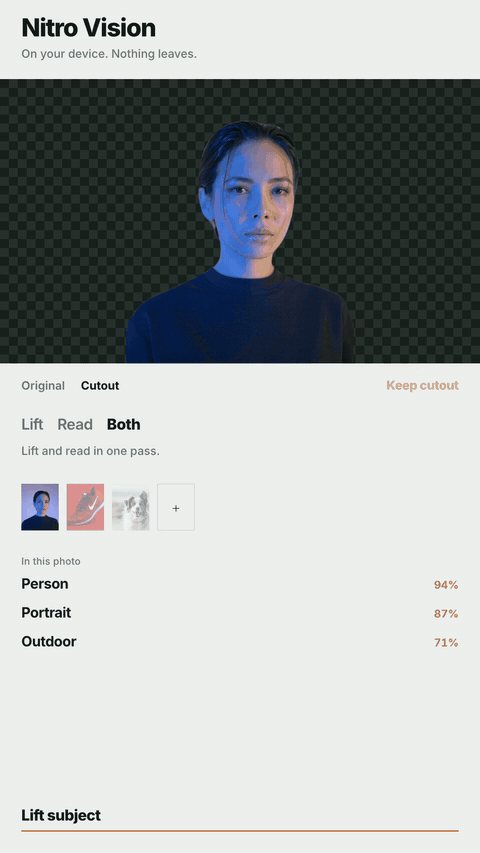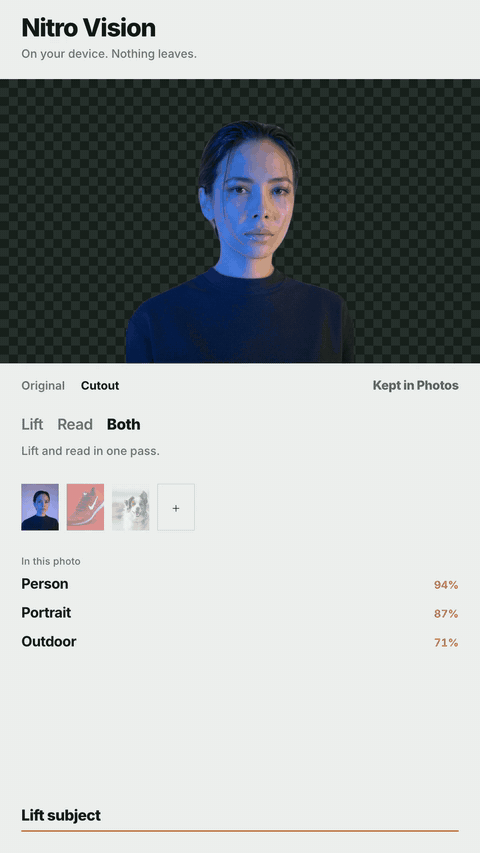
|
Install
npm install react-native-nitro-vision-kit react-native-nitro-modules
cd ios && pod install
| Minimum | |
|---|---|
| React Native | 0.75 |
react-native-nitro-modules |
0.36.0 |
| iOS | 13 · cutouts 17+ · OCR 18+ |
| Android | API 24 |
Requires the New Architecture.
Usage
import { VisionKit } from 'react-native-nitro-vision-kit'
Cutout:
if (!VisionKit.capabilities.supportsBackgroundRemoval) {
  throw new Error(VisionKit.capabilities.backgroundRemovalUnavailableReason)
}

const cutout = await VisionKit.removeBackground(imagePath, { trim: true })
const path = await cutout.saveToTemporaryFile('png', 100)
cutout.dispose()
Labels:
const labels = await VisionKit.classifyImage(imagePath, {
  maxResults: 5,
  minConfidence: 0.5,
})
OCR:
const ocr = await VisionKit.readText(imagePath)
console.log(ocr.text)
ocr.dispose()
All three at once:
const result = await VisionKit.analyzeImage(imagePath, {
  removeBackground: { trim: true },
  classify: { maxResults: 5 },
  readText: {},
})

result.segmentation?.dispose()
result.text?.dispose()
API
Capabilities
VisionKit.capabilities
| Field | Meaning |
|---|---|
supportsBackgroundRemoval |
Cutouts available |
backgroundRemovalUnavailableReason |
Why not |
supportsImageClassification |
Labels available |
supportsTextRecognition |
OCR available |
supportedTextLanguages |
Language tags you can request |
removeBackground(path, options?)
Returns a cutout HybridObject. iOS 17+, Android API 24+ with Play Services (ML Kit subject segmentation, beta).
Export via saveToTemporaryFile(format, quality), toArrayBuffer(), or toMaskBuffer().
Options & result fields
| Option | Default | Meaning |
|---|---|---|
trim |
true |
Crop to the subject |
maxPixels |
6_000_000 |
Cap when loading the image |
retainMask |
false |
Keep mask for toMaskBuffer() |
Result: width, height, bounds (VisionRect, 0–1), pixelBounds, foregroundCoverage, centroid, instanceCount, hasMask, sourceWidth, sourceHeight, trimOrigin.
classifyImage(path, options?)
Returns { label, confidence, index }[], highest confidence first. iOS 13+; on Android the model ships with the library.
Options
| Option | Default | Meaning |
|---|---|---|
maxResults |
0 |
0 keeps all above the score floor |
minConfidence |
0.5 |
Lowest score to keep |
region |
full image | VisionRect (0–1) |
readText(path, options?)
Returns a text HybridObject. Prefer text and blockAt(i) — blocks copies everything into JS. iOS 18+ (RecognizeTextRequest); Android uses Play Services script models (Latin, Chinese, Japanese, Korean, Devanagari).
Image load cap: 4M pixels on both platforms; on Android the longest side is also capped at 2048.
Options & platform quirks
| Option | Default | Platform |
|---|---|---|
languages |
auto / Latin | Both |
recognitionLevel |
accurate |
iOS |
region |
full image | Both (VisionRect) |
minTextHeightFraction |
unset | Both |
usesLanguageCorrection |
true |
iOS |
customWords |
unset | iOS |
maxCandidates |
1 |
iOS (1–10) |
Android: languages selects script models. Non-Latin models also read Latin; multiple non-Latin scripts can run together. A block may contain many lines.
iOS: each block is one line.
analyzeImage(path, options)
One decode. Pass at least one of removeBackground, classify, or readText.
- No subject found →
segmentationomitted; labels and text still run. - If classify/OCR omit
regionand a cutout ran → subject bounds are used.
Platform notes
Model download (Android)
classifyImage works offline out of the box (model is packaged). removeBackground and readText download a Play Services model once — allow up to ~2 minutes online on first use; offline with no model fails immediately. iOS ships its models with the OS.
Paths
Absolute paths and file:// work everywhere. content:// is Android-only.
Only pass paths created by your app — native code opens the path and returns pixels/text to JavaScript.
Example
cd example
npm install
cd ios && bundle install && bundle exec pod install && cd ..
npm run ios    # or: npm run android
After a cutout, Keep saves to Photos.
License
関連プロジェクトを探す
tensorflow/tensorflow
すべての人のためのオープンソース機械学習フレームワーク
201,583 スターhuggingface/transformers
🤗 Transformers:テキスト、ビジョン、音声、マルチモーダルの最先端機械学習モデル向けモデル定義フレームワークで、推論と学習の両方に対応します。
168,948 スターAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion の Web UI
165,301 スターComfy-Org/ComfyUI
グラフとノードによるインターフェースを備えた、最も強力でモジュール性の高い拡散モデル向け GUI、API、バックエンド。世界最速のローカル推論エンジン。
146,661 スター