
pivotlake/pivot has 174 GitHub stars and 12 forks. Star changes are not measured yet. Last checked 2026-11-12 08:07 UTC. Last push 2026-11-11.
Pivot is a high-performance real time analytics database on open data formats.
できること
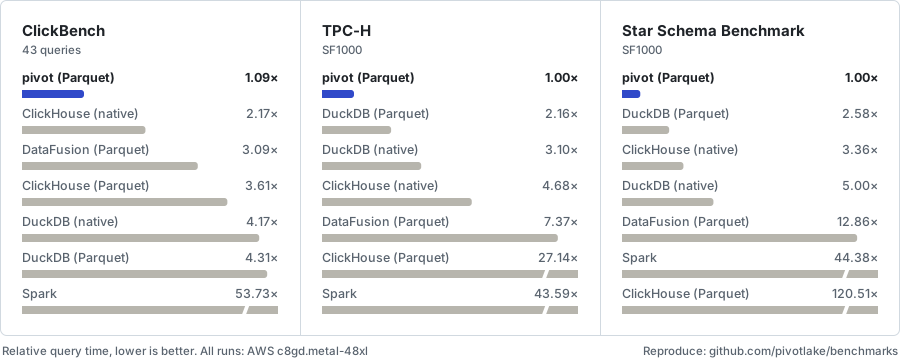
- Fast - Written in Rust and built on state-of-the-art columnar execution techniques, including morsel-driven parallelism, SIMD, NUMA-aware execution, and cache-conscious aggregation and joins, in addition to a few novel additions.
- Scalable - With object storage as its backing store, Pivot can be scaled up, down, or to zero almost instantly.
- Portable - Pivot can run both as a server serving backends and clients, or as a local engine where users and agents query the source of truth directly—allowing local ad-hoc and agentic analytics to share the same engine and architecture as traditional dashboards and in-app analytics
- Open - Pivot is open source and built on open data formats (Delta Lake and Iceberg). This means you can use Pivot with data already stored in your data warehouse, while data ingested by Pivot remains accessible to other query engines.
計測したスター増加
- 24時間
- 履歴を収集中
- 7日間
- 履歴を収集中
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
README.md
オリジナル


Pivot is a high-performance analytics database that runs on open data formats. It delivers low-latency queries and high concurrency without replicating data into a dedicated real-time analytics database such as ClickHouse / Druid.
Key features
- Fast - Written in Rust and built on state-of-the-art columnar execution techniques, including morsel-driven parallelism, SIMD, NUMA-aware execution, and cache-conscious aggregation and joins, in addition to a few novel additions.
- Scalable - With object storage as its backing store, Pivot can be scaled up, down, or to zero almost instantly.
- Portable - Pivot can run both as a server serving backends and clients, or as a local engine where users and agents query the source of truth directly—allowing local ad-hoc and agentic analytics to share the same engine and architecture as traditional dashboards and in-app analytics
- Open - Pivot is open source and built on open data formats (Delta Lake and Iceberg). This means you can use Pivot with data already stored in your data warehouse, while data ingested by Pivot remains accessible to other query engines.
Getting started
curl https://pivotlake.io | sh
See the Quickstart for Docker, the Debian package and a first query.
[!NOTE] Pivot is in early development and not yet production ready. Expect breaking changes between releases.
Contributing
Contributions are welcome! See CONTRIBUTING.md, and ask questions in Discussions.
License
Licensed under either of the Apache License, Version 2.0 or the MIT license, at your option.
関連プロジェクトを探す
Asabeneh/30-Days-Of-Python
30 Days of Python プログラミングチャレンジは、Python プログラミング言語を 30 日で学ぶためのステップバイステップのガイドです。このチャレンジは 100 日以上かかることもあります。自分のペースで進めてください。こちらの動画も役立つかもしれません: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 スターgrafana/grafana
オープンで組み合わせ可能なオブザーバビリティおよびデータ可視化プラットフォームです。Prometheus、Loki、Elasticsearch、InfluxDB、Postgres など、複数のソースからメトリクス、ログ、トレースを可視化できます。
77,830 スターredis/redis
リアルタイムのデータ駆動型アプリケーションを構築する開発者にとって、Redis は最も選ばれ、最速で、機能が最も豊富なキャッシュ、データ構造サーバー、ドキュメントおよびベクトルクエリエンジンです。
77,395 スターapache/superset
Apache Superset は、データ可視化とデータ探索のためのプラットフォームです。
75,473 スター