
katerakelly/pytorch-maml
katerakelly/pytorch-maml has 567 GitHub stars and 123 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-21 17:56 UTC. Last push 2018-10-04.
計測したスター増加
- 24時間
- 0
- 7日間
- 0
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
PyTorch implementation of MAML: https://arxiv.org/abs/1703.03400
機械学習README.md
オリジナルpytorch-maml
This is a PyTorch implementation of the supervised learning experiments from the paper Model-Agnostic Meta-Learning (MAML): https://arxiv.org/abs/1703.03400
Important: You will need the latest version of PyTorch, v.0.2.0 to run this code (otherwise you will get errors about double backwards not being supported).
Currently, only the Omniglot experiments have been replicated here. The hyper-parameters are the same as those used in the original Tensorflow implementation, except that only 1 random seed is used here.
5-way 1-shot training, best performance 98.9%
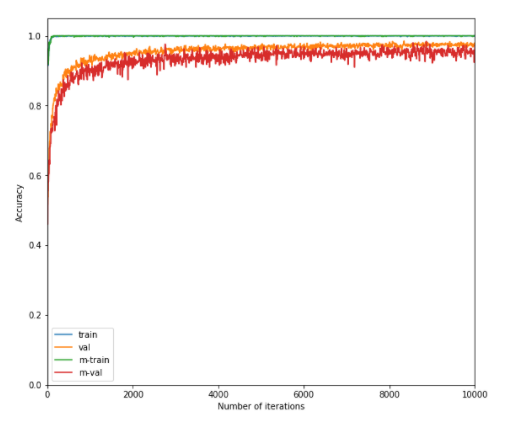
20-way 1-shot training, best performance 92%
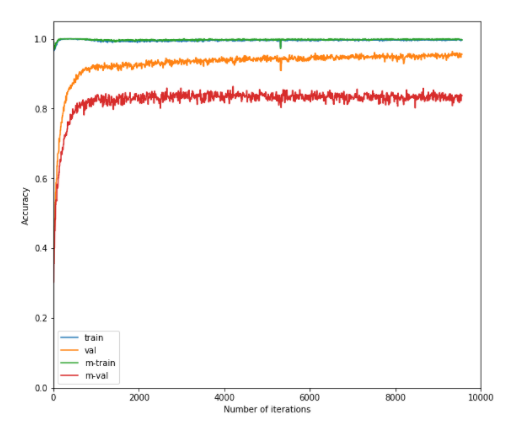
Note: the 20-way performance is slightly lower than that reported in the paper (they report 95.8%). If you can see why this might be, please let me know. Also in this experiment, we can see evidence of overfitting to the meta-training set.
The 5-way results are achieved by simply meta-testing the network trained on the 1-shot task on the 5-shot task (e.g. for the 5-way 5-shot result, test the 5-way 1-shot trained network with 5-shots). Again the 20-way result is lower here than reported in the paper.
This repo also contains code for running maml experiments on permuted MNIST (tasks are created by shuffling the labels). This is a nice sanity check task.
license
This software is distributed under the MIT license.
to-do
- port to pytorch 0.4 from 0.2 and python 3 from 2
- investigate performance difference from TF version
- add first-order version
関連プロジェクトを探す
読み込み中…