
denis-pplx/autojev
denis-pplx/autojev has 134 GitHub stars and 15 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-20 00:14 UTC. Last push 2026-09-22.
計測したスター増加
- 24時間
- 0
- 7日間
- 0
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
Full-weight Qwen decision model with calibrated probabilities, training code, REST API, and playground.
機械学習README.md
オリジナルAutoJev-27B
Built with autonomous agents, from research and data generation to training, evaluation, and deployment. The user set the goals and refined the scope; agents executed the work.
AutoJev-27B is a multimodal decision model based on Qwen3.8-27B. It returns probabilities over supplied choices in one forward pass per question, with a TypeSafe-compatible API and browser playground.
Results
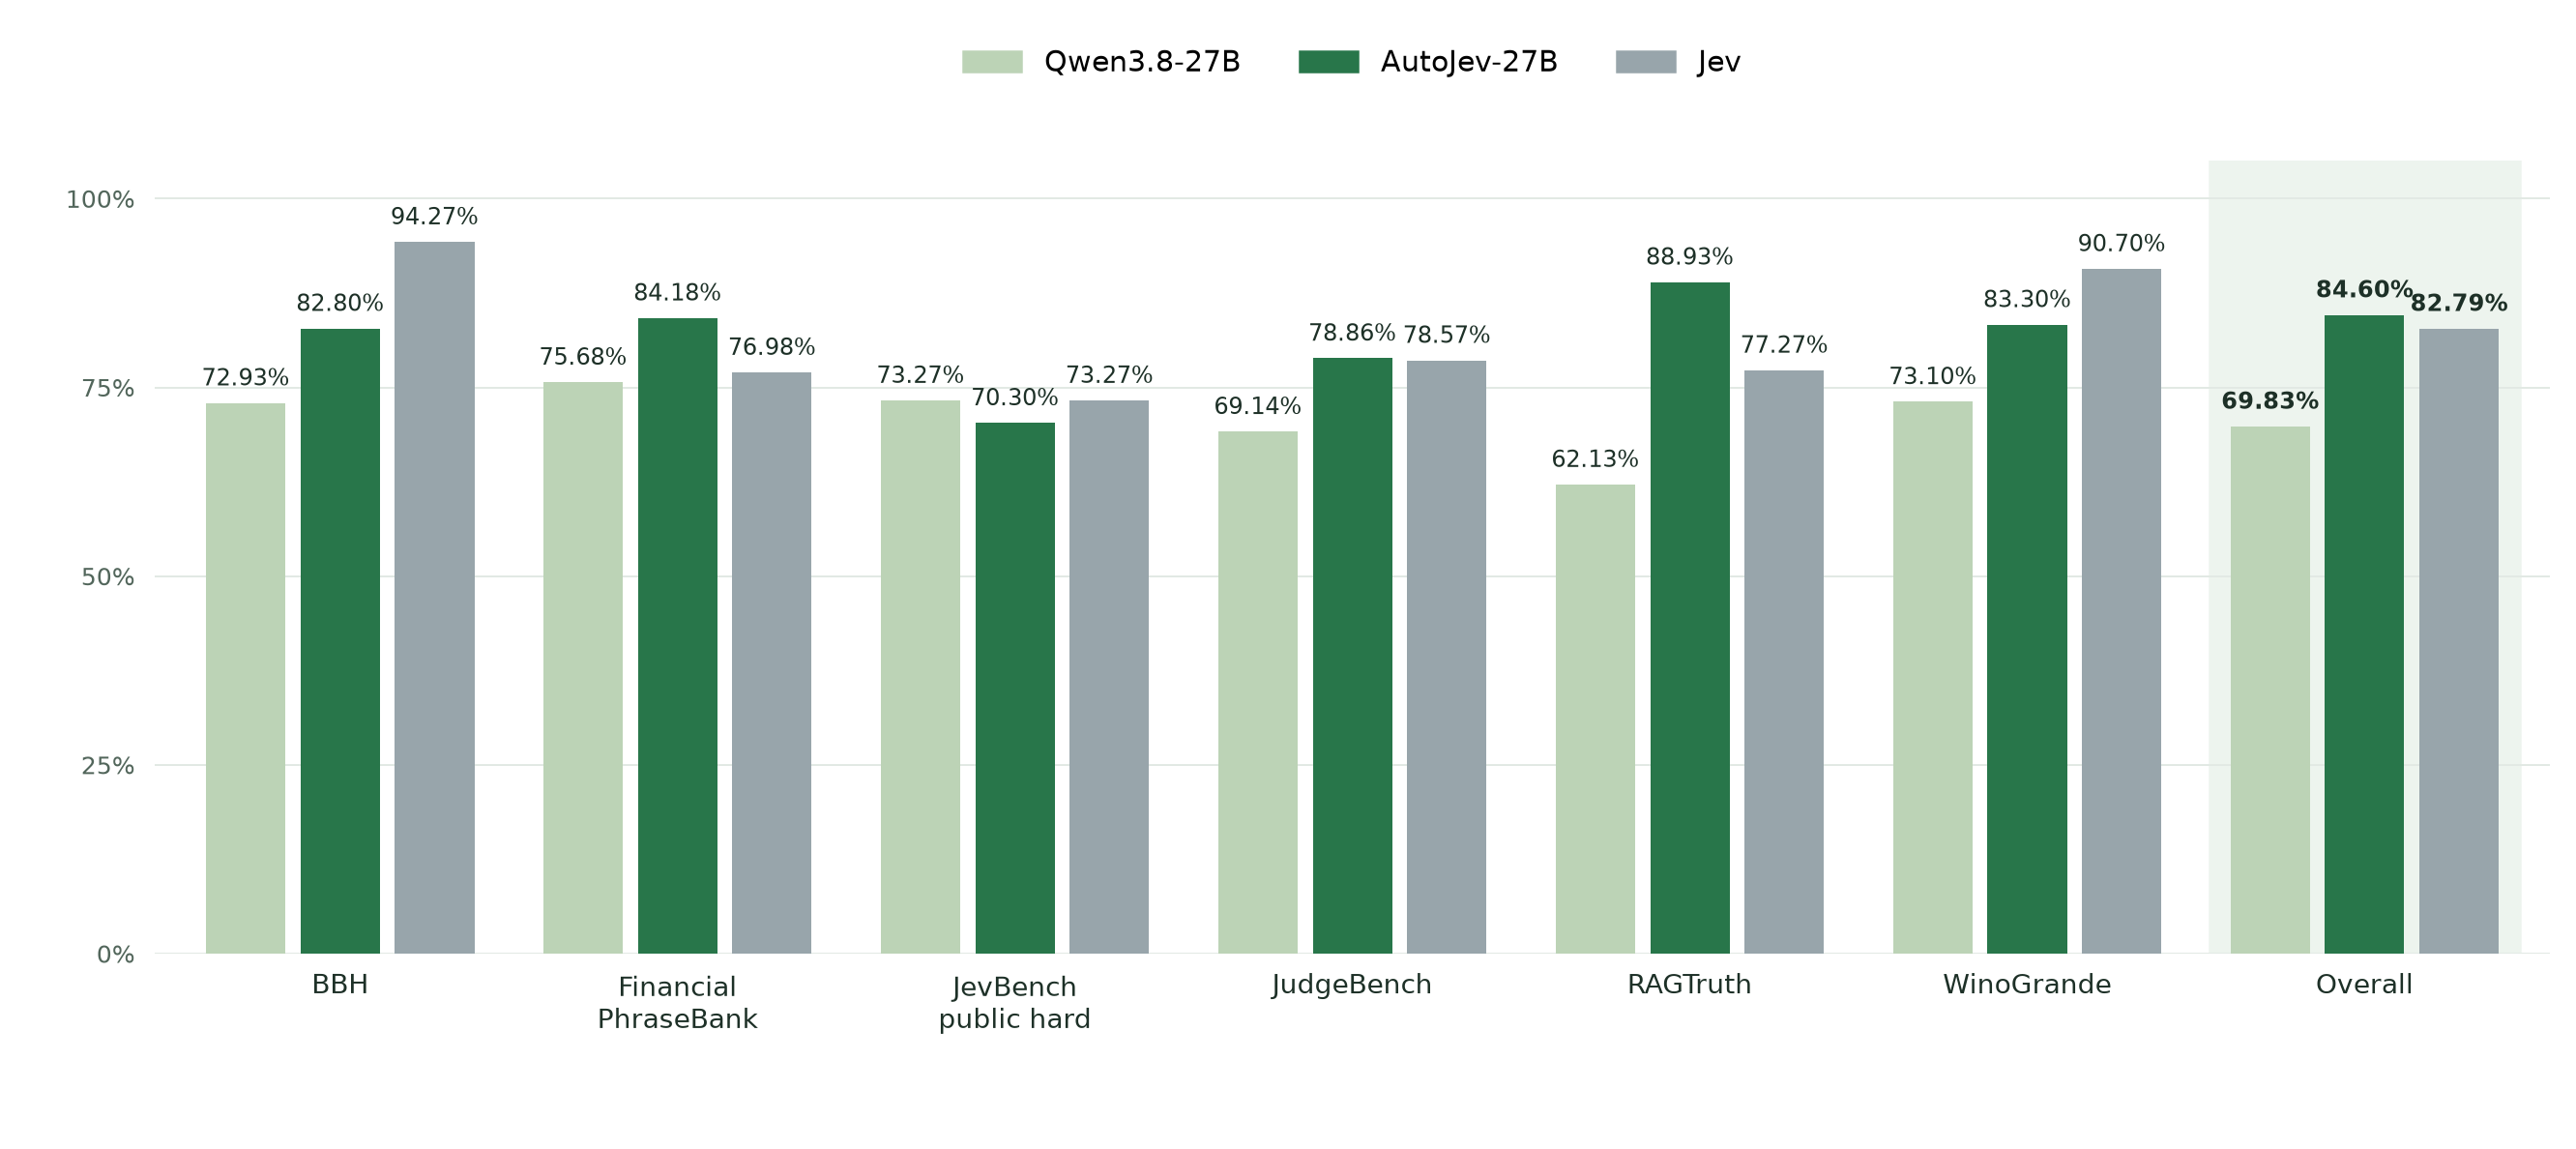
| Model | Overall accuracy ↑ | ECE ↓ | Brier ↓ |
|---|---|---|---|
| Qwen3.8-27B | 69.83% | 0.06483 | 0.40834 |
| AutoJev-27B | 84.60% | 0.04282 | 0.22027 |
| Jev | 82.79% | 0.05274 | 0.25400 |
Training
One H200 · full-weight SFT · 73,000 unique training examples · 286 updates. The released model is checkpoint 200. Training uses cross-entropy; calibration fits a scalar temperature separately.
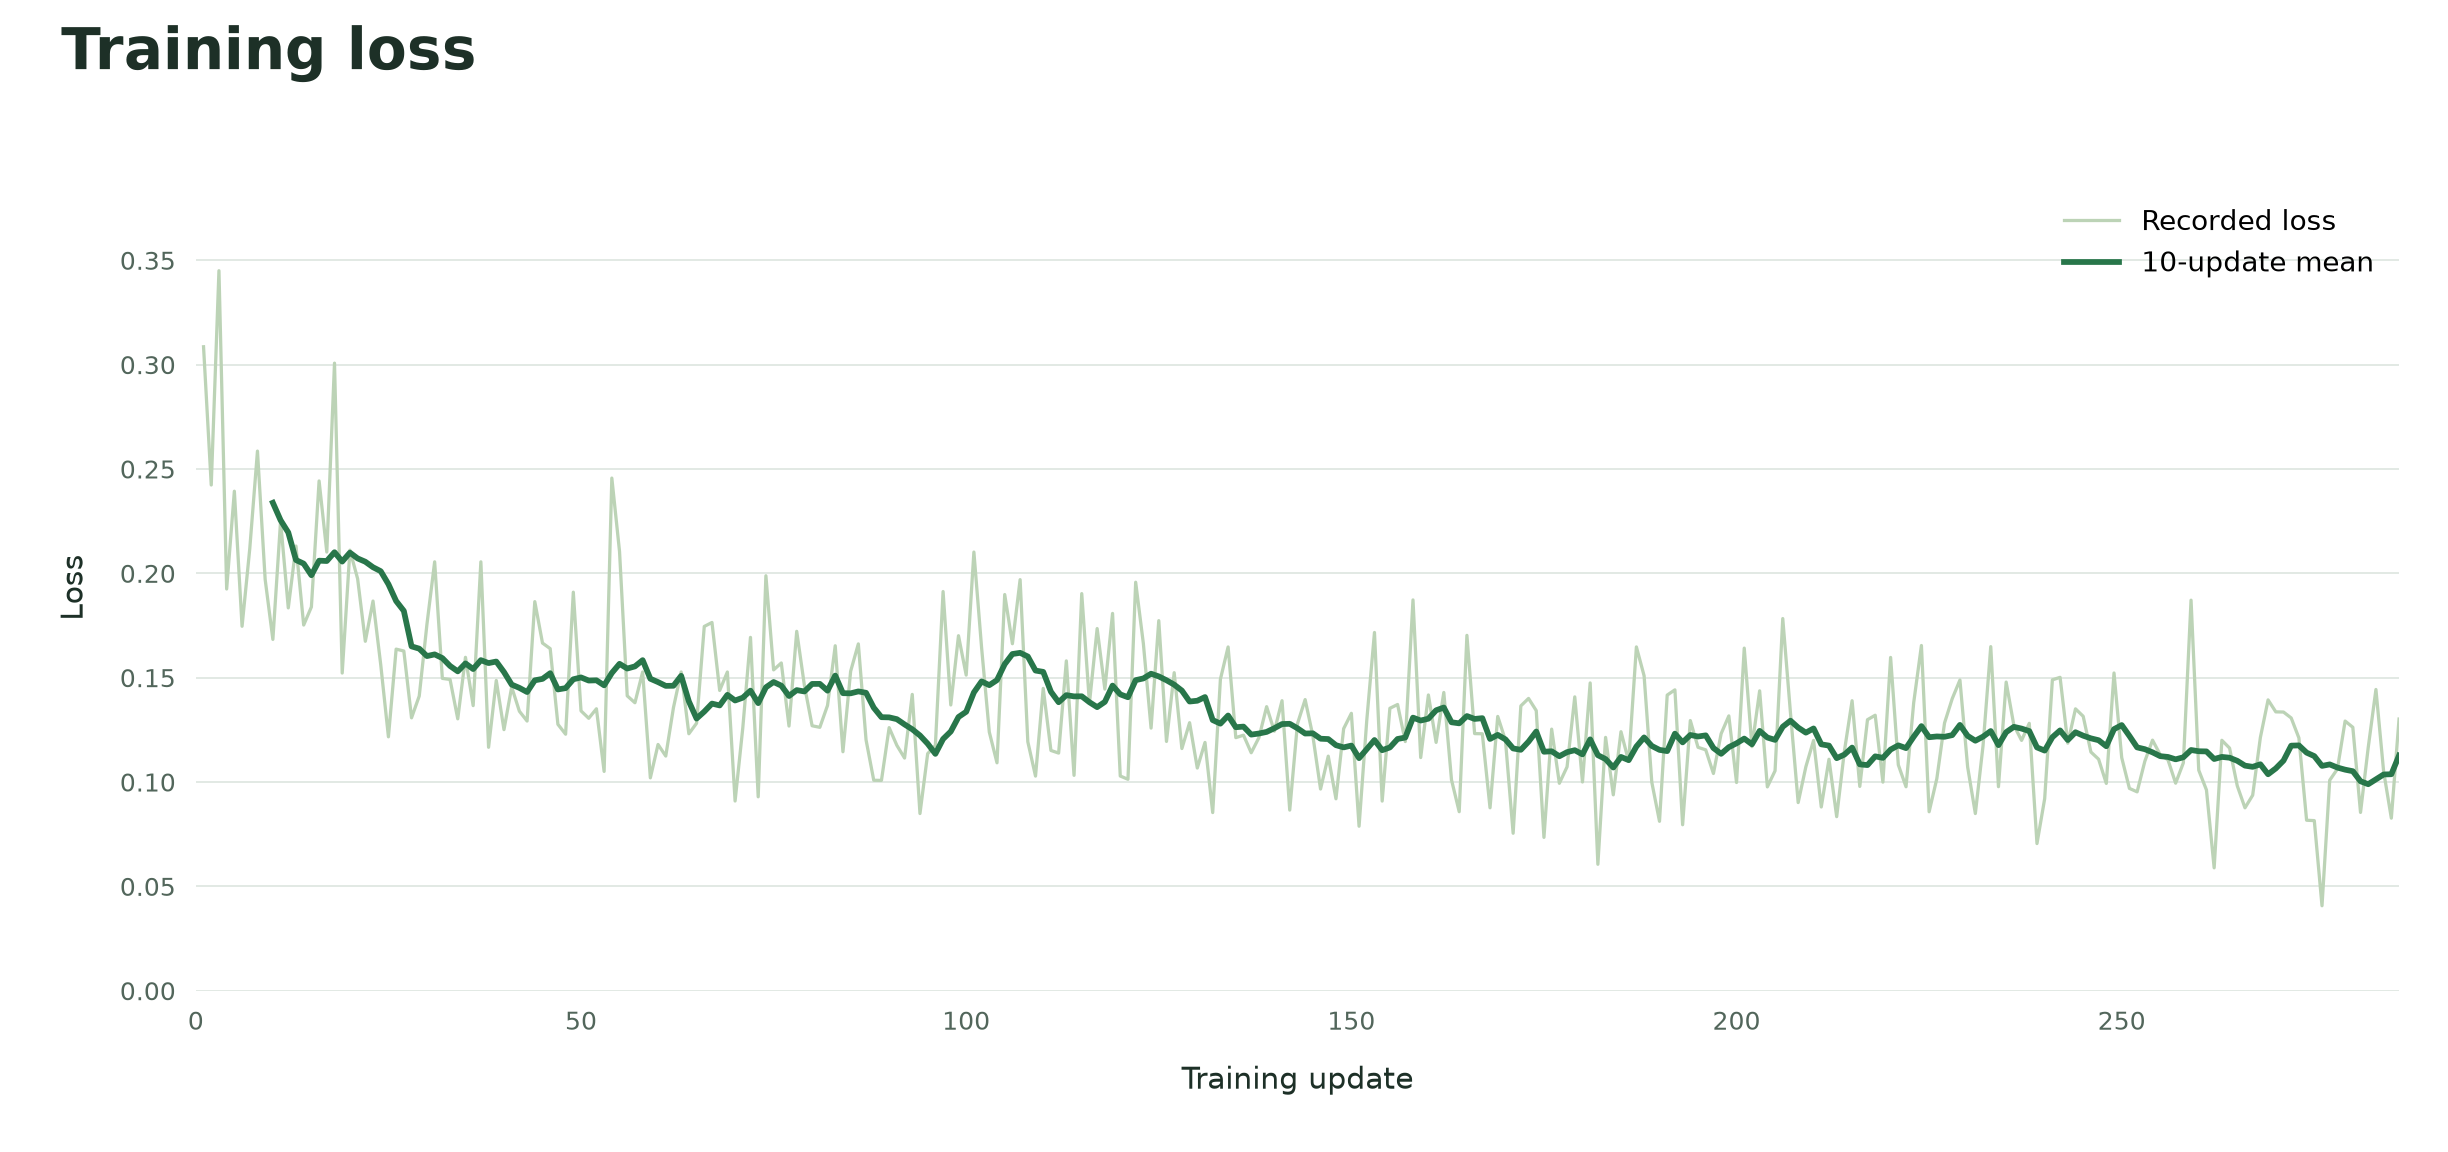
Run bash configs/train.sh --help for training arguments. The exact curated training corpus is not bundled.
Run
Python 3.12+, uv and a GPU with space for approximately 49 GiB of BF16 weights plus runtime overhead.
git clone https://github.com/denis-pplx/autojev.git
cd autojev
uv sync --frozen --python 3.12
uv run hf download denis-pplx/autojev-27b --local-dir checkpoints/selected
AUTOJEV_CHECKPOINT=checkpoints/selected uv run autojev-serve
Open http://localhost:8000 for the playground or /docs for the API. POST /v1/systemone supports choice, noul, score, and optional base64 images. Set AUTOJEV_API_KEY to enable authentication. While the weights are private, authenticate with uv run hf auth login before downloading.
Use the included DecisionModel loader or server. Published benchmarks measure text decisions; image support is not a natural-image accuracy claim.
Code: MIT · Weights: Apache 2.0 · Independent implementation inspired by Jev.