
bradyz/cross_view_transformers has 576 GitHub stars and 82 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-19 19:23 UTC. Last push 2023-11-06.
計測したスター増加
- 24時間
- 0
- 7日間
- 履歴を収集中
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
Cross-view Transformers for real-time Map-view Semantic Segmentation (CVPR 2022 Oral)
機械学習README.md
オリジナルCross View Transformers
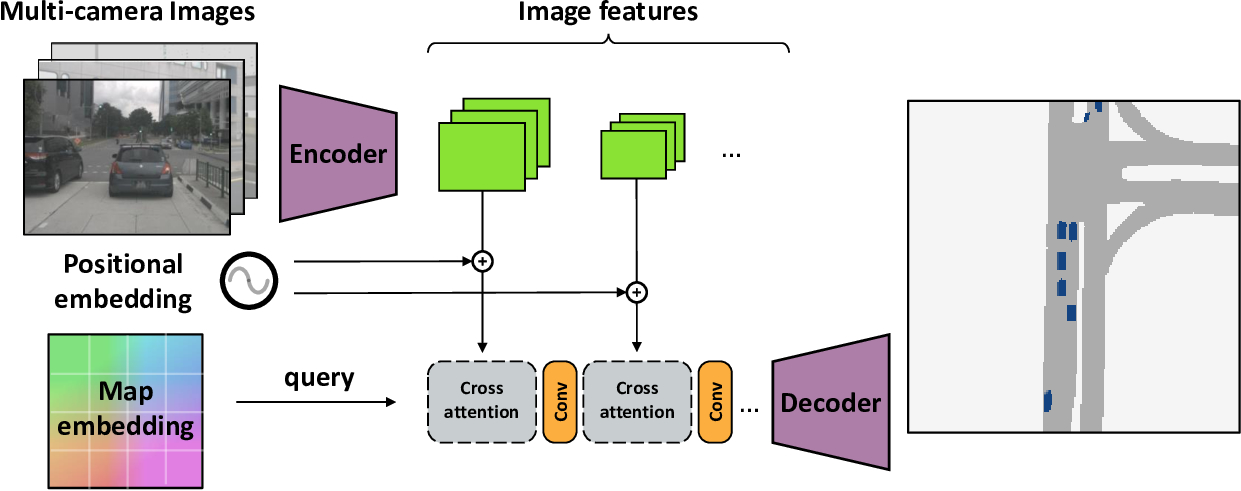
This repository contains the source code and data for our paper:
Cross-view Transformers for real-time Map-view Semantic Segmentation
Brady Zhou, Philipp Krähenbühl
CVPR 2022
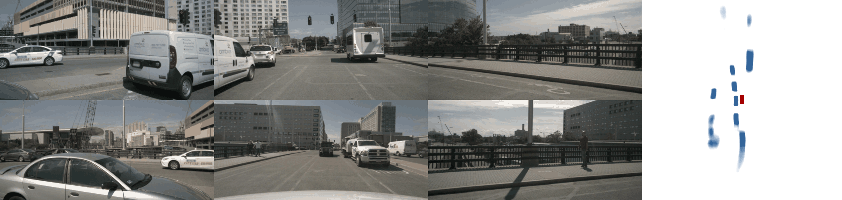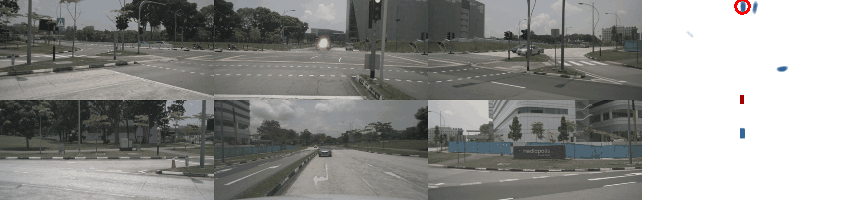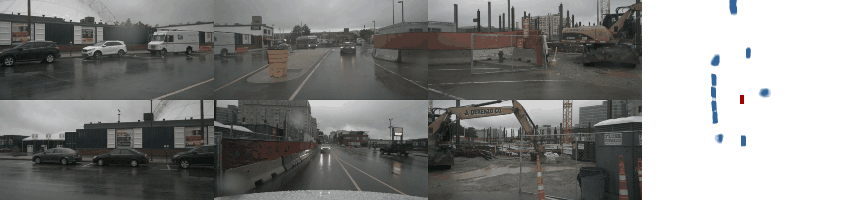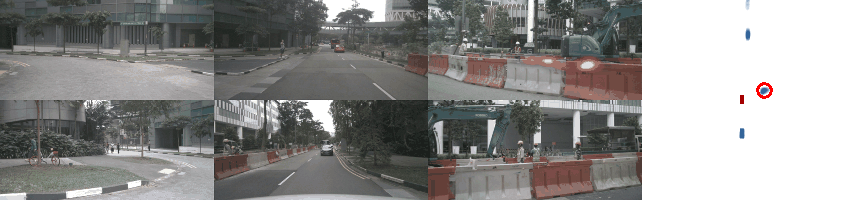
Demos
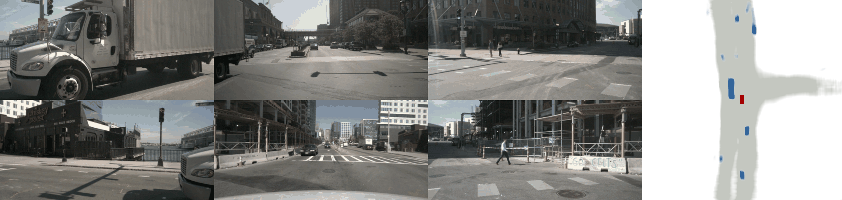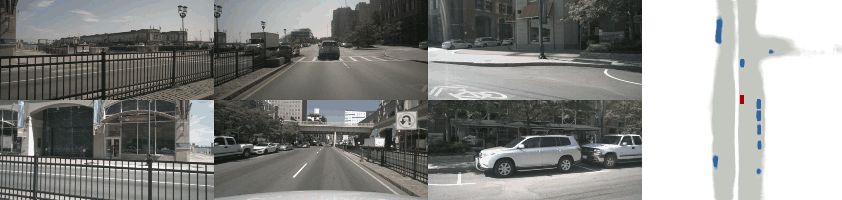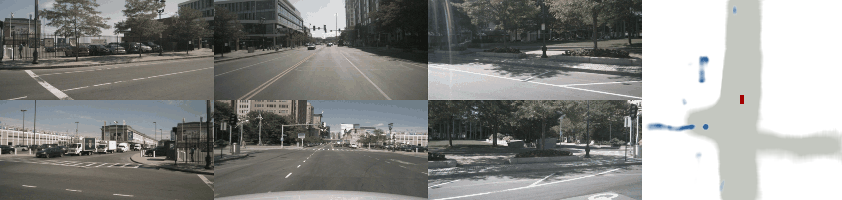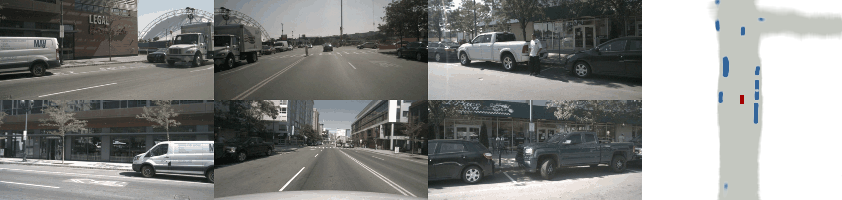
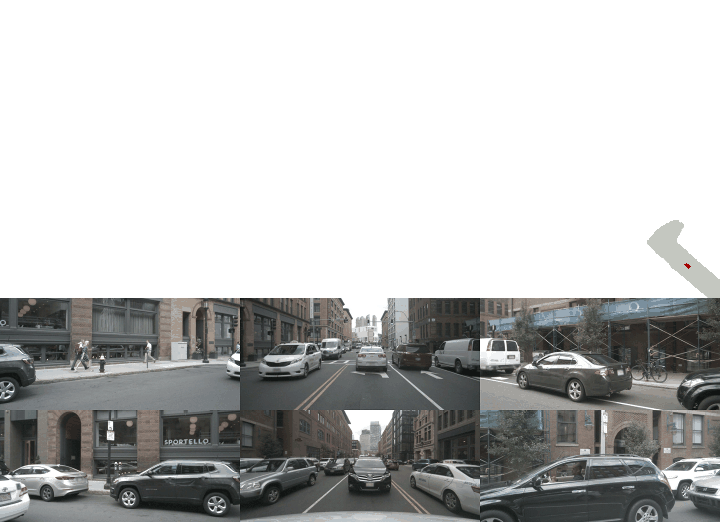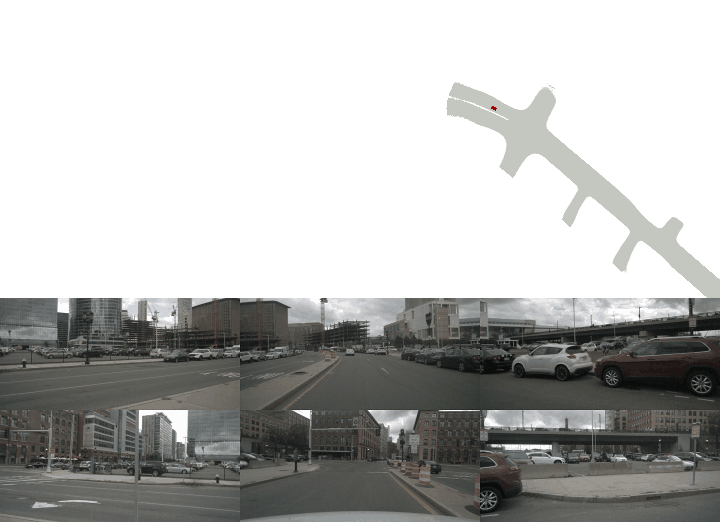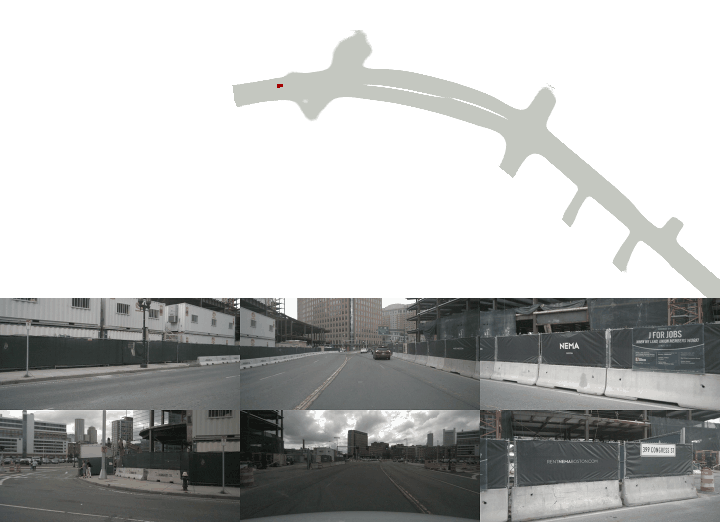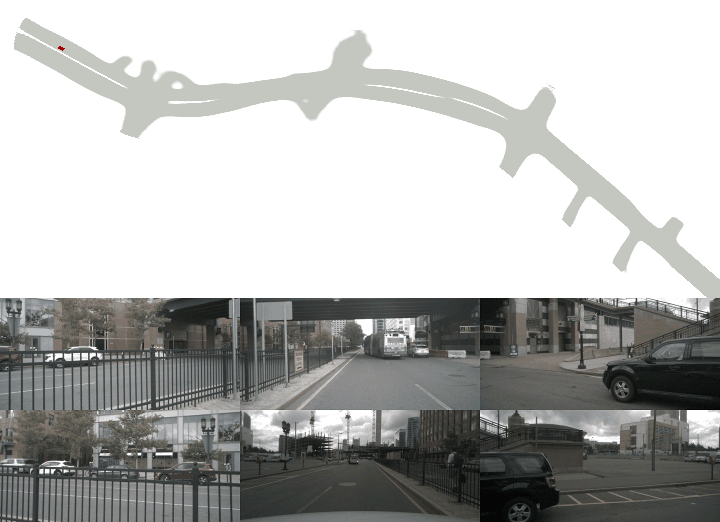
Installation
# Clone repo
git clone https://github.com/bradyz/cross_view_transformers.git

cd cross_view_transformers

# Setup conda environment
conda create -y --name cvt python=3.8

conda activate cvt
conda install -y pytorch torchvision cudatoolkit=11.3 -c pytorch

# Install dependencies
pip install -r requirements.txt
pip install -e .
Data
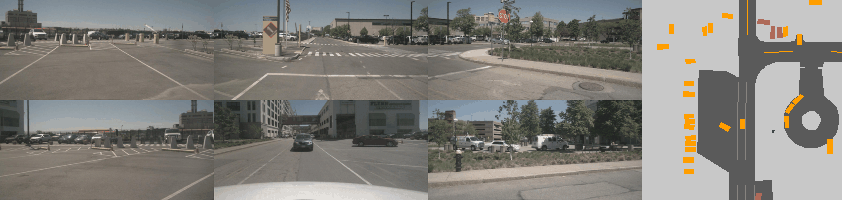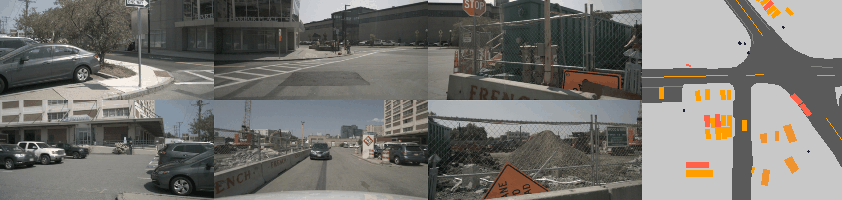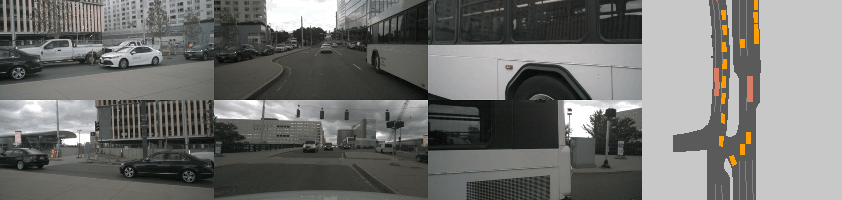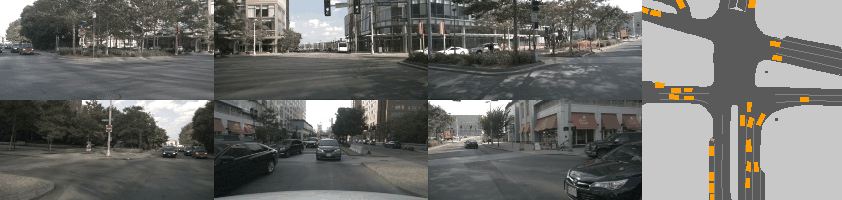
Documentation:
- Dataset setup
- Label generation (optional)
Download the original datasets and our generated map-view labels
| Dataset | Labels | |
|---|---|---|
| nuScenes | keyframes + map expansion (60 GB) | cvt_labels_nuscenes.tar.gz (361 MB) |
| Argoverse 1.1 | 3D tracking | coming soon™ |
The structure of the extracted data should look like the following
/datasets/
├─ nuscenes/
│  ├─ v1.0-trainval/
│  ├─ v1.0-mini/
│  ├─ samples/
│  ├─ sweeps/
│  └─ maps/
│     ├─ basemap/
│     └─ expansion/
└─ cvt_labels_nuscenes/
   ├─ scene-0001/
   ├─ scene-0001.json
   ├─ ...
   ├─ scene-1000/
   └─ scene-1000.json
When everything is setup correctly, check out the dataset with
python3 scripts/view_data.py \
  data=nuscenes \
  data.dataset_dir=/media/datasets/nuscenes \
  data.labels_dir=/media/datasets/cvt_labels_nuscenes \
  data.version=v1.0-mini \
  visualization=nuscenes_viz \
  +split=val
Training


An average job of 50k training iterations takes ~8 hours.
Our models were trained using 4 GPU jobs, but also can be trained on single GPU.
To train a model,
python3 scripts/train.py \
  +experiment=cvt_nuscenes_vehicle
  data.dataset_dir=/media/datasets/nuscenes \
  data.labels_dir=/media/datasets/cvt_labels_nuscenes
For more information, see
config/config.yaml- base configconfig/model/cvt.yaml- model architectureconfig/experiment/cvt_nuscenes_vehicle.yaml- additional overrides
Additional Information
Awesome Related Repos
- https://github.com/wayveai/fiery
- https://github.com/nv-tlabs/lift-splat-shoot
- https://github.com/tom-roddick/mono-semantic-maps
License
This project is released under the MIT license
Citation
If you find this project useful for your research, please use the following BibTeX entry.
@inproceedings{zhou2022cross,
    title={Cross-view Transformers for real-time Map-view Semantic Segmentation},
    author={Zhou, Brady and Kr{\"a}henb{\"u}hl, Philipp},
    booktitle={CVPR},
    year={2022}
}