
airscholar/e2e-data-engineering
airscholar/e2e-data-engineering has 371 GitHub stars and 159 forks. GitHot measured +1 stars in 24 hours and +1 in 7 days. Last checked 2026-11-09 16:59 UTC. Last push 2025-02-14.
An end-to-end data engineering pipeline that orchestrates data ingestion, processing, and storage using Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. All components are containerized with Docker for easy deployment and scalability.
計測したスター増加
- 24時間
- +1
- 7日間
- +1
- 15日間
- 更新が遅れています
- 1か月
- 更新が遅れています
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
README.md
オリジナルRealtime Data Streaming | End-to-End Data Engineering Project
Table of Contents
- Introduction
- System Architecture
- What You'll Learn
- Technologies
- Getting Started
- Watch the Video Tutorial
Introduction
This project serves as a comprehensive guide to building an end-to-end data engineering pipeline. It covers each stage from data ingestion to processing and finally to storage, utilizing a robust tech stack that includes Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. Everything is containerized using Docker for ease of deployment and scalability.
System Architecture
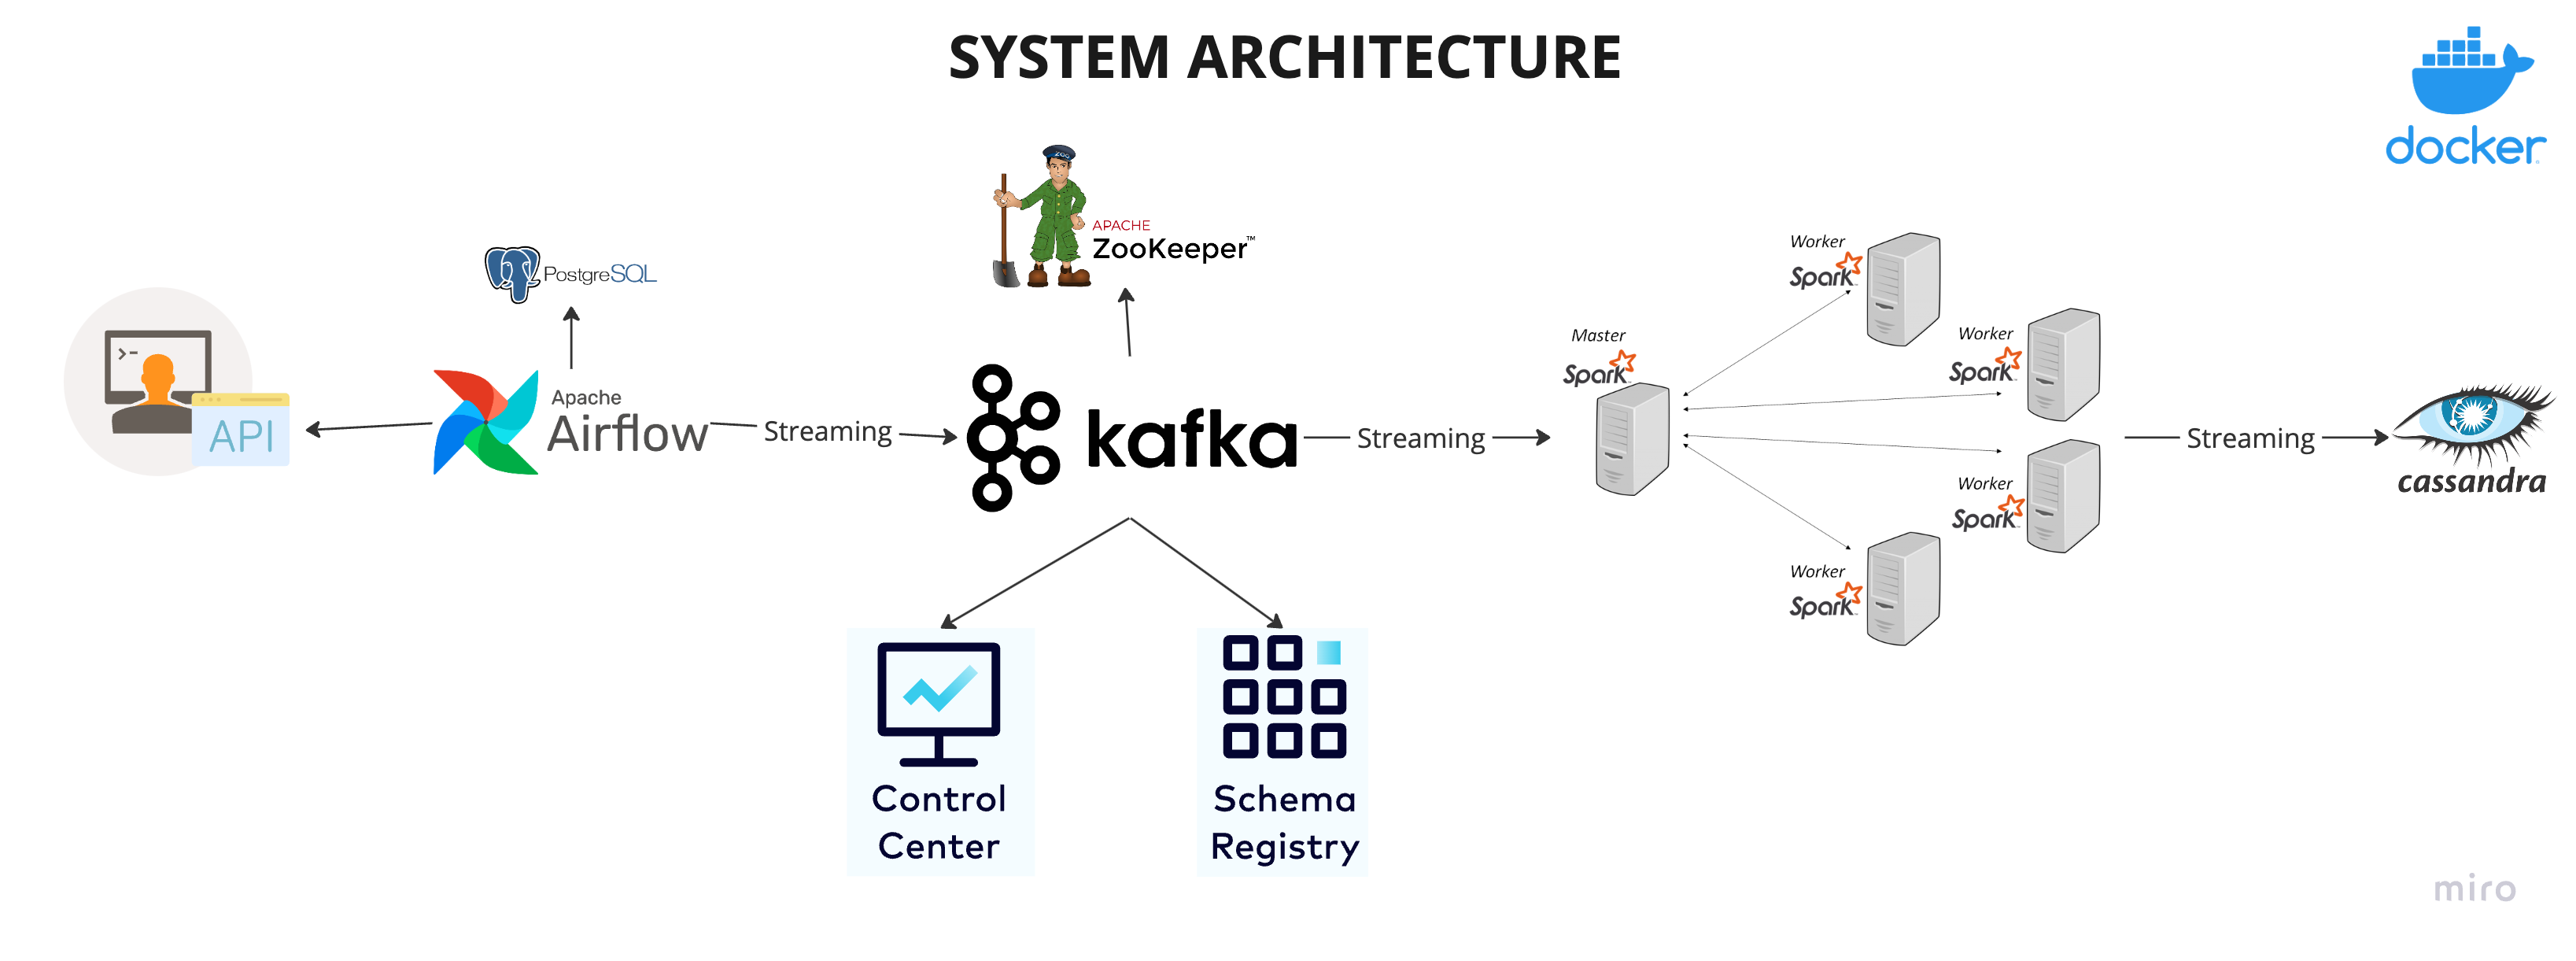
The project is designed with the following components:
- Data Source: We use
randomuser.meAPI to generate random user data for our pipeline. - Apache Airflow: Responsible for orchestrating the pipeline and storing fetched data in a PostgreSQL database.
- Apache Kafka and Zookeeper: Used for streaming data from PostgreSQL to the processing engine.
- Control Center and Schema Registry: Helps in monitoring and schema management of our Kafka streams.
- Apache Spark: For data processing with its master and worker nodes.
- Cassandra: Where the processed data will be stored.
What You'll Learn
- Setting up a data pipeline with Apache Airflow
- Real-time data streaming with Apache Kafka
- Distributed synchronization with Apache Zookeeper
- Data processing techniques with Apache Spark
- Data storage solutions with Cassandra and PostgreSQL
- Containerizing your entire data engineering setup with Docker
Technologies
- Apache Airflow
- Python
- Apache Kafka
- Apache Zookeeper
- Apache Spark
- Cassandra
- PostgreSQL
- Docker
Getting Started
Clone the repository:
git clone https://github.com/airscholar/e2e-data-engineering.gitNavigate to the project directory:
cd e2e-data-engineeringRun Docker Compose to spin up the services:
docker-compose up
For more detailed instructions, please check out the video tutorial linked below.
Watch the Video Tutorial
For a complete walkthrough and practical demonstration, check out our YouTube Video Tutorial.
関連プロジェクトを探す
Asabeneh/30-Days-Of-Python
30 Days of Python プログラミングチャレンジは、Python プログラミング言語を 30 日で学ぶためのステップバイステップのガイドです。このチャレンジは 100 日以上かかることもあります。自分のペースで進めてください。こちらの動画も役立つかもしれません: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,486 スターgrafana/grafana
オープンで組み合わせ可能なオブザーバビリティおよびデータ可視化プラットフォームです。Prometheus、Loki、Elasticsearch、InfluxDB、Postgres など、複数のソースからメトリクス、ログ、トレースを可視化できます。
77,790 スターredis/redis
リアルタイムのデータ駆動型アプリケーションを構築する開発者にとって、Redis は最も選ばれ、最速で、機能が最も豊富なキャッシュ、データ構造サーバー、ドキュメントおよびベクトルクエリエンジンです。
77,332 スターapache/superset
Apache Superset は、データ可視化とデータ探索のためのプラットフォームです。
75,455 スター