
adaptive-machine-learning/CapyMOA has 153 GitHub stars and 51 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and 0 in 15 days. Last checked 2026-11-22 06:48 UTC. Last push 2026-11-20.
計測したスター増加
- 24時間
- 0
- 7日間
- 0
- 15日間
- 0
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
概要
CapyMOA does efficient machine learning for data streams in Python. CapyMOA is a toolbox of methods and evaluators for: classification, regression, clustering, anomaly detection, semi-supervised learning, online continual learning, and drift detection for data streams.
機械学習README.md
オリジナルCapyMOA


CapyMOA does efficient machine learning for data streams in Python. A data stream is a sequence of items that arrive one by one and are too large or urgent to process offline. CapyMOA is a toolbox of methods and evaluators for: classification, regression, clustering, anomaly detection, semi-supervised learning, online continual learning, and drift detection for data streams.
To install:
pip install capymoa
The deep-learning parts of CapyMOA (capymoa.ocl, capymoa.core.torch.ann, the Batch*
learners) need PyTorch, which is an optional extra:
pip install capymoa[torch]
Refer to the Setup guide for other options, including CPU-only PyTorch and dev dependencies.
from capymoa.datasets import Electricity
from capymoa.classifier import HoeffdingTree, evaluate_classifier

# 1. Load a streaming dataset
stream = Electricity()

# 2. Create a machine learning model
model = HoeffdingTree(stream.get_schema())

# 3. Run with test-then-train evaluation
results = evaluate_classifier(stream, model)

# 4. Success!
print(f"Accuracy: {results['cumulative']['accuracy']:.2f}%")
Next, we recommend the Tutorials.
⚠️ WARNING
CapyMOA is still in the early stages of development. The API is subject to change until version 1.0.0. If you encounter any issues, please report them in GitHub Issues or talk to us on Discord.
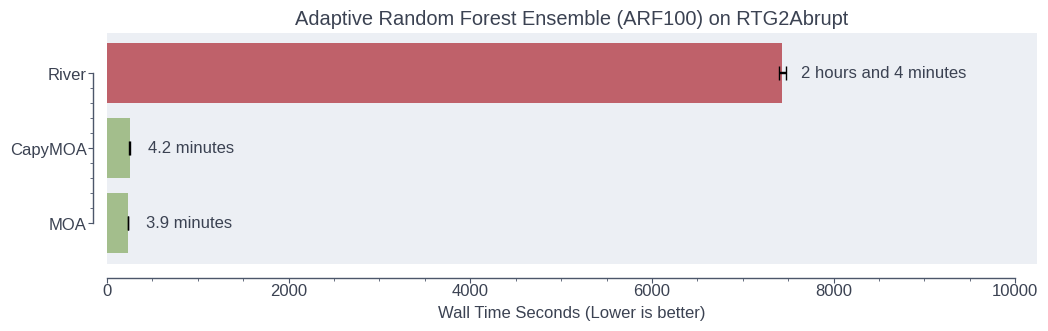 Benchmark comparing CapyMOA against other data stream libraries. The benchmark
was performed using an ensemble of 100 ARF learners trained on
the
capymoa.datasets.RTG_2abrupt dataset containing 100,000 samples and 30
features. You can find the code to reproduce this benchmark in
benchmarks/README.md, with the runnable script at
benchmarks/benchmarking.py.
CapyMOA has the speed of MOA with the flexibility of Python and the richness of
Python's data science ecosystem.
Cite Us
If you use CapyMOA in your research, please cite us using the following BibTeX item.
@misc{gomes2025,
  title={{CapyMOA}: Efficient Machine Learning for Data Streams and Online Continual Learning in Python},
  author={Heitor Murilo Gomes and Anton Lee and Nuwan Gunasekara and Yibin Sun and Guilherme Weigert Cassales and Justin Jia Liu and Marco Heyden and Vitor Cerqueira and Maroua Bahri and Yun Sing Koh and Bernhard Pfahringer and Albert Bifet},
  year={2025},
  eprint={2502.07432},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2502.07432}
}
関連プロジェクトを探す
読み込み中…