
YudongGuo/AD-NeRF has 1,072 GitHub stars and 177 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-12 07:28 UTC. Last push 2023-10-27.
This repository contains a PyTorch implementation of "AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis".
計測したスター増加
- 24時間
- 0
- 7日間
- 0
- 15日間
- 履歴を収集中
- 1か月
- 履歴を収集中
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
README.md
オリジナルAD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis
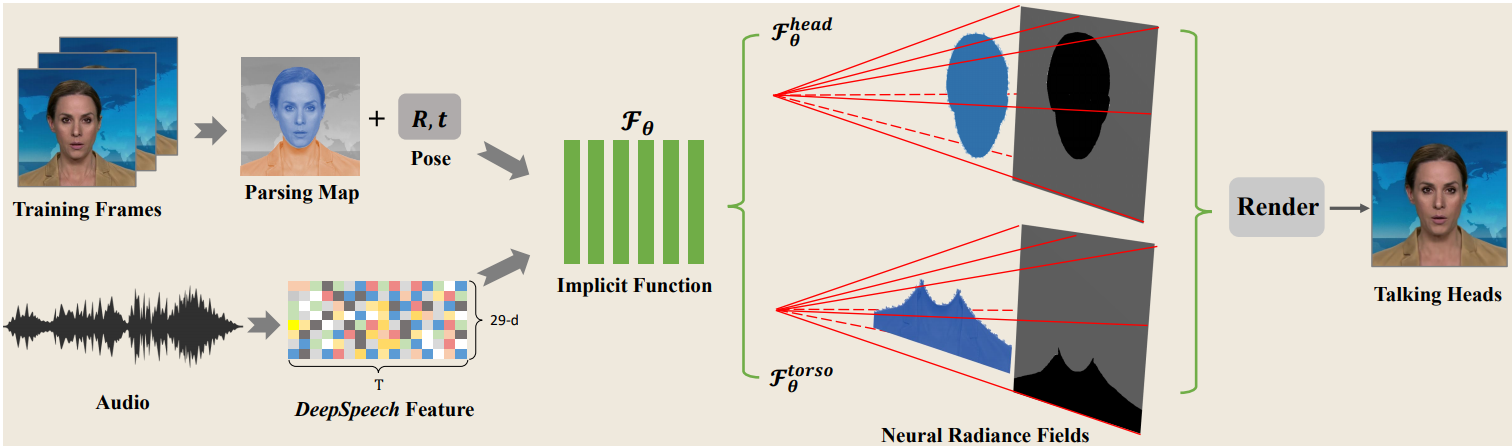
PyTorch implementation for the paper "AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis (ICCV 2021)".
Authors: Yudong Guo, Keyu Chen, Sen Liang, Yong-Jin Liu, Hujun Bao and Juyong Zhang.
Prerequisites
You can create an anaconda environment called adnerf with:
conda env create -f environment.yml conda activate adnerf-
Recommend install from a local clone
git clone https://github.com/facebookresearch/pytorch3d.git cd pytorch3d && pip install -e . -
Put "01_MorphableModel.mat" to data_util/face_tracking/3DMM/; cd data_util/face_tracking; run
python convert_BFM.py
Train AD-NeRF
Data Preprocess ($id Obama for example)
bash process_data.sh Obama- Input: A portrait video at 25fps containing voice audio. (dataset/vids/$id.mp4)
- Output: folder dataset/$id that contains all files for training
Train Two NeRFs (Head-NeRF and Torso-NeRF)
- Train Head-NeRF with command
python NeRFs/HeadNeRF/run_nerf.py --config dataset/$id/HeadNeRF_config.txt - Copy latest trainied model from dataset/$id/logs/$id_head to dataset/$id/logs/$id_com
- Train Torso-NeRF with command
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRF_config.txt - You may need the pretrained models to avoid bad initialization. #3
- Train Head-NeRF with command
Run AD-NeRF for rendering
- Reconstruct original video with audio input
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRFTest_config.txt --aud_file=dataset/$id/aud.npy --test_size=300 - Drive the target person with another audio input
python NeRFs/TorsoNeRF/run_nerf.py --config dataset/$id/TorsoNeRFTest_config.txt --aud_file=${deepspeechfile.npy} --test_size=-1
Citation
If you find our work useful in your research, please consider citing our paper:
@inproceedings{guo2021adnerf,
  title={AD-NeRF: Audio Driven Neural Radiance Fields for Talking Head Synthesis},
  author={Yudong Guo and Keyu Chen and Sen Liang and Yongjin Liu and Hujun Bao and Juyong Zhang},
  booktitle={IEEE/CVF International Conference on Computer Vision (ICCV)},
  year={2021}
}
If you have questions, feel free to contact [email protected].
Acknowledgments
We use face-parsing.PyTorch for parsing head and torso maps, and DeepSpeech for audio feature extraction. The NeRF model is implemented based on NeRF-pytorch.
関連プロジェクトを探す
tensorflow/tensorflow
すべての人のためのオープンソース機械学習フレームワーク
201,505 スターhuggingface/transformers
🤗 Transformers:テキスト、ビジョン、音声、マルチモーダルの最先端機械学習モデル向けモデル定義フレームワークで、推論と学習の両方に対応します。
168,815 スターAUTOMATIC1111/stable-diffusion-webui
Stable Diffusion の Web UI
165,289 スターComfy-Org/ComfyUI
グラフとノードによるインターフェースを備えた、最も強力でモジュール性の高い拡散モデル向け GUI、API、バックエンド。世界最速のローカル推論エンジン。
146,271 スター