
FragDB/fragrance-database has 72 GitHub stars and 18 forks. Star changes are not measured yet. Last checked 2026-11-09 10:22 UTC. Last push 2026-11-01.
FragDB — Fragrance Database (multilingual): 134K+ fragrances, 23 languages, 4.9M UGC rows in companion parquets. Free 10-record samples.
できること
- 23 languages — English + 22 translations for all labels, note names, accords, countries, statuses
- Relational structure — Files linked via unique IDs
- Rich fragrance data — Notes pyramid, accords, ratings, votes
- Brand profiles — Logo, country, website, parent company (country/activity translated)
計測したスター増加
- 24時間
- 更新が遅れています
- 7日間
- 更新が遅れています
- 15日間
- 更新が遅れています
- 1か月
- 更新が遅れています
期間ごとの純増数です。期間は重複しており、日別の値ではありません。未計測の値は空欄です。スター数は注目度の指標であり、品質の保証ではありません。
README.md
オリジナルFragDB - Fragrance Database (Multilingual)
The most comprehensive fragrance database available — 158,000+ structured records across six interconnected CSV files with 23 language translations, plus 5.3M+ user-generated content rows in Apache Parquet companion datasets covering user reviews, editorial news articles, and community discussions.


Keywords: fragrance database · perfume dataset · Fragrantika · user reviews · perfume reviews · fragrance news · perfumery articles · cosmetics dataset · multilingual perfume data · scent recommendation · fragrance recommender system · perfume sentiment analysis · perfumer profiles · accord taxonomy · notes pyramid · NLP fragrance corpus · 23 languages
Overview
FragDB provides structured data for the fragrance industry:
| File | Records | Fields | Description |
|---|---|---|---|
fragrances.csv |
143,855 | 30 | Main fragrance database |
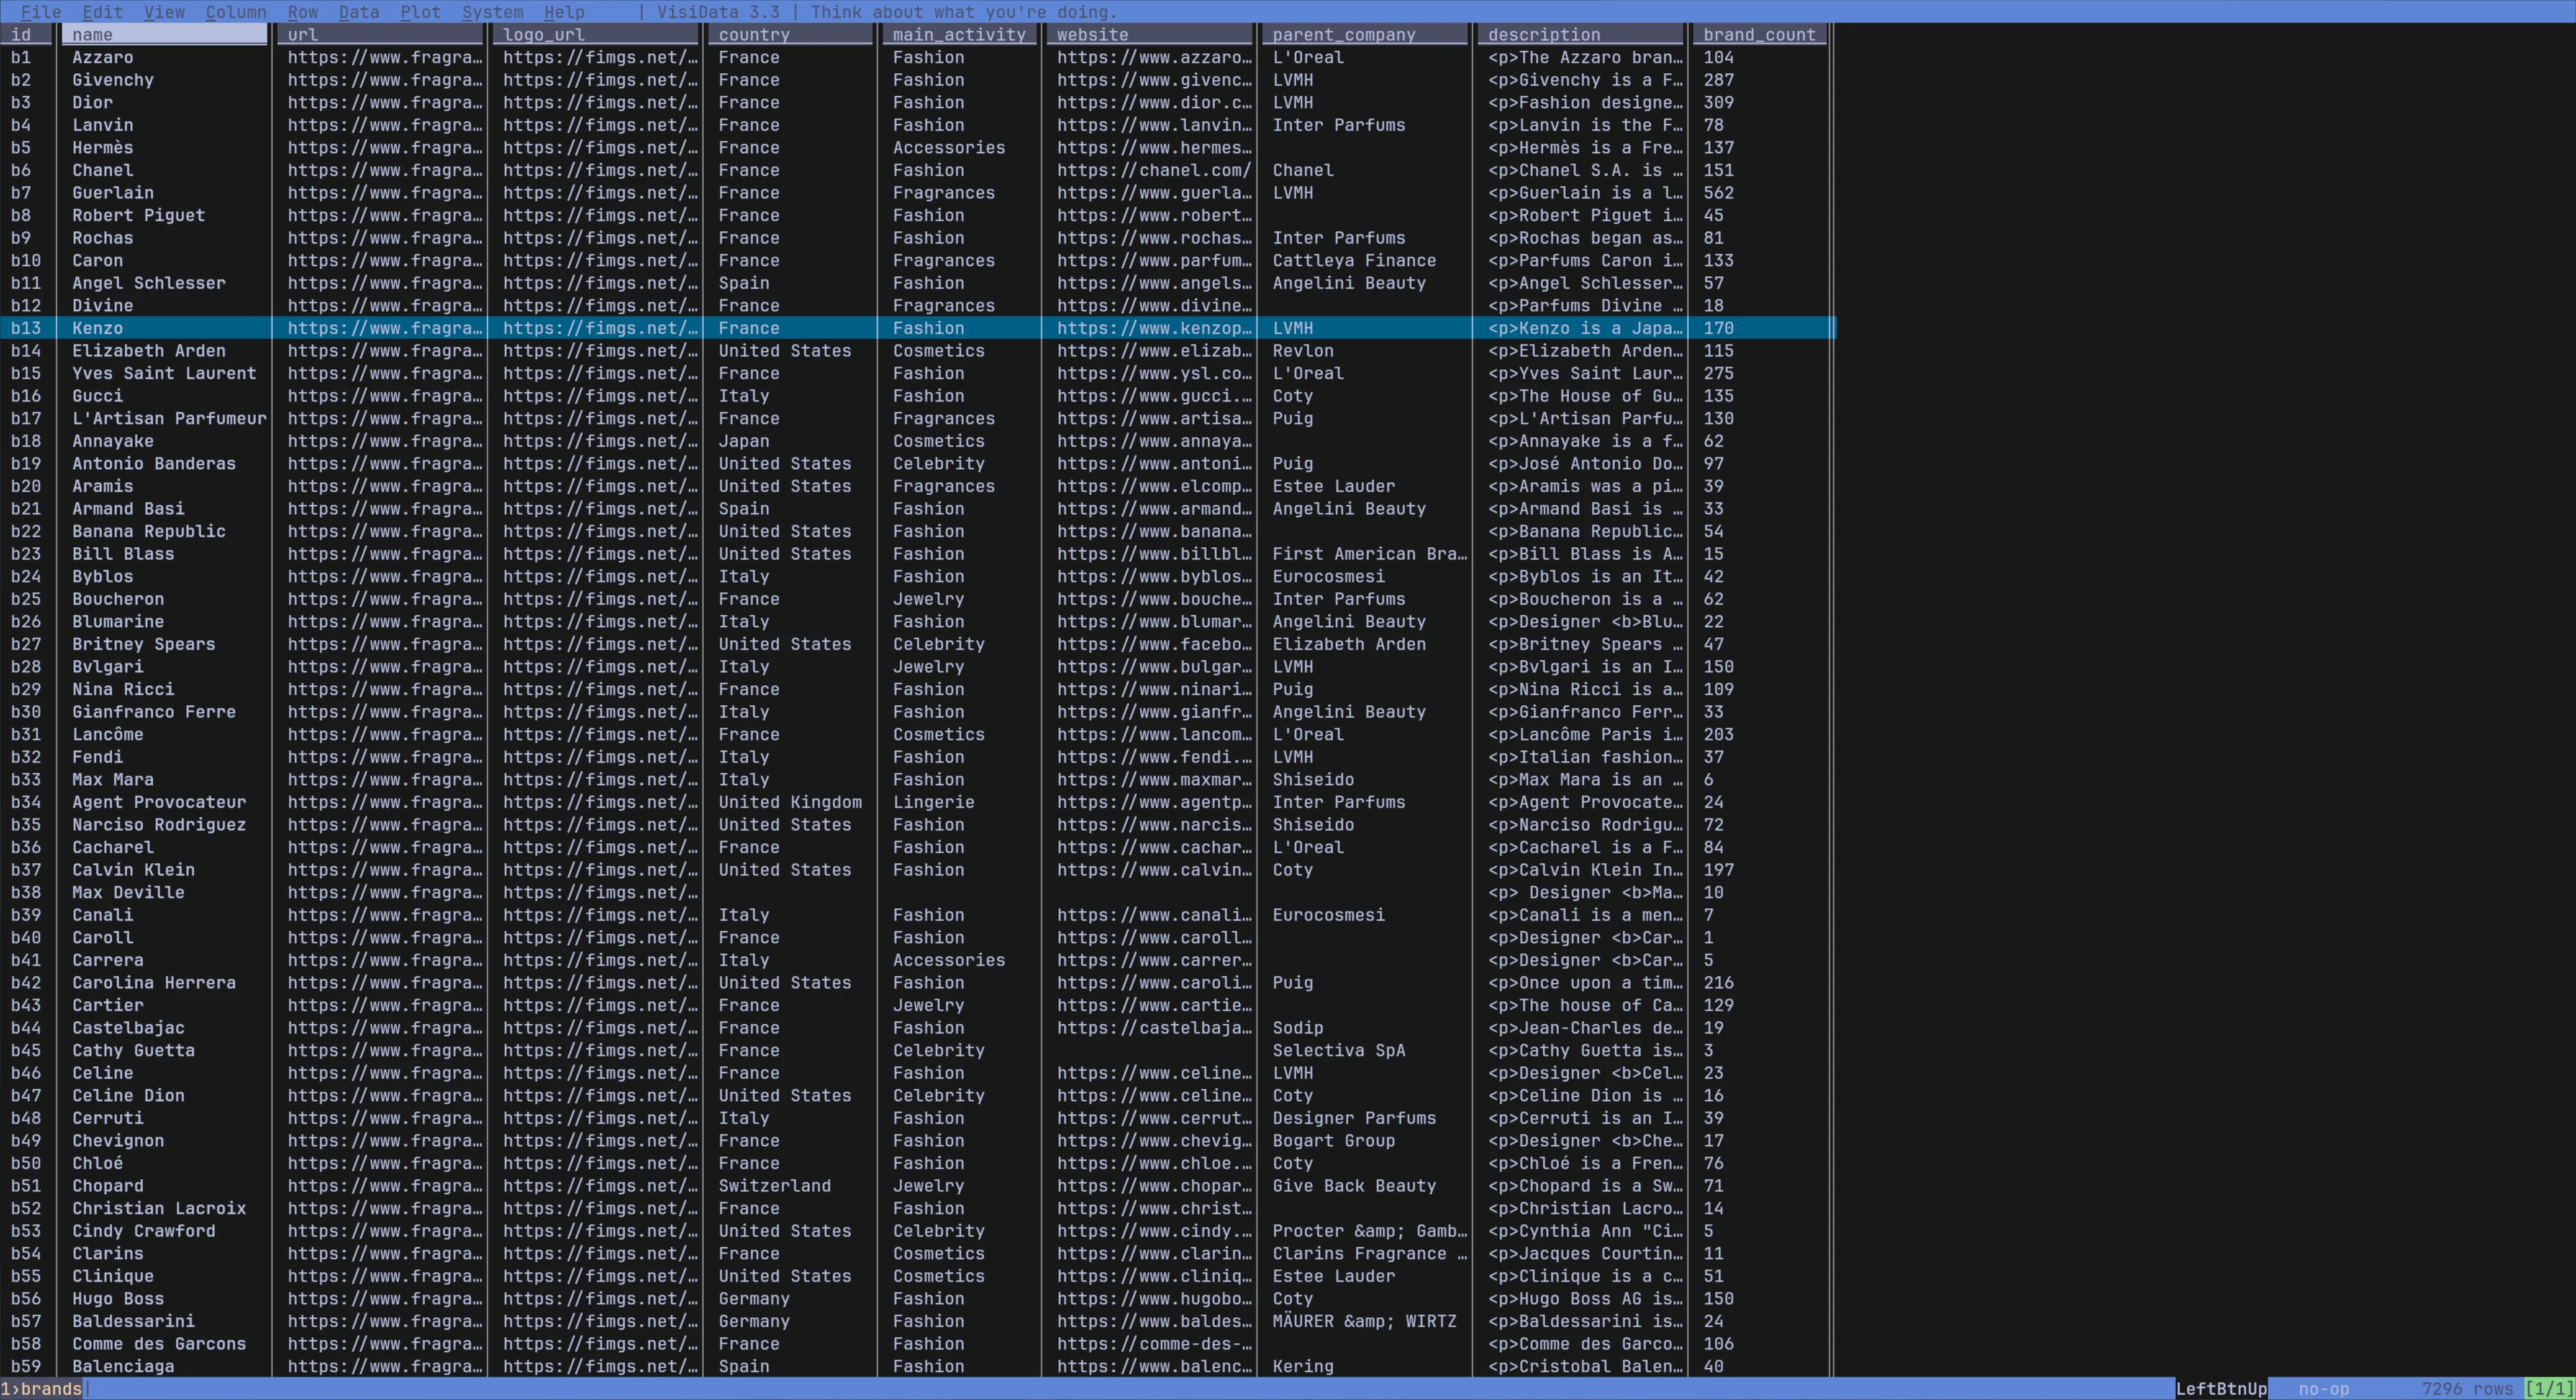
brands.csv |
8,501 | 54 | Brand profiles + translations |
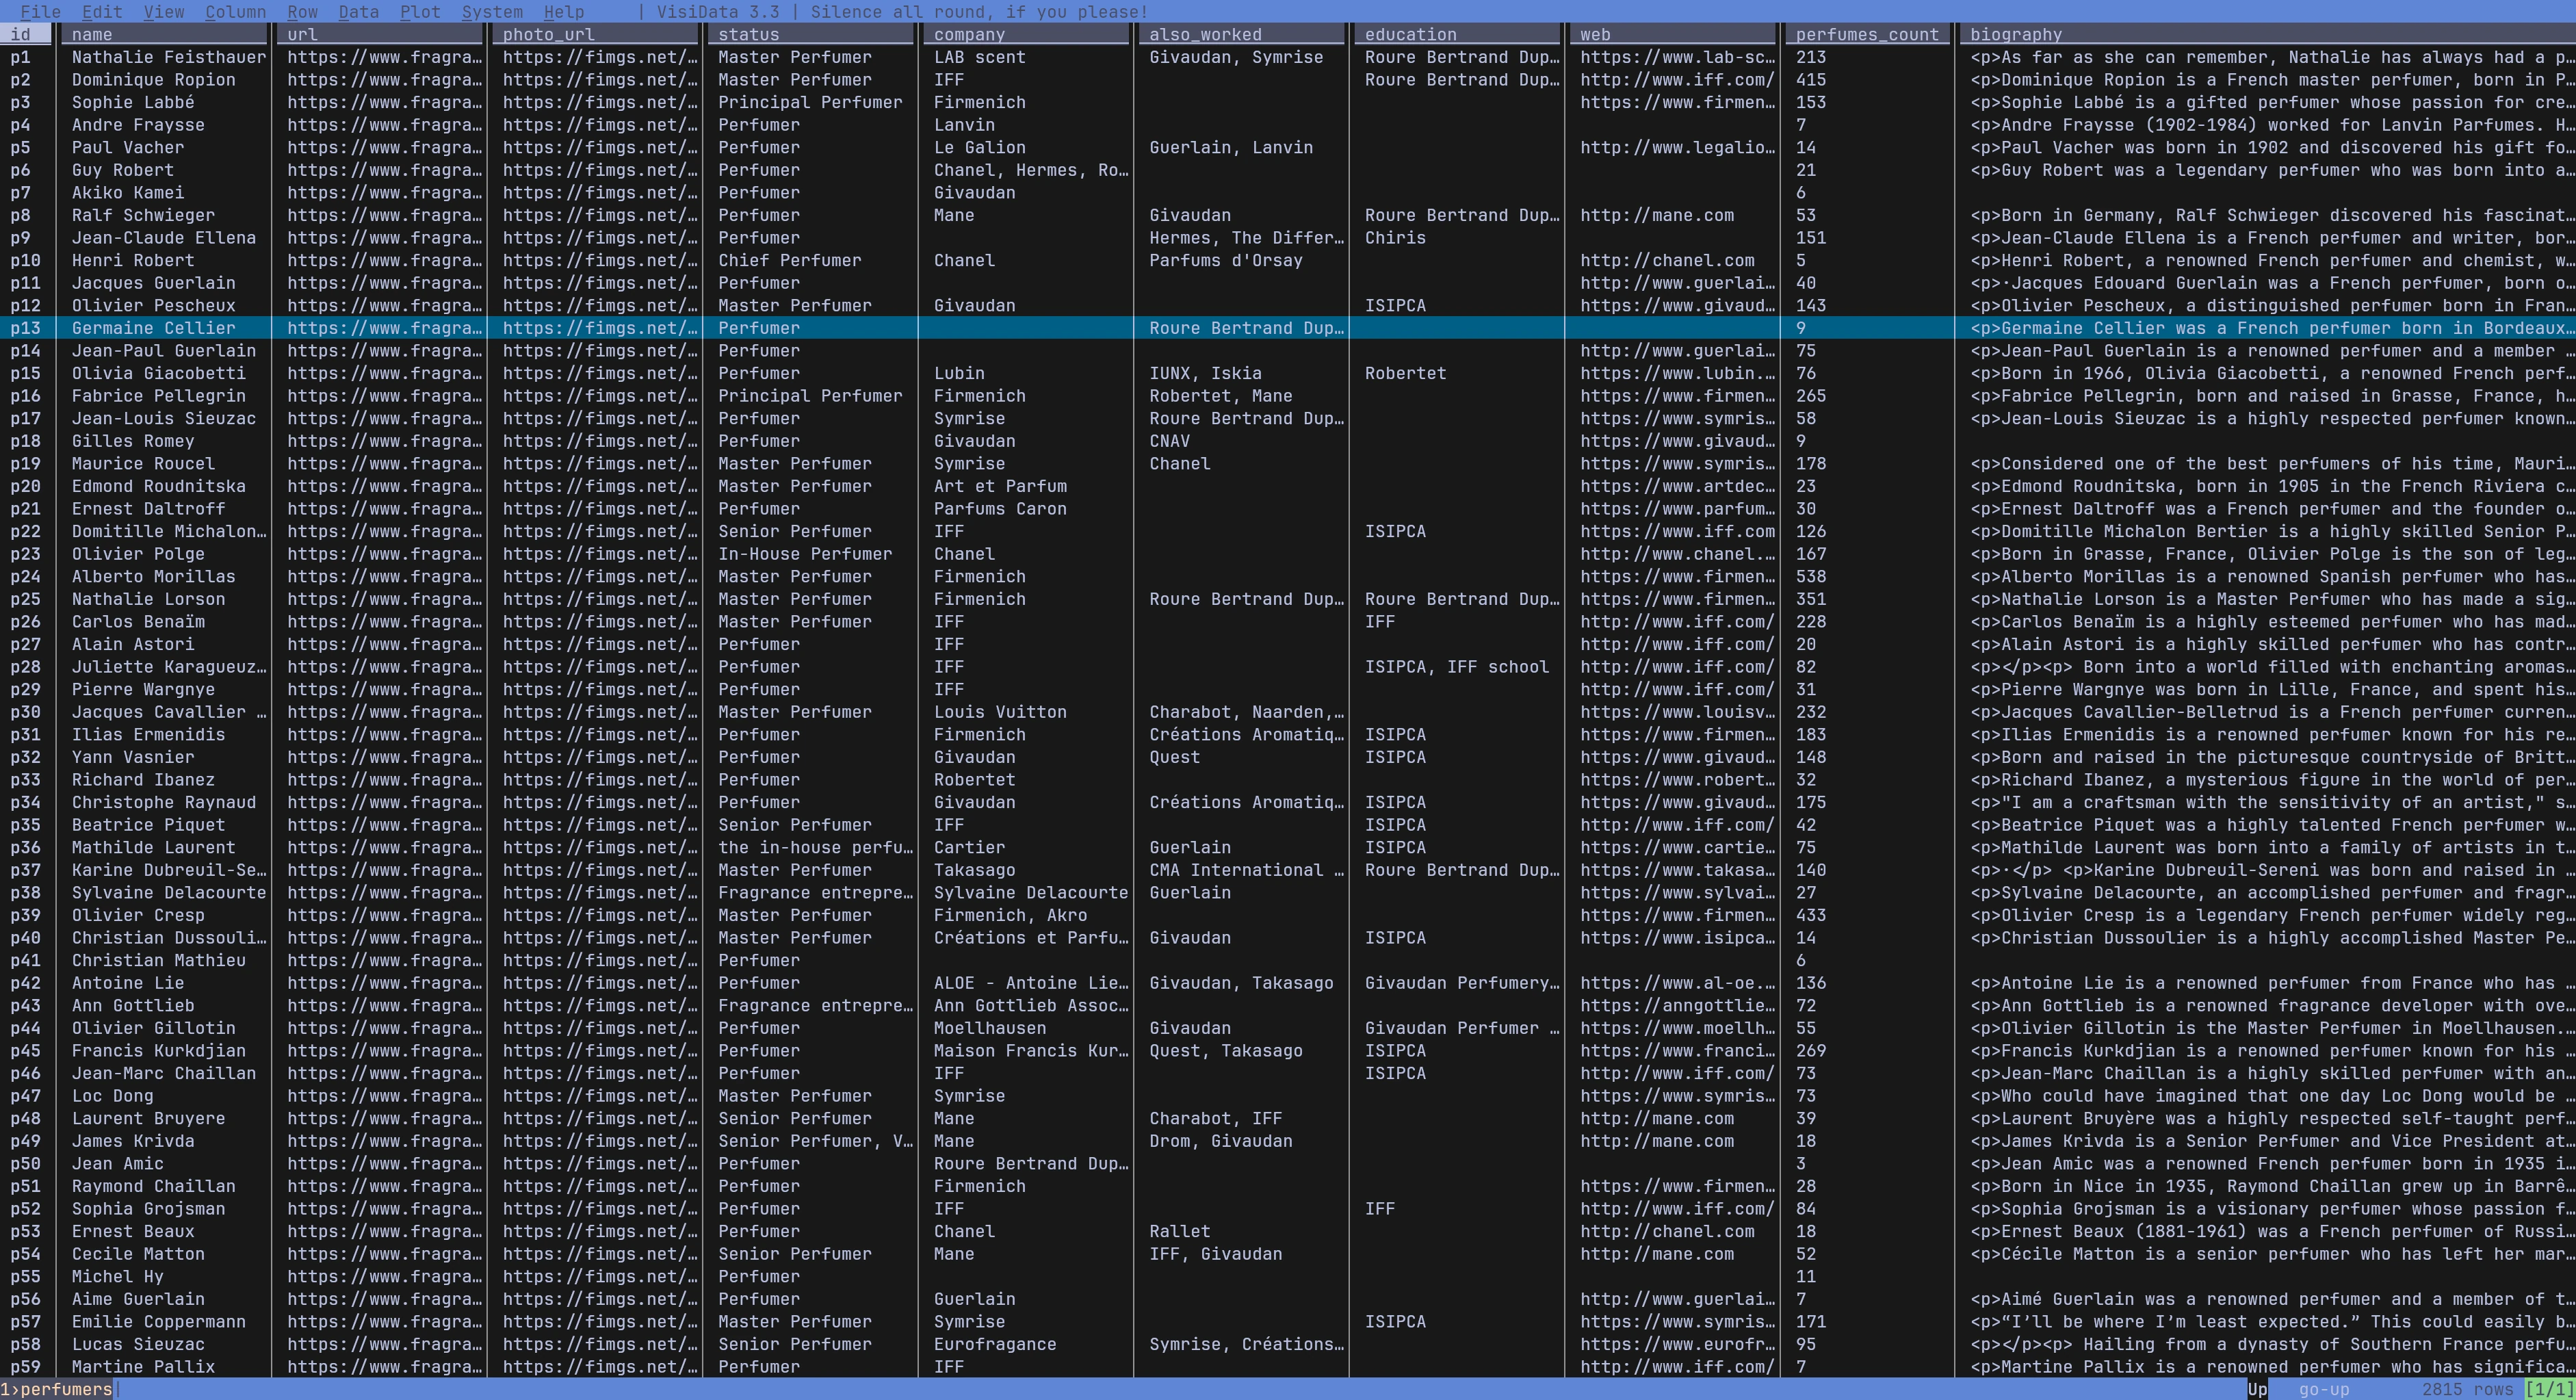
perfumers.csv |
3,198 | 42 | Perfumer profiles + translations |
notes.csv |
2,626 | 55 | Fragrance notes + translations |
accords.csv |
92 | 27 | Accords + translations |
translations.csv |
34 | 25 | Vocabulary: gender & voting labels × 23 languages |
Snapshot freshness
- Data refreshed: 2026-11-01 (v5.20) — an incremental update: the 1,179 fragrances new at the source were added on 2026-11-01; the existing records are carried over from v5.19 (as captured on 2026-10-08, and on 2026-10-19 for the 1,135 added in v5.19)
- Reviews, news, news comments (parquet): refreshed in this release — latest review 2026-10-31, latest article 2026-10-29, latest news comment 2026-11-01
Key Features
- 23 languages — English + 22 translations for all labels, note names, accords, countries, statuses
- Relational structure — Files linked via unique IDs
- Rich fragrance data — Notes pyramid, accords, ratings, votes
- Brand profiles — Logo, country, website, parent company (country/activity translated)
- Perfumer profiles — Photo, status, company, education, biography (status translated)
- Notes reference — 2,626 notes with translations, Latin names, groups, odor profiles
- Accords reference — Display colors + translated names
- Translation vocabulary — 34 entries for gender and voting labels
- Pipe-delimited CSV — Easy parsing, UTF-8 encoded
Preview
Fragrances
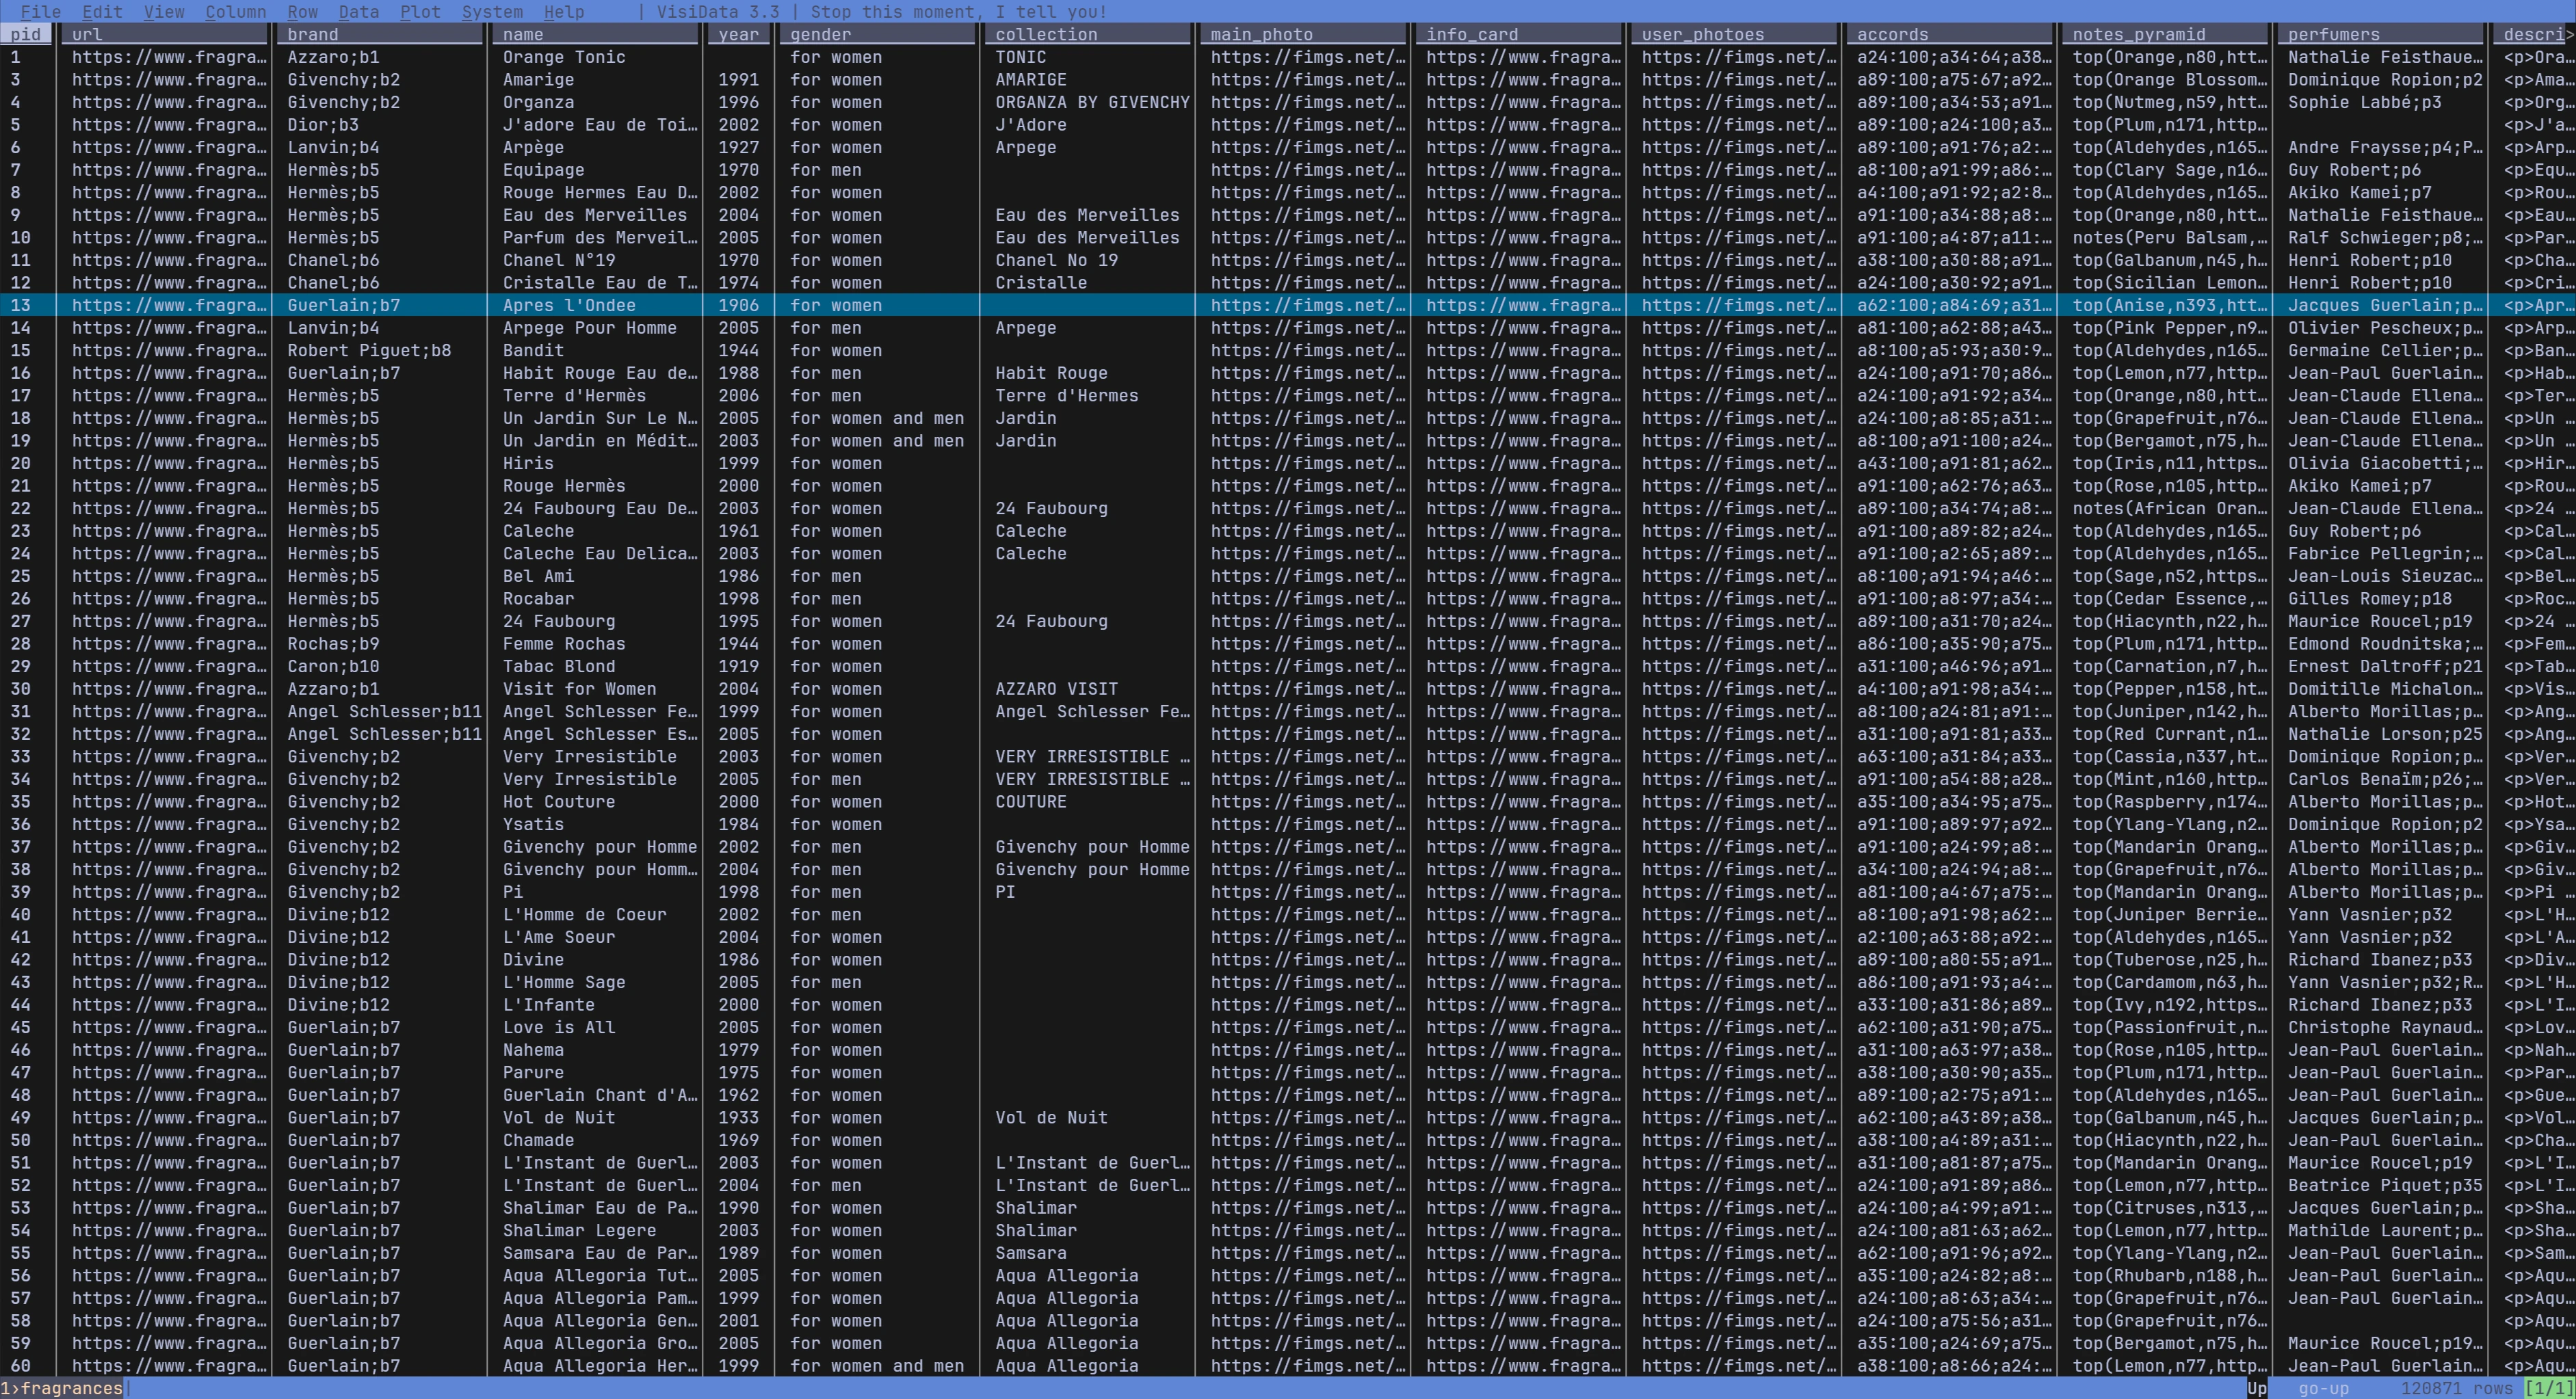
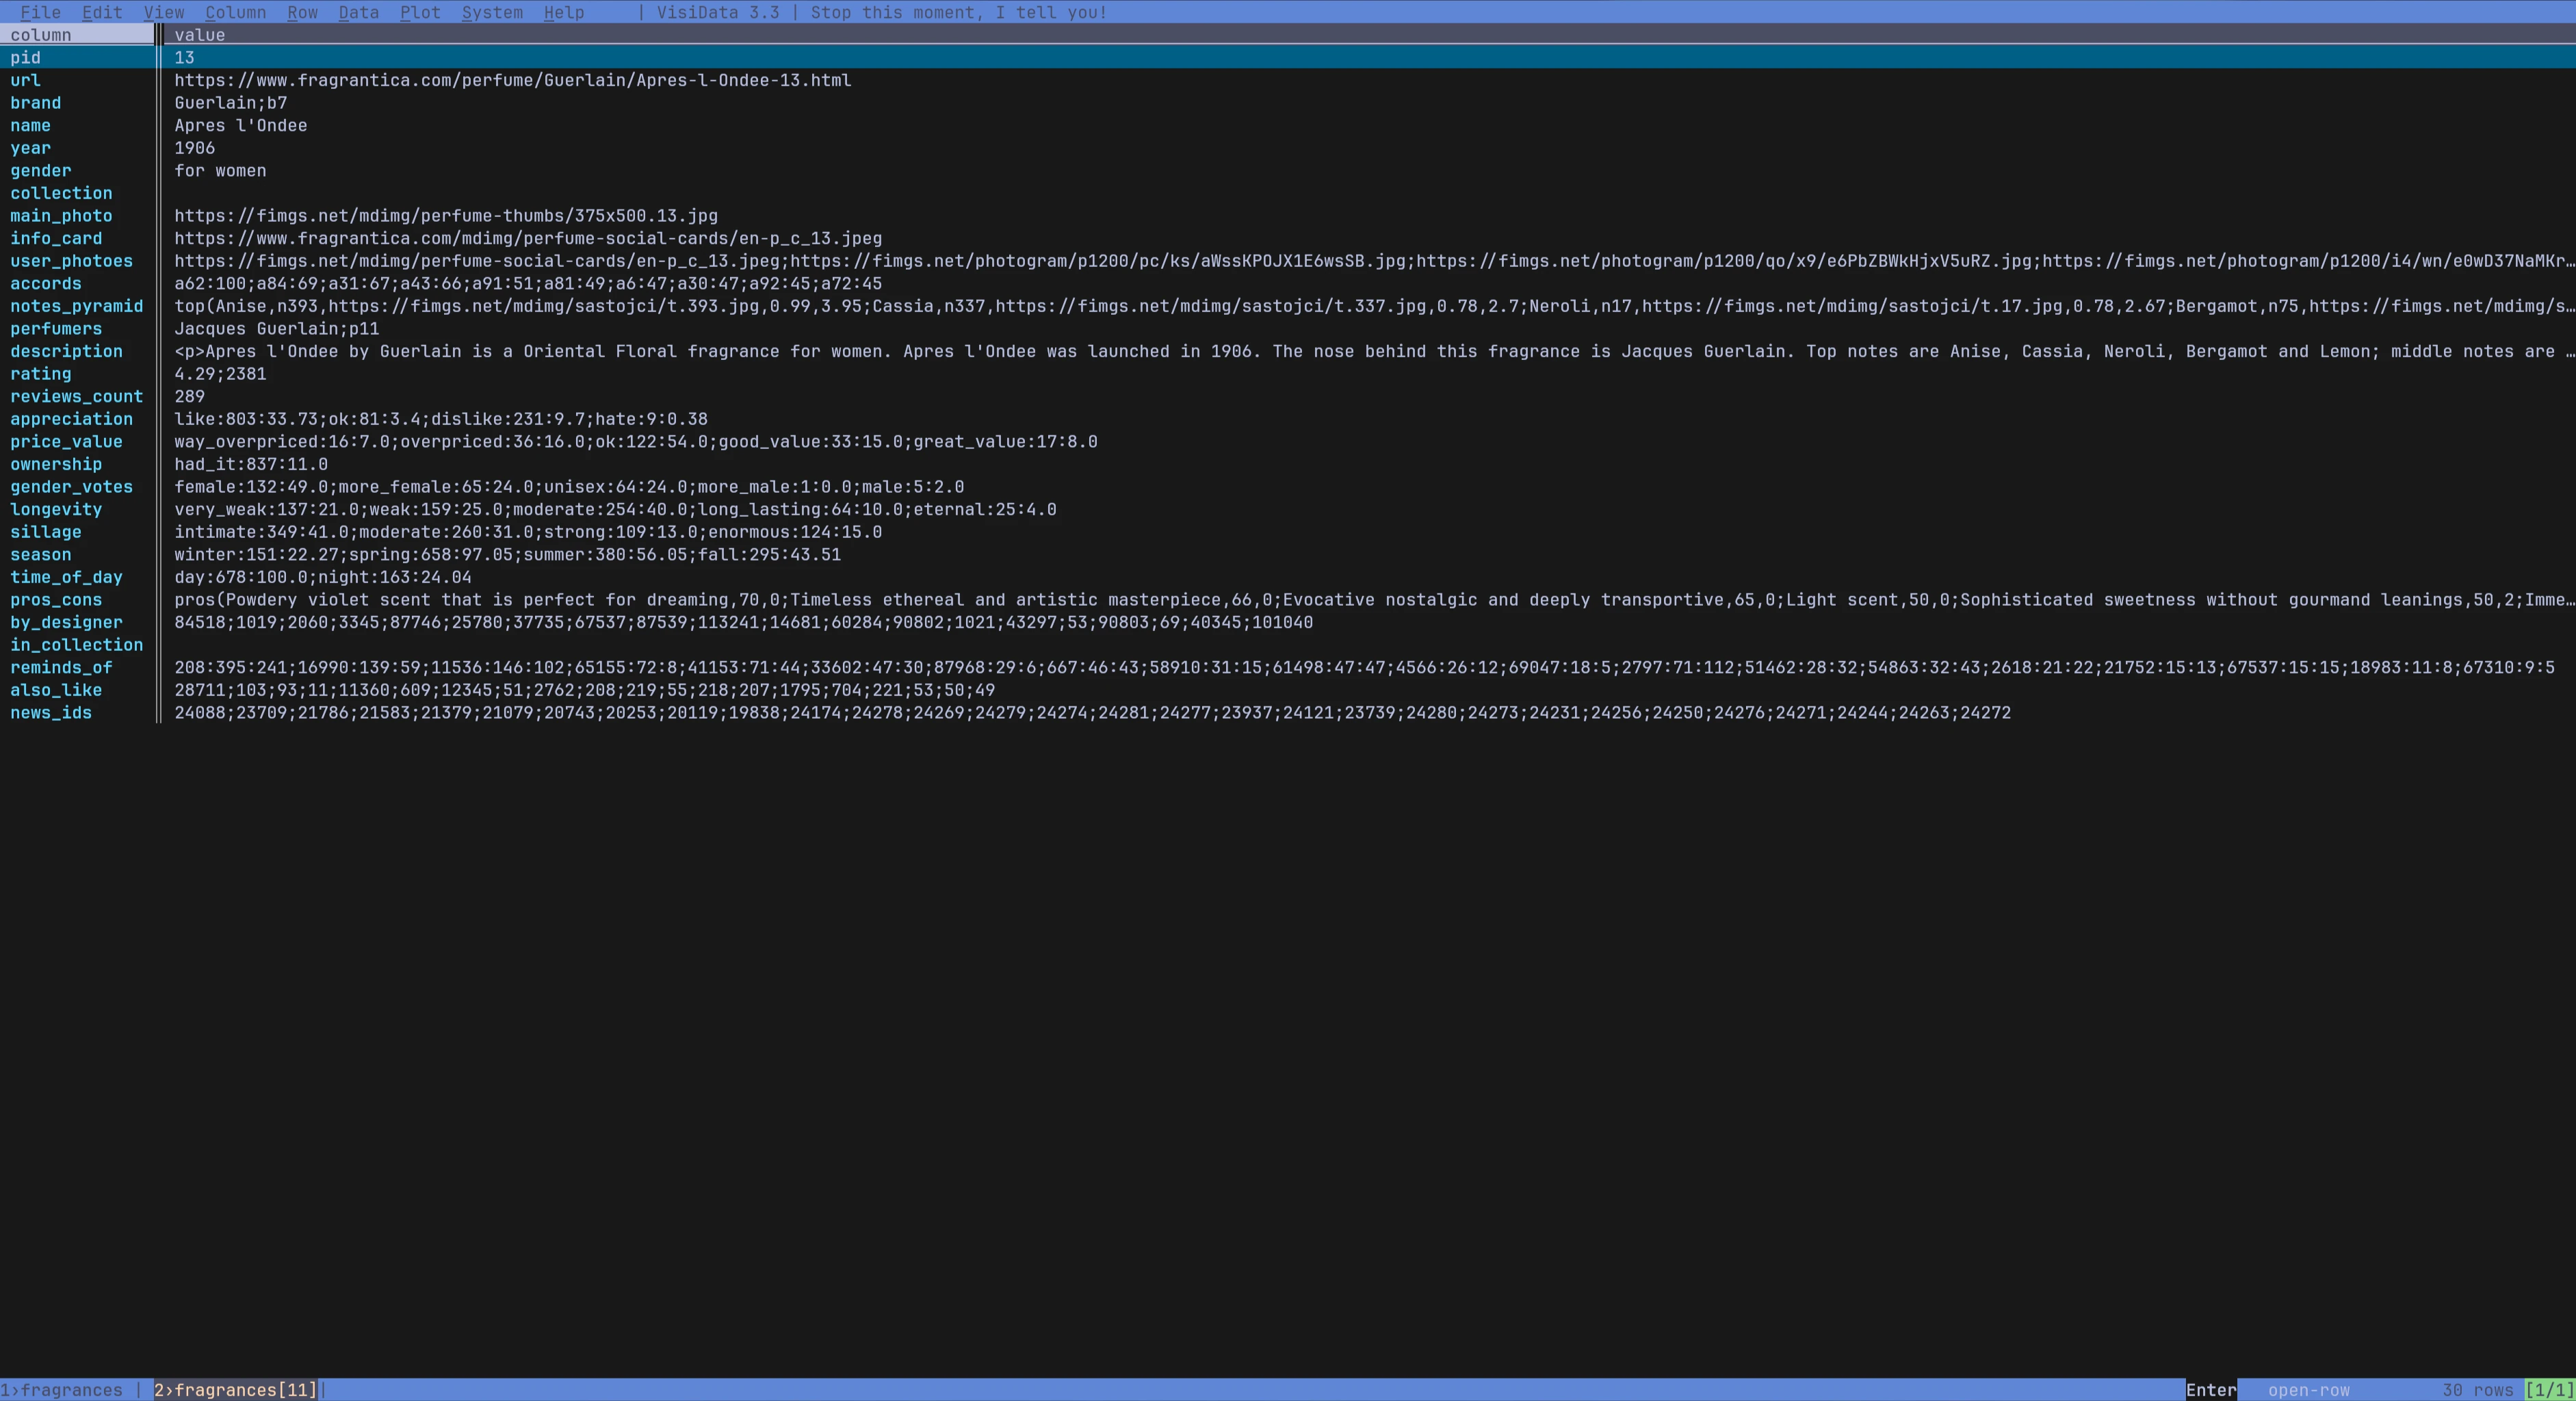
Brands & Perfumers
Notes
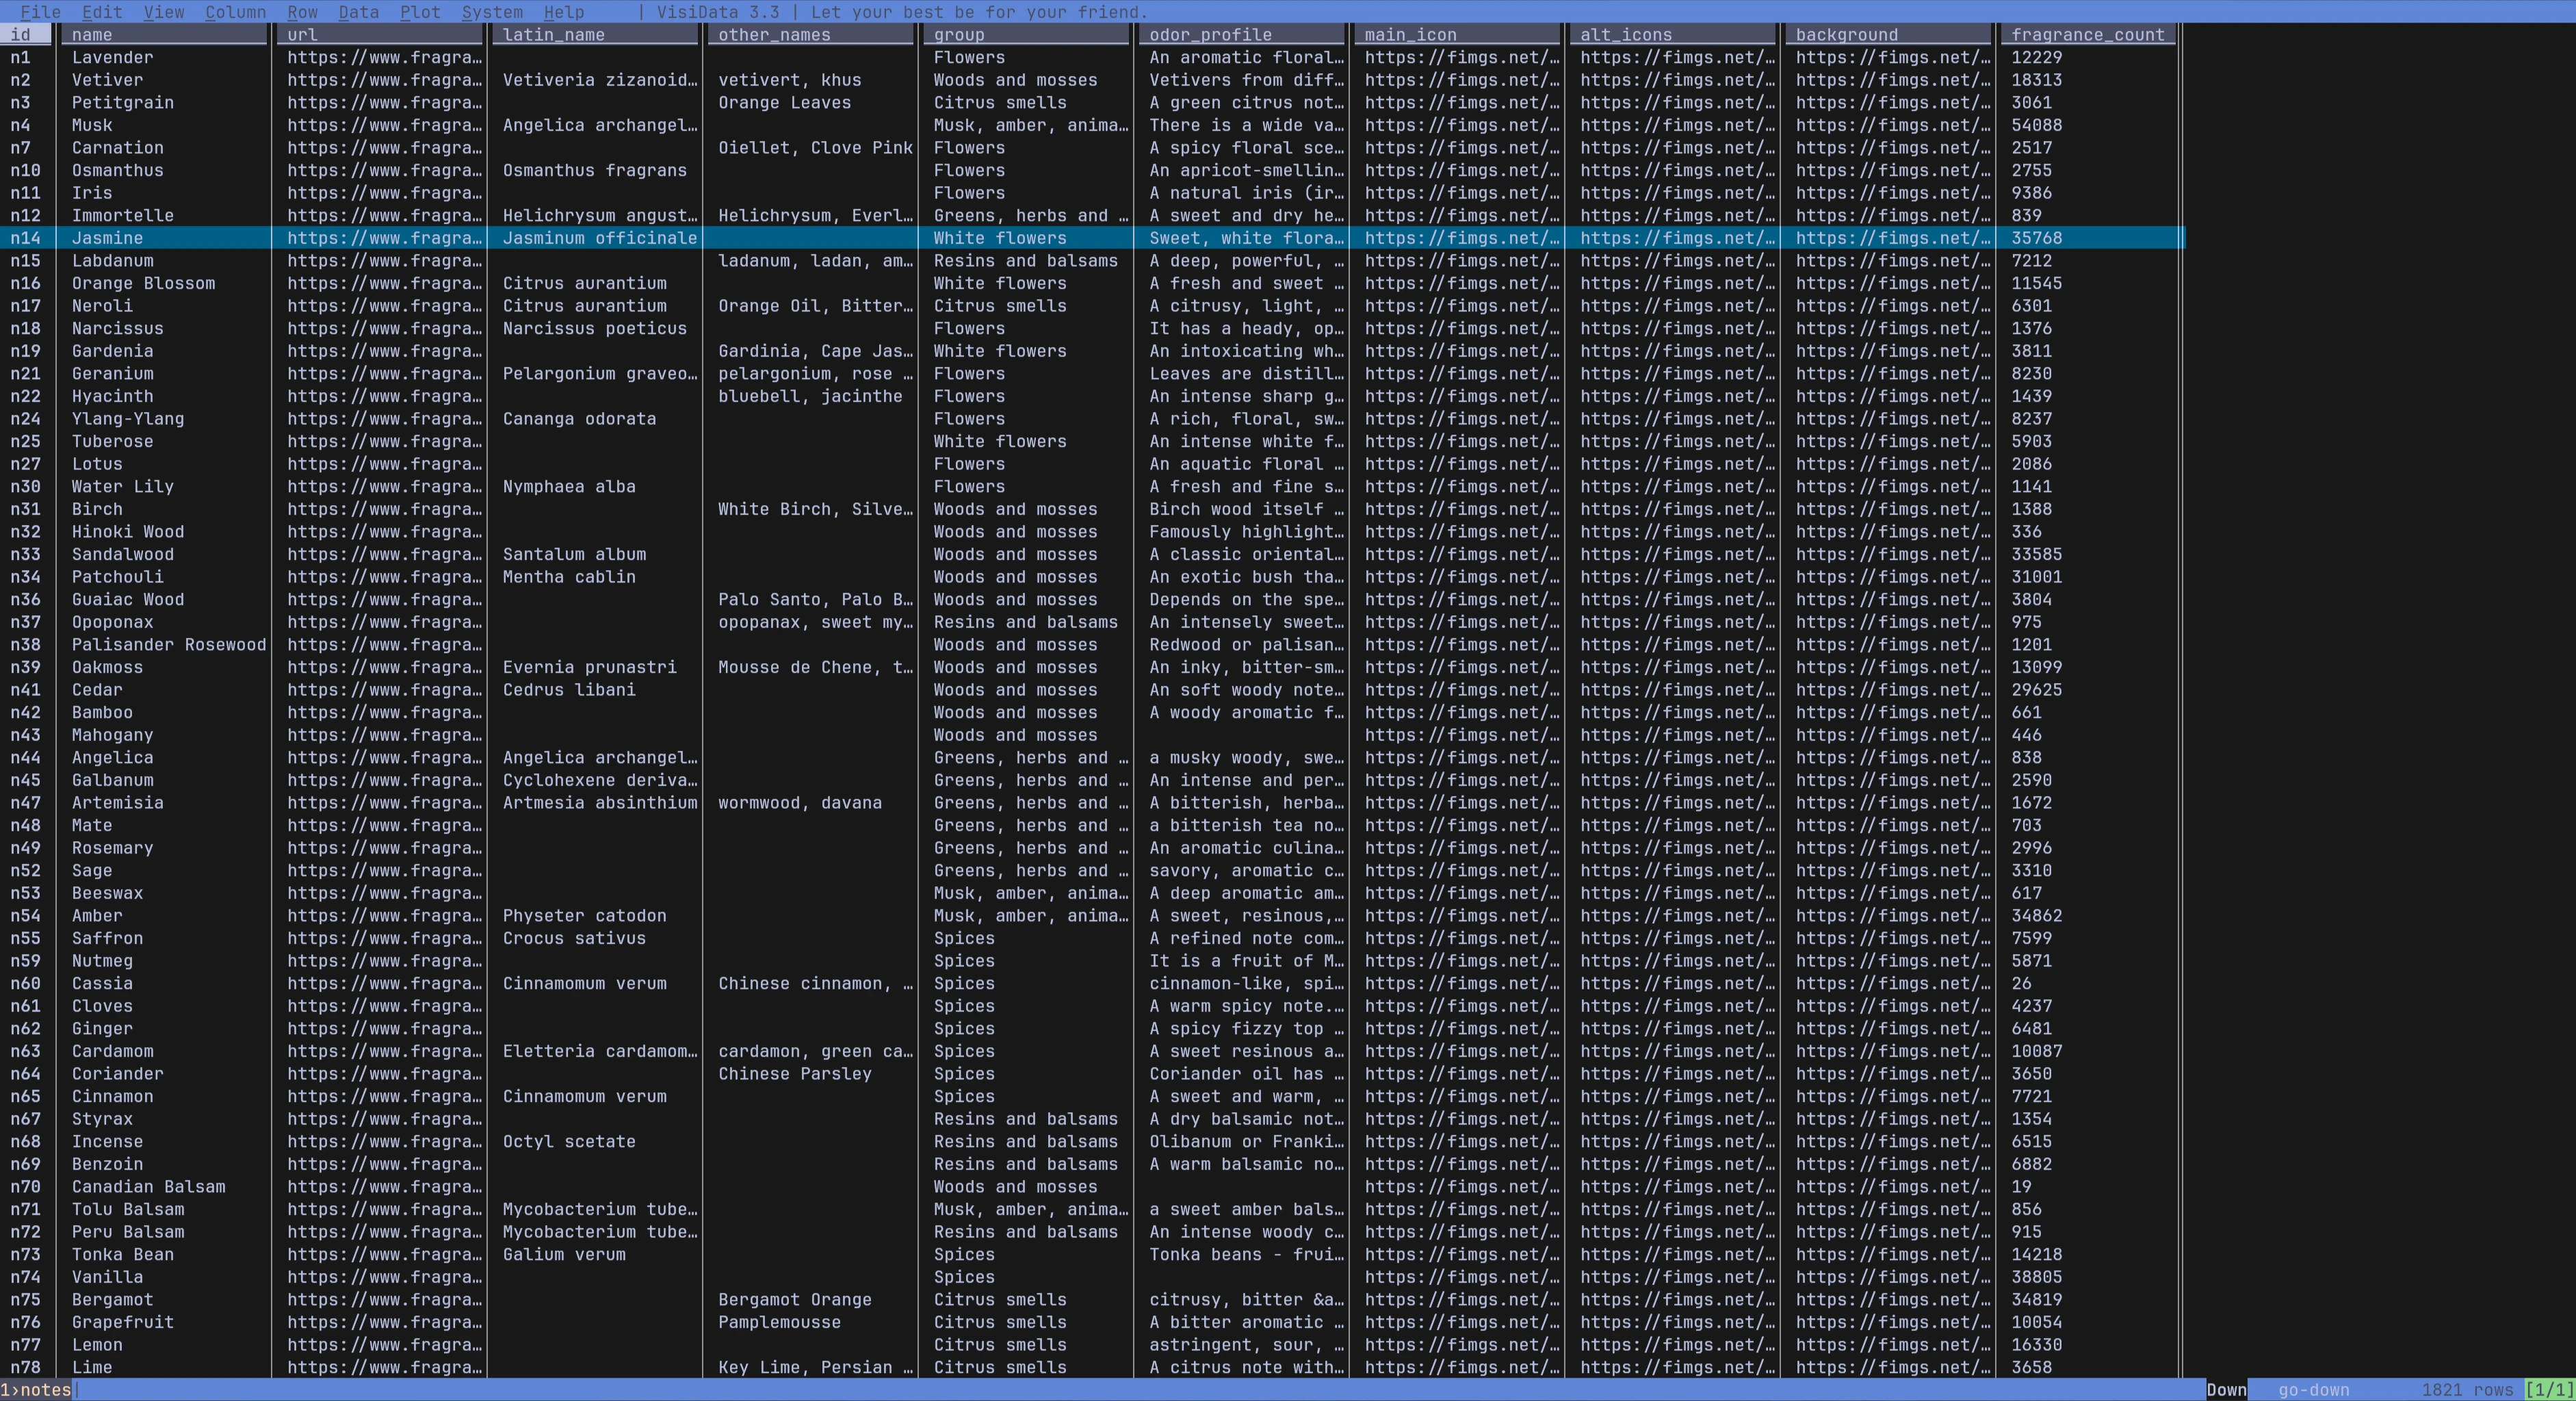
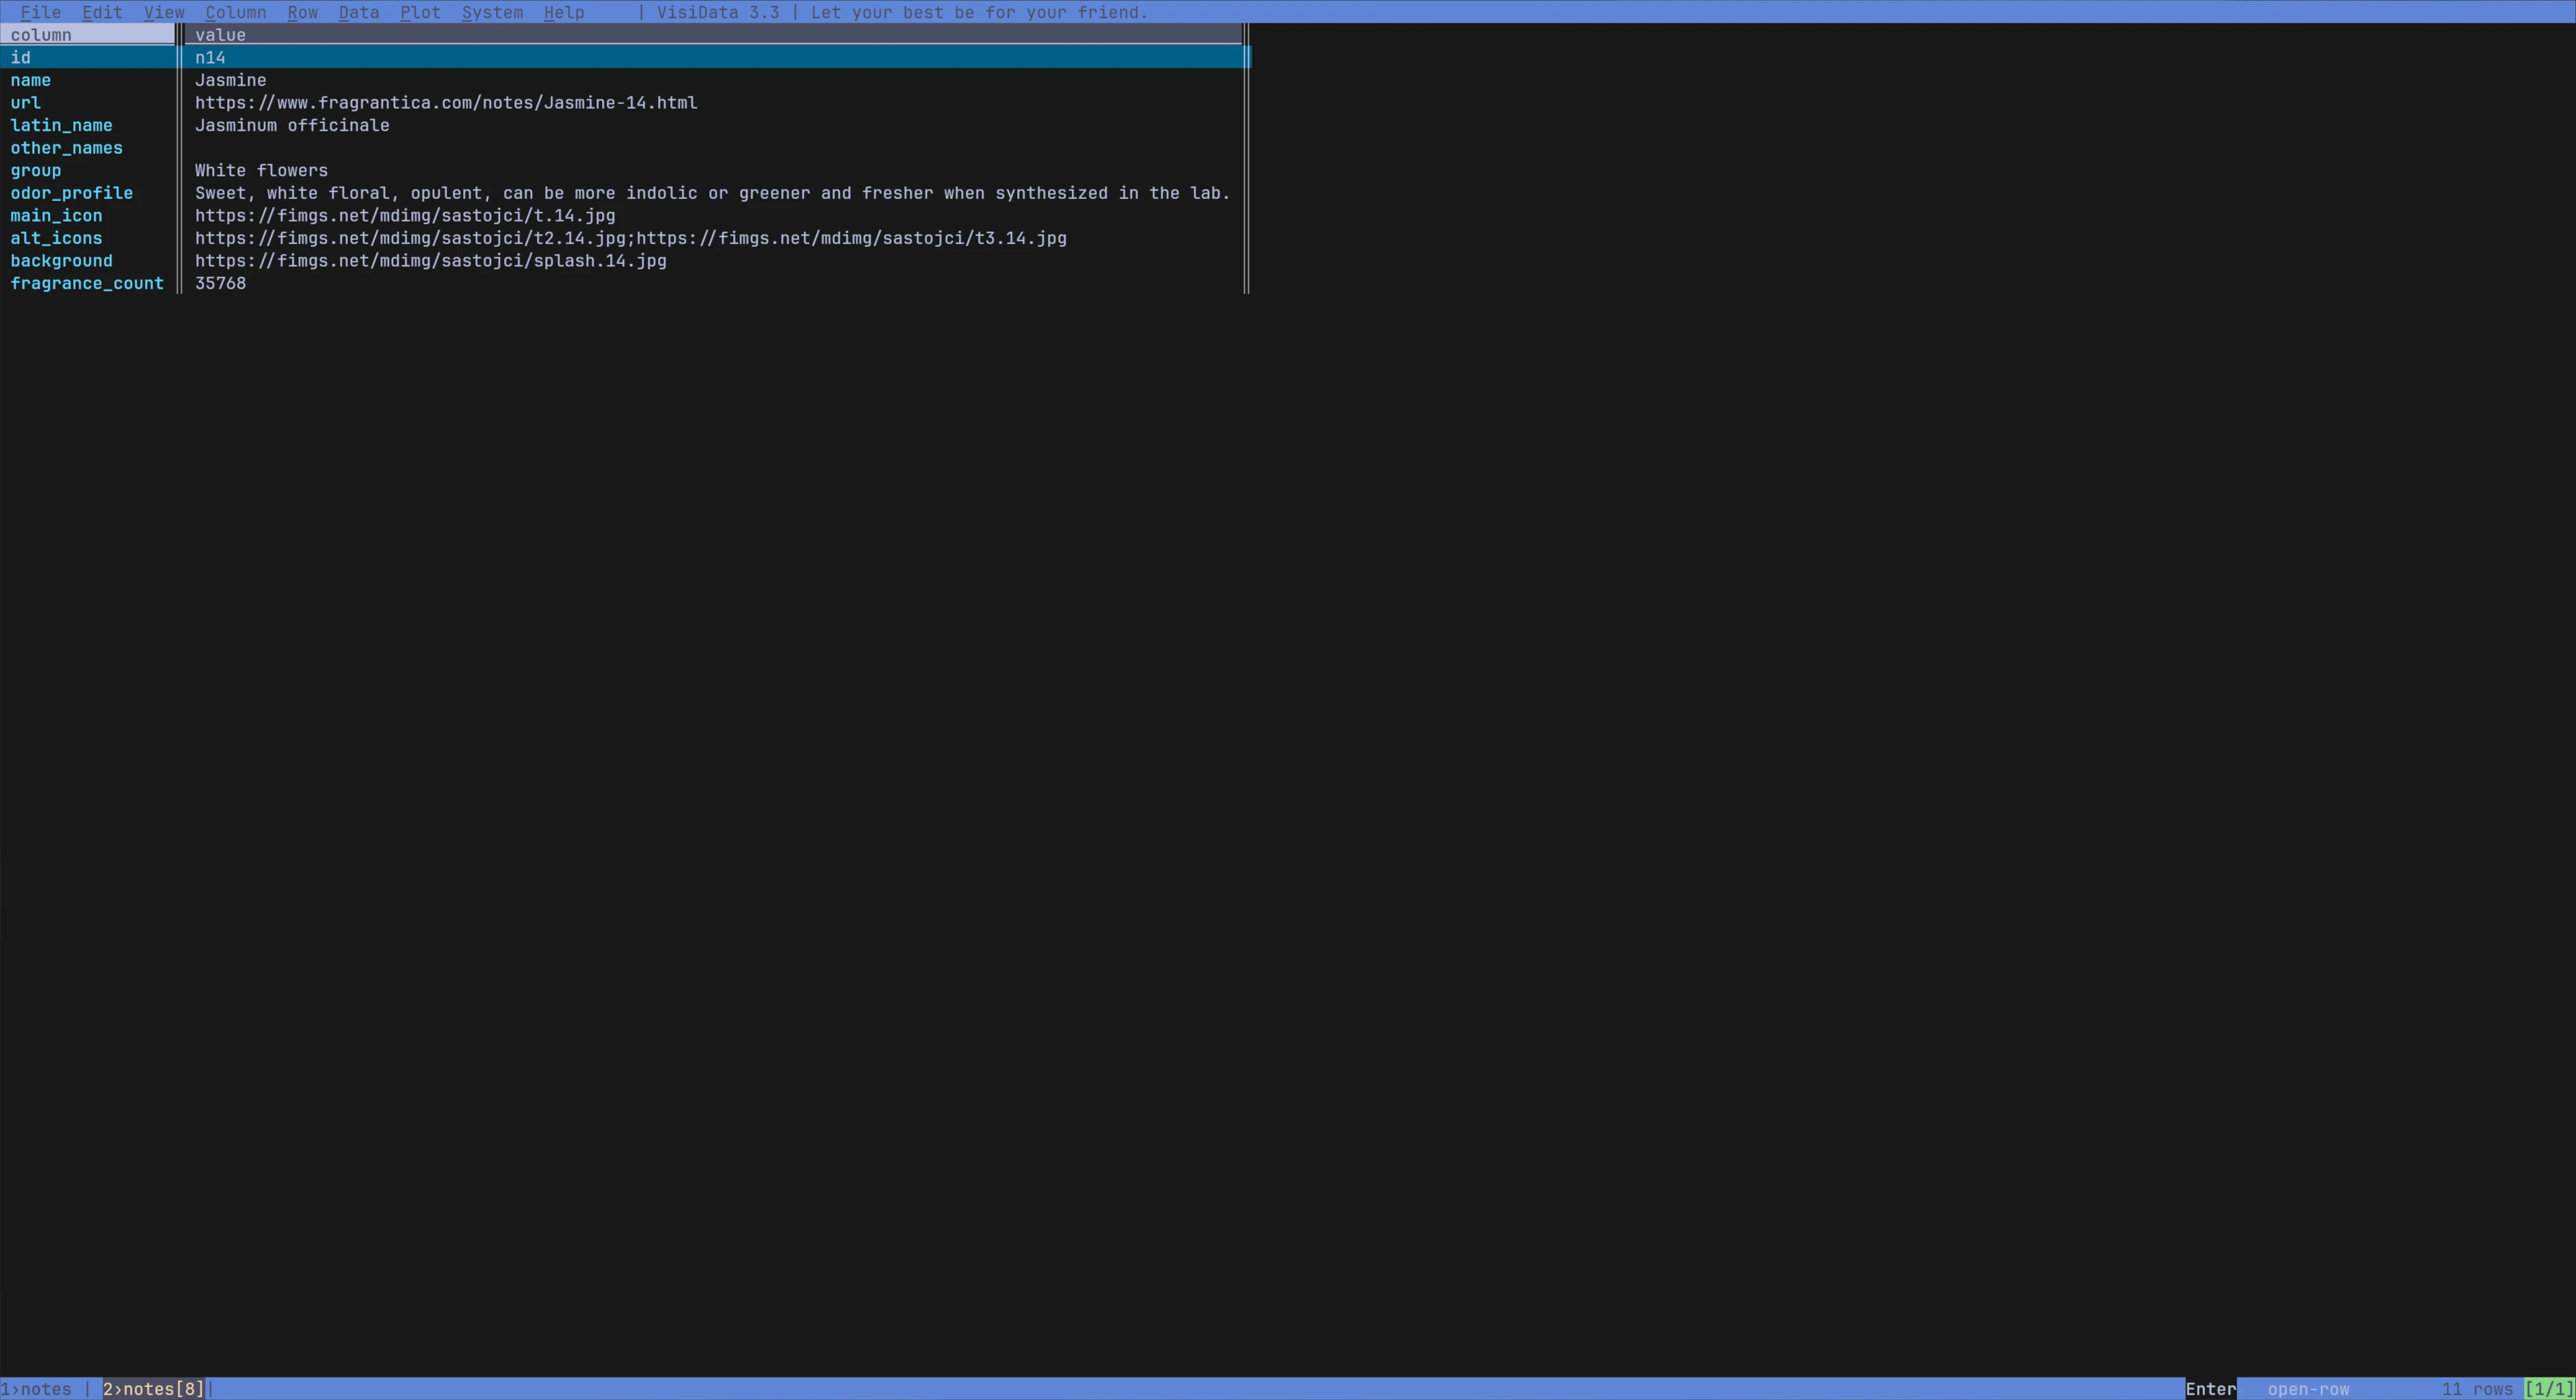
Quick Start
Python
import pandas as pd

# Load all files
fragrances = pd.read_csv('fragrances.csv', sep='|', encoding='utf-8')
brands = pd.read_csv('brands.csv', sep='|', encoding='utf-8')
notes = pd.read_csv('notes.csv', sep='|', encoding='utf-8')
translations = pd.read_csv('translations.csv', sep='|', encoding='utf-8')

# Join fragrances with brands
fragrances['brand_id'] = fragrances['brand'].str.split(';').str[1]
df = fragrances.merge(brands, left_on='brand_id', right_on='id', suffixes=('', '_brand'))

# Translate gender to any language
trans = translations.set_index('id')
df['gender_ru'] = df['gender'].map(lambda x: trans.loc[x, 'ru'] if x in trans.index else x)

# Brand country in Japanese
print(df[['name', 'name_brand', 'country_ja', 'gender_ru']].head())
JavaScript
const { parse } = require('csv-parse/sync');
const fs = require('fs');

// Load files
const fragrances = parse(fs.readFileSync('fragrances.csv', 'utf-8'), { columns: true, delimiter: '|' });
const brands = parse(fs.readFileSync('brands.csv', 'utf-8'), { columns: true, delimiter: '|' });
const translations = parse(fs.readFileSync('translations.csv', 'utf-8'), { columns: true, delimiter: '|' });

// Build lookup maps
const brandsMap = new Map(brands.map(b => [b.id, b]));
const transMap = new Map(translations.map(t => [t.id, t]));

// Get fragrance with translated fields
const frag = fragrances[0];
const [brandName, brandId] = frag.brand.split(';');
const brand = brandsMap.get(brandId);
const genderRu = transMap.get(frag.gender)?.ru || frag.gender;

console.log(`${frag.name} by ${brandName} (${brand?.country_ru}), ${genderRu}`);
SQL (PostgreSQL)
-- Import
COPY fragrances FROM 'fragrances.csv' DELIMITER '|' CSV HEADER ENCODING 'UTF8';
COPY brands FROM 'brands.csv' DELIMITER '|' CSV HEADER ENCODING 'UTF8';
COPY translations FROM 'translations.csv' DELIMITER '|' CSV HEADER ENCODING 'UTF8';

-- Join and translate gender to Russian
SELECT f.name, b.name AS brand, b.country_ru, t.ru AS gender_ru
FROM fragrances f
JOIN brands b ON SPLIT_PART(f.brand, ';', 2) = b.id
JOIN translations t ON f.gender = t.id;
See DATA_DICTIONARY.md for complete field documentation.
Companion Parquet Datasets — User Reviews, News, and Community Comments
FragDB ships with three Apache Parquet datasets containing 5.3 million rows of user-generated content and editorial coverage — the largest publicly-organized corpus of fragrance reviews and perfumery journalism. Use them for NLP, sentiment analysis, recommendation systems, market research, or training language models on fragrance-specific text.
comments.parquet — 5.0 Million User Reviews in 23 Languages
The world's largest collection of structured fragrance reviews. Every entry includes the perfume ID (joinable with fragrances.csv), author username, posting date, full review text, avatar URL, and language code.
- 5,026,322 user reviews covering every major perfume in the database
- 23 languages — English (1.91M reviews), Russian, Portuguese, Spanish, Korean, Turkish, Japanese, Polish, Italian, Hungarian, Serbian, Swedish, German, Hebrew, Ukrainian, French, Arabic, Greek, Czech, Chinese, Romanian, Mongolian, Dutch
- Coverage: 68.3% of all fragrances in the database have at least one review (98,276 of 143,855 PIDs)
- Deterministic global primary key — stable comment IDs survive re-scrapes
- Zero duplicate rows; every
pidjoinsfragrances.csvexcept 62 reviews (0.001%) on 12 perfumes no longer in the catalogue - Independent UGC per language — each language is genuine localized content, not machine translation
- 8 fields:
pid,lang,comment_id,author,date,text,avatar_url,gradient_class - PyArrow large_string format — combined corpus exceeds 32-bit string offset limit
Use cases: sentiment analysis · review classification · recommendation systems · perfume similarity from text · language detection benchmark · multilingual NLP training corpus · fragrance market research · author network analysis · trend detection by language
news.parquet — 25,981 Editorial Articles (2008–2026)
Two decades of professional fragrance journalism. Every article includes title, author, full text (plain + HTML), category, related perfumes/brands/perfumers, publication date, and main image. Foreign keys to fragrances, brands, and perfumers make this a powerful resource for content-based recommendation and knowledge graph construction.
- 25,981 editorial articles from 2008 to 2026 — the complete public archive
- 30+ categories — top: New Fragrances (33.9%), Fragrance Reviews (24.1%), Niche Perfumery (10.1%), Designer Brands, Interviews, History, Industry News, Niche Houses, and more
- Bilingual storage —
text(plain) for NLP / search,text_html(preserved markup) for rich display - Linked entities —
related_pids[],related_brands[],related_perfumers[]as JSON arrays - 127,609 PID references — all but 177 (0.14%) resolve; those point to perfumes no longer in the catalogue
- Modern + archived — 59.5% archived legacy articles, 40.5% modern articles, all dated except 27 of the 30 newest (NID 26,464 and above)
- 16 fields:
nid,title,category,author,url,is_archived,date_unix,description,text,text_html,main_image,article_images,related_pids,related_brands,related_perfumers,comments_count - List fields stored as JSON-encoded strings — never null (empty =
"[]")
Use cases: content recommendation · article search engine · perfume knowledge graph · trend analysis · author influence study · category classification · entity linking · timeline analysis · industry research · niche perfumery research · fragrance journalism corpus
news_comments.parquet — 280,874 Threaded Community Comments
Community discussions attached to editorial articles, with threading support for replies. Joinable with news.parquet via nid.
- 280,874 threaded comments across 23,215 articles (89.4% of news articles have at least one comment)
- 5.6% reply rate — threaded conversations with reply detection (
is_replyflag) - 100% populated timestamps —
date_unixparsed for every comment - 9 fields:
nid,comment_id,is_reply,author,date,date_unix,text,avatar_url,gradient - Zero foreign key orphans against
news.parquet.nid
Use cases: community engagement analysis · threaded discussion mining · reply network construction · comment sentiment · author activity profiles · temporal analysis of community responses
Tier Availability
The parquet datasets ship with all paid tiers except the $200 Core:
| Tier | CSV Core | Parquet Datasets |
|---|---|---|
| $200 One-Time Core | ✅ | ❌ |
| $400 One-Time Full Database | ✅ | ✅ |
| Annual Subscription | ✅ | ✅ (always latest) |
| Lifetime Access | ✅ | ✅ (always latest) |
See https://fragdb.net/#pricing for complete tier comparison.
Free Parquet Samples Included
This repository includes free parquet preview samples in samples/:
comments_sample.parquet— 25 user reviews (8 fields)news_sample.parquet— 20 editorial articles (16 fields)news_comments_sample.parquet— 20 threaded news comments (9 fields)SPEC.md— full field-by-field schema documentation (Apache Parquet)
Quick Start — Reading Parquet Datasets
import pyarrow.parquet as pq
import pandas as pd

# Read user reviews
reviews = pq.read_table('comments.parquet').to_pandas()
print(reviews.head())
print(f"Total reviews: {len(reviews):,}")
print(f"Languages: {reviews['lang'].nunique()}")

# Join with CSV fragrance metadata
fragrances = pd.read_csv('fragrances.csv', sep='|')
reviews_with_frag = reviews.merge(fragrances, on='pid', how='left')

# Read news articles
import json
news = pq.read_table('news.parquet').to_pandas()
# Parse JSON-encoded list fields
news['related_pids_list'] = news['related_pids'].apply(json.loads)
news['related_brands_list'] = news['related_brands'].apply(json.loads)
print(news[['nid', 'title', 'category', 'date_unix']].head())

# Read news comments and join with articles
news_comments = pq.read_table('news_comments.parquet').to_pandas()
discussion = news_comments.merge(news[['nid', 'title']], on='nid')
print(discussion[['nid', 'title', 'author', 'text']].head())
Full schema, field types, and audit statistics are documented in SPEC.md.
Data API — per-record access
The whole catalogue, one record at a time. A metered HTTP API over the same database we sell as files. You pay per record returned, at the level of detail you ask for. No subscription and no seats: top up a balance, fetch what your application needs, cache it as long as you like.
fragdb.net/api → · OpenAPI spec · Sign up · FAQ · Terms
Endpoints
GET  /api/v1/fragrances/{id}        one record
GET  /api/v1/brands/{id}            one brand
GET  /api/v1/notes/{id}             one note
GET  /api/v1/perfumers/{id}         one perfumer
POST /api/v1/{collection}/batch     up to 100 ids in one call
GET  /api/v1/index                  the full index, gzipped JSONL
GET  /api/v1/release                current release label and date — free
GET  /api/v1/account                balance, limits, usage — free
Detail level is chosen with ?level=list|basic|full.
There are no list endpoints. /api/v1/fragrances?limit=50 answers 404, by design. You
enumerate the catalogue with the index file — id, name, brand, year and change status — search
it on your side, and fetch whole records only for the hits you need. The index costs no units
and needs a paid key: five downloads a day, and an unchanged index answers 304.
Detail levels
| Level | Units | Per record | What comes back |
|---|---|---|---|
list |
1 | $0.0025 | id, brand, name, year, gender, rating with vote count, and a thumbnail |
basic |
2 | $0.005 | plus the photo, the collection, review count, main accords with their strength and the credited perfumers |
full |
4 | $0.01 | the note pyramid as published, seven vote blocks, description, pros and cons, related fragrances, and every label translated inline |
1 unit = $0.0025. Top-ups are multiples of $50, from $100 up to $5,000 — $100 buys 40,000 units. Paid units do not expire while the account is open. Minimum spend is $100 (40,000 units) per 180 days, $16.67 a month, counted from the first top-up. Payment in BTC, ETH, TRX, XMR or USDT.
Try it before you pay
Sign up and a free test key appears straight away. It costs nothing, charges nothing and serves 5 sample records at every level — enough to write your parser against the real shape of a response before you pay for anything.
curl -H "Authorization: Bearer <your test key>" \
  "https://fragdb.net/api/v1/fragrances/f_9kwkhn9yqx?level=full"
That id is one of the five public samples, so the call works on a test key.
Already bought a database file? You get 500 units for 30 days to try the API. (The 500 units come with a file purchase, not with signing up.)
Limits
10 requests per second and 300 per minute on a key · 20 per second on an account · 100 ids per batch call · 50,000 charged records per account per UTC day · 5 index downloads per day · 5 keys per account. Call the API from your server, never from a browser.
How it sits next to the files
The API serves the same catalogue that is sold as files, refreshed about three times a month.
Every response carries the release label and its date, and GET /api/v1/release tells you
which release you are on.
Ids are permanent: a record withdrawn at its source stays available with its last known content and a status flag.
Reviews, news articles and community comments are not in the API — those stay in the downloadable files described in this README.
What's New in v5.20
- Data update: 142,676 → 143,855 fragrances (+1,179 added, none removed), 8,501 brands (+68), 3,198 perfumers (+27), 2,626 notes (+8)
- An incremental release: the source was crawled for new pages on 2026-11-01 and the 1,179 new fragrances were added; the existing 142,676 fragrance records are carried over unchanged from v5.19
- Reviews, news and news comments refreshed: reviews 5,024,093 → 5,026,322 (+2,229, all English; the other 22 languages keep their v5.19 row counts), editorial articles 25,875 → 25,981 (+106), news comments 279,843 → 280,874 (+1,031)
- Photos: 633,541 → 635,680
- Perfumer photos: 52 existing perfumers gained a
photo_url— portraits are now read from the fragrance pages on every crawl, so a photo added at the source after the perfumer first appeared is picked up. 1,418 of 3,198 perfumers have a photo; no other column of an existing perfumer changed - Notes: 2 of the 8 new rows are new names the source now shows on existing note pages —
n2707Schisandra (the page ofn1290Chinese Magnolia) andn2702Cocoa Shell (the page ofn1553cocoa shell); the old ids keep their names. Three existing translations were updated at the source (Balsamic Notes and Floral Notes in Turkish, Timur in Italian) - Review coverage is 68.3% (98,276 of 143,855 perfumes): most of the fragrances added in this release are new launches with no reviews yet
- No brand renames or folded brand pages in this release; no perfume changed brand. Every id carried over from v5.19 keeps its record
- News: 27 of the 30 newest articles (NID 26,464 and above) have
date_unix = 0— the source adds the date to the article page a few days after publication, and the next news refresh picks it up. Two new articles (NID 26,404 and 26,462) did not respond during collection and will be added with the next news refresh - Sample files unchanged: the schema did not move between v5.19 and v5.20, so the 10-record previews in
samples/are byte-identical
What's New in v5.19
- Data update: 141,541 → 142,676 fragrances (+1,135 added, none removed), 8,433 brands (+49), 3,171 perfumers (+17), 2,618 notes (+3)
- An incremental release: the source was crawled for new pages on 2026-10-19 and the 1,135 new fragrances were added; the existing 141,541 records are carried over unchanged from the 2026-10-08 snapshot (v5.18)
- Reviews, news and news comments refreshed: reviews 5,022,398 → 5,024,093 (+1,695, all English; the other 22 languages keep their v5.18 row counts), editorial articles 25,780 → 25,875 (+95), news comments 278,905 → 279,843 (+938)
- Photos: 631,816 → 633,541
- Review coverage is 68.9% (98,240 of 142,676 perfumes): most of the fragrances added in this release are new launches with no reviews yet
- No brand renames or folded brand pages in this release; no perfume changed brand. Every id carried over from v5.18 keeps its record
- The 23 articles that v5.18 shipped without a publication date are now dated. In v5.19, 19 of the 23 newest articles (NID 26,363 and above) have
date_unix = 0 - Sample files unchanged: the schema did not move between v5.18 and v5.19, so the 10-record previews in
samples/are byte-identical
What's New in v5.18
- Data update: 140,946 → 141,541 fragrances (+595: 601 added, 6 removed because their pages were deleted at the source), 8,384 brands (+25), 3,154 perfumers (+10), 2,615 notes (+5)
- Reviews, news and news comments refreshed: reviews 4,988,692 → 5,022,398 (+33,706, all English; the other 22 languages keep their v5.17 row counts), editorial articles 25,709 → 25,780 (+71), news comments 277,446 → 278,905 (+1,459)
- Photos: 625,052 → 631,816
- Brand ids now survive renames and merges at the source. A renamed brand keeps its id and takes the new name —
b7118Saleel → Saleel Parfums,b4760Aromatic Families → Aromatic. When the source folds one brand page into another, both ids stay and now carry the same name and page URL: five such pairs in this release, the largestb532(417 perfumes) withb8330(15), Novaya Zarya – The New Dawn. Joins onbrand_idare unaffected; group byid, not by name, to keep each pair apart. The full list is in CHANGELOG.md - Two perfumes moved to another brand because the source moved them: PID 115180 (Maison Incens → Rocco d'Orazio) and PID 141384 (Opula Perfumes → Opal Perfumes)
- The 84 articles that v5.17 shipped without a publication date are now dated. In v5.18, 23 of the 29 newest articles (NID 26,262 and above) have
date_unix = 0 - Sample files unchanged: the schema did not move between v5.17 and v5.18, so the 10-record previews in
samples/are byte-identical
What's New in v5.17
- Data update: 140,230 → 140,946 fragrances (+716), 8,359 brands (+43), 3,144 perfumers (+18), 2,610 notes (+4)
- Reviews, news and news comments refreshed again: reviews 4,986,774 → 4,988,692 (+1,918), editorial articles 25,619 → 25,709 (+90), news comments 276,483 → 277,446 (+963)
- Photos: 623,790 → 625,052
- Figures on this page are measured against the v5.17 files. The technical specification (
SPEC.md) had kept parts of its May 2026 snapshot — the language table, perfume coverage, the date-coverage section and the category table; all of it is now restated from the v5.17 files - Correction: the specification said every non-archived article carries a publication date. In v5.17, 84 of the 250 newest articles (NID 25,970 and above) have
date_unix = 0; the page now says so - Sample files unchanged: the schema did not move between v5.16 and v5.17, so the 10-record previews in
samples/are byte-identical
What's New in v5.16
- Data update: 139,501 → 140,230 fragrances (+729), 8,316 brands (+44), 3,126 perfumers (+10), 2,606 notes (+10)
- Reviews, news and news comments are refreshed for the first time since June. Reviews 4,643,851 → 4,986,774 (+342,923), editorial articles 24,440 → 25,619 (+1,179), news comments 263,798 → 276,483 (+12,685). The three parquet files in the Full tier are new, not carried over
- Photos: 622,513 → 623,790
- New: a Data API — per-record HTTP access to the same catalogue, priced per record. See the section above
- Figures on this page are measured against the v5.16 files: review coverage, the language split, PID reference resolution, the archived/modern article split and the reply rate all moved with the new parquet
- Sample files unchanged: the schema did not move between v5.15 and v5.16, so the 10-record previews in
samples/are byte-identical
What's New in v5.15
- Data update: 137,789 → 139,501 fragrances (+1,712), 8,272 brands (+25), 3,116 perfumers (+6), 2,596 notes (+4: 7 new, 3 retired)
- Full source recrawl (10 Sep 2026) — every field class re-read, not only the new tail
- Three note IDs retired — the source merged case duplicates:
n473→n2661(Heather),n653→n2646(Icing Pink),n813→n2660(Hazelnut Cocoa Spread). No fragrance references the retired IDs - Photos: 615,066 → 622,513
- Figures on this page restated from the release files. The records badge and the full-database totals had stayed at v5.10, and the notes row showed 2,588 while v5.14 shipped 2,592. The notes figure is now the row count of
notes.csv— the number fragdb.net shows. Review coverage and foreign-key figures are measured against this catalogue - Reviews, news and news comments: the same parquet files as v5.14
- Sample files unchanged: the schema did not move between v5.14 and v5.15, so the 10-record previews in
samples/are byte-identical
What's New in v5.14
- Data update: 137,147 → 137,789 fragrances (+642), 8,247 brands (+37), 3,110 perfumers (+8), 2,586 unique note names (unchanged — the notes reference only moves on a full crawl)
- Photos: 613,933 → 615,066
- Sample files unchanged: the schema did not move between v5.13 and v5.14, so the 10-record previews in
samples/are byte-identical. They show structure, not freshness.
What's New in v5.13
- Data update: 136,682 → 137,147 fragrances (+465), 8,210 brands (+35), 3,102 perfumers (+12), 2,588 notes (+2)
- Clean incremental delta (19 Aug 2026) — no perfume changed its canonical URL and none disappeared; the previous full recrawl had 59 such moves, so this cycle is pure growth
- Field coverage flat across all 30 columns (max movement 0.22 pp) — new entries arrive slightly less complete than the catalog average, which is normal for fresh pages, not a regression
- New note
Kiwanoshipped with all 22 translations on its first cycle, instead of waiting for the next full recrawl - Free sample refreshed — the 10-record CSV samples in
samples/rebuilt from v5.13 data
What's New in v5.12
- Data update: 135,308 → 136,682 fragrances (+1,374), 8,175 brands (+82), 3,090 perfumers (+33), 2,586 notes (+13)
- Covers two upstream releases (v5.11 and v5.12); the previous public snapshot was v5.10
- Full source recrawl (9 Aug 2026) — every field class re-read, not just the new tail; 784 records that a resume-scan bug had frozen since May are current again
- Notes multilingual 100% — every note translated across all 22 languages, verified with a strict per-language check
- Free sample refreshed — the 10-record CSV samples in
samples/rebuilt from v5.12 data
What's New in v5.9
- Data update: 134,022 → 134,577 fragrances (+555), 8,036 brands, 3,046 perfumers, 2,567 notes
- 154 brand names canonicalized — parser restored the
Fragrance(s)suffix stripped by an old bug ("Demeter" → "Demeter Fragrance", "Lacoste" → "Lacoste Fragrances", …); brand IDs unchanged - URL hygiene: note-pyramid anchors normalized to one domain (300K
beta.→www.), photo cache-busters stripped - Free sample refreshed — the 10-record CSV samples in
samples/rebuilt from v5.9 data
Schema (stable since v5.4)
- Perfumer transliterations in 9 languages (ru, uk, ja, zh, ko, ar, he, el, mn);
perfumers.csv42 columns
From v5.3 (unchanged)
- 23 languages — all labels, note names, accords, countries, statuses translated
- translations.csv — vocabulary file for gender values and voting labels
- Compact notes pyramid —
note_id,opacity,weight(name/icon via notes.csv JOIN) - Each note name variant (Rose, Damask Rose, Turkish Rose) has its own ID
- Gender & voting fields use translation IDs instead of English text
See DATA_DICTIONARY.md for complete field documentation with parsing examples.
Sample Data
The free sample includes 10 records per file across all six CSV files, plus parquet samples and SPEC.md:
CSV samples
| File | Records | Description |
|---|---|---|
| fragrances.csv | 10 | Iconic fragrances (30 fields) |
| brands.csv | 10 | Brand profiles (54 fields, 22 lang) |
| perfumers.csv | 10 | Perfumer profiles (42 fields, 22 lang + 9 translit) |
| notes.csv | 10 | Fragrance notes (55 fields, 22 lang) |
| accords.csv | 10 | Accords with colors (27 fields, 22 lang) |
| translations.csv | 34 | Gender & voting vocabulary (full, 25 fields) |
Parquet samples (Full tier preview)
| File | Records | Description |
|---|---|---|
| comments_sample.parquet | 25 | User reviews preview (8 fields) |
| news_sample.parquet | 20 | Editorial articles preview (16 fields) |
| news_comments_sample.parquet | 20 | News comments preview (9 fields) |
| SPEC.md | — | Parquet schema documentation |
Preview: SAMPLE_PREVIEW.md
Documentation
- DATA_DICTIONARY.md — Complete field documentation with parsing examples
- CHANGELOG.md — Version history
Use Cases
CSV Core (all tiers)
- E-commerce — Enrich product listings with detailed fragrance data, notes, accords
- Mobile Apps — Build fragrance collection managers, scent discovery apps, perfume catalog apps
- Data Analysis — Analyze fragrance industry trends by brand, country, perfumer, year
- Recommendations — Content-based or collaborative filtering systems using accord/note vectors
- Content Creation — Power blogs, videos, fragrance reviews with accurate data
- Multilingual UIs — Localized perfume catalogs in 23 languages out of the box
- Knowledge Graphs — Brand → Perfumer → Fragrance → Notes → Accords graph construction
- Market Research — Country-of-origin analysis, parent company portfolios, perfumer productivity stats
Parquet Datasets ($400+ tiers)
- NLP & Sentiment Analysis — Train models on 5.0M multilingual fragrance reviews
- Recommender Systems — Hybrid models combining CSV structure with review text similarity
- Language Models — Domain-specific corpus for fragrance/perfumery LLM fine-tuning
- Review Classification — Identify positive/negative reviews, fake review detection
- Trend Detection — News article timeline analysis, emerging fragrance trends
- Author Networks — Identify influential reviewers, perfumery journalists, community leaders
- Content-Based Discovery — "Articles about this perfume" — JOIN news.related_pids with fragrances.pid
- Community Analytics — Reply networks, engagement metrics on editorial content
- Cross-Language Studies — Compare review sentiment across 23 languages for the same fragrance
- Search Engines — Full-text search across reviews, articles, and structured metadata
- Entity Resolution — Match journalist's
related_brands[]mentions withbrands.csvIDs - Knowledge Extraction — Mine 26K editorial articles for perfume facts, launch dates, perfumer interviews
Full Database
The free sample contains 10 records per file. The full FragDB database includes:
| Feature | Free Sample | Full Database |
|---|---|---|
| Fragrances | 10 | 143,855 |
| Brands | 10 | 8,501 |
| Perfumers | 10 | 3,198 |
| Notes | 10 | 2,626 |
| Accords | 10 | 92 |
| Translations | 34 (full) | 34 |
| Languages | 23 | 23 |
| Total Records | ~84 | 158,306 |
| Updates | None | Regular |
| Commercial Use | Yes (sample) | Yes (licensed) |
Contributing
Contributions are welcome! See CONTRIBUTING.md for guidelines.
- Bug fixes for code examples
- New language examples
- Documentation improvements
- Use case additions
License
- Sample Data & Code: MIT License
- Full Database: Commercial license (see fragdb.net)
Links
- Website: fragdb.net
- Data API: fragdb.net/api
- Hugging Face: huggingface.co/datasets/FragDBnet/fragrance-database
- Documentation: DATA_DICTIONARY.md
- Issues: GitHub Issues
Built with data passion by the FragDB team.
関連プロジェクトを探す
Asabeneh/30-Days-Of-Python
30 Days of Python プログラミングチャレンジは、Python プログラミング言語を 30 日で学ぶためのステップバイステップのガイドです。このチャレンジは 100 日以上かかることもあります。自分のペースで進めてください。こちらの動画も役立つかもしれません: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,486 スターgrafana/grafana
オープンで組み合わせ可能なオブザーバビリティおよびデータ可視化プラットフォームです。Prometheus、Loki、Elasticsearch、InfluxDB、Postgres など、複数のソースからメトリクス、ログ、トレースを可視化できます。
77,790 スターredis/redis
リアルタイムのデータ駆動型アプリケーションを構築する開発者にとって、Redis は最も選ばれ、最速で、機能が最も豊富なキャッシュ、データ構造サーバー、ドキュメントおよびベクトルクエリエンジンです。
77,332 スターapache/superset
Apache Superset は、データ可視化とデータ探索のためのプラットフォームです。
75,455 スター