
data_sci_guide
Chris-Engelhardt
540étoiles
A community-sourced data science repo.
Comparez bases de données, analyses, SQL et projets d’ingénierie des données.
Chris-Engelhardt
A community-sourced data science repo.

chrisdiana
A clean, responsive storefront boilerplate with no database or backend

chrisgreg
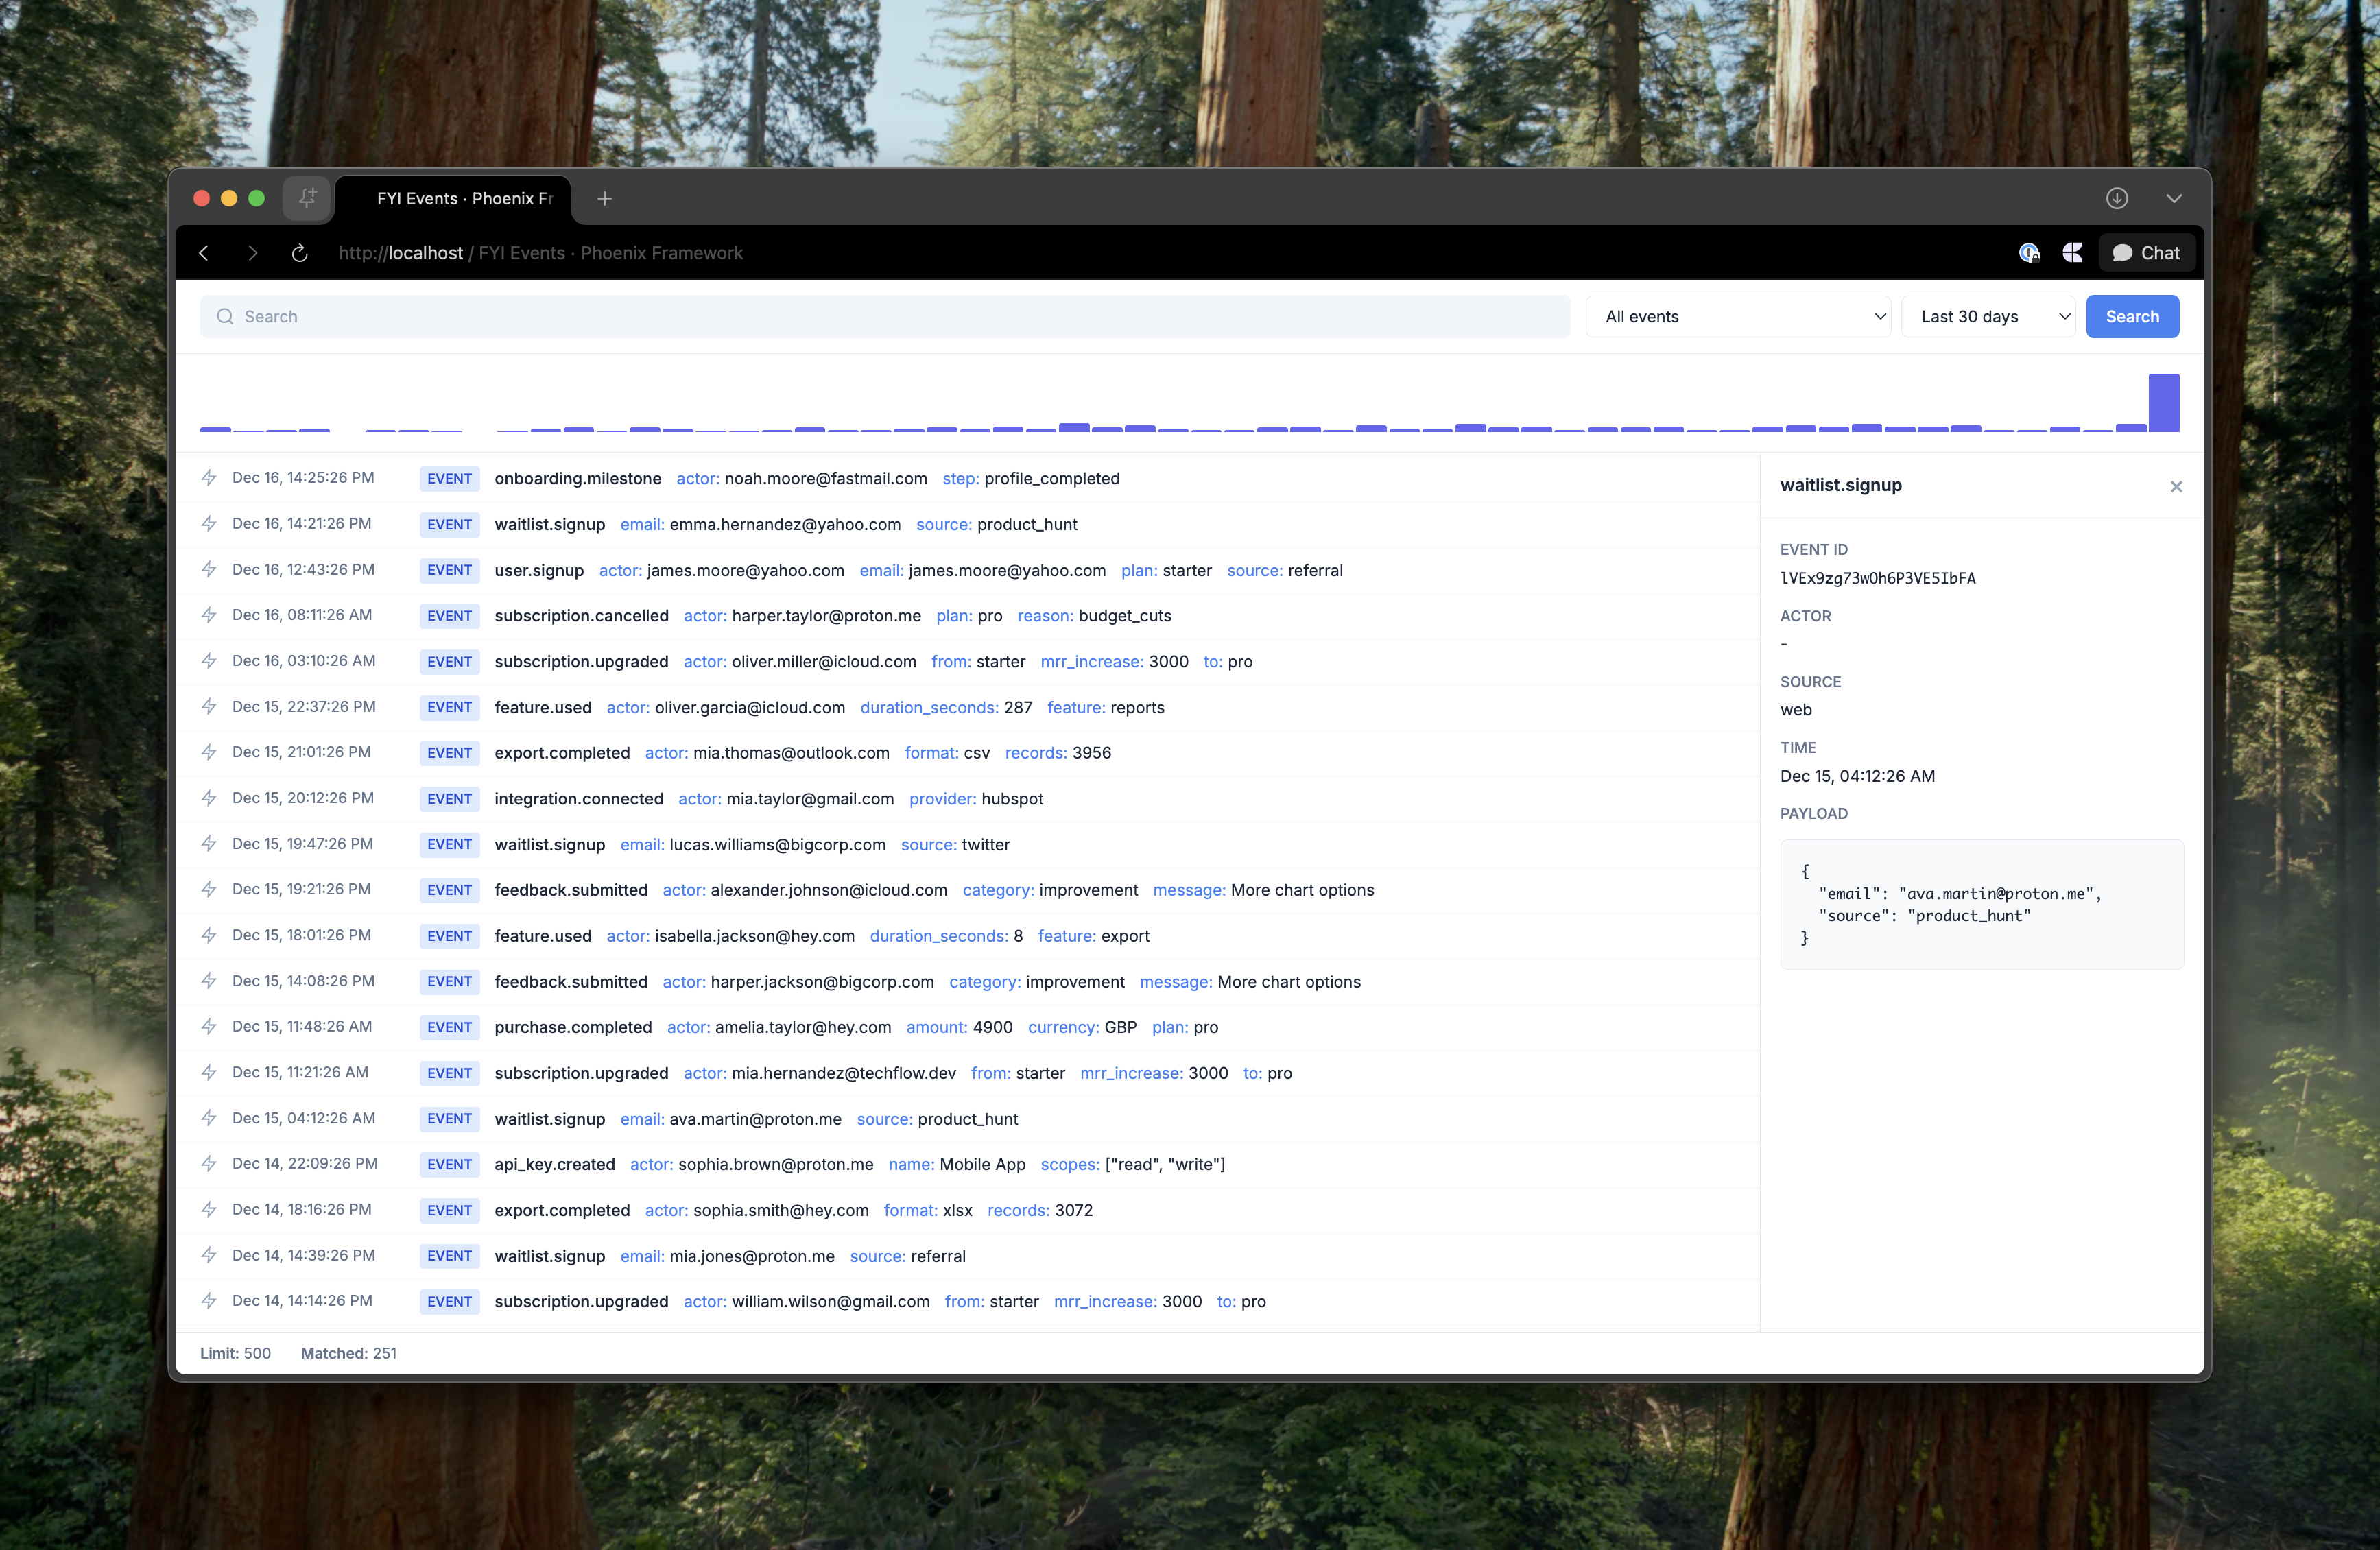
In-app events & feedback with Slack/Telegram notifications for Phoenix

Chrisinho8
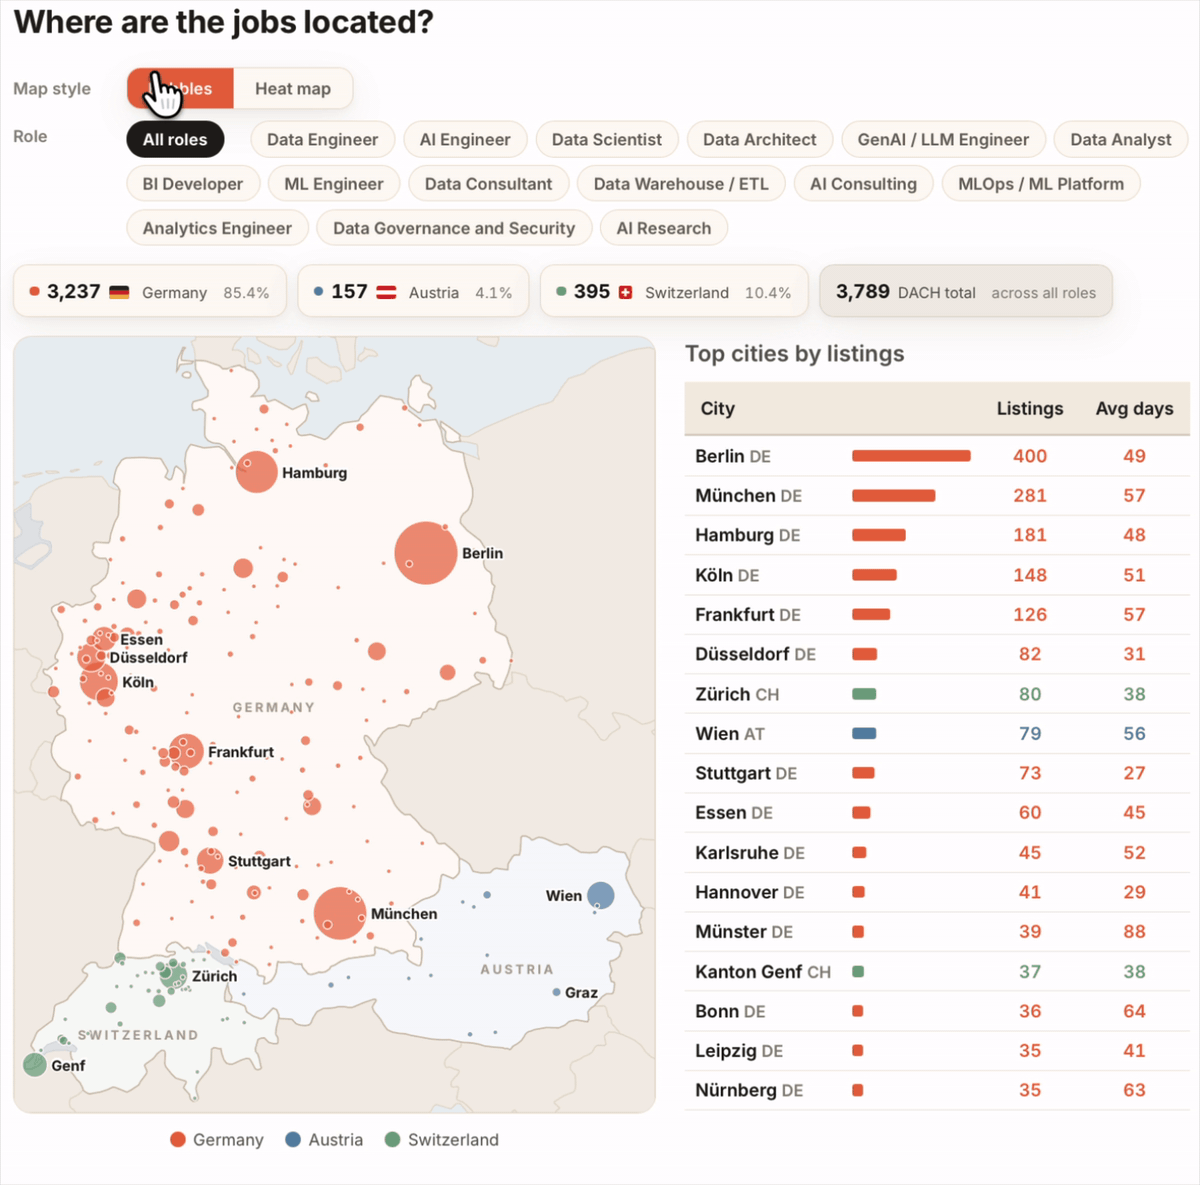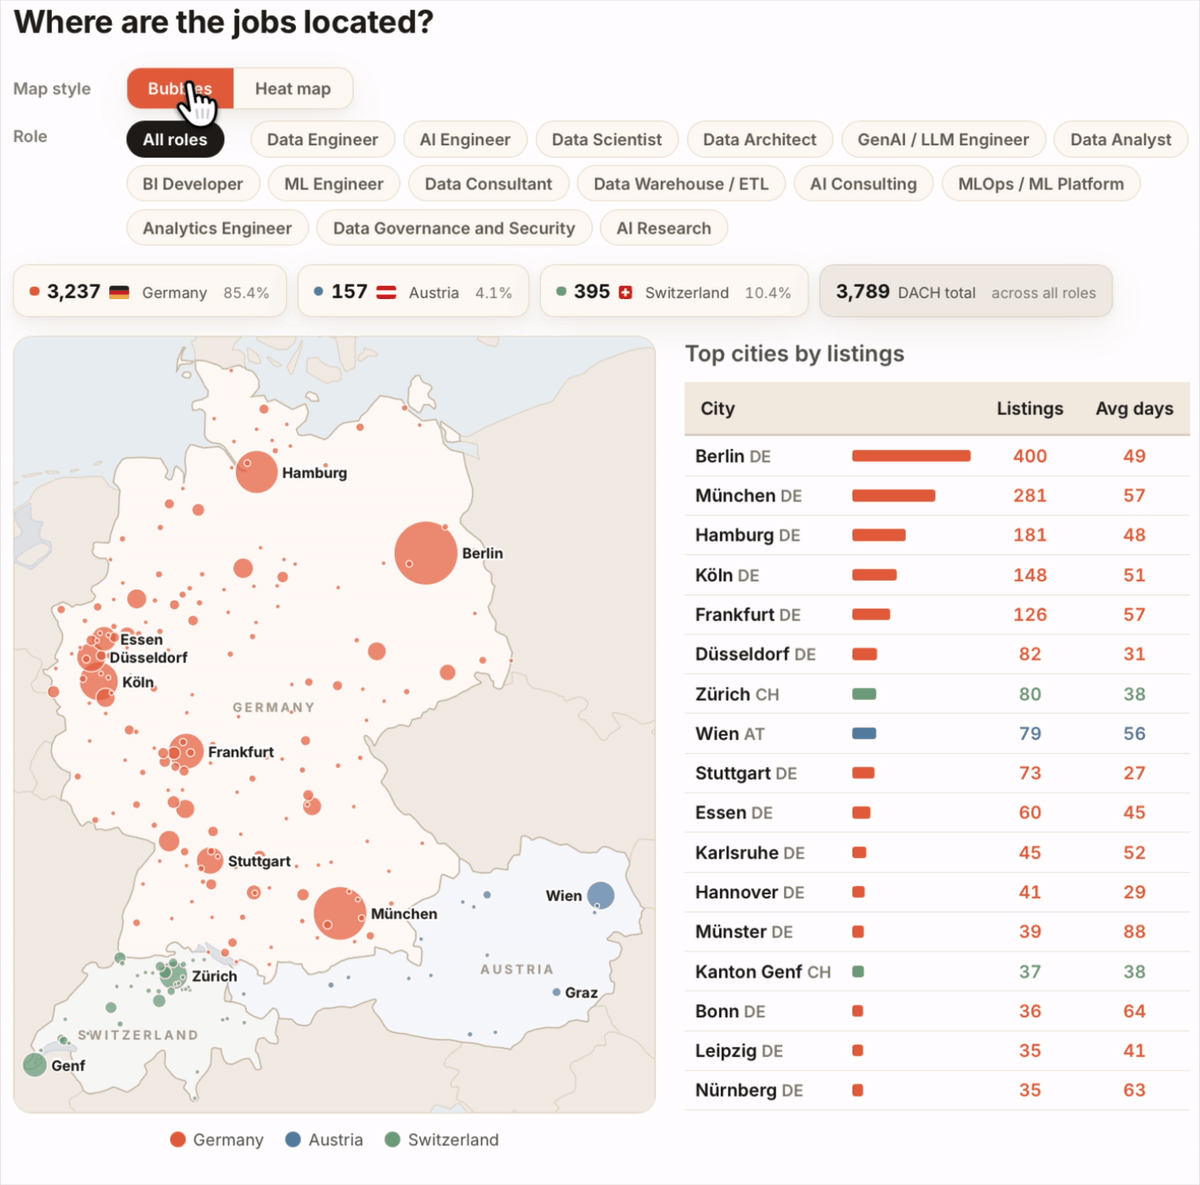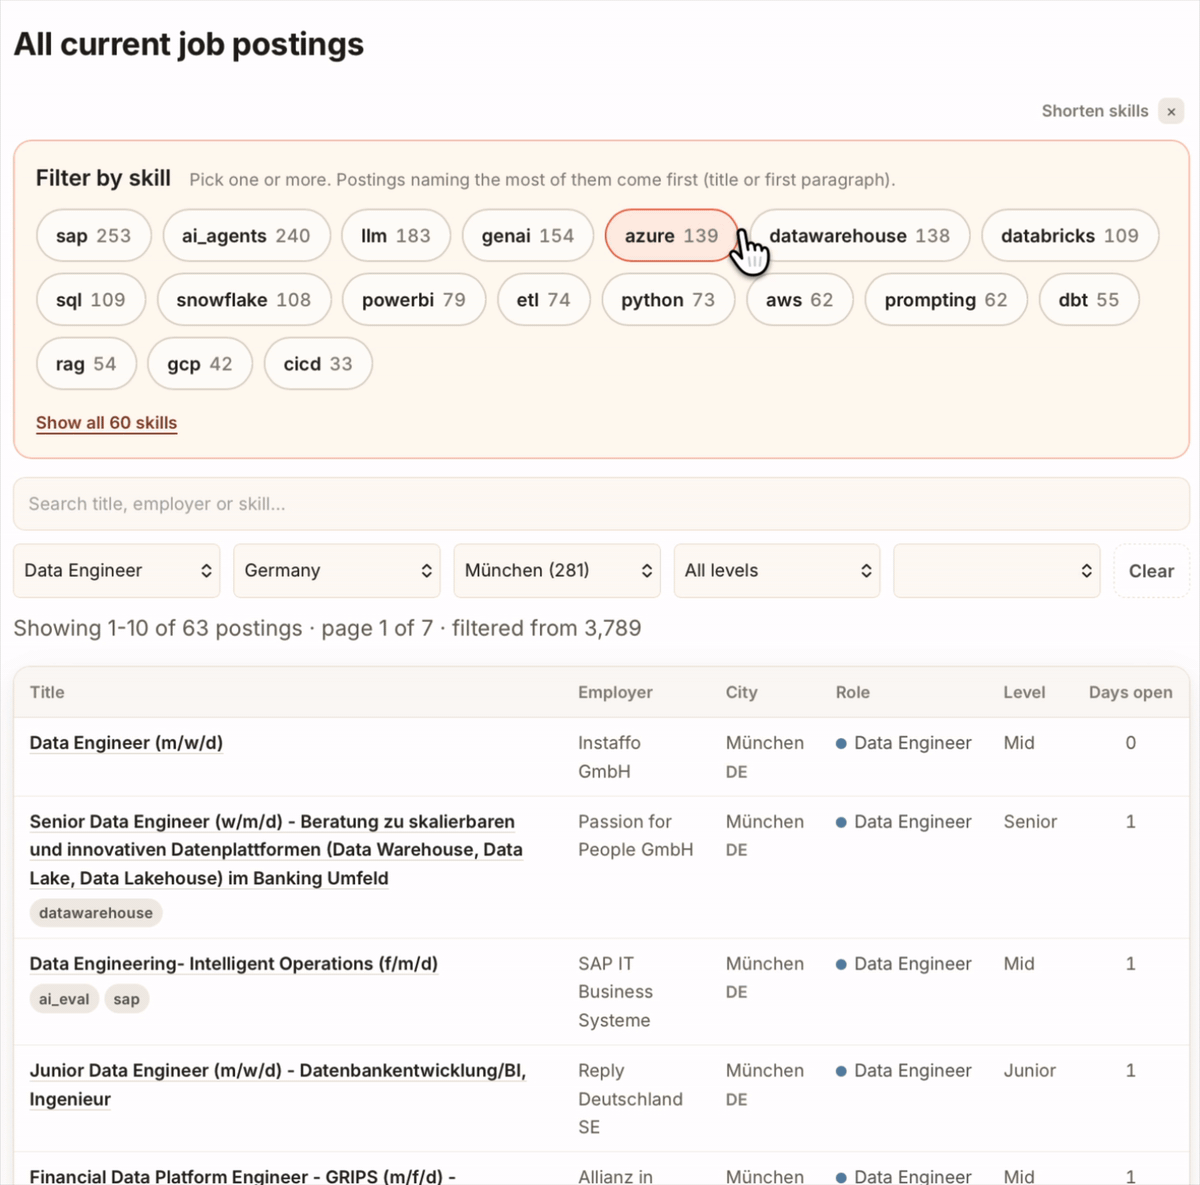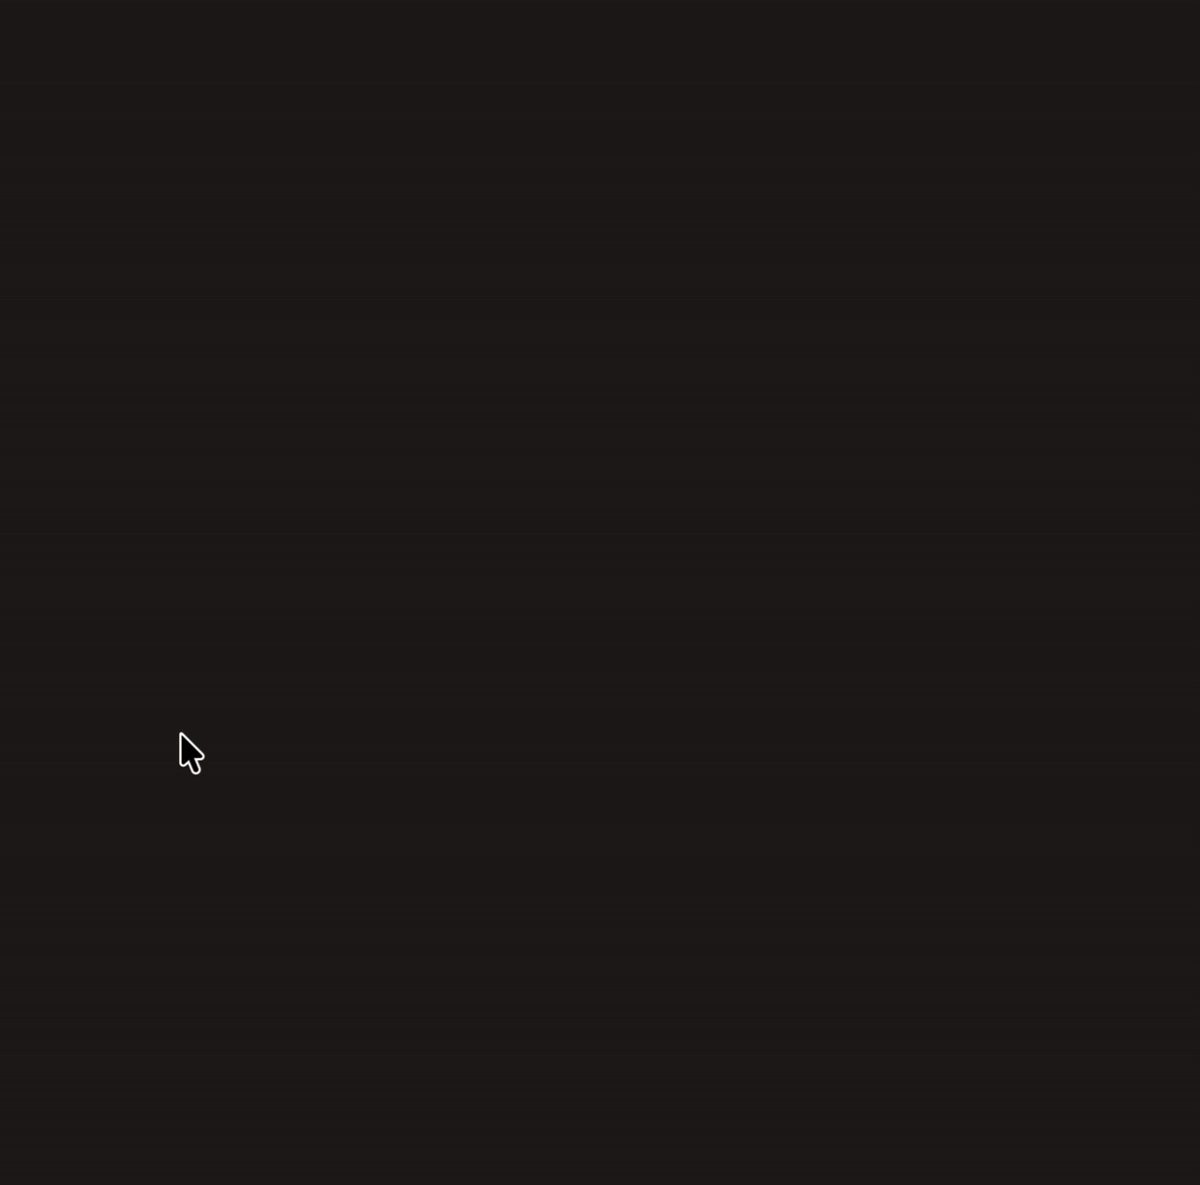
Daily tracker of the AI/Data job market in Germany, Austria and Switzerland. 3,000+ live postings processed through a Databricks + Delta Lake pipeline, with links to the original listings. Free and open, published on GitHub Pages.

chrismccord
A loyal data retriever for your Rails development databases.

ChristianTremblay
Pyhaystack is a module that allow python programs to connect to a haystack server project-haystack.org. Connection can be established with Niagara Platform running the nhaystack, Skyspark and Widesky. For this to work with Anaconda IPython Notebook in Windows, be sure to use "python setup.py install" using the Anaconda Command Prompt in Windows. If not, module will be installed for System path python but won't work in the environment of Anaconda IPython Notebook. You will need hszinc 1.3+ for this to work.

chrisveness
Koa Sample App (handlebars templating + RESTful API using MySQL, on Node.js)

chrisvoncsefalvay

Learn Julia the hard way!

ChuckBell
Database connector library for using MySQL with your Arduino projects.

ChuckHend
Execute SQL now and get the results later.
ChuckHend
Simple and focused time-series tables for PostgreSQL

chucknorris
RoundhousE is a Database Migration Utility for .NET using sql files and versioning based on source control
A real-time interactive web app based on data pipelines using streaming Twitter data, automated sentiment analysis, and MySQL&PostgreSQL database (Deployed on Heroku)

chungquantin

EDMA is an interactive terminal app for managing multiple embedded databases system at once with powerful byte deserializer support.

CHYbeta
Code-Audit-Challenges

ciaren-labs
Open-source, local-first visual ETL and data pipeline builder. Drag-and-drop data prep and ML workflows, preview every step, schedule runs, and export clean pandas or Polars Python code. Self-hosted, no lock-in.

cincuranet
Firebird ADO.NET Data Provider

cinemagoer
Cinemagoer est un paquet Python permettant de récupérer et de gérer les données sur les films, les personnes et les personnages de la base de données cinématographique IMDb (à laquelle nous ne sommes aucunement affiliés).

ciphermodelabs
User-friendly secure computation engine based on secure multi-party computation

cipherstash
Encrypt and search your sensitive data in PostgreSQL, with no SQL changes

circuithub

Hey! Hey! Can u rel8?

CIS-Team
Back End Squad Roadmap

CiscoCXSecurity
SQL Injection Exploitation Tool

citrusvanilla
The tiny time series database optimized for your happiness.
