
pydbgen
tirthajyoti
312étoiles
Random dataframe and database table generator
Comparez bases de données, analyses, SQL et projets d’ingénierie des données.
tirthajyoti
Random dataframe and database table generator
tirthajyoti
Fundamentals of Spark with Python (using PySpark), code examples

tko22
Simple flask boilerplate with Postgres, Docker, and Heroku/Zeit now

todoist

Powerful analytics and cohort library using Redis bitmaps.

toluaina

Postgres, MySQL, or MariaDB to Elasticsearch/OpenSearch sync

tonsky
Immutable database and Datalog query engine for Clojure, ClojureScript and JS

top-think
Think ORM——the PHP Database&ORM Framework

topling
ToplingDB is a cloud native LSM Key-Value Store with searchable compression algo and distributed compaction

toptal
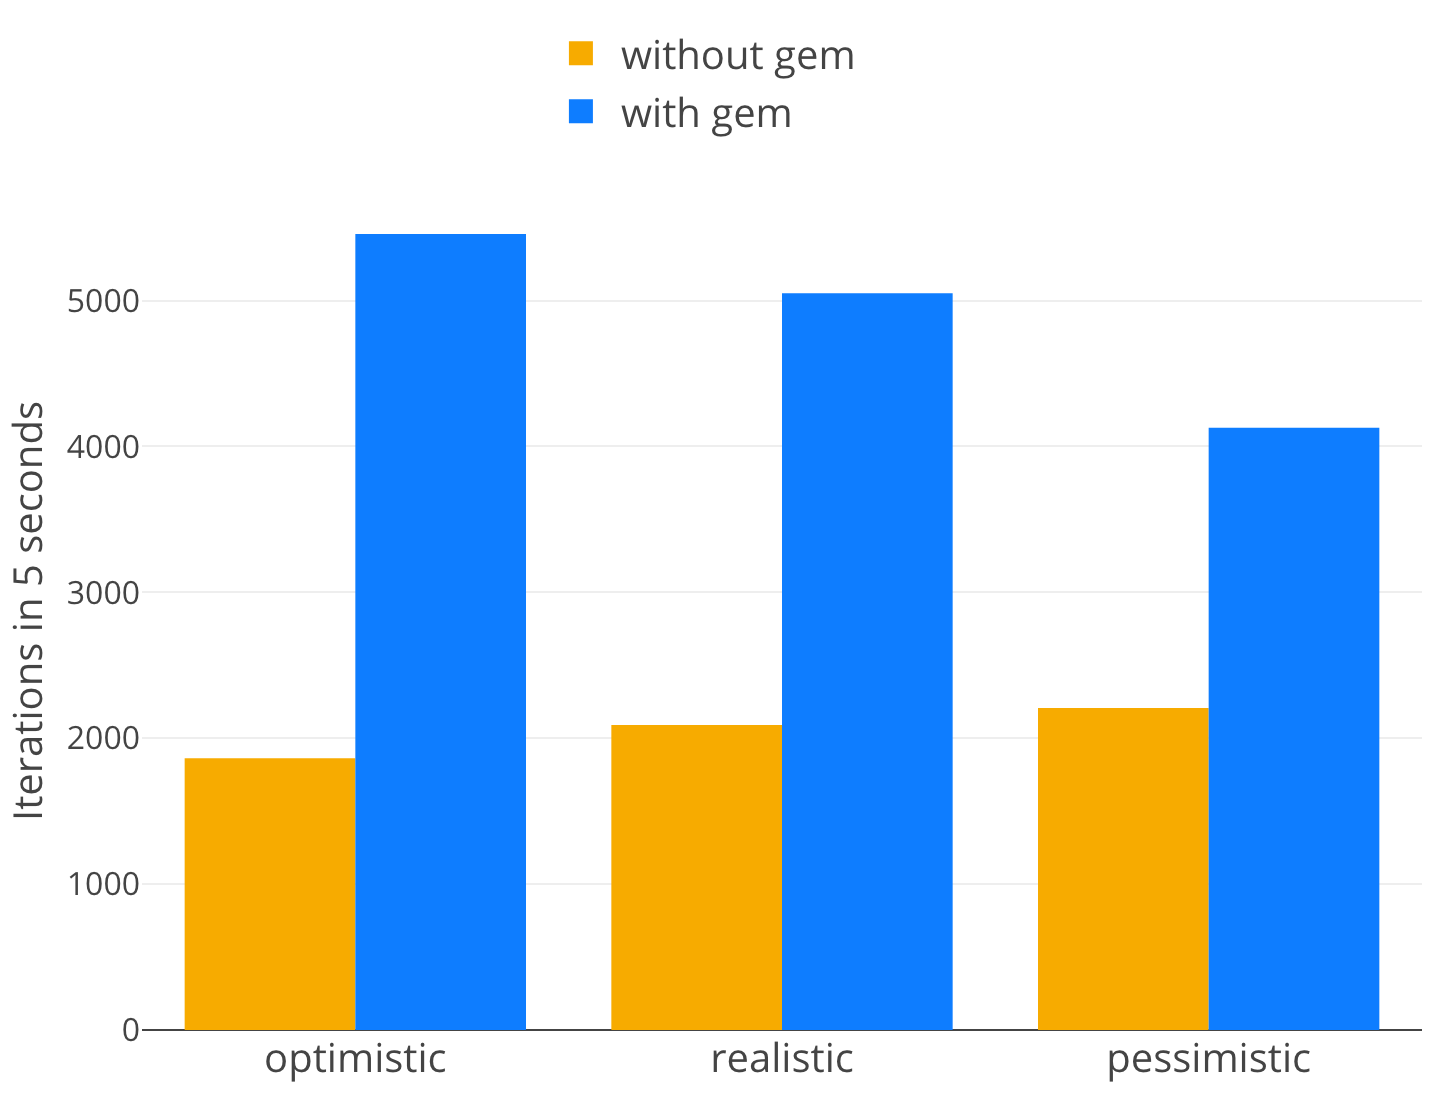
Database validations for ActiveRecord

torodb

The ToroDB solution to provide better analytics on top of MongoDB and make it easier to migrate from MongoDB to SQL

torque59
A Python Framework For NoSQL Scanning and Exploitation

tortoise
A database migrations tool for TortoiseORM, ready to production.
Support for many missing PostgreSQL specific features

tpope
dadbod.vim: Modern database interface for Vim

traildb

TrailDB is an efficient tool for storing and querying series of events

treeverse
lakeFS : contrôle de version des données de votre data lake | Git pour les données

treffynnon
A consistent code style guide for SQL to ensure legible and maintainable projects

tumblr
MySQL toolkit for managing billions of rows and hundreds of database machines

tuplex
Tuplex is a parallel big data processing framework that runs data science pipelines written in Python at the speed of compiled code. Tuplex has similar Python APIs to Apache Spark or Dask, but rather than invoking the Python interpreter, Tuplex generates optimized LLVM bytecode for the given pipeline and input data set.

TurboWay
大数据分析项目

turicas
A common, beautiful interface to tabular data, no matter the format

TylerBrock

MongoDB Shell Enhancements for Hackers

typelevel
A data access library for Scala + Postgres.

typicode
Makes it easy to manipulate id-based resources with lodash or lowdb
