Skip to content
Catégories de projets

Données · GitHub

Comparez bases de données, analyses, SQL et projets d’ingénierie des données.

Projets GitHub utiles

3,192 projets

gluten

apache

1,619étoiles
gluten preview

Gluten is a middle layer responsible for offloading JVM-based SQL engines' execution to native engines.

DonnéesScalaApache-2.0GitHub

hamilton

apache

2,628étoiles
hamilton preview

Apache Hamilton helps data scientists and engineers define testable, modular, self-documenting dataflows, that encode lineage/tracing and metadata. Runs and scales everywhere python does.

  • Separation of concerns. Apache Hamilton separates the DAG "definition" and "execution" which lets data scientists focus on solving problems and engineers manage production pipelines.
  • Effective collaboration. The Apache Hamilton UI provides a shared interface for teams to inspect results and debug failures throughout the development cycle.
DonnéesJupyter NotebookApache-2.0GitHub

hugegraph

apache

3,207étoiles
hugegraph preview

A graph database that supports more than 100+ billion data, high performance and scalability (Include OLTP Engine & REST-API & Backends)

  • Schema Metadata Management: VertexLabel, EdgeLabel, PropertyKey, and IndexLabel
  • Multi-type Indexes: Exact query, range query, and complex conditions combination query
DonnéesJavaApache-2.0GitHub

iotdb

apache

6,434étoiles

Apache IoTDB

  • Flexible deployment strategy. IoTDB provides users with a one-click installation tool on either the cloud platform or the terminal devices, and a data synchronization tool bridging the data on cloud platform and terminals.
  • Low cost on hardware. IoTDB can reach a high compression ratio of disk storage.
DonnéesJavaApache-2.0GitHub

kvrocks

apache

4,498étoiles
kvrocks preview

Apache Kvrocks est une base de données NoSQL distribuée clé-valeur qui utilise RocksDB comme moteur de stockage et est compatible avec le protocole Redis.

DonnéesC++Apache-2.0GitHub

kyuubi

apache

2,379étoiles
kyuubi preview

Apache Kyuubi is a distributed and multi-tenant gateway to provide serverless SQL on data warehouses and lakehouses.

DonnéesScalaApache-2.0GitHub

linkis

apache

3,420étoiles
linkis preview

Apache Linkis builds a computation middleware layer to facilitate connection, governance and orchestration between the upper applications and the underlying data engines.

  • Support for diverse underlying computation storage engines : Spark, Hive, Python, Shell, Flink, JDBC, Pipeline, Sqoop, OpenLooKeng, Presto, ElasticSearch, Trino, SeaTunnel, etc.;
  • Support for diverse language : SparkSQL, HiveSQL, Python, Shell, Pyspark, Scala, JSON and Java;
DonnéesJavaApache-2.0GitHub

pinot

apache

6,171étoiles
pinot preview

Apache Pinot: a real-time analytics database for low-latency SQL and vector search, serving user-facing and agent-facing applications

  • Fast Queries: Filter and aggregate petabyte data sets with P90 latencies in the tens of milliseconds—fast enough to return live results interactively in the UI.
  • High Concurrency: With user-facing applications querying Pinot directly, it can serve hundreds of thousands of concurrent queries per second.
DonnéesJavaApache-2.0GitHub

pouchdb

apache

17,627étoiles

:kangaroo: - PouchDB est une base de données compacte et légère.

DonnéesJavaScriptApache-2.0GitHub

sedona-db

apache

528étoiles
sedona-db preview

A single-node analytical database engine with geospatial as a first-class citizen

  • High Performance: Built in Rust for exceptional speed and memory efficiency
  • Comprehensive Spatial Toolkit: Supports both vector and raster functions in a single library
DonnéesRustApache-2.0GitHub
20,827étoiles
shardingsphere preview

Renforcez l’intelligence des données grâce au SQL distribué, pour le partitionnement, l’évolutivité et la sécurité de toutes les bases de données.
  • Database types completely decoupled, supporting rapid integration of new databases
  • Functional modules completely decoupled, supporting on-demand feature combination
DonnéesJavaApache-2.0GitHub
8,197étoiles
shardingsphere-elasticjob preview

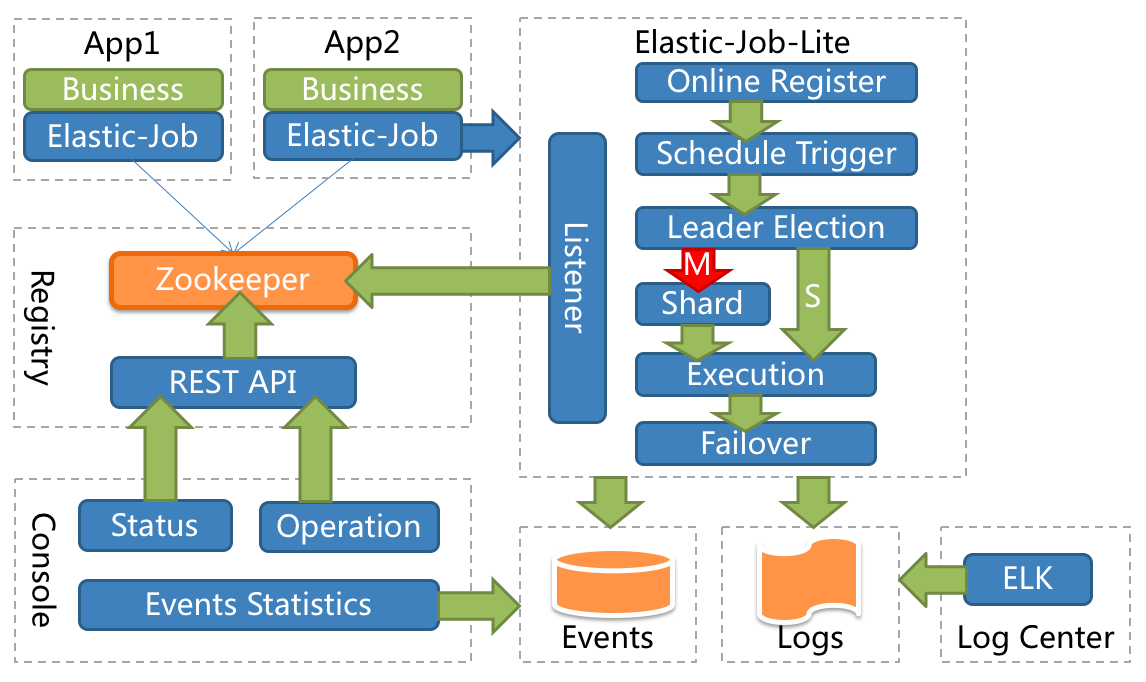
Distributed scheduled job

  • Support job sharding and high availability in distributed system
  • Scale out for throughput and efficiency improvement
DonnéesJavaApache-2.0GitHub

spark

apache

44,454étoiles

Apache Spark – Un moteur d’analyse unifié pour le traitement de données à grande échelle

DonnéesScalaApache-2.0GitHub