
z-lab/dflash
z-lab/dflash has 6,223 GitHub stars and 445 forks. GitHot measured +13 in 7 days. Last checked 2026-11-09 23:09 UTC. Last push 2026-08-18.
Comment ces chiffres sont mesurés
DFlash: Block Diffusion for Flash Speculative Decoding
Progression mesurée des étoiles
- in 24h
- Mise à jour retardée
- in 7 days
- +13
- in 15 days
- Mise à jour retardée
- in 1 month
- Mise à jour retardée
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
README.md
OriginalDFlash: Block Diffusion for Flash Speculative Decoding
DFlash is a lightweight block diffusion model designed for speculative decoding. It enables efficient and high-quality parallel drafting.
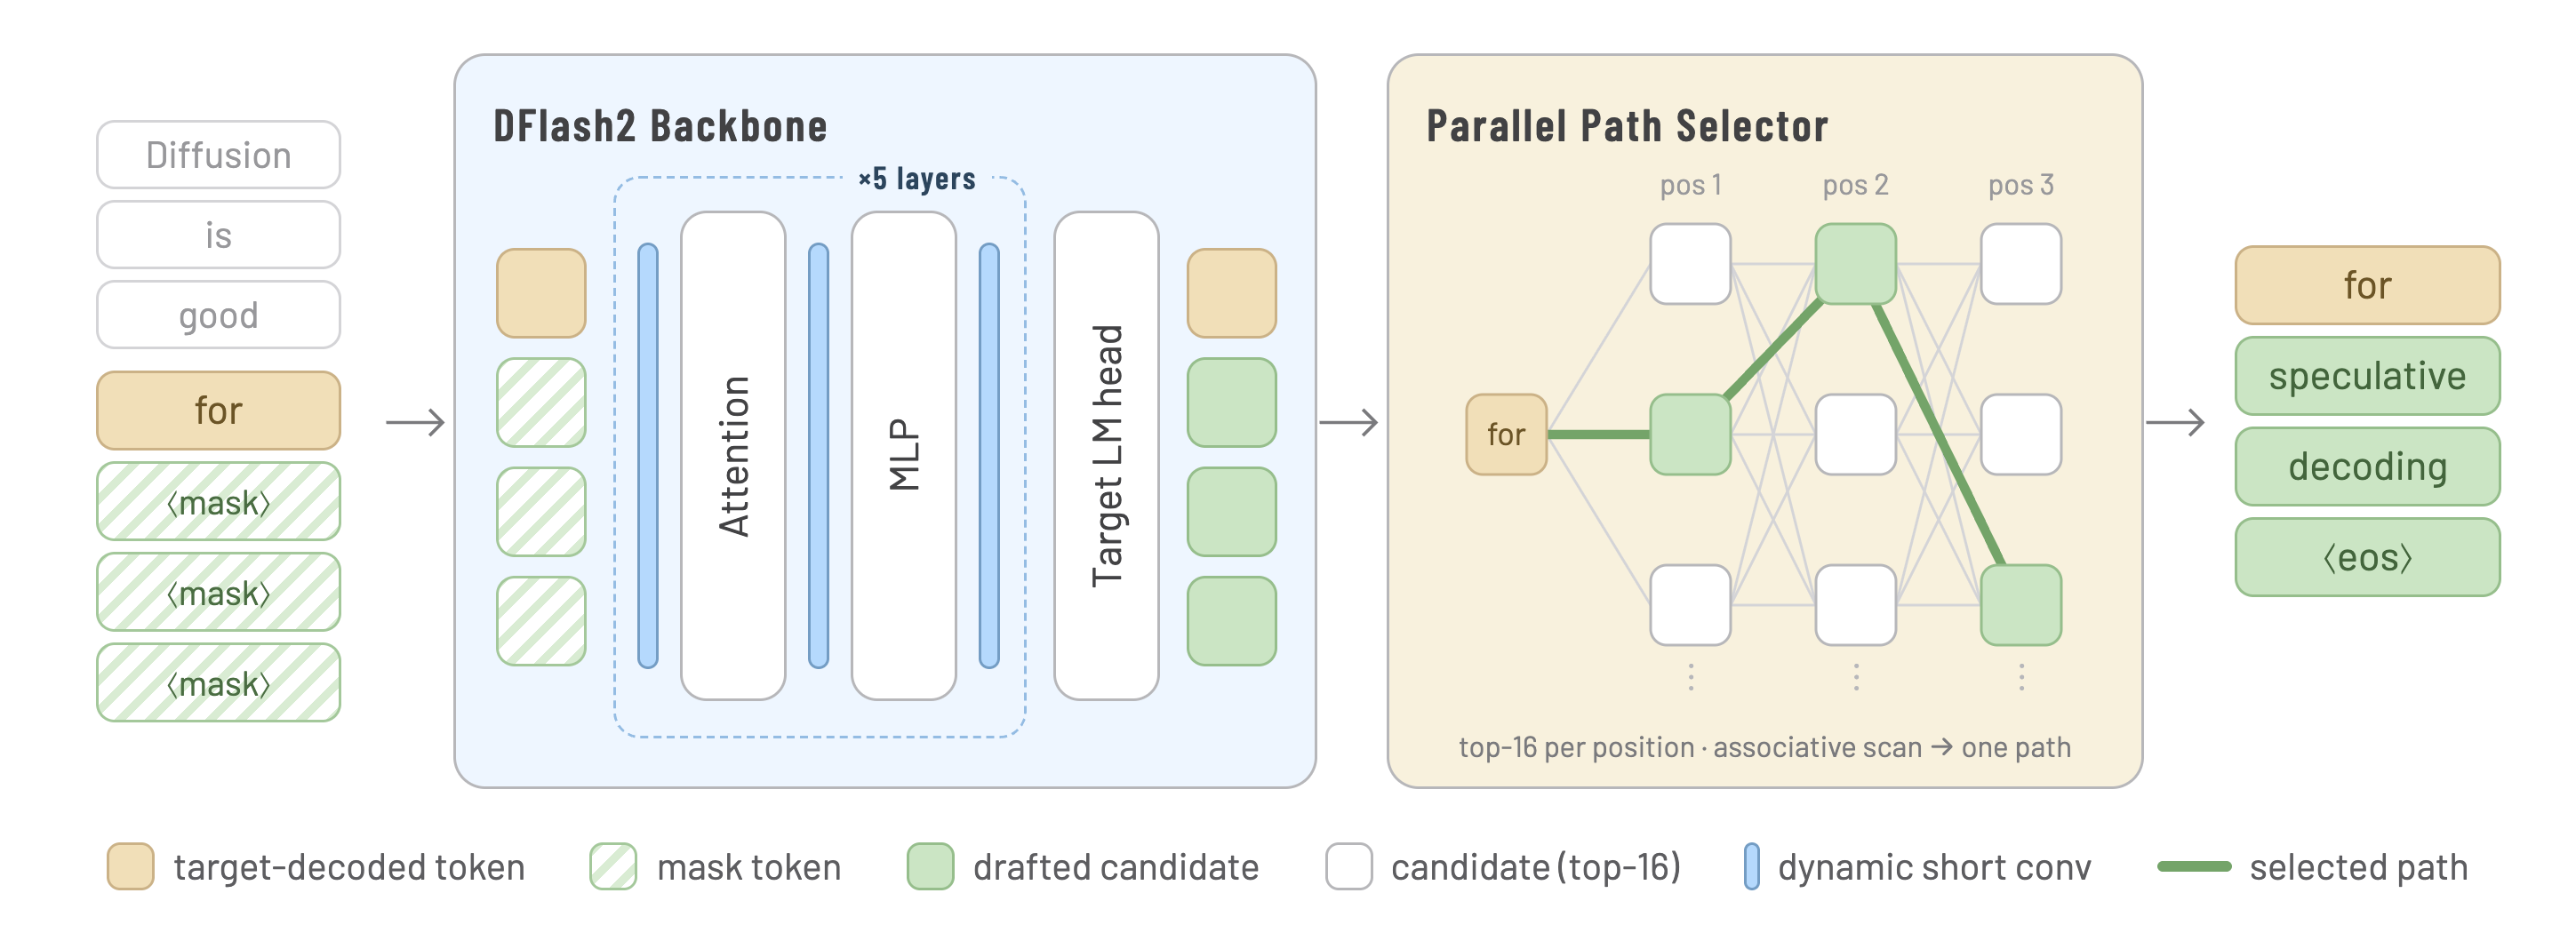
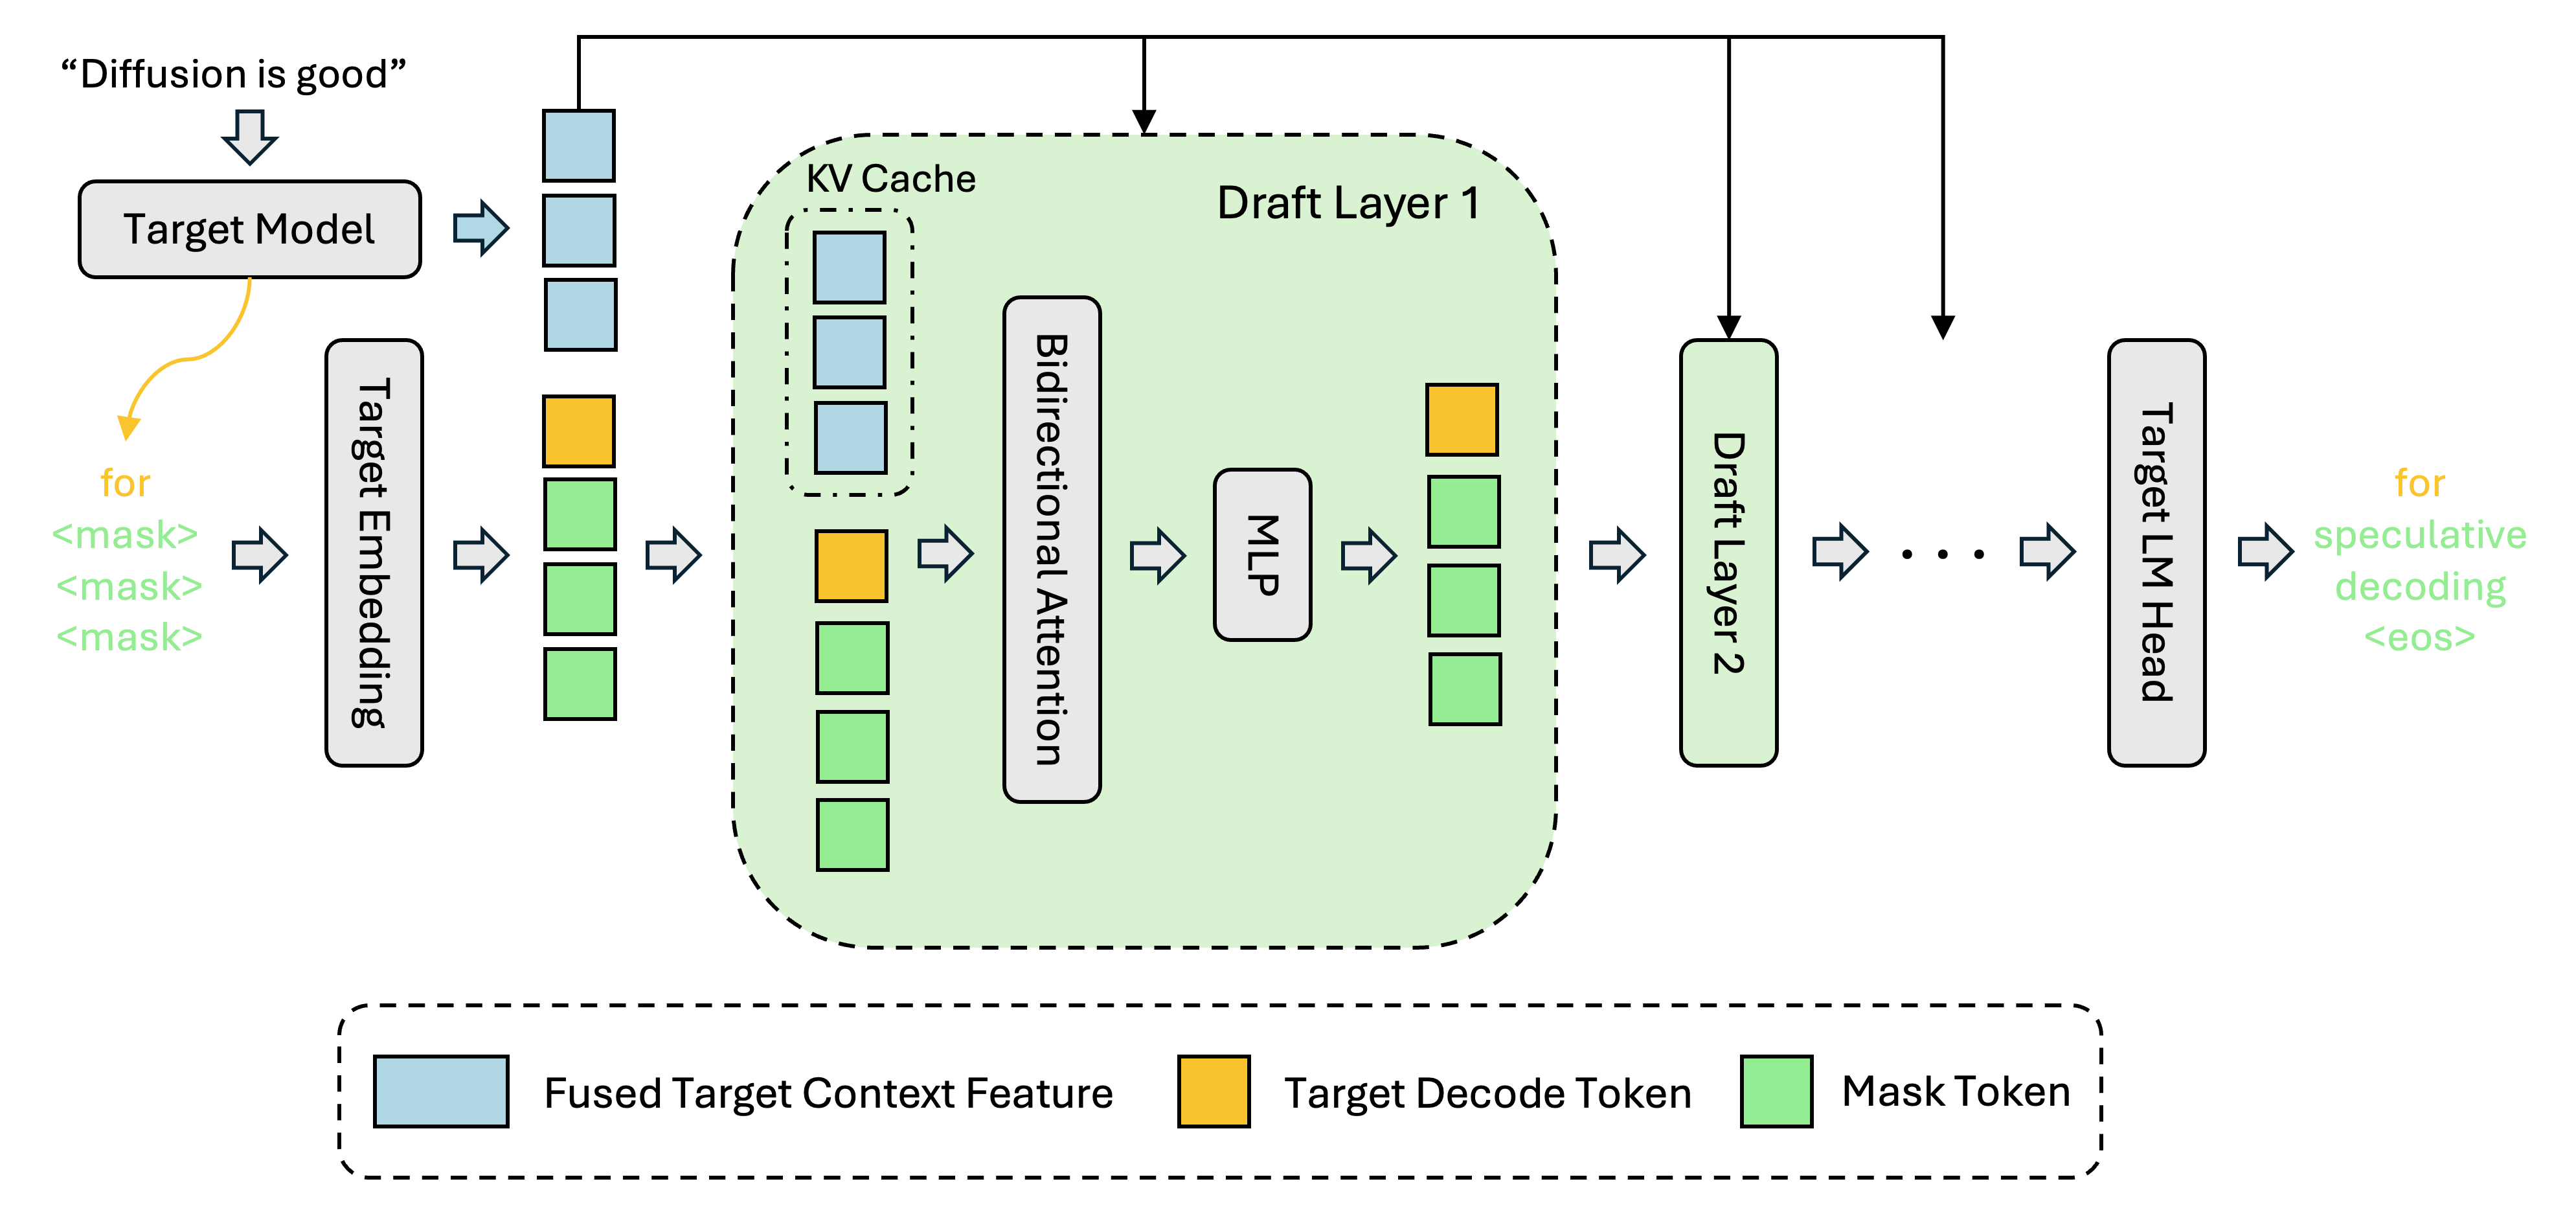
Supported Models
DFlash 2
Available checkpoints: Muse-Glimmer-30B and Qwen3.8-27B. See the DFlash 2 collection for updates.
DFlash
Public checkpoints are available in the DFlash collection:
- Qwen: Qwen3.6 (27B, 35B-A3B), Qwen3.5 (4B, 9B, 27B, 35B-A3B, 122B-A10B, 397B-A17B), Qwen3 (4B/8B non-thinking, Coder-Next, Coder-30B-A3B)
- Gemma: Gemma 4 (12B, 31B, 26B-A4B)
- MiniMax: M2.5, M2.7
- Kimi: K2.5, K2.6, K2.7-Code
- Others: GPT-OSS (20B, 120B), Llama-3.1-8B, GLM 5.1, Alpamayo 1.5/R1 10B
Use the Transformers or MLX backends below for their explicitly listed model families. Other checkpoints can be benchmarked through an OpenAI-compatible SGLang or vLLM server.
📦 Installation
Install the base package for an OpenAI-compatible server, or include local inference dependencies. The local install uses MLX on Apple Silicon and Transformers on Linux.
pip install dflash
pip install "dflash[local]"  # local inference
For serving benchmarks, install a supported version of SGLang, vLLM, oMLX, or llama.cpp separately, launch its OpenAI-compatible server with DFlash, and pass its --base-url below.
🚀 Quick Start
Transformers
The Transformers backend supports DFlash 2 for Muse-Glimmer-30B, and DFlash for
Qwen3 and LLaMA-3.1-8B. Muse uses reasoning_strength: low, medium, high
(default), or xhigh.
dflash generate transformers \
    --model meta-models/Muse-Glimmer-30B \
    --draft z-lab/Muse-Glimmer-30B-DFlash2 \
    --reasoning high --temperature 1 --top-p 0.95 --top-k 64 \
    "How many positive whole-number divisors does 196 have?"
MLX (Apple Silicon)
The MLX backend supports DFlash 2 for Qwen3.8-27B, and DFlash for Qwen3,
Qwen3.5, Qwen3.6, and Gemma 4. Qwen3.8 uses reasoning_effort: low, medium,
or xhigh (default). For quantized targets or drafts, use block_size <= 5: MLX's current
quantized matmul kernel becomes less efficient at larger verify widths.
The example below runs both the target and draft with 4-bit weights.
dflash generate mlx \
    --model mlx-community/Qwen3.8-27B-4bit \
    --draft z-lab/Qwen3.8-27B-DFlash2 \
    --draft-bits 4 --block-size 5 --reasoning xhigh \
    "How many positive whole-number divisors does 196 have?"
OpenAI-compatible server
Launch the latest SGLang or vLLM server separately, then run:
dflash generate openai \
    --base-url http://127.0.0.1:8000 --model Qwen/Qwen3.8-27B \
    "How many positive whole-number divisors does 196 have?"
📊 Evaluation
All benchmarks share the same datasets (gsm8k, math500, humaneval, mbpp, mt-bench), downloaded and cached by Hugging Face Datasets.
OpenAI-compatible server (SGLang or vLLM):
dflash benchmark openai \
    --base-url http://127.0.0.1:8000 --model Qwen/Qwen3.8-27B \
    --dataset gsm8k --num-prompts 128 --concurrency 1 --reasoning xhigh \
    --temperature 1 --top-p 0.95 --top-k 20
Transformers (Muse-Glimmer-30B DFlash 2):
dflash benchmark transformers \
    --model meta-models/Muse-Glimmer-30B --draft z-lab/Muse-Glimmer-30B-DFlash2 \
    --dataset gsm8k --max-samples 128 --reasoning high
MLX (Qwen3.8-27B 4-bit DFlash 2):
dflash benchmark mlx \
    --model mlx-community/Qwen3.8-27B-4bit --draft z-lab/Qwen3.8-27B-DFlash2 \
    --dataset gsm8k --max-samples 128 --reasoning xhigh --block-size 5 --draft-bits 4
Acknowledgement
Huge thanks to @dcw02, @gongy, and the team at @modal-labs for their fast, high-quality support in bringing DFlash to SGLang. And huge thanks as well to @benchislett at NVIDIA for his work in bringing DFlash to vLLM and helping make it available to the broader serving community.
Citation
If you find DFlash useful, please cite our work. To share feedback on DFlash or request new model support, please fill out this form: DFlash Feedback.
@article{chen2026dflash,
  title   = {{DFlash: Block Diffusion for Flash Speculative Decoding}},
  author  = {Chen, Jian and Liang, Yesheng and Liu, Zhijian},
  journal = {arXiv preprint arXiv:2602.06036},
  year    = {2026}
}

@misc{inco2026dflash2,
  title  = {DFlash 2: Keep Drafting Parallel},
  author = {{Inco AI}},
  year   = {2026},
  month  = {August},
  url    = {https://inco.ai/blog/dflash2/}
}
Explorer des projets similaires
codecrafters-io/build-your-own-x
Maîtrisez la programmation en recréant de zéro vos technologies préférées.
561,695 étoilespublic-apis/public-apis
Une liste collective d'API gratuites
498,092 étoilesmorluto/rea
Rétro-ingénierie de n'importe quoi avec des agents, du comportement des applications jusqu'aux binaires natifs.
451,208 étoilesopenclaw/openclaw
L'IA qui fait vraiment les choses. Tout système d'exploitation, toute plateforme. À la manière du homard. 🦞
394,318 étoiles