
tinker495/JAxtar
tinker495/JAxtar has 52 GitHub stars and 3 forks. GitHot measured 0 stars in 24 hours and 0 in 7 days. Last checked 2026-11-13 10:53 UTC. Last push 2026-10-31.
Progression mesurée des étoiles
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- Historique en cours
- in 1 month
- Historique en cours
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
À propos
JAxtar is a project with a JAX-native implementation of parallelizeable A* & Q* solver for neural heuristic search research.
Apprentissage automatiqueREADME.md
Original
JAxtar: GPU-accelerated Batched parallel A* & Q* solver in pure JAX!
JAxtar is a project with a JAX-native implementation of parallelizable a A* & Q* solver for neural heuristic search research. This project is inspired by mctx from Google DeepMind. If MCTS can be implemented entirely in pure JAX, why not A*?
This project provides the following algorithms:
- A*: Standard A* Search
- A* Deferred: A* Search with deferred node expansion (for heavy expansion costs)
- Bi-A*: Bidirectional A* Search
- Bi-A* Deferred: Bidirectional A* Search with deferred node expansion
- ID-A*: Iterative Deepening A* Search
- Beam Search: Standard Beam Search
- Q*: Q* Search (A* with learned Q-values)
- Bi-Q*: Bidirectional Q* Search
- ID-Q*: Iterative Deepening Q* Search (Experimental)
- Q-Beam: Beam Search with learned Q-values
MCTS, or tree search, is used in many RL algorithmic techniques, starting with AlphaGo, but graph search (not tree search) doesn't seem to have received much attention. Nevertheless, there are puzzle‐solving algorithms that use neural heuristics like DeepcubeA with A* or Q*(graph search).
However, the most frustrating aspect of my brief research (MSc) in this area is the time it takes to pass information back and forth between the GPU and CPU. When using a neural heuristic to evaluate a single node, the communication between the CPU and GPU, rather than the computation itself, can consume between 50% and 80% of the total processing time. Because of this communication overhead, DeepcubeA batches multiple nodes concurrently, which appears to work quite well.
However, these issues indicate that a more fundamental solution is needed. This led me to search for ways to perform A* directly on the GPU, but I discovered that most implementations suffer from the following problems.
- Many are written in pure C and CUDA, which is not well-suited for machine learning research.
- Some are written in JAX or PyTorch, but these are often limited to 2D grid environments or connectivity matrices, and cannot scale to an infinite number of different states that cannot all be held in memory.
- The implementation itself is often dependent on the specific definition of the state or problem.
To address these challenges, I decided to develop code based on the following principles:
- Pure JAX implementation
- Specifically for machine learning research.
- JAX-native priority queue
- The A* algorithm necessitates a priority queue to process nodes based on the lowest combined cost and heuristic estimate.
- However, standard Python heaps use lists, which are not JIT-compilable in JAX. Thus, a JAX-iterable heap is necessary.
- Hashable state representation and a hashtable for JAX operations.
- This is crucial for tracking node status (open/closed) in A* and efficiently retrieving parent state information.
- Hashing is optional for simple, indexable states. But for complex or infinite state spaces, hashing becomes essential for efficient indexing and retrieval of unique states.
- Fully batched and parallelized operations
- GPUs provide massive parallelism but have slower cores than CPUs. Therefore, algorithms for GPUs must be highly parallelized to leverage their architecture.
- Puzzle-agnostic implementation
- The implementation should be general enough to handle any puzzle with a defined state and action space.
- This generality enables wider research and allows for formalizing 'strict' behaviors in future implementations.
This project features specially written components, including:
Xtructure: A library providing JAX-compatible hash and priority queue implementations, originally developed as part of this project and later separated. This package includes:- a hashtable for parallel lookup and insertion operations
- a priority queue that supports batching, push, and pop operations
PuXle: All puzzle implementations have been moved to this separate high-performance library for parallelized puzzle environments built on JAX- PuXle world models registered for latent-space heuristic search
- Network heuristics and Q-functions designed for JIT-compilable integration with A* & Q* algorithm
- a fully JIT-compiled A* & Q* algorithm for puzzles
This project was quite challenging to develop, and it felt like performing acrobatics with JAX. However, I managed to create a fully functional version, and hopefully it will inspire you to discover something amazing as you delve into JAX.
Installation
Add JAxtar directly from GitHub to another uv project:
uv add "jaxtar @ git+https://github.com/tinker495/JAxtar.git"
For development or to use the checkout-only CLI, clone the repository and sync its environment:
git clone https://github.com/tinker495/JAxtar.git
cd JAxtar
uv sync --extra gpu
JAxtar uses pyproject.toml for installation and command registration. PuXle and Xtructure are
declared as Git dependencies and resolved to the revisions in uv.lock. From the synced checkout:
uv run jaxtar --help
uv run jaxtar test --help
uv run astar_d --help
For the complete GPU training pipeline, including logging backends and evaluation tools:
uv sync --extra train
The console commands are checkout-only. External distributions intentionally contain only the
JAxtar core package; generic top-level modules such as cli, config, and helpers are not
packaged.
Omit --extra gpu for CPU-only use, or replace it with --extra tpu on TPU. Evaluation tools are
installed by default. The train extra adds the GPU runtime and all logging backends, so it
conflicts with tpu.
Usage and Documentation
The CLI uses tyro with typed options. Existing flat flags, short aliases, and
10M / 2^20 numeric notation are supported. Both --batch-size and
--batch_size work. Use --help for help; -h retains its --hard meaning.
Omitted options inherit puzzle and training preset defaults.
For detailed information on all available commands and their options, please refer to the official documentation.
Result
We can find the optimal path using a jittable, batched A* search as shown below. This is not a super blazingly fast result, but it can be well integrated with heuristics using neural networks.
The following speed benchmarks were measured on an Nvidia RTX 5090 hosted at vast.ai.
You can easily test it yourself with the colab link below.

Test Run
$ uv run astar
╭─────────────── Seed 0 ────────────────╮
│    Start State        Target State    │
│ ┏━━━┳━━━┳━━━┳━━━┓   ┏━━━┳━━━┳━━━┳━━━┓ │
│ ┃ 9 ┃ E ┃ 6 ┃ 8 ┃   ┃ 1 ┃ 2 ┃ 3 ┃ 4 ┃ │
│ ┣━━━╋━━━╋━━━╋━━━┫   ┣━━━╋━━━╋━━━╋━━━┫ │
│ ┃ D ┃ 4 ┃ 7 ┃   ┃   ┃ 5 ┃ 6 ┃ 7 ┃ 8 ┃ │
│ ┣━━━╋━━━╋━━━╋━━━┫ → ┣━━━╋━━━╋━━━╋━━━┫ │
│ ┃ B ┃ 1 ┃ A ┃ C ┃   ┃ 9 ┃ A ┃ B ┃ C ┃ │
│ ┣━━━╋━━━╋━━━╋━━━┫   ┣━━━╋━━━╋━━━╋━━━┫ │
│ ┃ 5 ┃ 3 ┃ F ┃ 2 ┃   ┃ D ┃ E ┃ F ┃   ┃ │
│ ┗━━━┻━━━┻━━━┻━━━┛   ┗━━━┻━━━┻━━━┻━━━┛ │
│              Dist: 34.00              │
╰───────────────────────────────────────╯
     Search Result for Seed 0
┏━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┓
┃ Metric        ┃          Value ┃
┡━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━┩
│ Status        │ Solution Found │
│ Cost          │           50.0 │
│ Search Time   │         0.12 s │
│ Search States │           738K │
│ States/s      │          6.15M │
└───────────────┴────────────────┘
Test vmapped run
$ uv run astar --vmap_size 20
╭──────────────────────────────── Vmapped Search Setup ─────────────────────────────────╮
│ ╭────────────────────────────────── Batched State ──────────────────────────────────╮ │
│ │  ┏━━━┳━━━┳━━━┳━━━┓  ┏━━━┳━━━┳━━━┳━━━┓       ┏━━━┳━━━┳━━━┳━━━┓  ┏━━━┳━━━┳━━━┳━━━┓  │ │
│ │  ┃ 9 ┃ E ┃ 6 ┃ 8 ┃  ┃ 9 ┃ E ┃ 6 ┃ 8 ┃       ┃ 9 ┃ E ┃ 6 ┃ 8 ┃  ┃ 9 ┃ E ┃ 6 ┃ 8 ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫       ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ D ┃ 4 ┃ 7 ┃   ┃  ┃ D ┃ 4 ┃ 7 ┃   ┃       ┃ D ┃ 4 ┃ 7 ┃   ┃  ┃ D ┃ 4 ┃ 7 ┃   ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  ...  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ B ┃ 1 ┃ A ┃ C ┃  ┃ B ┃ 1 ┃ A ┃ C ┃       ┃ B ┃ 1 ┃ A ┃ C ┃  ┃ B ┃ 1 ┃ A ┃ C ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫       ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ 5 ┃ 3 ┃ F ┃ 2 ┃  ┃ 5 ┃ 3 ┃ F ┃ 2 ┃       ┃ 5 ┃ 3 ┃ F ┃ 2 ┃  ┃ 5 ┃ 3 ┃ F ┃ 2 ┃  │ │
│ │  ┗━━━┻━━━┻━━━┻━━━┛  ┗━━━┻━━━┻━━━┻━━━┛       ┗━━━┻━━━┻━━━┻━━━┛  ┗━━━┻━━━┻━━━┻━━━┛  │ │
│ ╰────────────────────────────────── shape: (20,) ───────────────────────────────────╯ │
│                                                                                       │
│                                           ↓                                           │
│                                                                                       │
│ ╭─────────────────────────────── Batched SolveConfig ───────────────────────────────╮ │
│ │  ┏━━━┳━━━┳━━━┳━━━┓  ┏━━━┳━━━┳━━━┳━━━┓       ┏━━━┳━━━┳━━━┳━━━┓  ┏━━━┳━━━┳━━━┳━━━┓  │ │
│ │  ┃ 1 ┃ 2 ┃ 3 ┃ 4 ┃  ┃ 1 ┃ 2 ┃ 3 ┃ 4 ┃       ┃ 1 ┃ 2 ┃ 3 ┃ 4 ┃  ┃ 1 ┃ 2 ┃ 3 ┃ 4 ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫       ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ 5 ┃ 6 ┃ 7 ┃ 8 ┃  ┃ 5 ┃ 6 ┃ 7 ┃ 8 ┃       ┃ 5 ┃ 6 ┃ 7 ┃ 8 ┃  ┃ 5 ┃ 6 ┃ 7 ┃ 8 ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  ...  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ 9 ┃ A ┃ B ┃ C ┃  ┃ 9 ┃ A ┃ B ┃ C ┃       ┃ 9 ┃ A ┃ B ┃ C ┃  ┃ 9 ┃ A ┃ B ┃ C ┃  │ │
│ │  ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫       ┣━━━╋━━━╋━━━╋━━━┫  ┣━━━╋━━━╋━━━╋━━━┫  │ │
│ │  ┃ D ┃ E ┃ F ┃   ┃  ┃ D ┃ E ┃ F ┃   ┃       ┃ D ┃ E ┃ F ┃   ┃  ┃ D ┃ E ┃ F ┃   ┃  │ │
│ │  ┗━━━┻━━━┻━━━┻━━━┛  ┗━━━┻━━━┻━━━┻━━━┛       ┗━━━┻━━━┻━━━┻━━━┛  ┗━━━┻━━━┻━━━┻━━━┛  │ │
│ ╰────────────────────────────────── shape: (20,) ───────────────────────────────────╯ │
│                                                                                       │
╰───────────────────────────────────────────────────────────────────────────────────────╯
           Vmapped Search Result
┏━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Metric          ┃                  Value ┃
┡━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━┩
│ Search Time     │       3.18s (x26.5/20) │
│ Search States   │ 14.8M (4.64M states/s) │
│ Speedup         │                   x0.8 │
│ Solutions Found │                100.00% │
└─────────────────┴────────────────────────┘
A* with neural heuristic model
$ uv run astar -nn -h -p rubikscube -w 0.2

...

     Search Result for Seed 0
┏━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┓
┃ Metric        ┃          Value ┃
┡━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━┩
│ Status        │ Solution Found │
│ Cost          │           22.0 │
│ Search Time   │         0.49 s │
│ Search States │          1.85M │
│ States/s      │          3.78M │
└───────────────┴────────────────┘
Q* with neural Q model
$ uv run qstar -nn -h -p rubikscube -w 0.2

...

     Search Result for Seed 0
┏━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┓
┃ Metric        ┃          Value ┃
┡━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━┩
│ Status        │ Solution Found │
│ Cost          │           22.0 │
│ Search Time   │         0.16 s │
│ Search States │          1.79M │
│ States/s      │          10.9M │
└───────────────┴────────────────┘
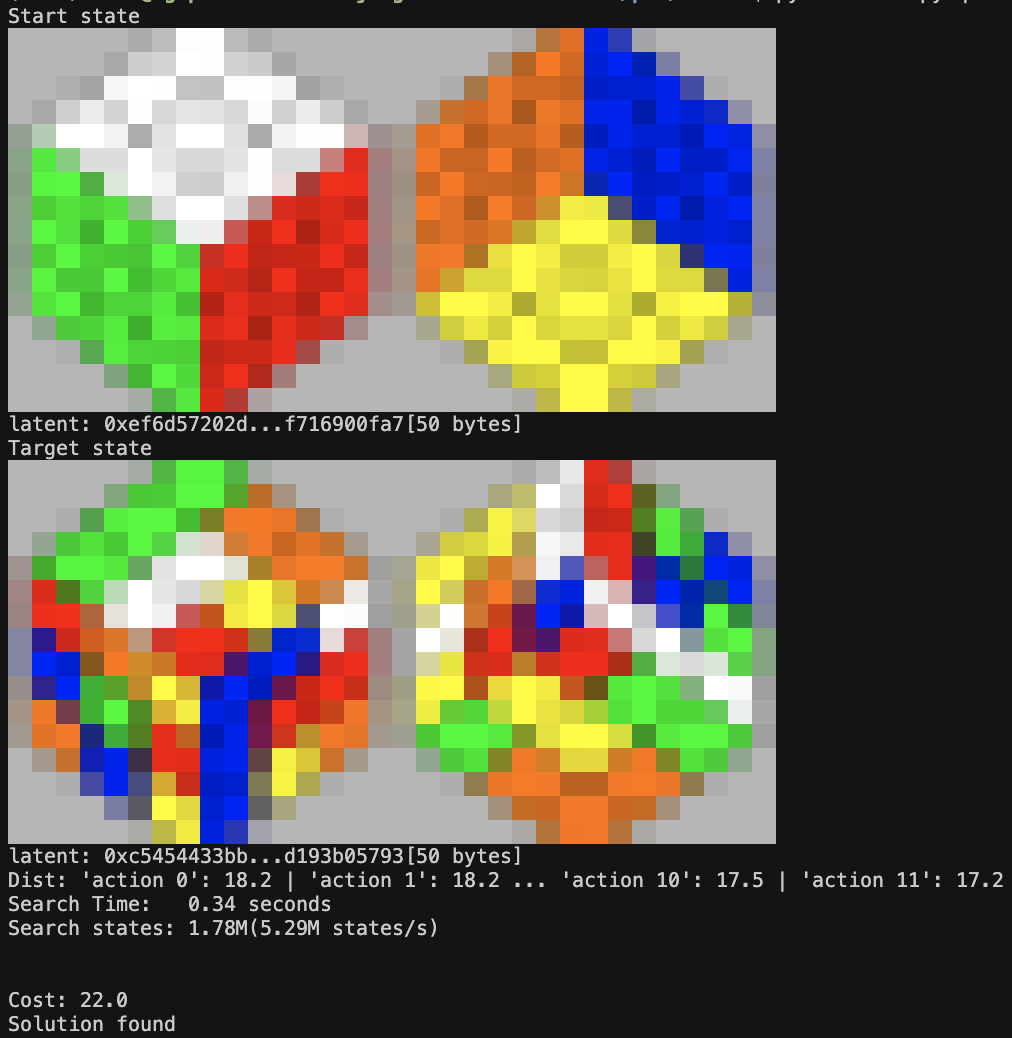
World Model Puzzle with A* & Q*
$ uv run qstar -p rubikscube_world_model_optimized -nn -w 0.6

...

     Search Result for Seed 0
┏━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┓
┃ Metric        ┃          Value ┃
┡━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━┩
│ Status        │ Solution Found │
│ Cost          │           22.0 │
│ Search Time   │         0.17 s │
│ Search States │          1.82M │
│ States/s      │          10.5M │
└───────────────┴────────────────┘
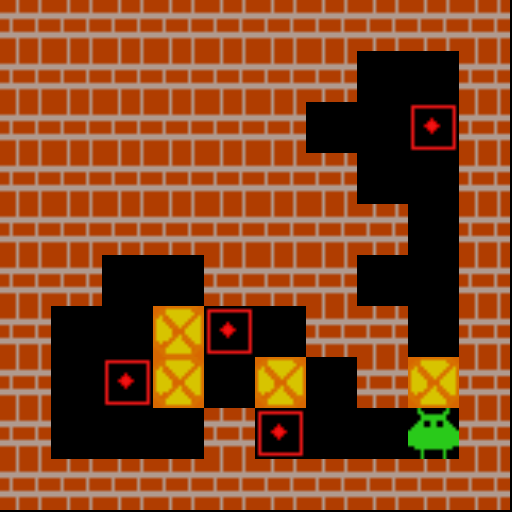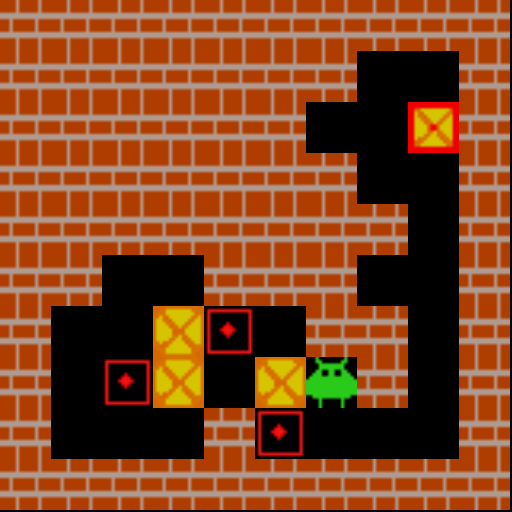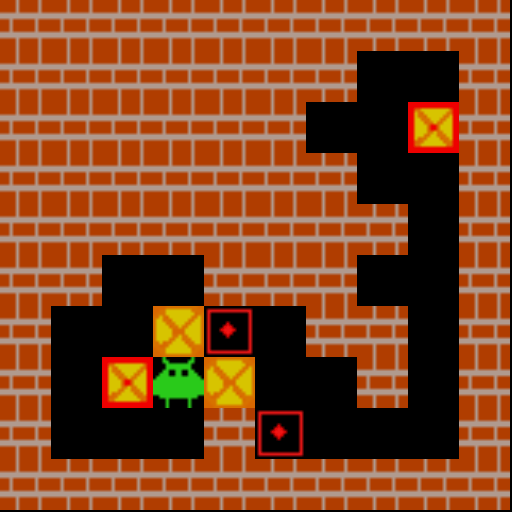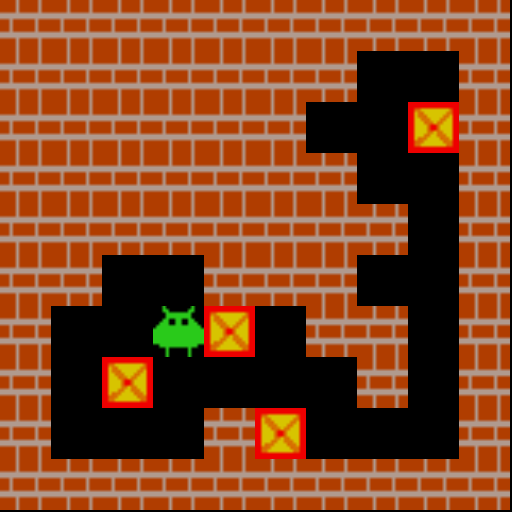
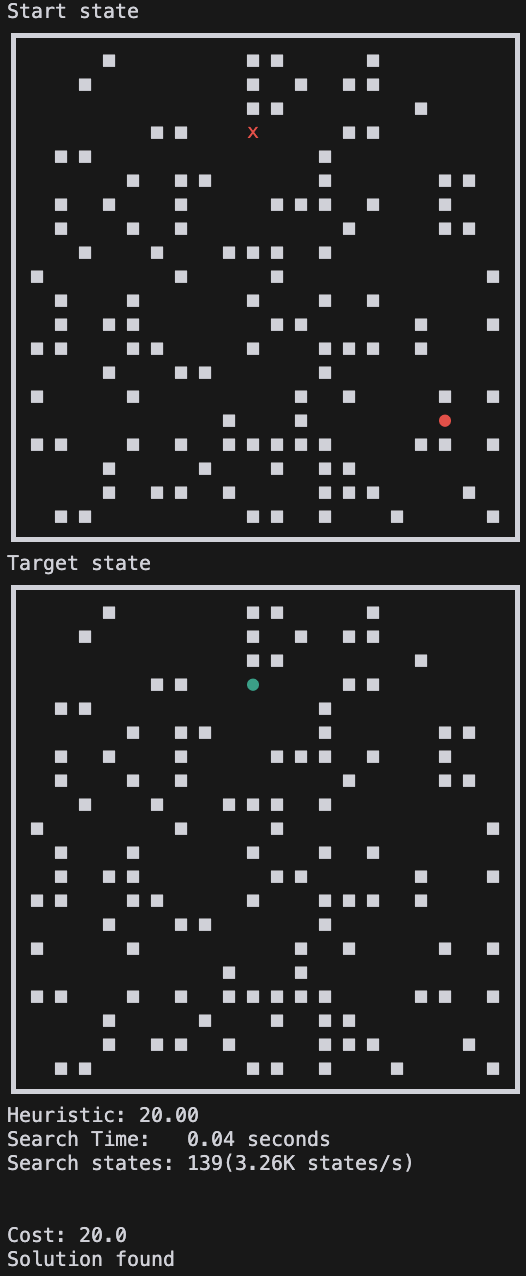
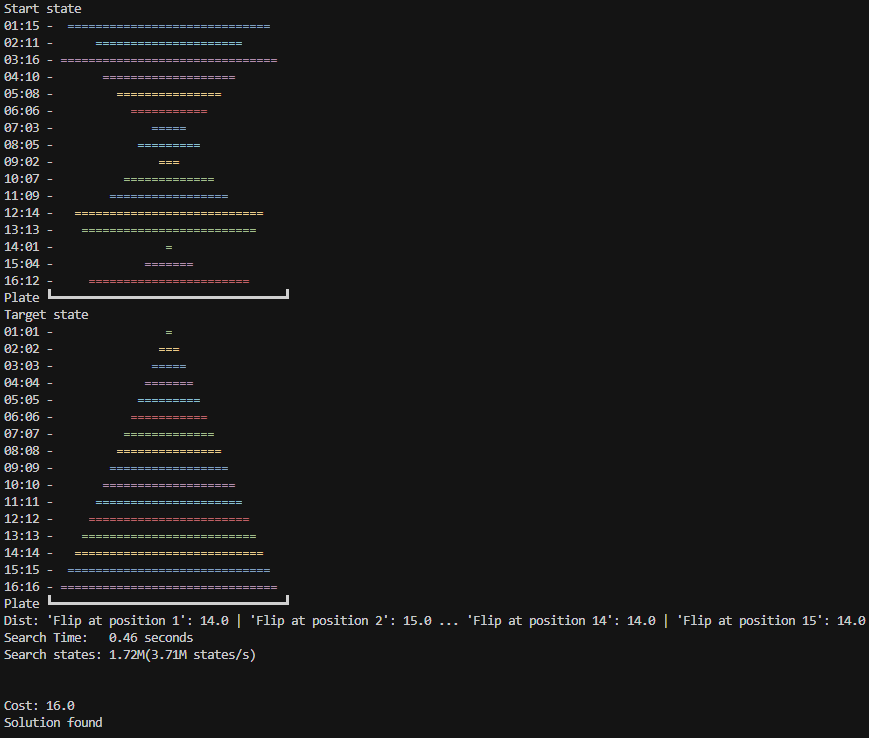
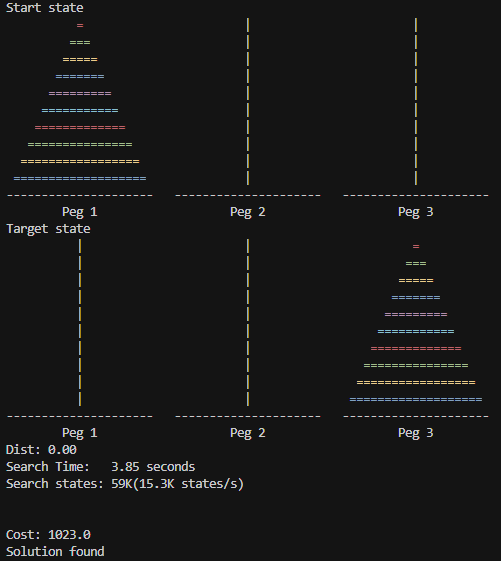
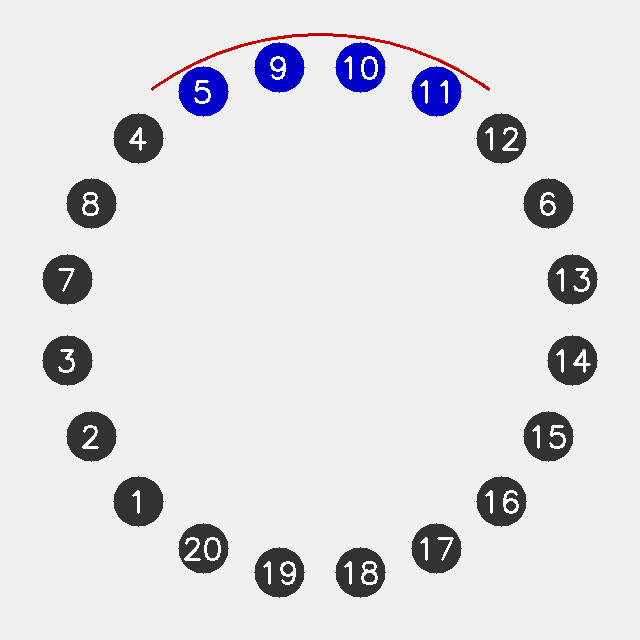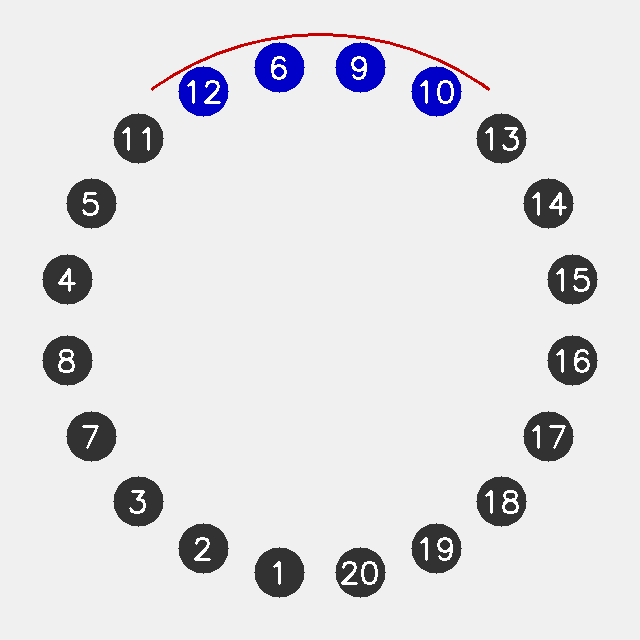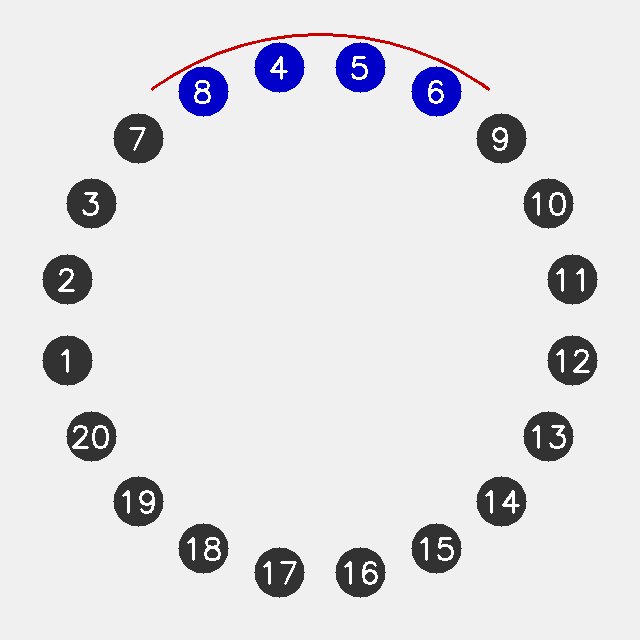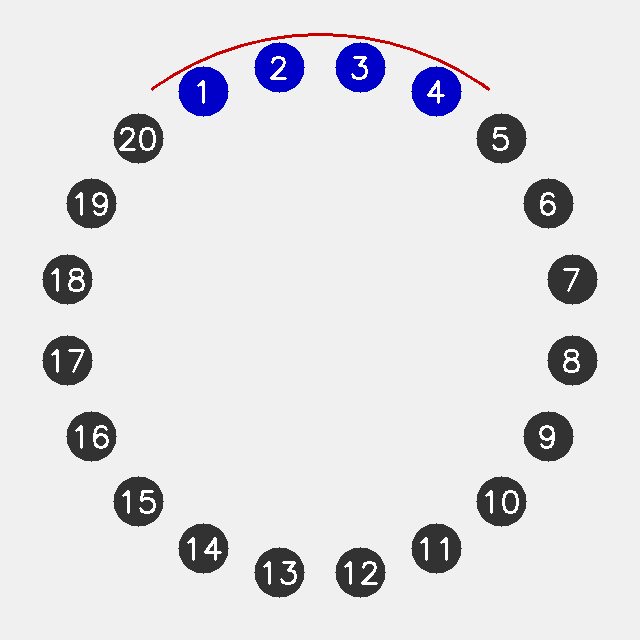
Puzzles
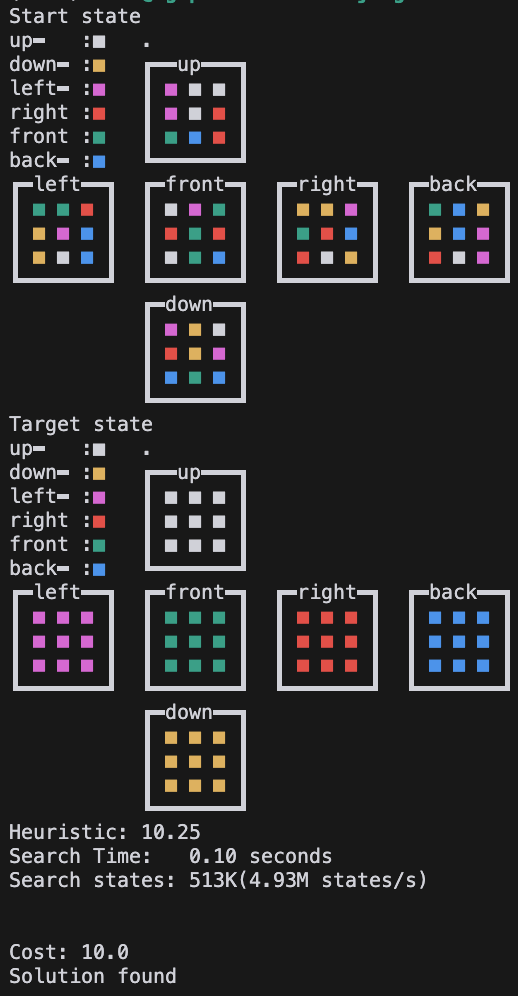
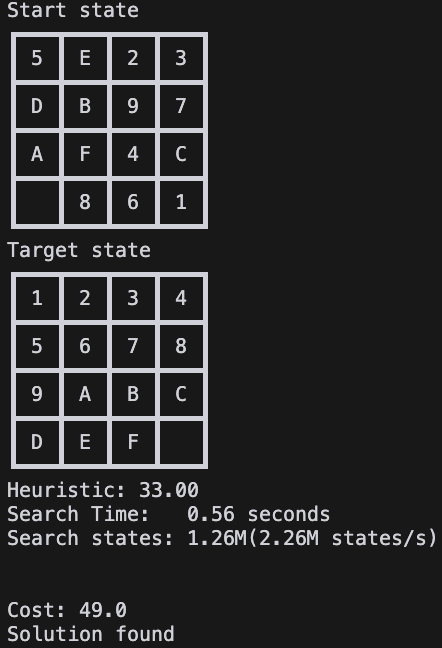
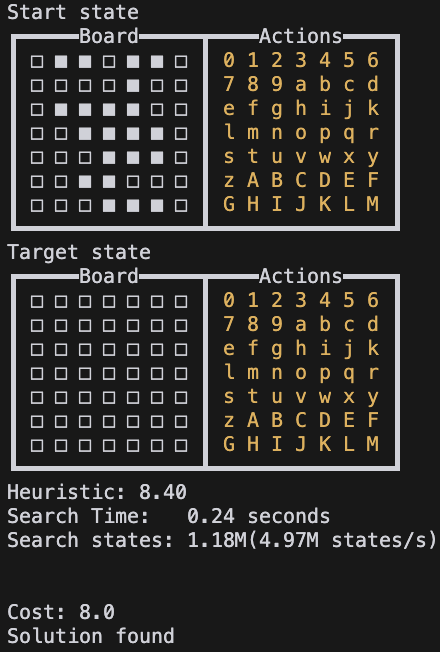
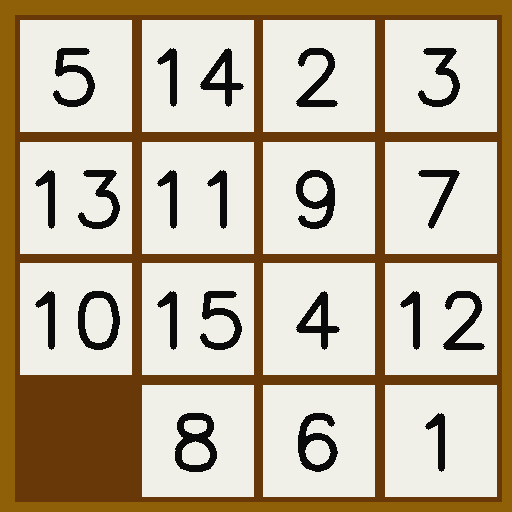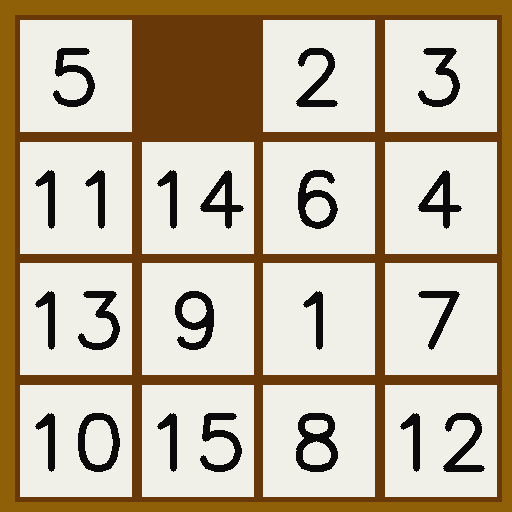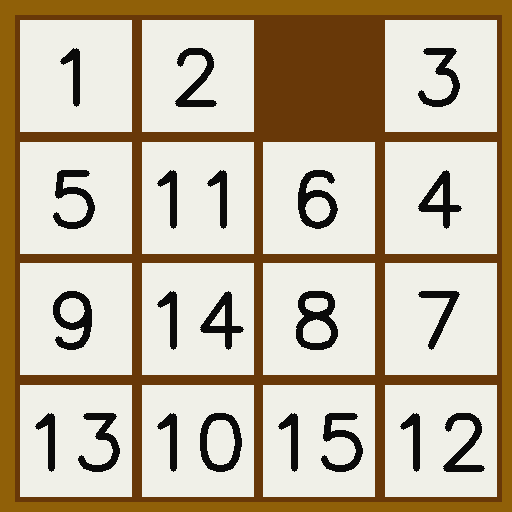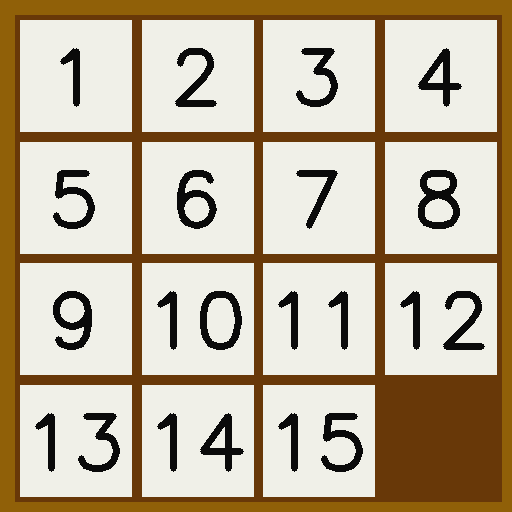
Target available puzzle
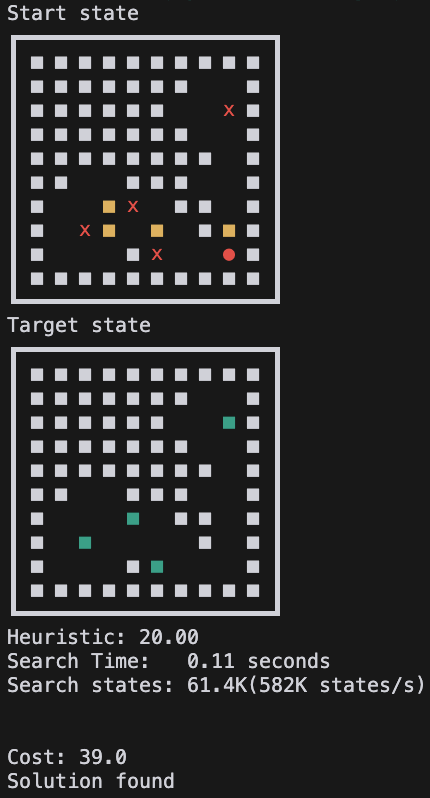
| Rubikscube | Slidepuzzle | Lightsout | Sokoban |
|---|---|---|---|
 |
 |
 |
 |
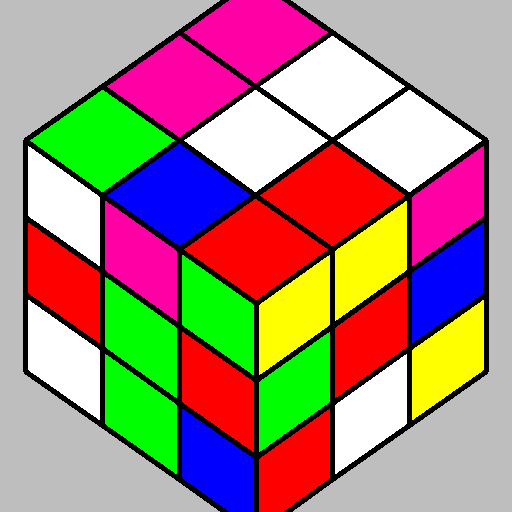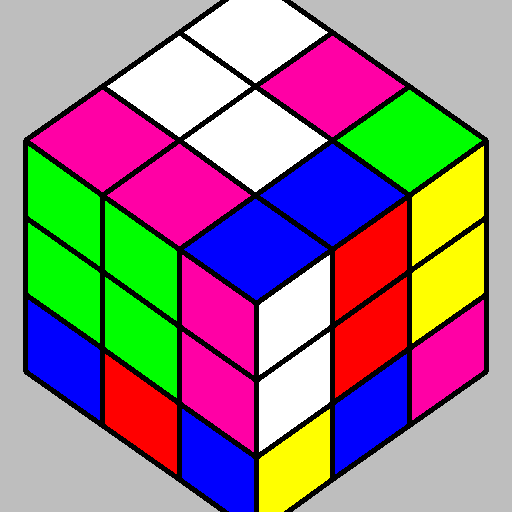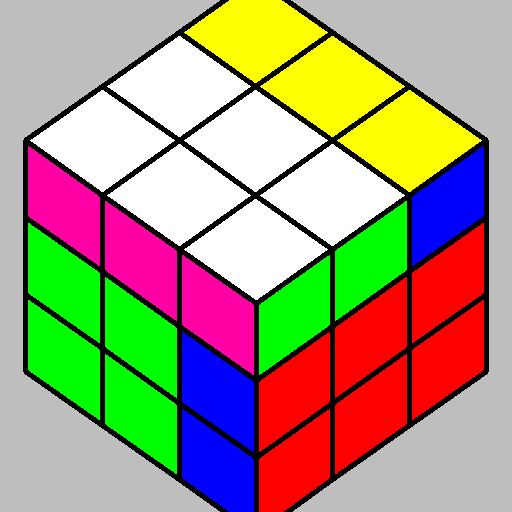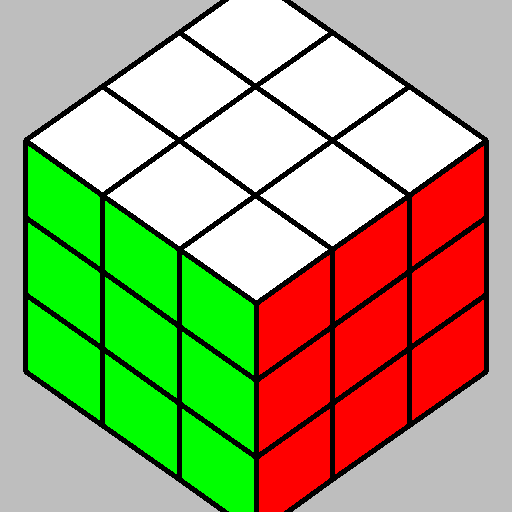 |
 |
 |
 |
| Maze | Pancake Sorting | Hanoi | TopSpin |
|---|---|---|---|
 |
 |
 |
 |
 |
 |
 |
 |
Target not available puzzle
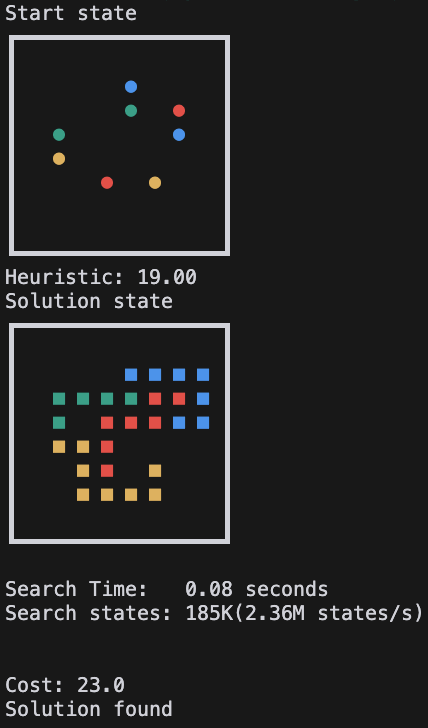
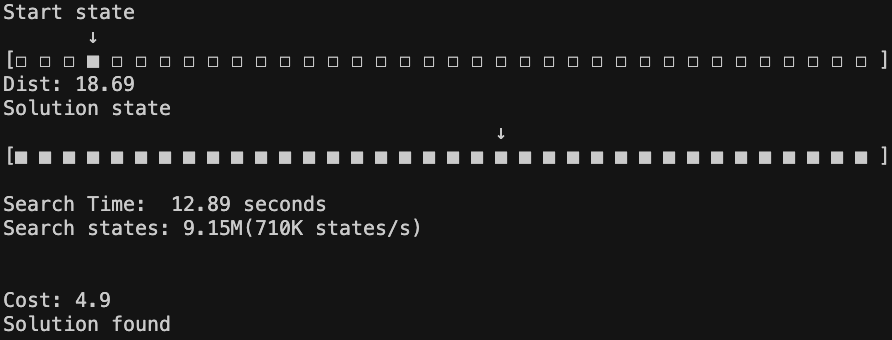
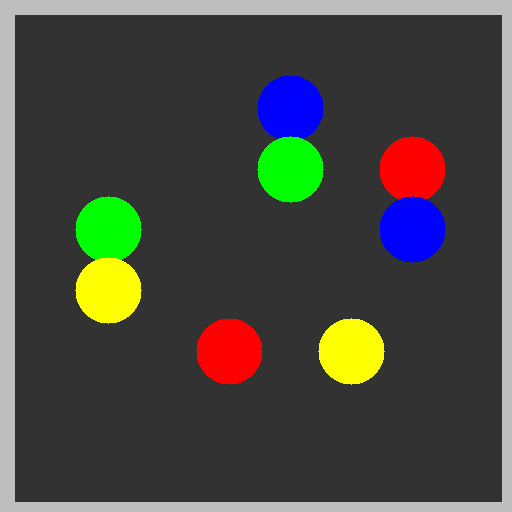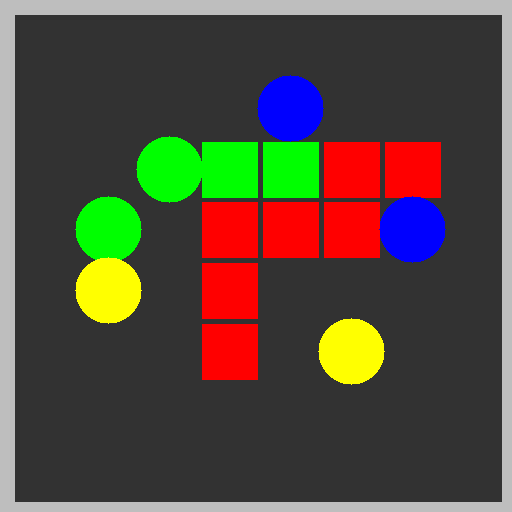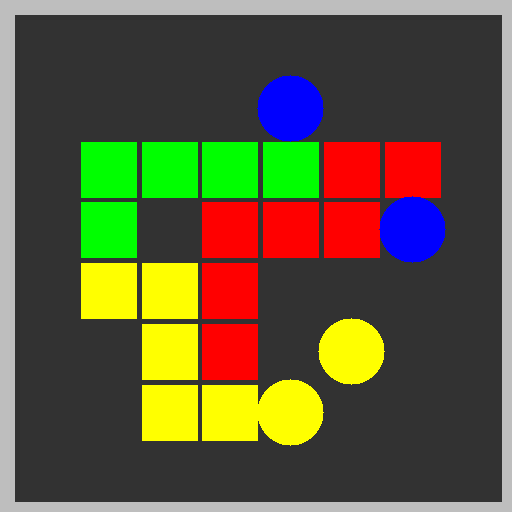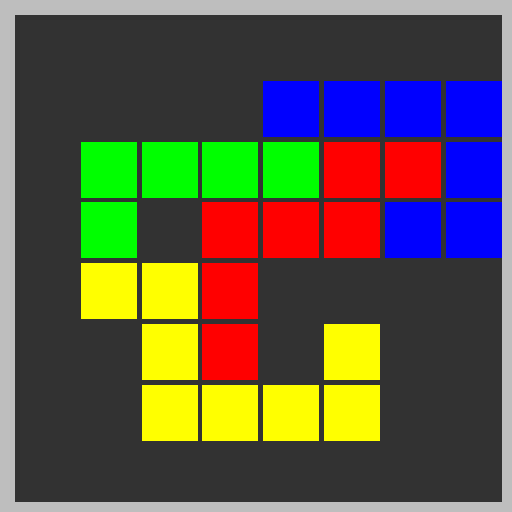
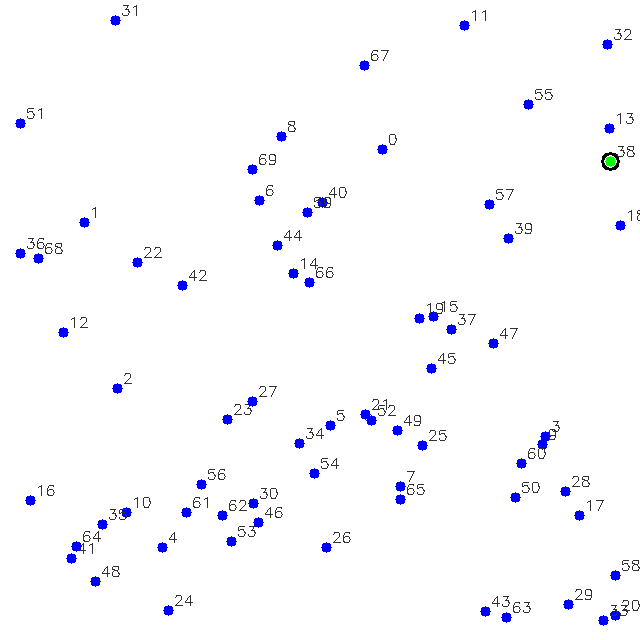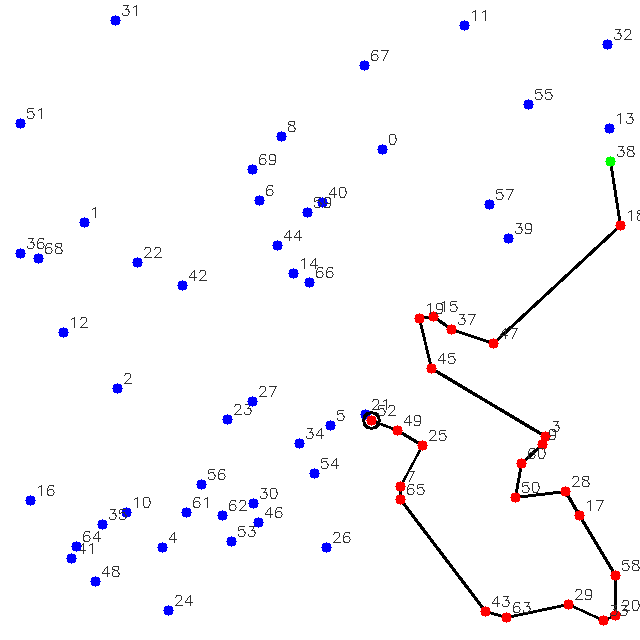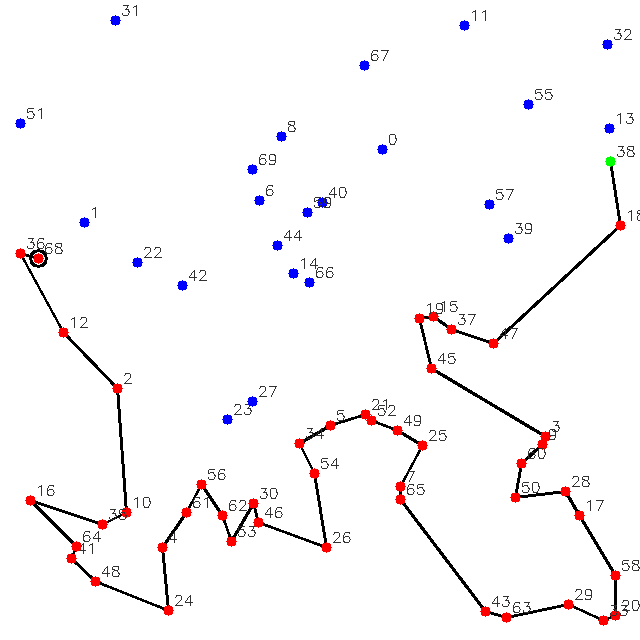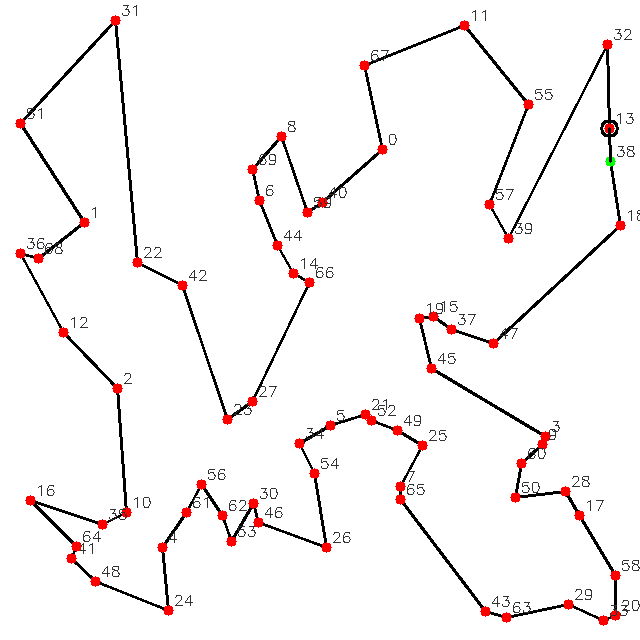
These types of puzzles are not strictly the kind that are typically solved with A*, but after some simple testing, it turns out that, depending on how the problem is defined, they can be solved. Furthermore, this approach can be extended to TSP and countless other COP problems, provided that with a good heuristic. The training method will need to be investigated further.
| Dotknot | TSP |
|---|---|
 |
 |
 |
 |
World Model Puzzle
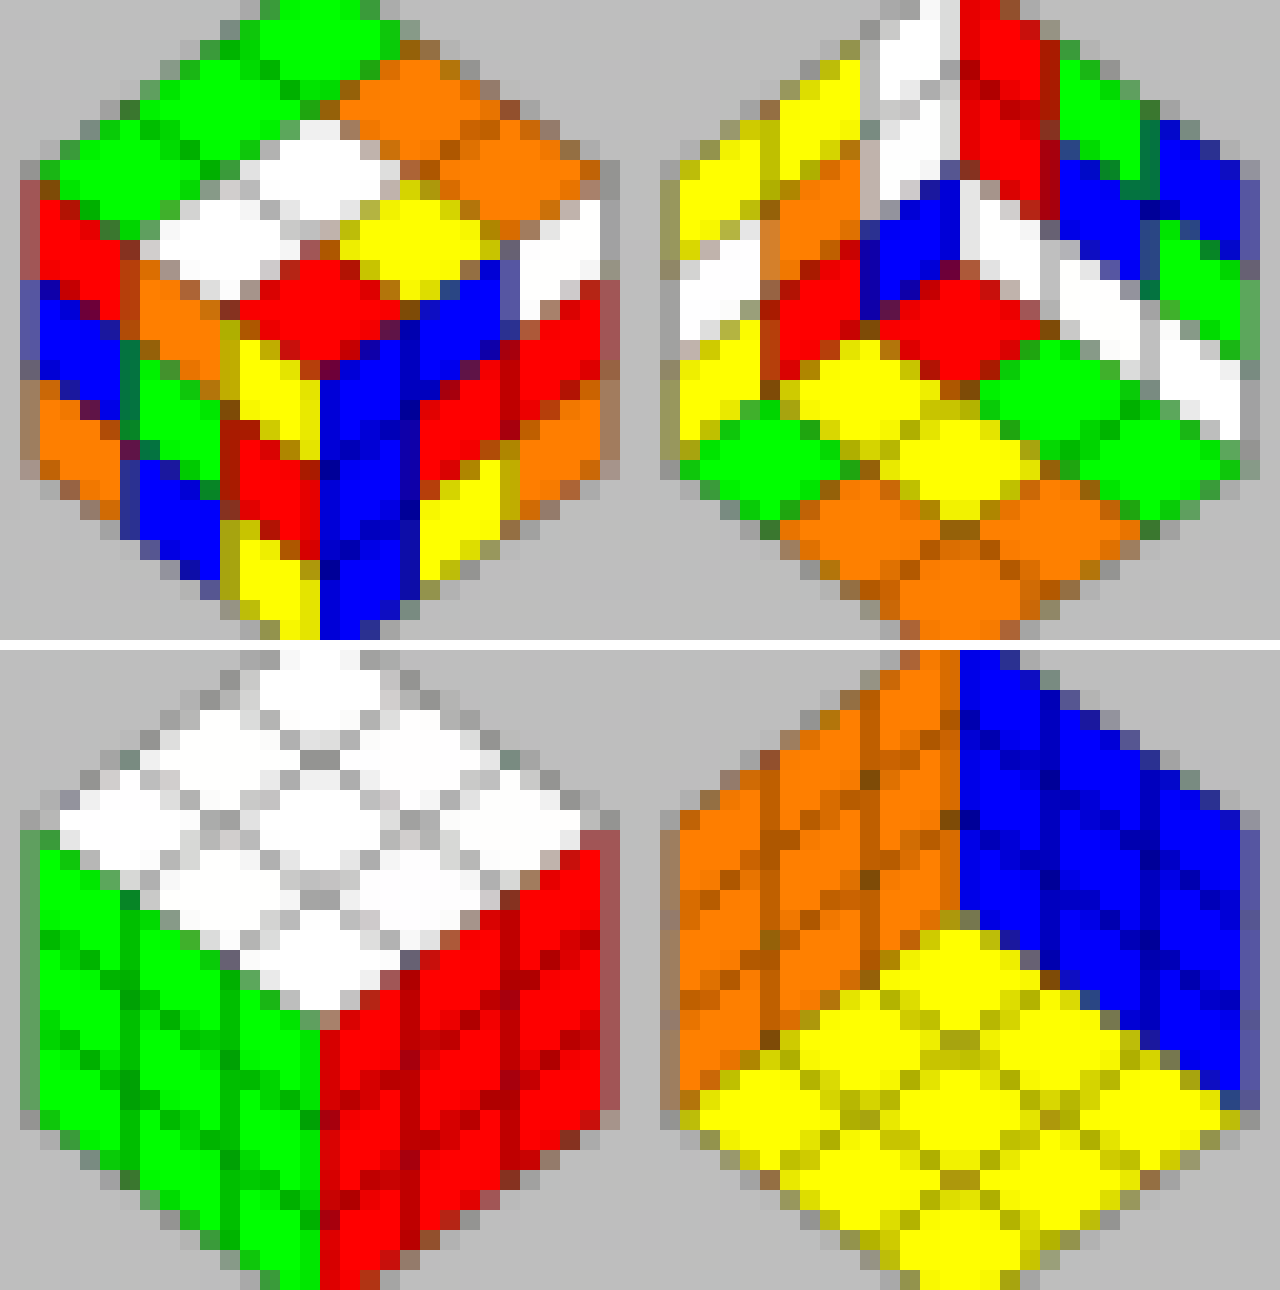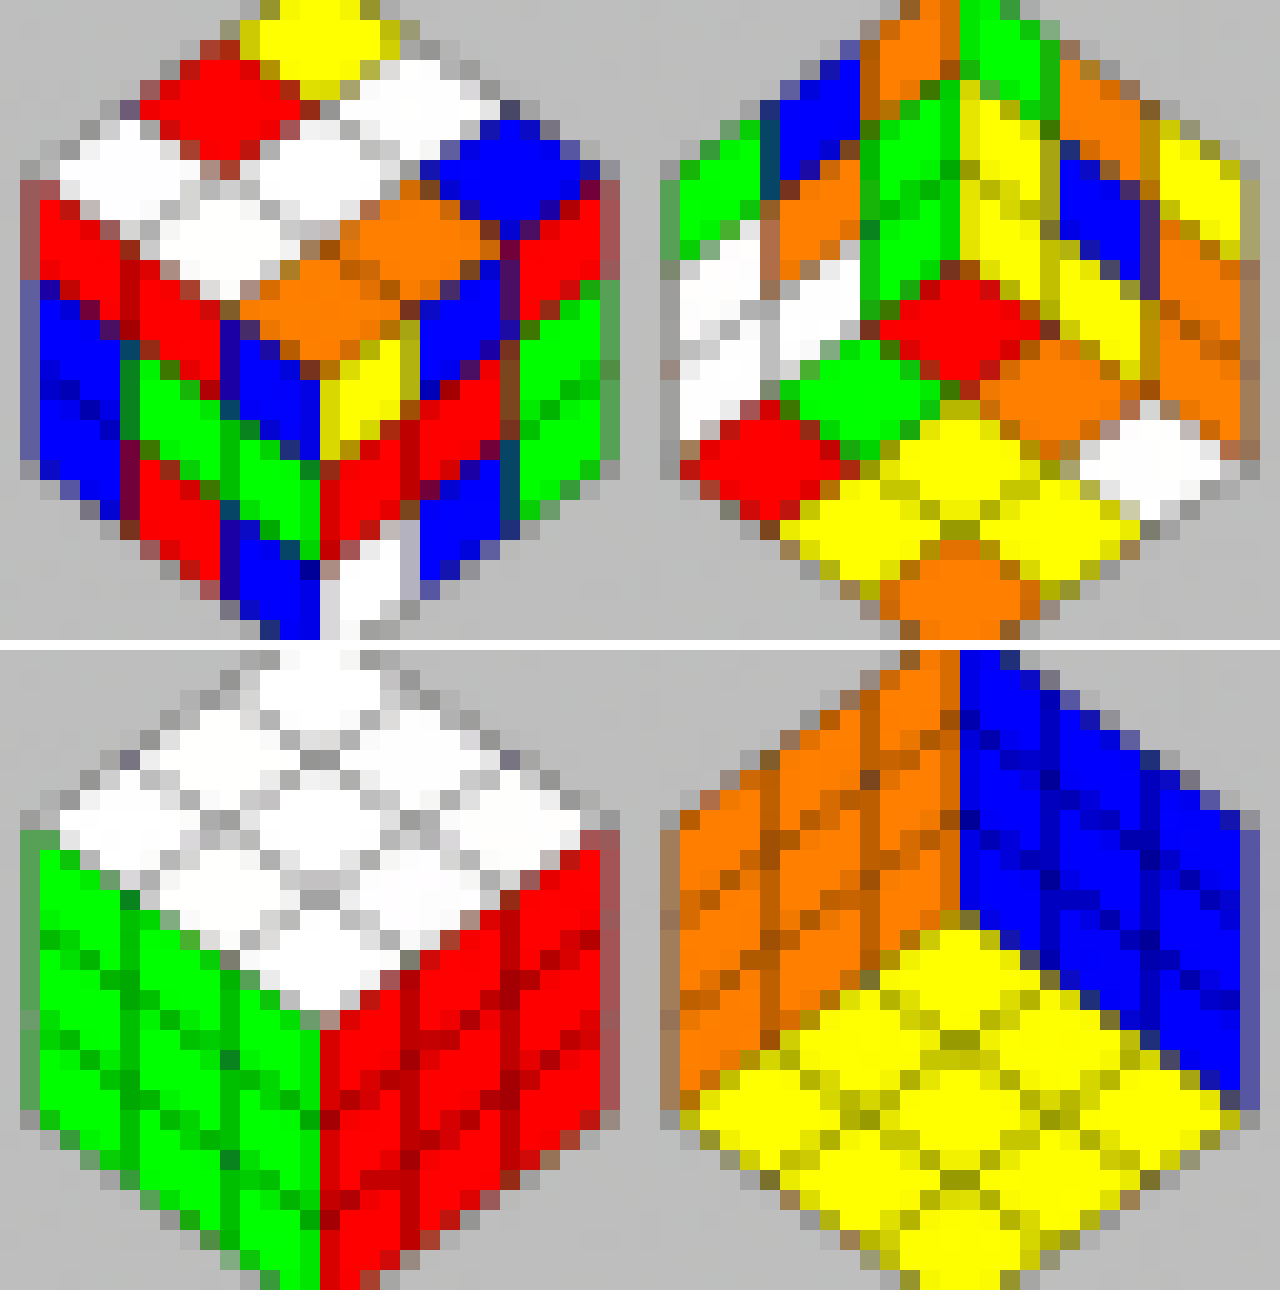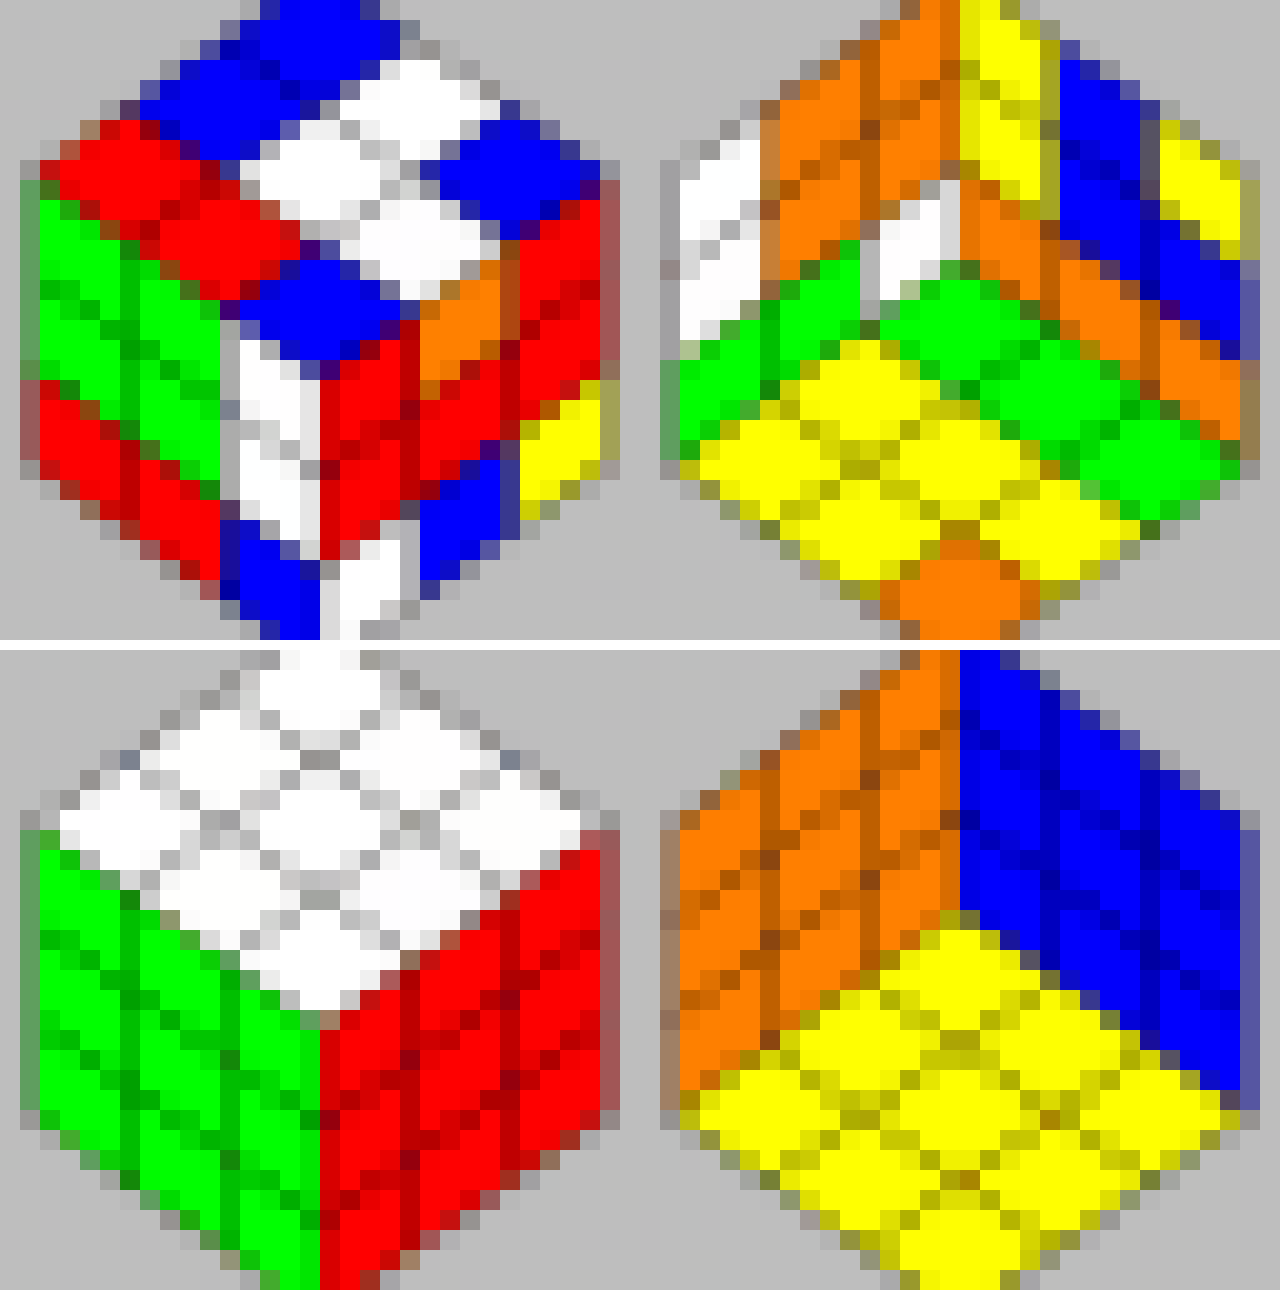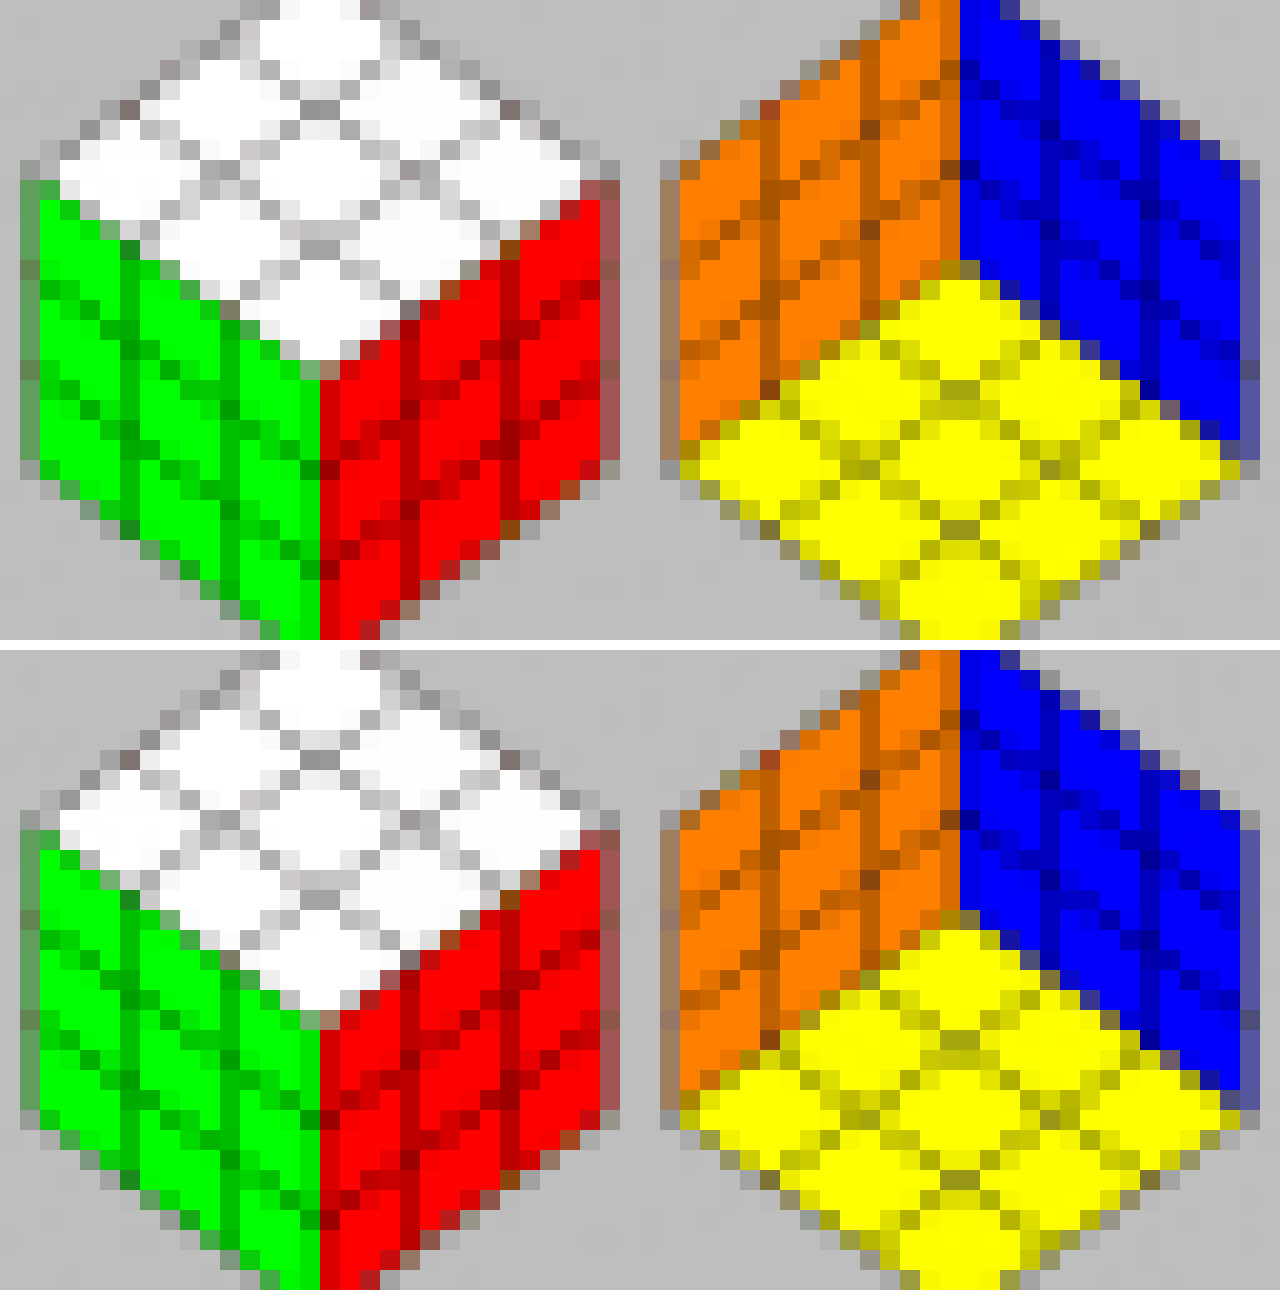
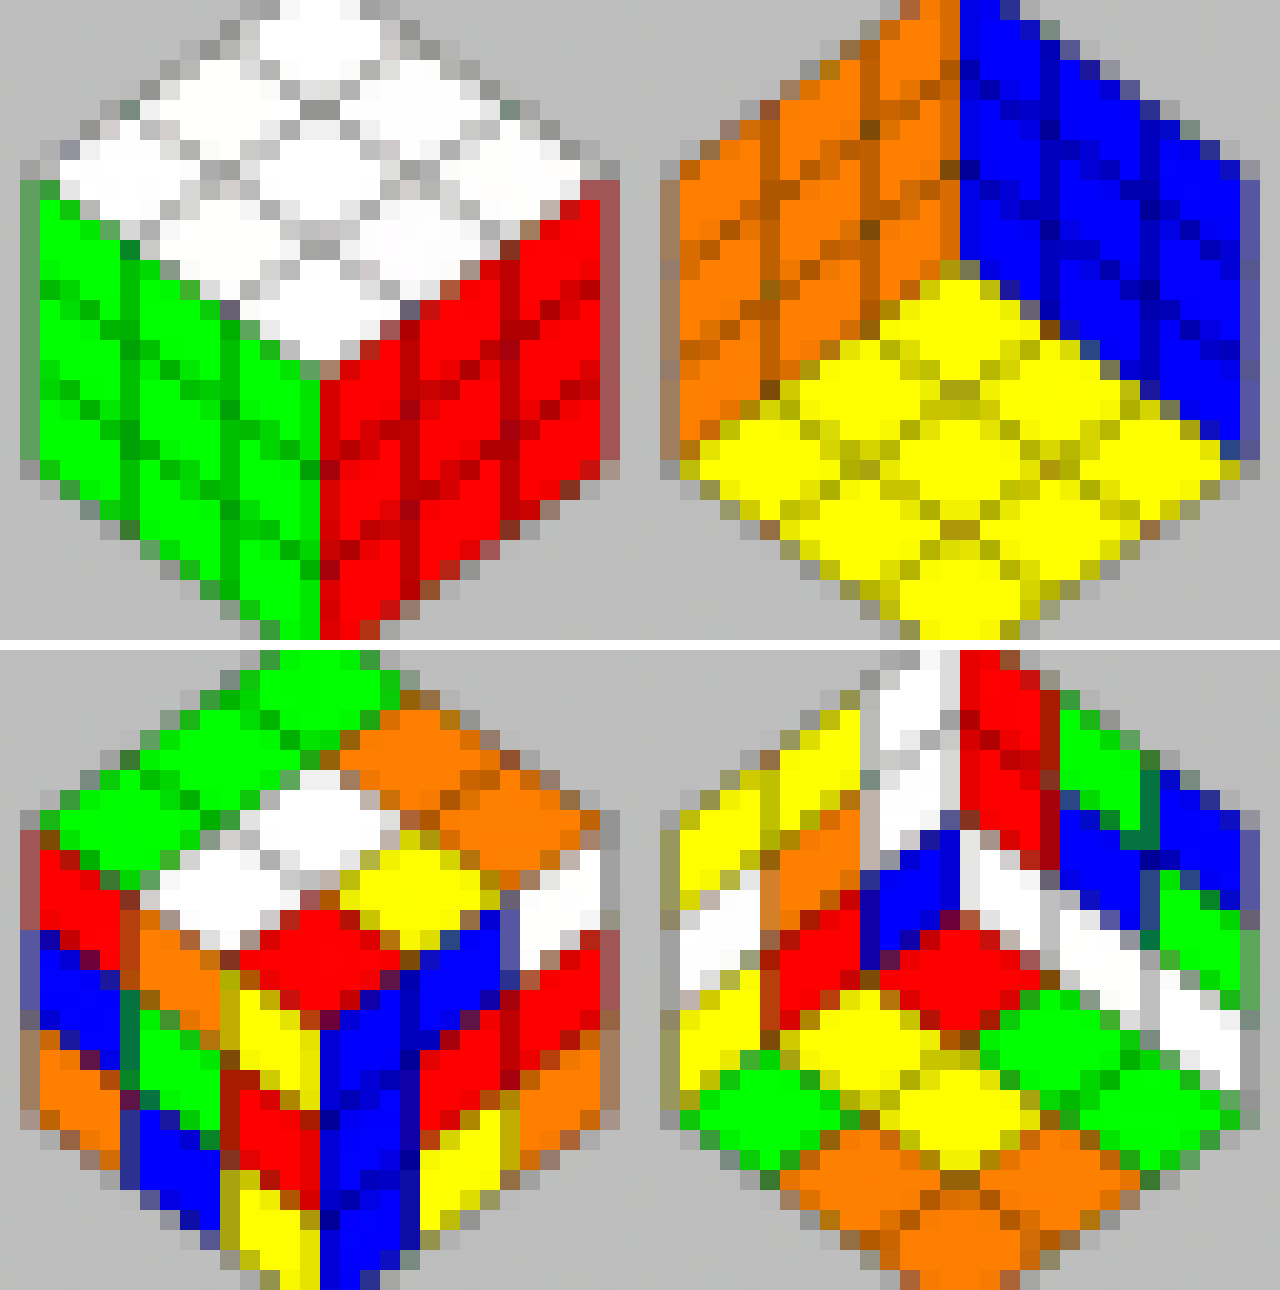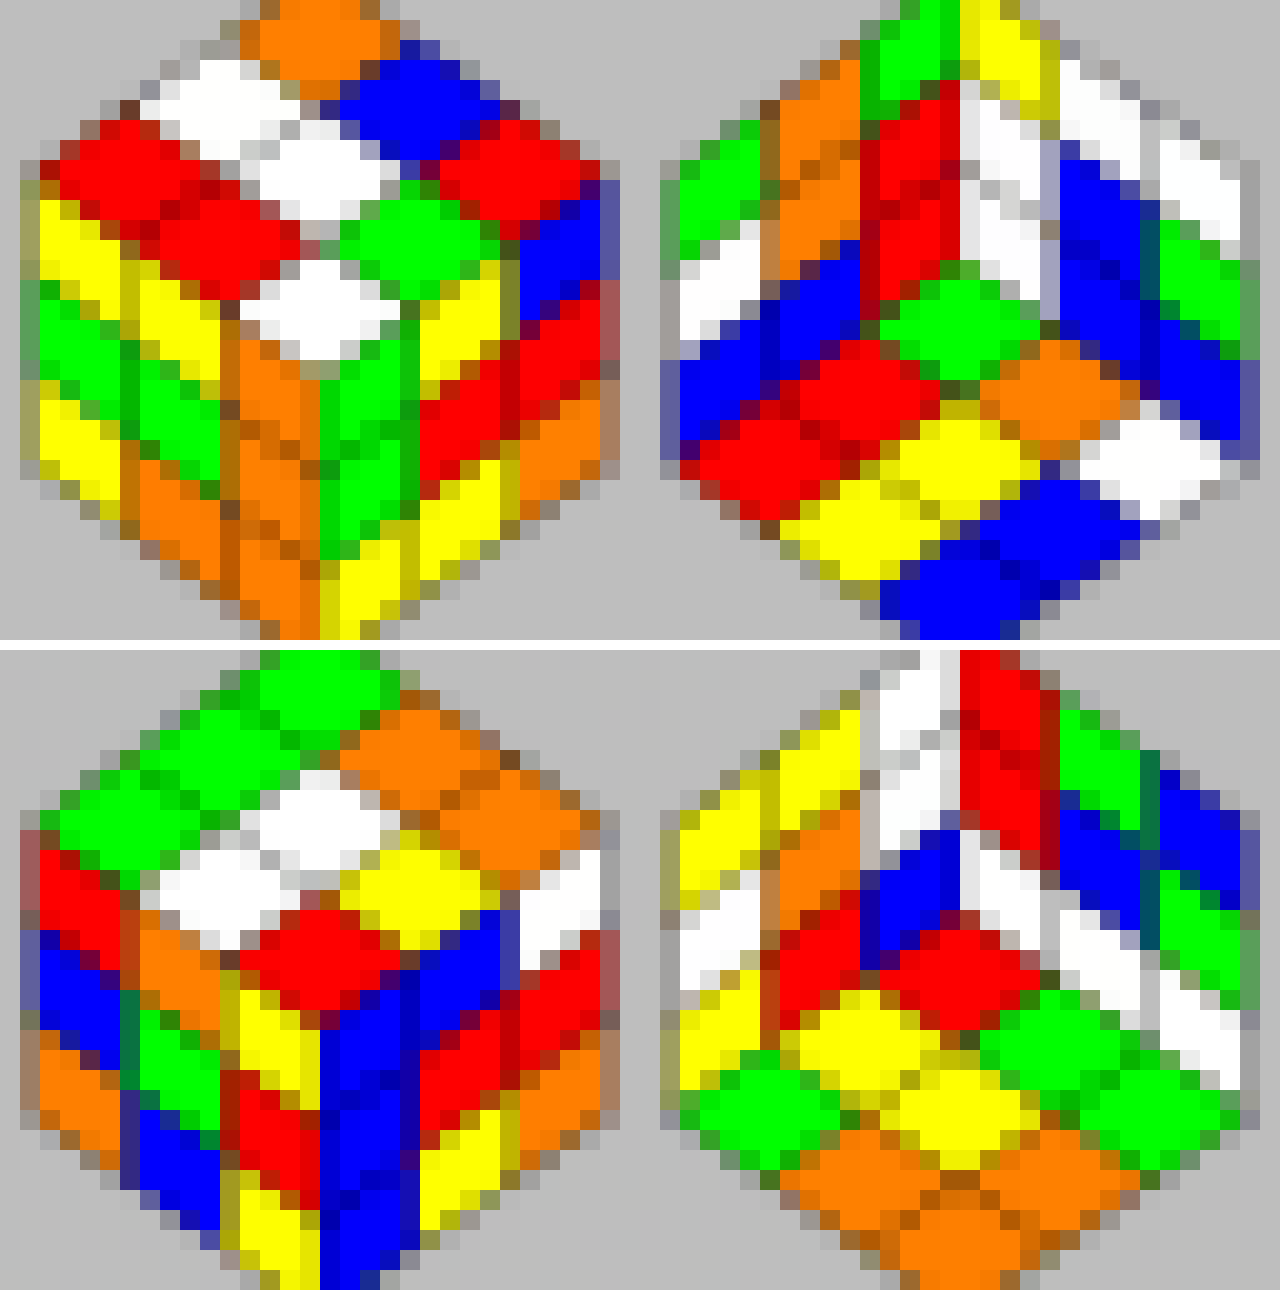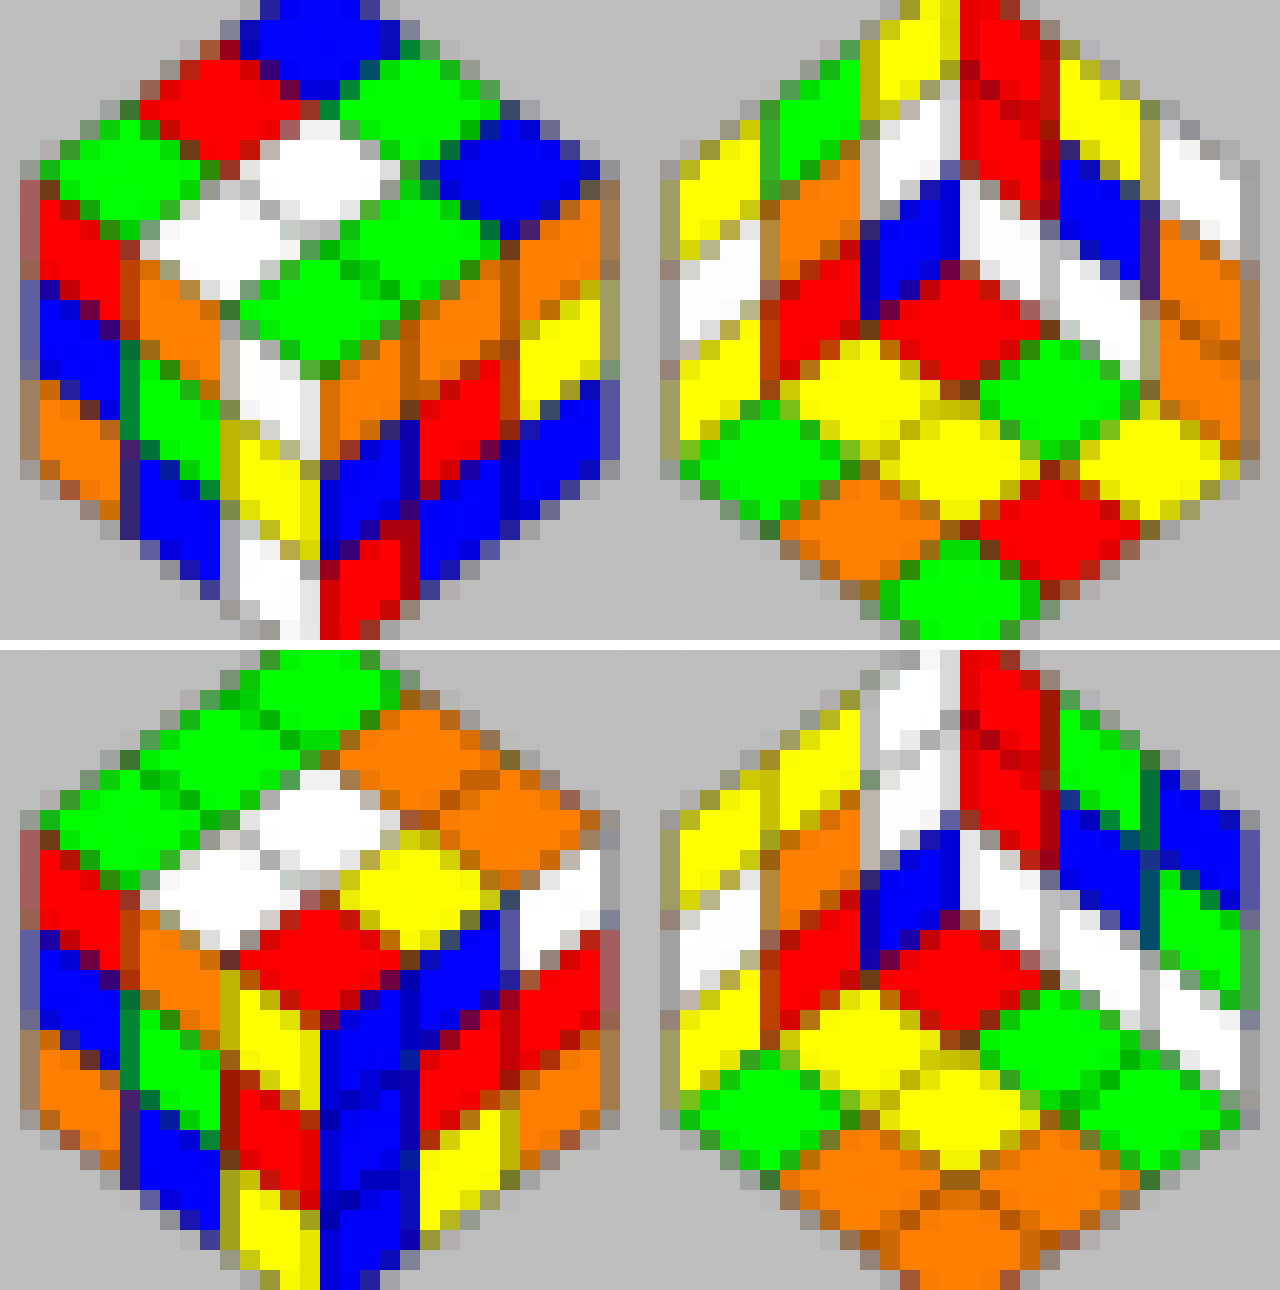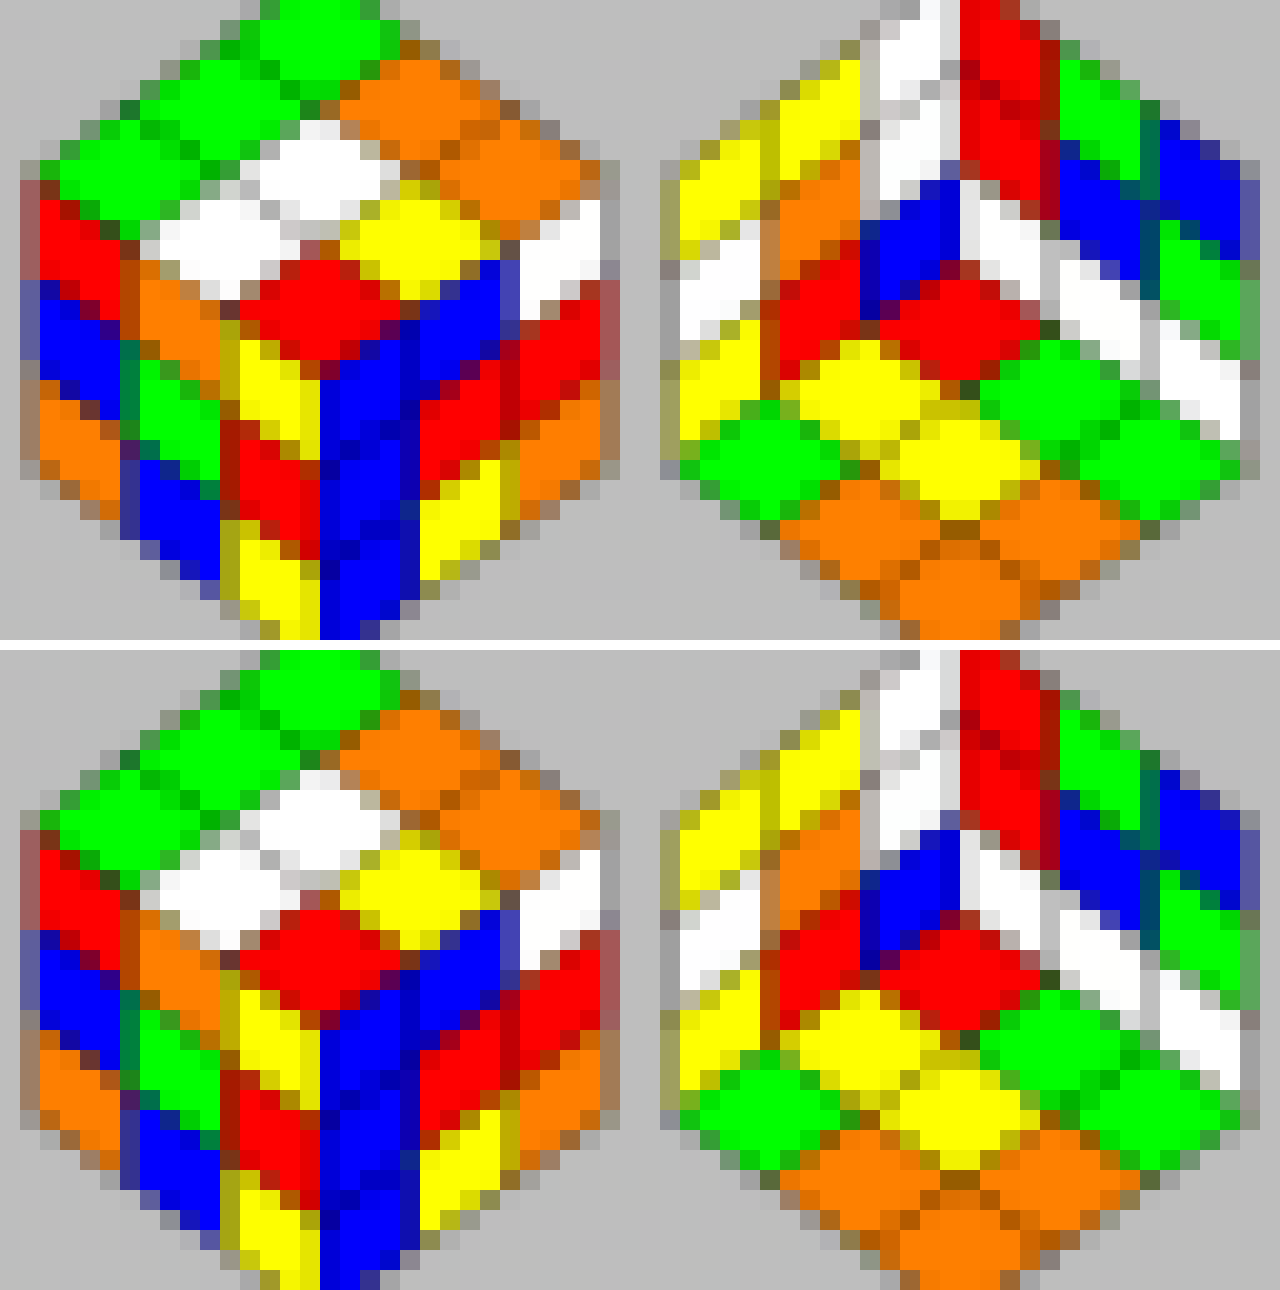
The world-model implementation and training APIs live in PuXle. JAxtar registers those models to perform A* & Q* search in the learned latent space, following "Learning Discrete World Models for Heuristic Search".
| Terminal View | Rubiks Cube | Rubiks Cube Reversed | Sokoban |
|---|---|---|---|
 |
 |
 |
 |
Citation
Please use this citation to reference this project.
@software{kyuseokjung2024jaxtar,
  title = {JA^{xtar}: GPU-accelerated Batched parallel A* & Q* solver in pure JAX!},
  author = {Kyuseok Jung},
  url = {https://github.com/tinker495/JAxtar},
  year = {2024},
}
Explorer des projets similaires
tensorflow/tensorflow
Un framework open source d'apprentissage automatique pour tous
201,584 étoileshuggingface/transformers
🤗 Transformers : le framework de définition de modèles pour les modèles d'apprentissage automatique de pointe en texte, vision, audio et multimodal, pour l'inférence et l'entraînement.
168,943 étoilesAUTOMATIC1111/stable-diffusion-webui
Interface web de Stable Diffusion
165,303 étoilesComfy-Org/ComfyUI
La GUI, l'API et le backend les plus puissants et modulaires pour les modèles de diffusion, avec une interface de graphes et de nœuds. Le moteur d'inférence local le plus rapide au monde.
146,622 étoiles