
nace-ai/kapitsa
nace-ai/kapitsa has 790 GitHub stars and 105 forks. Star changes are not measured yet. Last checked 2026-11-14 02:32 UTC. Last push 2026-11-13.
What you can do
- 🏆 Fastest decode in 33 of 38 Mac and model pairs: 351 tok/s on Qwen3.6 35B (M5 Max) (numbers, how)
- 🤖 Runs your coding agent: kapitsa claude, codex, opencode, pi, hermes, aider, goose, copilot
- 🗄️ Big models on small Macs: 180B at 61 tok/s on a 48 GB M5 Pro
- 💾 No waiting after a restart: a 16K follow-up starts in 0.16 s, not 17 s, on an M4 Pro (numbers)
Progression mesurée des étoiles
- in 24h
- Historique en cours
- in 7 days
- Historique en cours
- in 15 days
- Historique en cours
- in 1 month
- Historique en cours
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
À propos
Blazing fast Apple Silicon inference engine optimized for Qwen & Nemotron. OpenAI + Anthropic API compatible. Built by folks from nace.ai
Outils de développementREADME.md
Original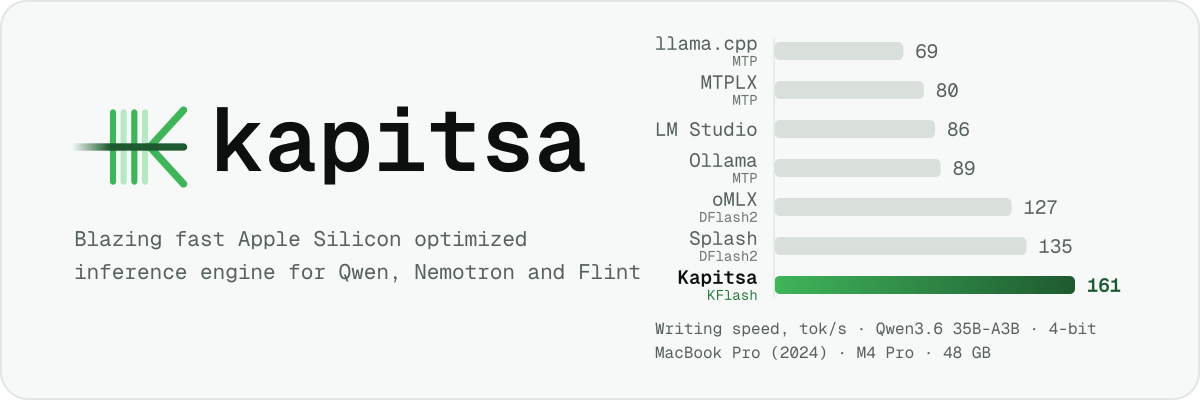
Kapitsa is an inference engine for Apple silicon that runs Qwen, Nemotron and Recursive's Flint models locally, built for coding agents. It starts opencode, Claude Code, Codex, Pi, Hermes, aider or Goose on a local model, and serves OpenAI and Anthropic APIs.
Quickstart · What's new · Features · Benchmarks · CLI · Models · How KFlash works · Docs · Xcode 26 guide · 日本語
Quickstart
Requirements: a Mac with Apple silicon (M1 or newer) and macOS 14 Sonoma or later.
Limits: Apple silicon only: no Linux or Windows. Flint, the four text-only Nemotrons, Clover, Ornith and the 35B's 16gb build read text only, not images (which models read images).
brew install nace-ai/tap/kapitsa
# or: curl -fsSL https://raw.githubusercontent.com/nace-ai/kapitsa/main/install.sh | bash
kapitsa opencode --model 35b # also: claude, codex, pi
On a 16-24 GB Mac use --model 9b, or 4b for the quickest replies.
🔥 What's new
- [2026/11] 🎯 Nace quants: the 4B, 9B, 27B and 35B-A3B downloads are closer to the original model than the packs they replace, at the same size (numbers).
- [2026/11] ⚡ Qwen3.8-Flash-Next 180B writes 6% faster on an M5 Max, with the same tokens: greedy decode 107.3 → 113.9 tok/s after three verify-kernel changes (numbers).
- [2026/10] 🍀 DiffuSpace's Clover-35B-A3B, a block-diffusion MoE, writes at 304 tok/s on an M5 Max:
kapitsa serve --model clover(numbers, how). - [2026/10] 🗄️ A 180B model runs on a 48 GB Mac: Qwen3.8-Flash-Next's Q2_0 experts stream from the SSD (numbers).
- [2026/10] 🏆 The fastest decode in 33 of the 38 model and Mac pairs measured against nine engines (poster).
Features
- 🏆 Fastest decode in 33 of 38 Mac and model pairs: 351 tok/s on Qwen3.6 35B (M5 Max) (numbers, how)
- 🤖 Runs your coding agent:
kapitsa claude,codex,opencode,pi,hermes,aider,goose,copilot - 🗄️ Big models on small Macs: 180B at 61 tok/s on a 48 GB M5 Pro
- 💾 No waiting after a restart: a 16K follow-up starts in 0.16 s, not 17 s, on an M4 Pro (numbers)
- 🎯 Closer to the original: Nace quants for the Qwen 4B, 9B, 27B and 35B-A3B, closer than the 4-bit packs they are compared with at the same size (numbers)
- 🔌 OpenAI and Anthropic APIs: plus a chat page, on
127.0.0.1:8000 - 🧠 GPU and Neural Engine together: prefill hands part of its work to the Neural Engine
- 🖥️ Several Macs, one model: a Mac that can't hold a model uses one that can (how)
Nace quants
Downloads closer to the original model, at the same size. Nace quants are our quantization for MLX packs. 4b, 9b, 27b and 35b use them.
| 4-bit | Compared with | KL from bf16 (lower is closer) | GSM8K, 1,319 questions |
|---|---|---|---|
| 4B | lmstudio-community | 0.070 → 0.048 | 0.914 → 0.923 |
| 9B | lmstudio-community | 0.081 → 0.037 | 0.927 → 0.944 |
| 27B | the plain 4-bit pack (27b:4bit) |
0.054 → 0.035 | 0.950 → 0.953 |
| 35B-A3B | MTPLX | 0.096 → 0.059 | 0.948 → 0.952 |
The 9B row is the legacy pack (9b on M3 and M4); on M5 and newer 9b is Nace Q4, which these numbers do not cover. How it was measured · every run
Drex decision models
The Drex decision models run through kapitsa-systemone. These commands import the v1 Q8_0 GGUF to Kapitsa's affine 8-bit layout and need Kapitsa v0.2.25 or later (an affine Q4 checkpoint is in the guide):
brew install nace-ai/tap/kapitsa
kapitsa import /path/to/drex-max-v1-Q8_0.gguf --name drex-max-v1
kapitsa-drex-pointer /path/to/drex-max-v1-Q8_0.gguf ~/.cache/kapitsa/models/drex-max-v1/pointer.bin
kapitsa-systemone --model ~/.cache/kapitsa/models/drex-max-v1 --port 8000 --context 2048
The guide has the request, the memory a longer context needs and the encoding.
Benchmarks
Kapitsa has the fastest decode in 33 of the 38 model and Mac pairs measured against nine engines (how each number was measured).
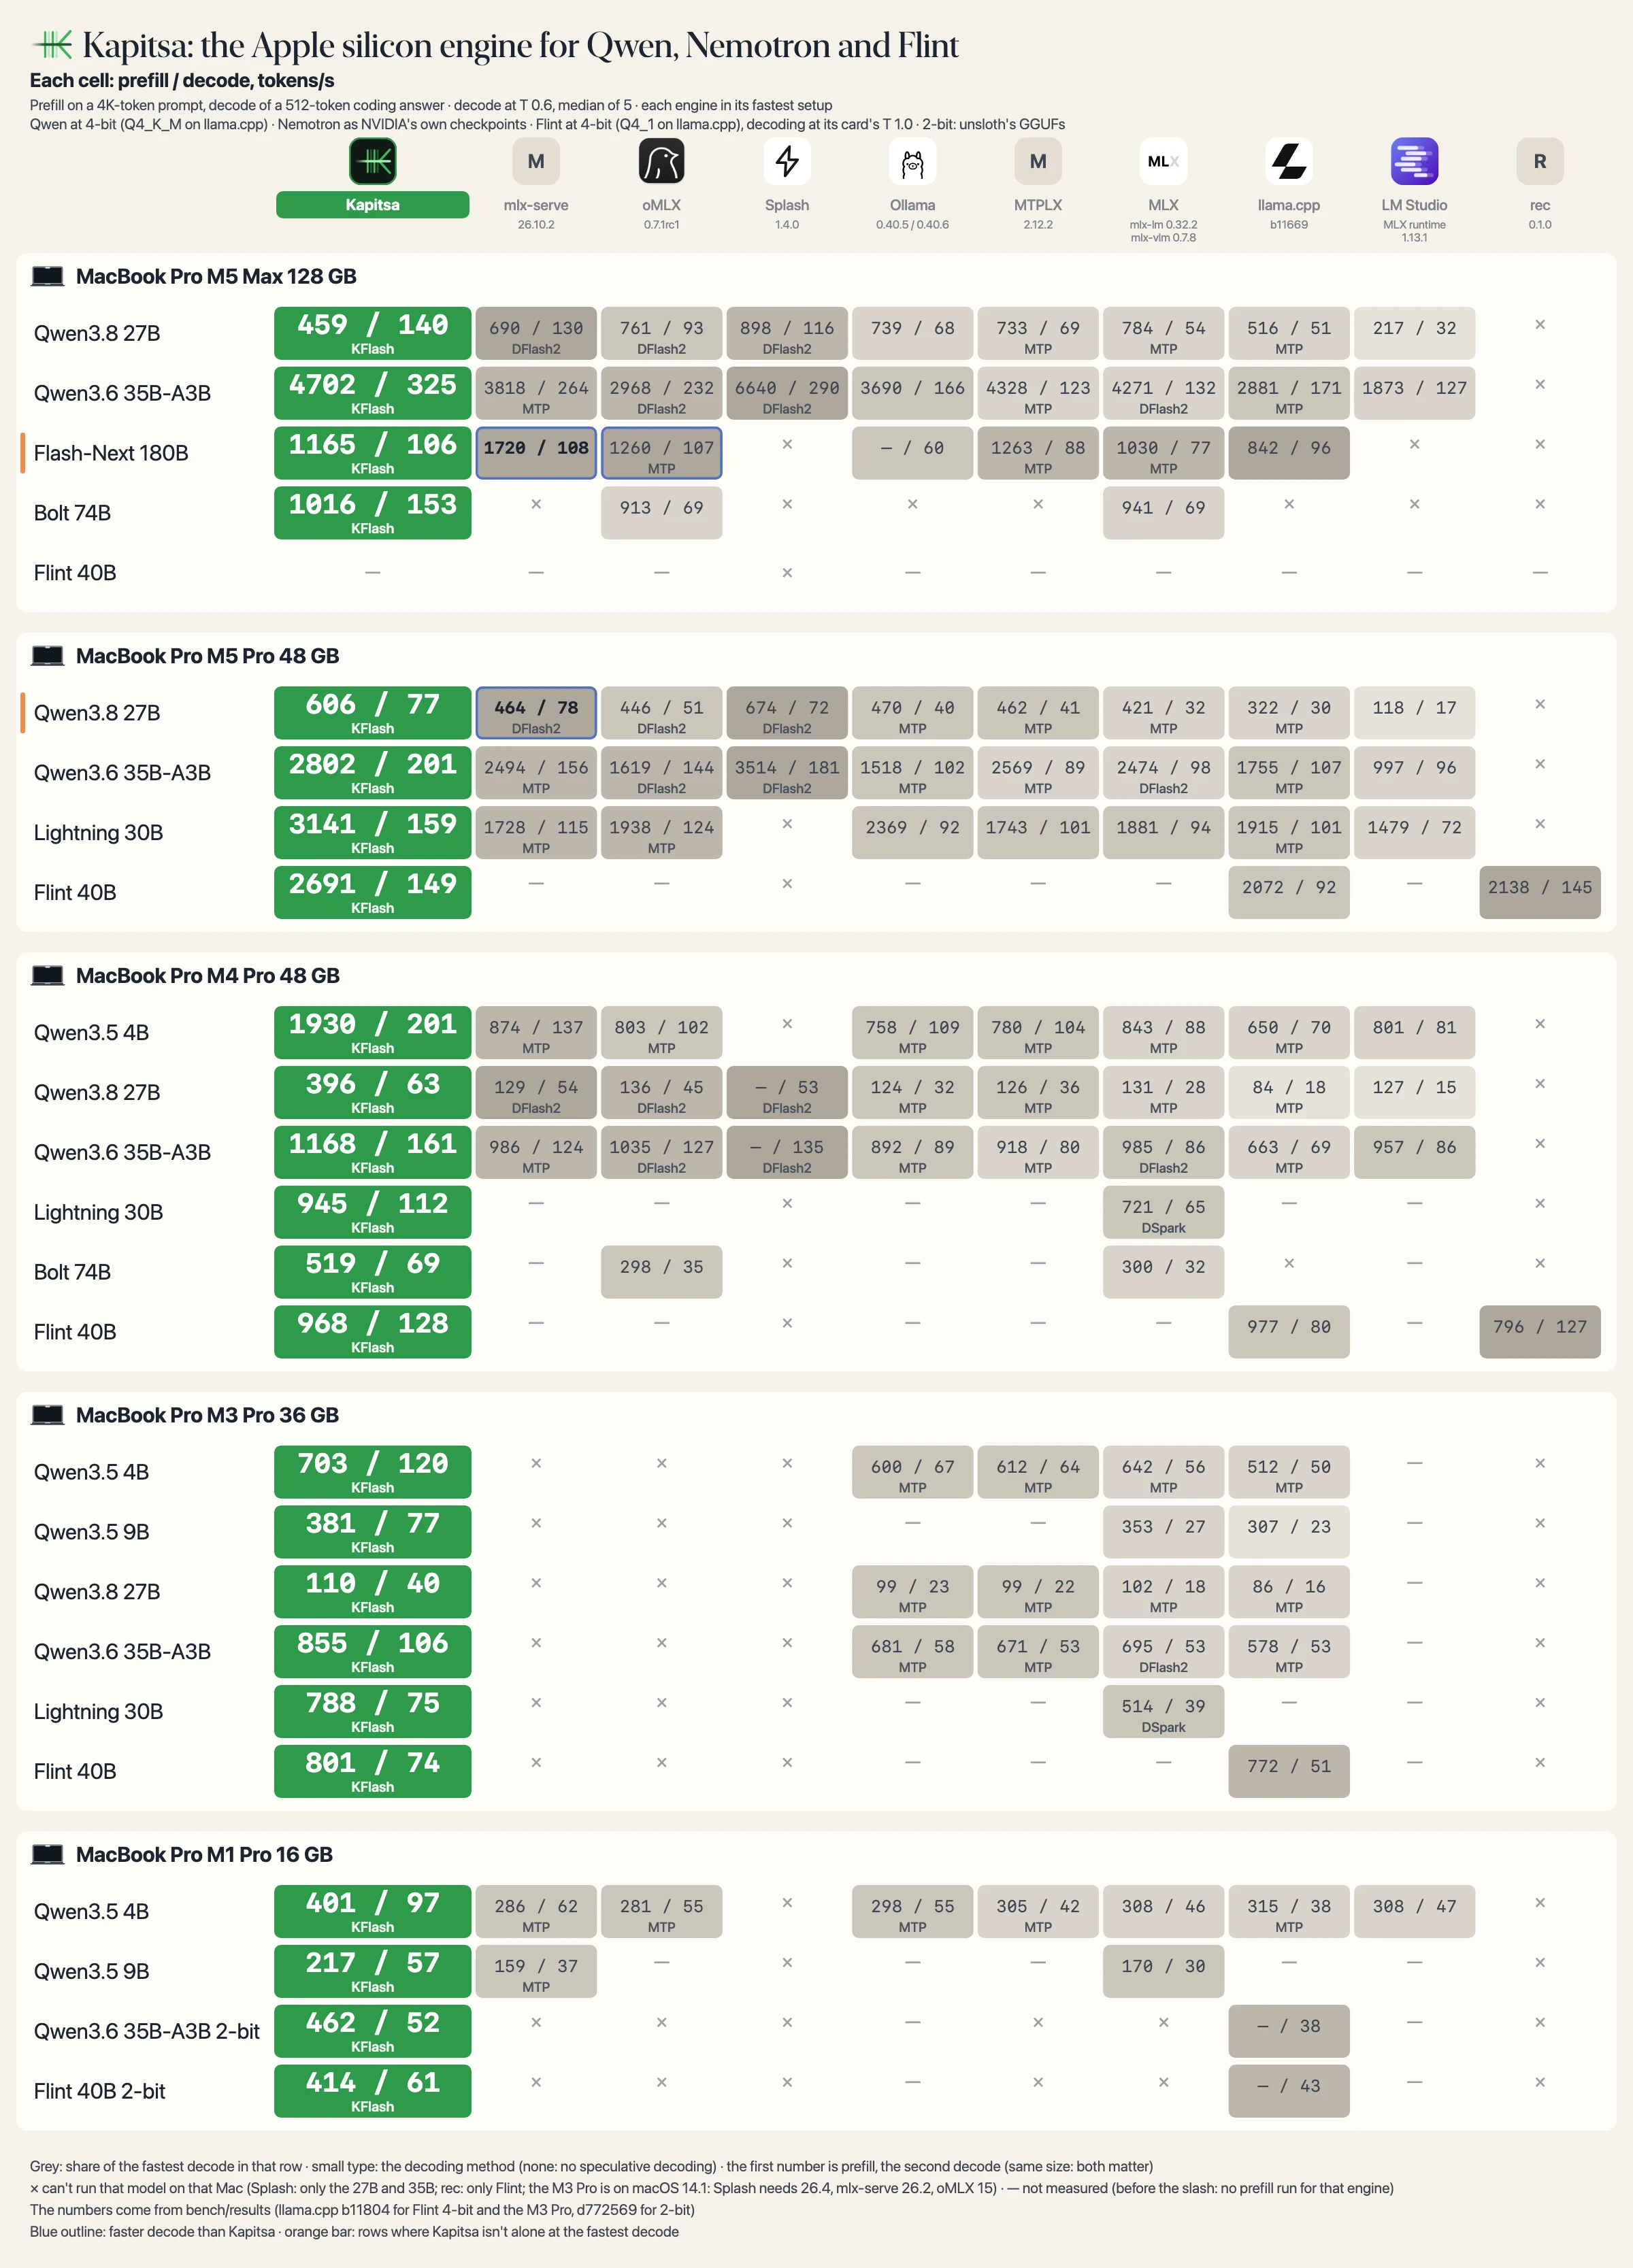
Each cell reads prefill / decode in tokens per second, from a 4K-token prompt and a 512-token answer at T 0.6 (Flint at its card's T 1.0). The M5 Pro's Flash-Next 180B Q2 row is a 256-token answer at T 0 on that run's own 4,074-token prompt, and its Kapitsa column is Kapitsa with KFlash against plain Splash 1.5.0: a tie, the two engines' ranges overlap (record). Footnotes, run dates and flags: docs/benchmarks.md.
The poster's numbers, and the models it leaves out, are in each Mac's table under Speed on each Mac. Every recorded run, with its Mac, model, prefill and decode speed, is in the benchmark table. Measure your Mac: kapitsa bench --submit adds it to the community results and the community leaderboard. Another engine faster on your Mac? kapitsa bench compare ranks every engine you have installed, and --report writes a Markdown report.
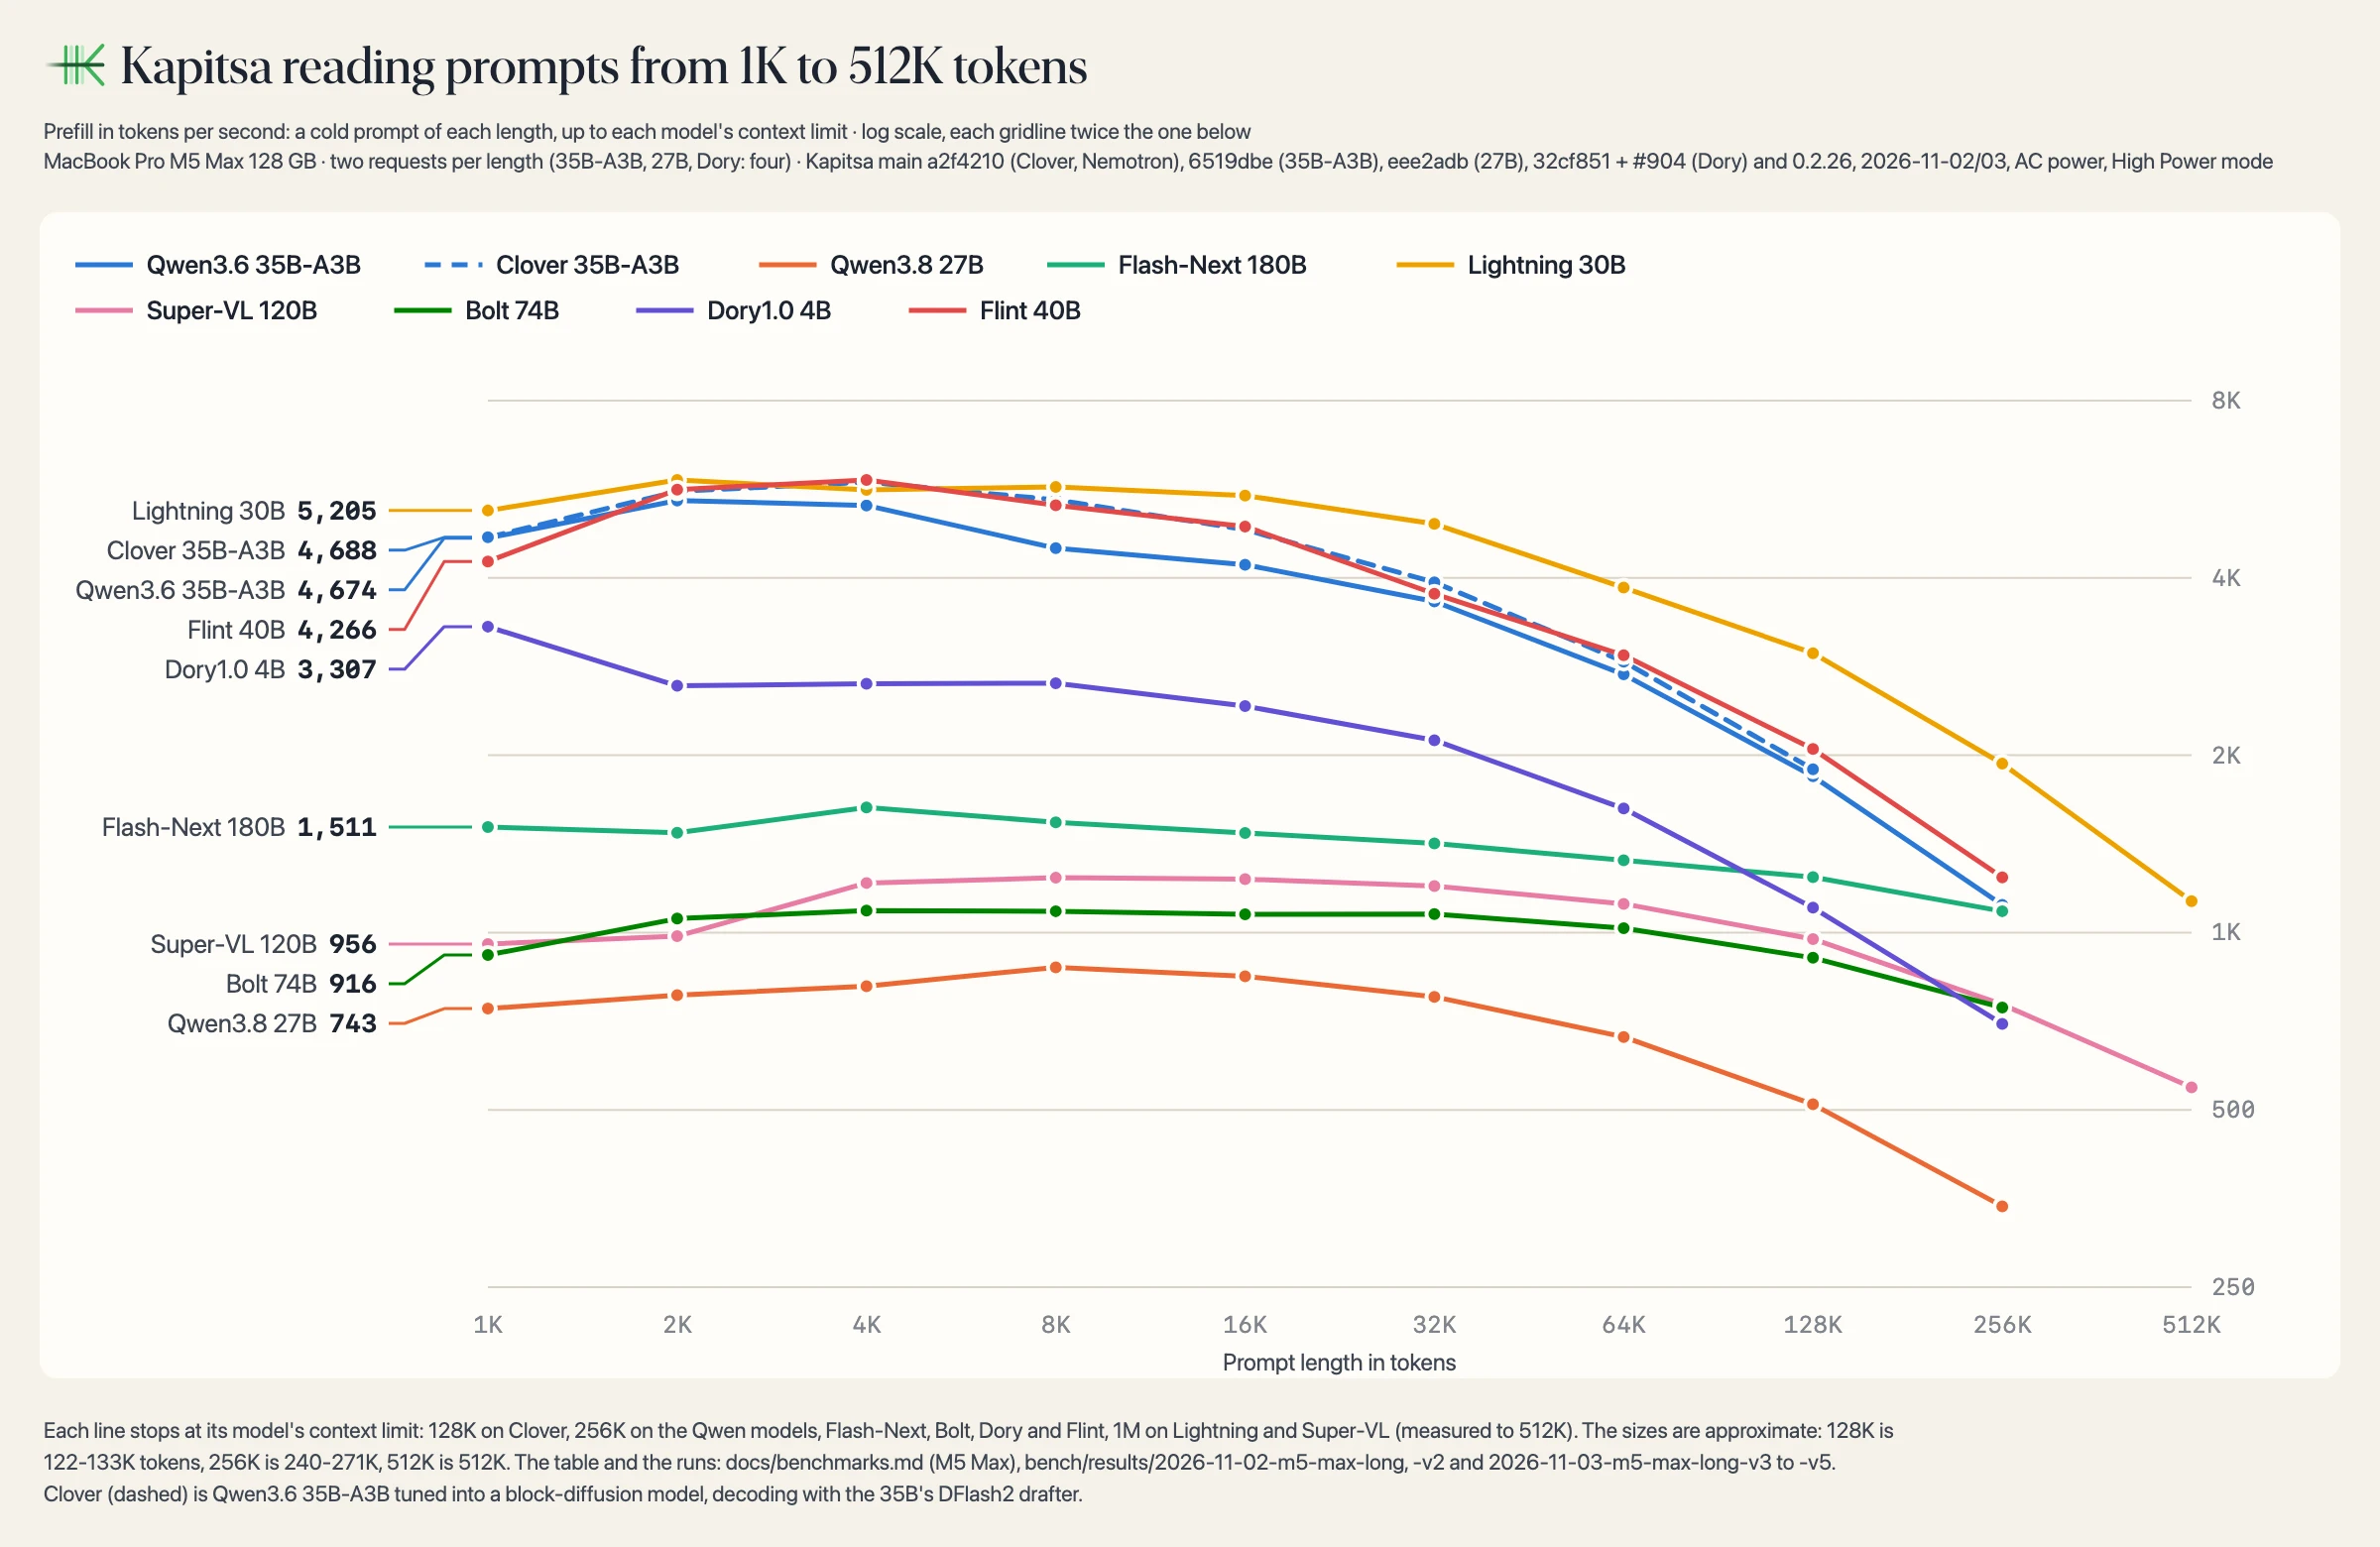
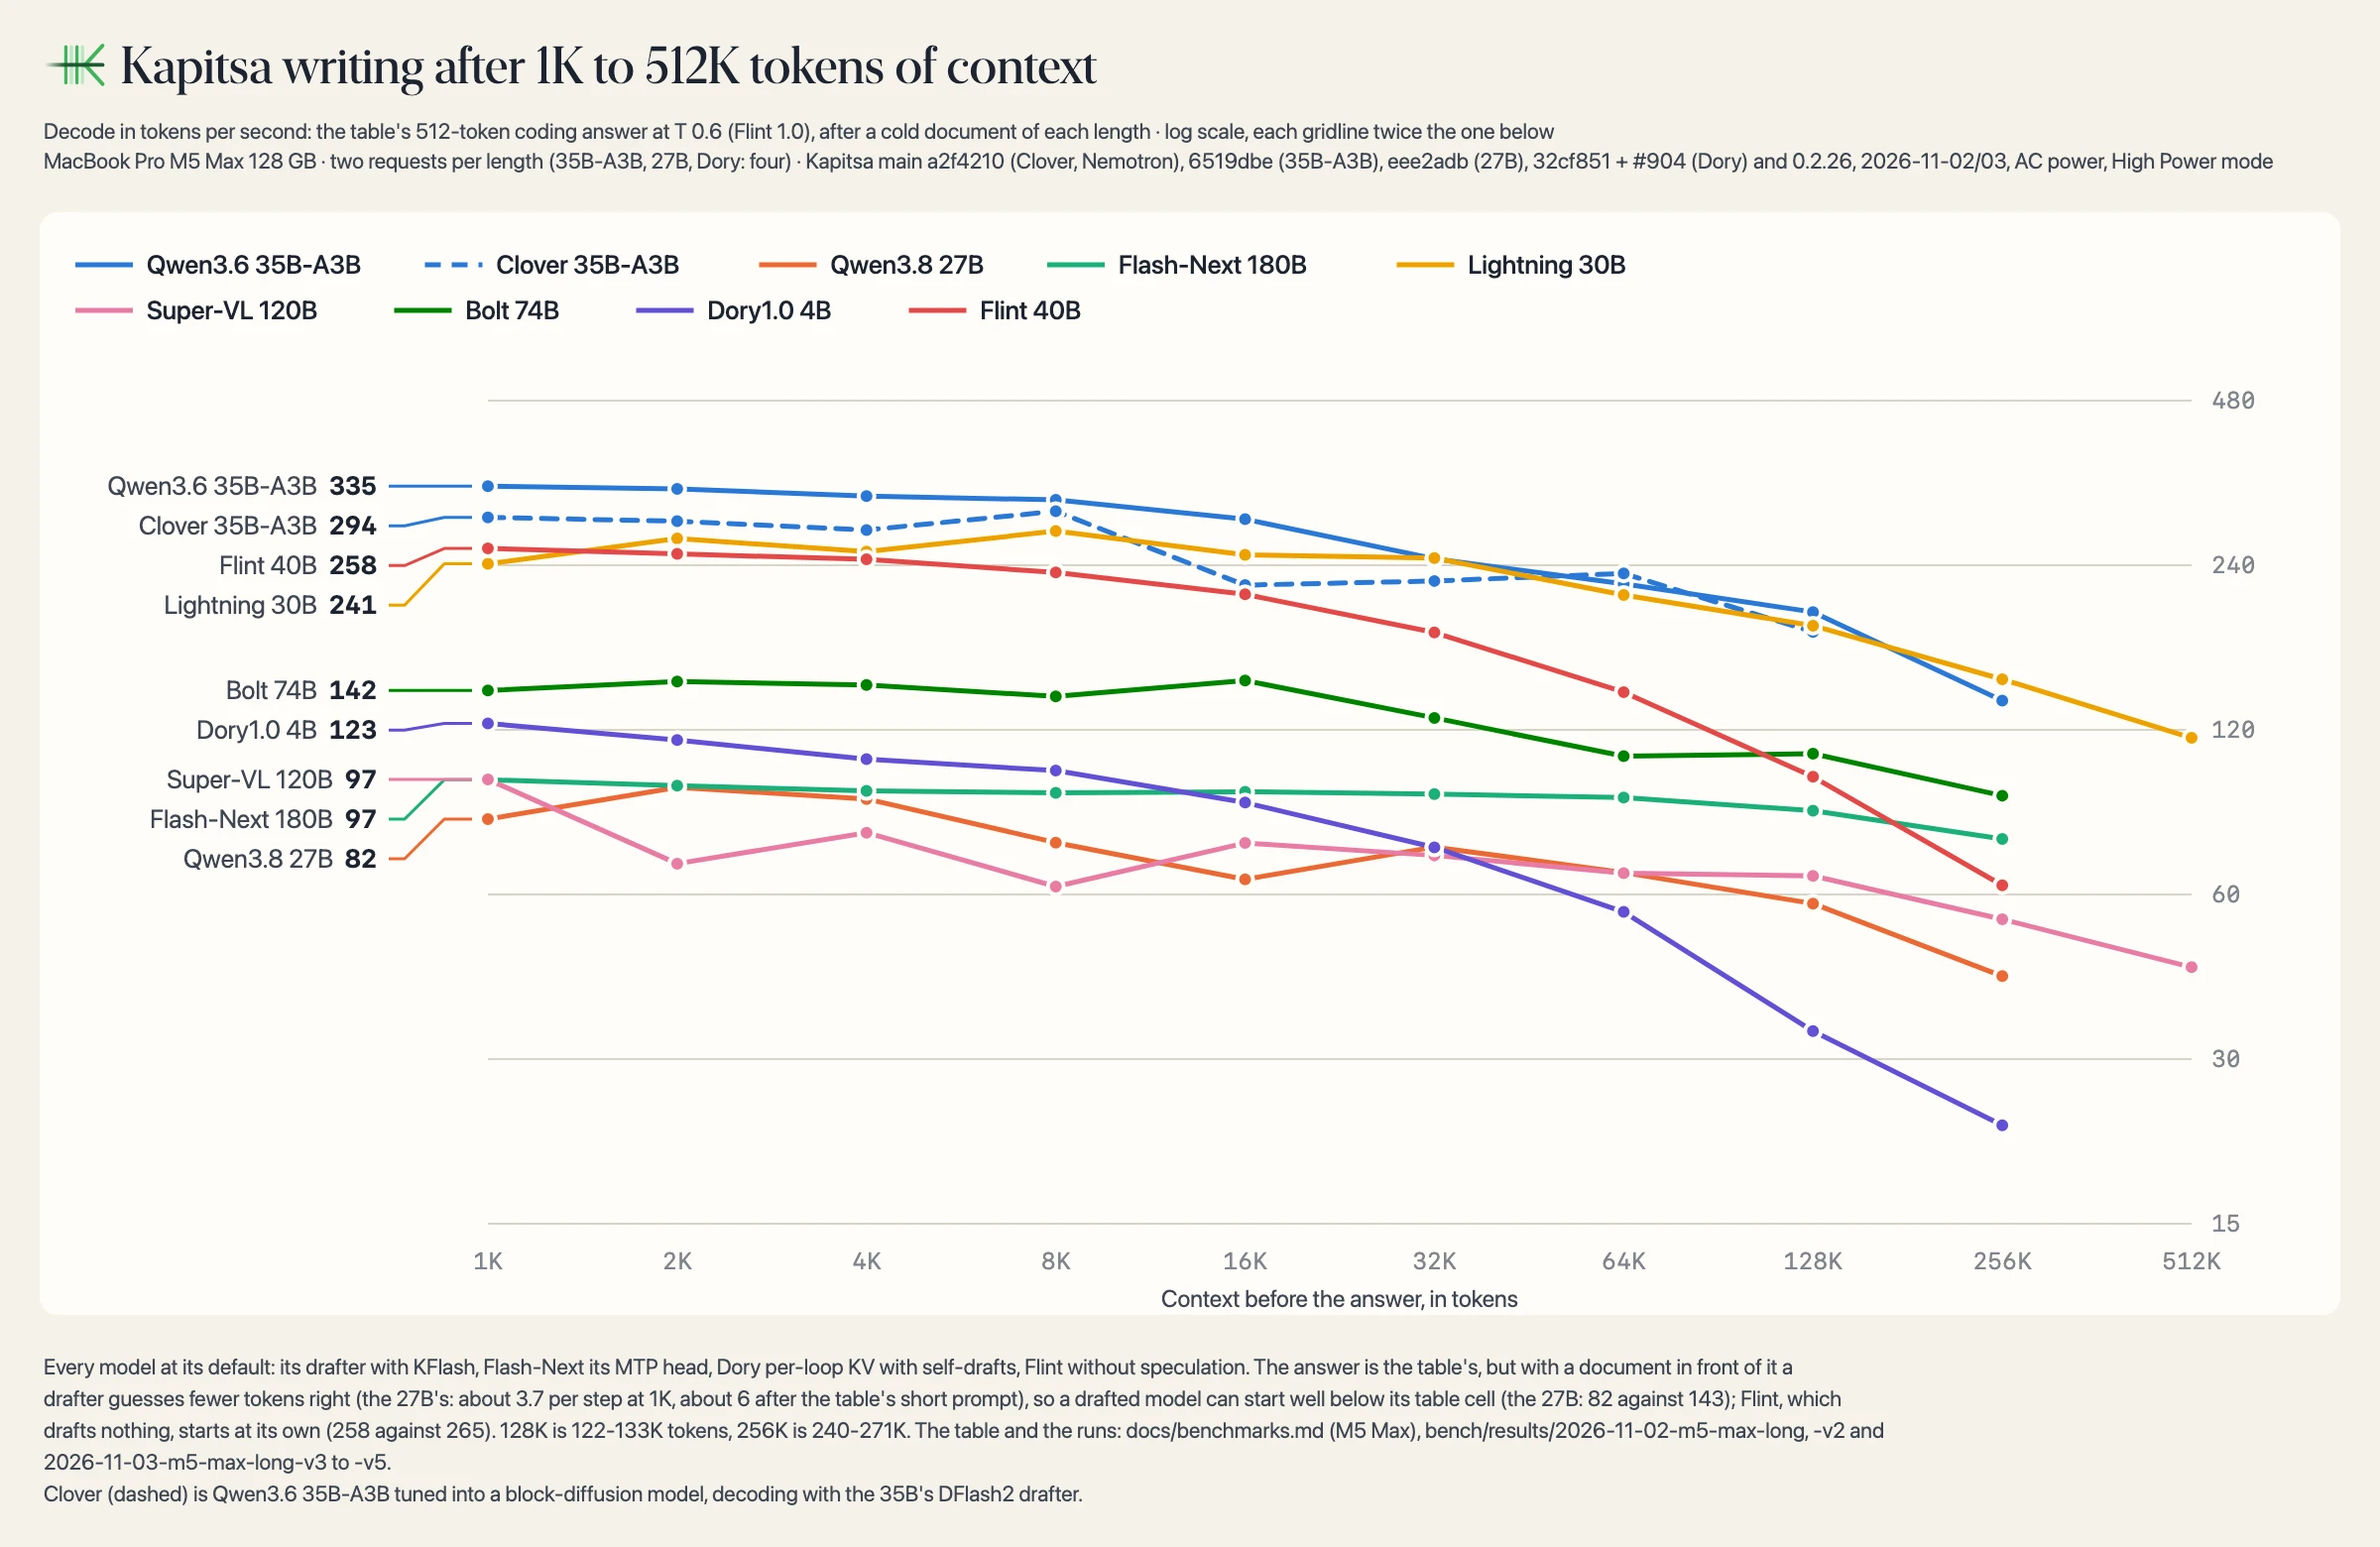
How Kapitsa's speed holds from 1K tokens of context to each model's limit, up to 512K, every model on the M5 Max (log scale; the table). The decode chart is the poster's 512-token coding answer written after a document of each length: with a document in front of it a drafter guesses fewer tokens right, so a drafted model's 1K point can sit well below its poster cell (the 27B: 82 against 143), while Flint, which drafts nothing, matches its cell:
How it works
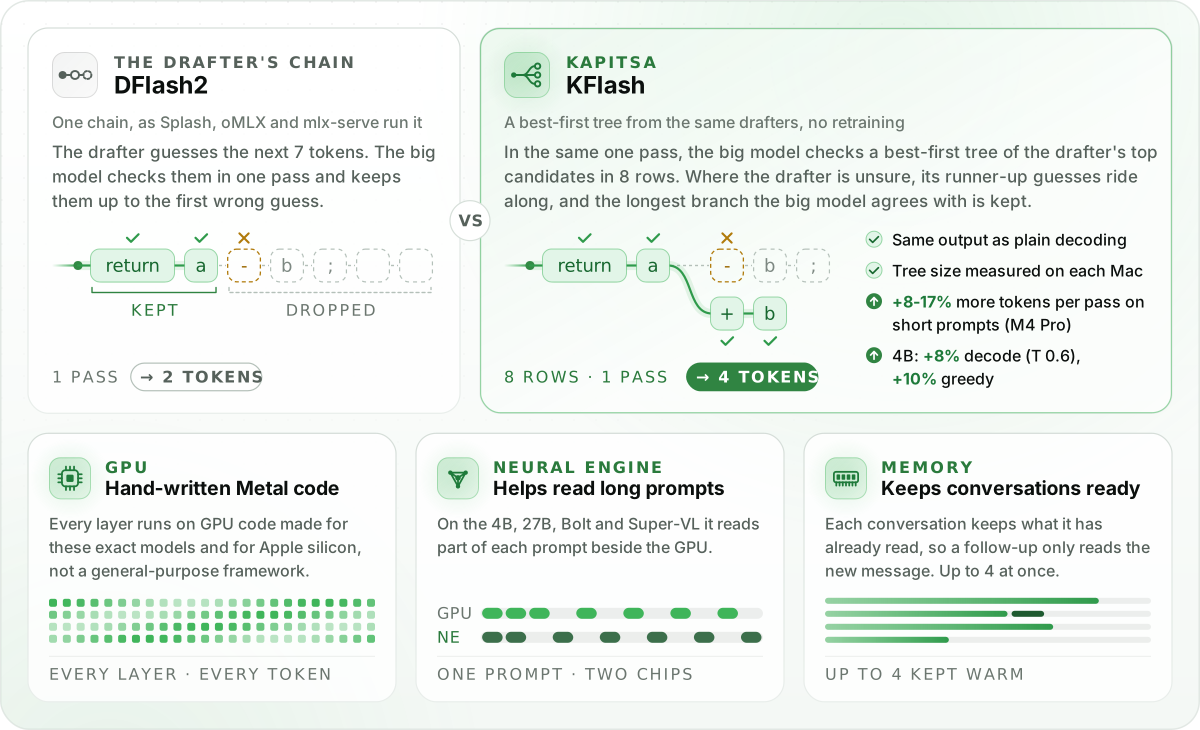
Kapitsa decodes with KFlash. A draft model such as DFlash2 guesses the next seven tokens, with a few candidates for each one. Engines that run it as published (Splash, oMLX, mlx-serve) check one chain of guesses and stop at the first wrong one. KFlash checks a best-first tree of the drafter's candidates in the same pass, so where the drafter hesitates, its runner-ups are checked too and more tokens survive each pass. The tree's size comes from what a verify row costs on your Mac, measured there, and it changes no output: the big model checks every token. It runs on z-lab's DFlash, DFlash2, and NVIDIA's DSpark and LiLiCorr as published, and on our retrain of the 27B's DFlash2 with a 16-row block. How KFlash works
CLI
kapitsa serve                   # chat + OpenAI/Anthropic APIs at http://127.0.0.1:8000
kapitsa claude                  # Claude Code on Kapitsa
kapitsa doctor                  # this Mac's GPU and memory, and which models fit it
kapitsa cluster                 # the Macs on this network that run Kapitsa, and their models
kapitsa bench                   # benchmark this Mac, share it with the community
kapitsa bench compare           # the same test against the other engines installed here
kapitsa pull 27b                # download a model without starting it
kapitsa list                    # downloaded models and their size
kapitsa rm 27b                  # delete a downloaded model
kapitsa import model.gguf       # use a Qwen or Flint GGUF from LM Studio, Ollama or llama.cpp
kapitsa update                  # update now (it also updates itself)
--model picks the model and its precision (35b:6bit). kapitsa <command> --help has the options.
A Mac that cannot hold a model whole uses another Mac on the network that runs it, and two Macs that would each stream
Flash-Next pair to hold it in memory between them (Several Macs); --private keeps a
server to its own Mac. Usage guide
In-process SDK
The opt-in C ABI SDK lets desktop clients reuse a loaded model, stream and cancel requests. See its build instructions and host-process lifetime limitations. The Node.js / TypeScript binding provides async calls over the same C ABI.
Roadmap — what is open in the tracker: KV cache quantization (#547).
Models
The most precise variant of each catalog model that runs on a Mac of each size. Which Hugging Face repo each alias downloads, with its pinned revision, draft model and size: docs/models.md. Sizes, download times and draft models: Models and downloads; kapitsa doctor prints the same for this Mac.
| Model | 16 GB | 24 GB | 32 GB | 36 GB | 48 GB | 64 GB | 128 GB |
|---|---|---|---|---|---|---|---|
Qwen3.5-4B · 4b |
BF16 | BF16 | BF16 | BF16 | BF16 | BF16 | BF16 |
Qwen3.5-9B · 9b |
4-bit | 4-bit | 4-bit | 4-bit | 4-bit | 4-bit | 4-bit |
Qwen3.8-27B · 27b |
— | 4-bit† | 5-bit | 5-bit | 8-bit | 8-bit | BF16 |
Qwen3.6-35B-A3B · 35b |
2-bit† | 2-bit | 4-bit | 4-bit | 6-bit | 8-bit | BF16 |
Qwen3.8-Flash-Next 180B-A7B · flash-next |
— | — | — | — | 2-bit + SSD | 2-bit | 4-bit |
Nemotron 3.5 Lightning 30B-A3B · lightning |
— | NVFP4† | NVFP4 | NVFP4 | NVFP4 | NVFP4 | NVFP4 |
Nemotron 3.5 Bolt 74B-A9B · bolt |
— | — | 2-bit† | 2-bit | 2-bit | 2-bit | 2-bit |
Nemotron 3.5 Super-VL 120B-A12B · super-vl |
— | — | — | — | — | — | NVFP4 |
Recursive Flint 40B-A2.5B · flint |
2-bit† | 2-bit | 2-bit | 4-bit | 4-bit | 4-bit | 4-bit |
Clover-35B-A3B-Preview · clover |
— | — | 4-bit | 4-bit | 4-bit | 4-bit | 4-bit |
Nemotron Dory1.0 4B · dory |
BF16 | BF16 | BF16 | BF16 | BF16 | BF16 | BF16 |
Nemotron 3 Nano 4B · nano-4b |
BF16 | BF16 | BF16 | BF16 | BF16 | BF16 | BF16 |
Nemotron Nano 9B v2 · nano-9b |
NVFP4 | NVFP4 | NVFP4 | NVFP4 | NVFP4 | NVFP4 | NVFP4 |
Drex 2.0 · kapitsa-systemone |
— | — | — | Q4† | Q4 | Q8 | Q8 |
The 9b pack is mixed 4/5-bit Nace Q4 on Macs with matrix units (M5 and newer), and legacy 4-bit Nace on other Macs, including M3 and M4.
Cells name the catalog's variant labels — 4bit, 5bit, 6bit, 8bit, bf16 and nvfp4, with 16gb, 24gb and Flash-Next's 64gb shown as 2-bit — that kapitsa serve <name>:<variant> takes, the most precise one that starts on that Mac at the bottom of its working-set range: weights, drafter, activations and 8K tokens of context. † needs the top of the range, about 80% of the RAM against 69% at the bottom; — nothing starts. Flash-Next's 48 GB cell is its Q2_0 pack with the experts the budget does not hold streamed from the SSD, and Drex 2.0's Q4 and Q8 are its release builds, served by kapitsa-systemone (decisions). The 24, 32 and 64 GB columns are kapitsa doctor's plan, and so is any cell in the 16, 36, 48 and 128 GB ones that differs from the default variant those Macs ran, usually 4-bit; kapitsa doctor prints the plan for this Mac.
Speed on each Mac
The catalog models measured on each Mac, against the engines that run them: one collapsed section per Mac, with a table for each model family. Decode is a 512-token coding answer at T 0.6 (Flint at its card's T 1.0), prefill a 4K-token prompt. Under each model's name are the weights Kapitsa ran; the other engines' weights and how each number was measured are in docs/benchmarks.md. Flint's speed from 1K to 128K tokens of prompt on the M5 Pro, against llama.cpp: bench/results/2026-10-24-flint-m5pro-context.
Each cell: prefill / decode, tokens/s (a lone number is decode: no prefill run) · 🟩 fastest decode · ≈ a decode tie with Kapitsa · small type: the decoding method (none: no speculative decoding) · × can't run on that Mac · — not measured
MacBook Pro (16-inch, 2026) · M5 Max · 128 GB · 9 models
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve | oMLX | Splash | Ollama | MTPLX | MLX (mlx-lm / mlx-vlm) |
llama.cpp | LM Studio |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 1126 / 144 KFlash · 7afb51d |
792 / 128 DFlash2 · 26.10.3 |
902 / 92 DFlash2 · 0.7.3.dev2 |
1039 / 116 DFlash2 · 1.4.0 |
844 / 71 MTP · 0.40.11, MLX runner |
848 / 73 MTP · 2.12.2 |
856 / 56 MTP · mlx-vlm 0.7.10 |
578 / 48 MTP · b11871 |
918 / 33 MLX runtime 1.13.1 (nax) |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 6539 / 351 KFlash · 39f20c8 |
4622 / 235 MTP · 26.10.3 |
3005 / 189 DFlash2 · 0.7.3.dev2 |
6386 / 281 DFlash2 · 1.4.0 |
3077 / 162 MTP · 0.40.11, MLX runner |
4291 / 130 MTP · 2.12.2 |
4439 / 138 DFlash2 · mlx-vlm 0.7.10 |
2881 / 171 MTP · b11669 |
4672 / 136 MLX runtime 1.13.1 (nax) |
Qwen3.8-Flash-Next 180B-A7B · flash-nextMoE, 7B active · 4-bit, 105.9 GB |
🟩 1726 / 108 KFlash · af7d795 |
🟩 1720 / 108 26.10.2 |
1260 / 107 MTP · 0.7.1rc1 |
× | 60 0.40.6 |
1263 / 88 MTP · 2.12.2 |
1030 / 77 MTP · mlx-vlm 0.7.8 |
842 / 96 b11669 |
× |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 122 KFlash · 7f4e709 |
× | × | × | × | × | 76 mlx-lm 0.32.3.dev3 |
9 b11551 |
× |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 287 KFlash · 7f4e709 |
190 26.10.2 |
190 0.7.1rc1 |
× | 153 0.40.6 |
131 2.12.2 |
139 mlx-lm 0.32.2 |
159 b11669 |
110 llama.cpp runtime 2.60.0 |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 1075 / 154 KFlash · 7f4e709 |
× | 903 / 71 0.7.3.dev2 |
× | × | × | 936 / 66 version not recorded |
× | × |
Nemotron 3.5 Super-VL 120B-A12B · superhybrid MoE, 12B active · NVFP4, 76.4 GB |
🟩 87 KFlash · 7f4e709 |
× | 52 0.7.1rc1 |
× | 64 0.40.6 |
44 2.12.2 |
46 mlx-vlm git main 73d366e |
66 b11669 |
61 llama.cpp runtime 2.60.0 |
Recursive Flint
| Model | Kapitsa | llama.cpp | rec |
|---|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 5770 / 265 KFlash |
3827 / 130 Q4_1, b11871 |
2863 / 224 0.1.0 |
DiffuSpace Clover
| Model | Kapitsa |
|---|---|
Clover-35B-A3B-Preview · cloverblock-diffusion MoE, 3B active · 4-bit pack converted by tools/convert_clover.py, 19.5 GB (measured; the catalog's clover serves the same files) |
🟩 5981 / 304 KFlash |
Kapitsa's cells are the 2026-11-01 runs (main 7f4e709, results), each the median of three runs (Super-VL five) on AC power in High Power mode, Clover's in its own folder, Flash-Next's a 2026-11-04 re-run on main af7d795 after #921, #922 and #923, three runs the same way, greedy 113.9 against 107.3 on 2026-11-01 (results), and the 27B's a 2026-11-05 re-run on 7afb51d (the tree of main 87d7dd5: 0.2.29 with #964, #969 and #970), three runs the same way (results), and the 35B-A3B's a re-run on main 39f20c8 after #975 (its GPU prefill wavefront), three runs the same way (results). The other engines' 27B, 35B-A3B and Bolt cells are the 2026-10-25 session (each engine's latest release, macOS 26.4); llama.cpp's 35B-A3B cell and the other engines' Flash-Next, Lightning, Super-VL and Dory cells are the 2026-10-18 runs, not yet re-measured; rec's and llama.cpp's Flint cells are one block on 2026-10-26 (results). The build each cell ran is under its number; details in bench/results/2026-10-25-m5-max and its re-runs.
MacBook Pro (16-inch, 2026) · M5 Pro · 48 GB · 7 models
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve | oMLX | Splash | Ollama | MTPLX | MLX (mlx-lm / mlx-vlm) |
llama.cpp | LM Studio |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
606 / 77 KFlash |
🟩 464 / 78 DFlash2 · 26.10.2 |
446 / 51 DFlash2 · 0.7.1rc1 |
674 / 72 DFlash2 · 1.4.0 |
470 / 40 MTP · 0.40.6 |
462 / 41 MTP · 2.12.2 |
421 / 32 MTP · mlx-vlm 0.7.8 |
322 / 30 MTP · b11669 |
118 / 17 MLX runtime 1.13.1 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 2802 / 201 KFlash |
2494 / 156 MTP · 26.10.2 |
1619 / 144 DFlash2 · 0.7.1rc1 |
3514 / 181 DFlash2 · 1.4.0 |
1518 / 102 MTP · 0.40.6 |
2569 / 89 MTP · 2.12.2 |
2474 / 98 DFlash2 · mlx-vlm 0.7.8 |
1755 / 107 MTP · b11669 |
997 / 96 MLX runtime 1.13.1 |
Qwen3.8-Flash-Next 180B-A7B · flash-nextMoE, 7B active · Q2_0 experts streamed from the SSD |
🟩 1218 / 61 KFlash · e67b764f |
× | × | 1178 / ≈56 1.5.0 |
— | × | × | 37 / 9 c7474afc |
— |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 70 KFlash |
× | × | × | × | × | 53 mlx-lm 0.32.2.dev0 |
13 version not recorded |
× |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 3141 / 159 KFlash |
1728 / 115 MTP · 26.10.2 |
1938 / 124 MTP · 0.7.1rc1 |
× | 2369 / 92 0.40.6 |
1743 / 101 2.12.2 |
1881 / 94 mlx-lm 0.32.2 |
1915 / 101 MTP · b11669 |
1479 / 72 llama.cpp runtime 2.60.0 |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 79 KFlash |
× | 39 0.7.1rc1 |
× | × | × | 41 version not recorded |
× | × |
Recursive Flint
| Model | Kapitsa | llama.cpp | rec |
|---|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 2691 / 149 KFlash |
2072 / 92 b11804 |
2138 / 145 0.1.0 |
Qwen3.8-Flash-Next 180B-A7B does not fit in 48 GB, so both engines stream its experts from the SSD. With Q2_0 weights on both and Kapitsa's expert store pinned at 24 GB (the auto size here is about 29.9 GB, but four runs at that size were stopped at memory pressure), Kapitsa's prefill is behind on short prompts, level at 4K and 16K and 2.7% ahead at 32K: not the fastest everywhere (correction, 24 Oct: on Kapitsa's warm second leg alone its prefill is 13.5-14.5% behind at 1K, level at 4K and a few percent ahead at 16K and 32K; numbers and caveats). The Flash-Next 180B Q2 row's Kapitsa and Splash cells are a 2026-10-30 re-measure (record): Kapitsa at main e67b764f running KFlash against the plain Splash 1.5.0 release, both at --expert-memory 16G --idle-release off, interleaved K S K S, 5 legs per arm of 2 runs each, with the scripts of the 2026-10-27 run. Its decode is a 256-token answer at T 0, not this table's 512-token answer at T 0.6, counted from the first token to the last over 10 requests per engine; its 4K prefill is prompt tokens over time to first token on that run's own 4,074-token prompt, against this table's 4,133. Kapitsa read 61.3 decode (53.7-64.7) and 1,218 prefill (976-1,269) against Splash's 56.5 (51.9-60.2) and 1,178 (1,040-1,262): the ranges overlap, so by the rule registered before the run it is a tie, not a win. KFlash's interleaved A/B at --expert-memory 20G (29 Oct, more runs per arm) measured decode 1.101x and 4K prefill 1.004x the release, the same tokens as the release on 6 prompts × 22 runs (numbers). The llama.cpp cell is the 2026-10-27 four-engine run, PR #751 (record), 2 requests. Kapitsa's own engine ran in that record too, with MTP depth 2 and its expert store pinned at 24 GB, not sized from free memory: 847 prefill and 53.7 decode at T 0, but three of its legs were stopped at memory-pressure level 4, with up to 4.5 GB of swap, late in the leg (16K prefill or turn 2), so its 16K and turn-2 cells have 9 runs against 12. Ollama and LM Studio were not run on that Q2_0 pack, so their cells are dashes, and mlx-serve, oMLX, MTPLX and MLX have no pack of this model that fits 48 GB.
MacBook Pro (16-inch, 2024) · M4 Pro · 48 GB · 7 models
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve | oMLX | Splash | Ollama | MTPLX | MLX (mlx-lm / mlx-vlm) |
llama.cpp | LM Studio |
|---|---|---|---|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 1930 / 201 KFlash |
874 / 137 MTP · 26.10.2 |
803 / 102 MTP · 0.7.1rc1 |
× | 758 / 109 MTP · 0.40.6 |
780 / 104 MTP · 2.12.2 |
843 / 88 MTP · mlx-vlm 0.7.8 |
650 / 70 MTP · b11669 |
801 / 81 MLX runtime 1.13.1 |
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 396 / 63 KFlash |
129 / 54 DFlash2 · 26.10.2 |
136 / 45 DFlash2 · 0.7.1rc1 |
53 DFlash2 · 1.4.0 |
124 / 32 MTP · 0.40.5 |
126 / 36 MTP · 2.12.2 |
131 / 28 MTP · mlx-vlm 0.7.8 |
84 / 18 MTP · b11669 |
127 / 15 MLX runtime 1.13.1 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 1168 / 161 KFlash |
986 / 124 MTP · 26.10.2 |
1035 / 127 DFlash2 · 0.7.1rc1 |
135 DFlash2 · 1.4.0 |
892 / 89 MTP · 0.40.5 |
918 / 80 MTP · 2.12.2 |
985 / 86 DFlash2 · mlx-vlm 0.7.8 |
663 / 69 MTP · b11669 |
957 / 86 MLX runtime 1.13.1 |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 64 KFlash |
× | × | × | × | × | 48 mlx-lm 0.32.3.dev3 |
6 version not recorded |
× |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 945 / 112 KFlash |
— | — | × | — | — | 721 / 65 DSpark · mlx-vlm 0.7.8 |
— | — |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 519 / 69 KFlash |
— | 298 / 35 0.7.1rc1 |
× | — | — | 300 / 32 mlx-vlm 0.7.8 |
× | — |
Recursive Flint
| Model | Kapitsa | llama.cpp | rec |
|---|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 968 / 128 KFlash |
977 / 80 b11804 |
796 / 127 0.1.0 |
Splash's cells are Splash 1.4.0 at decode only (2026-10-21): Splash needs macOS 26.4 or later, and this MacBook is on 27.0.1. On an AWS EC2 Mac mini M4 Pro (48 GB, macOS 26.7) on 2026-10-28, Splash 1.4.1 read 1056 / 140 on the 35B-A3B and 251 / 50 on the 27B, against Kapitsa 0.2.23's 1171 / 169 and 392 / 65 on the same Mac (record).
MacBook Pro (16-inch, 2023) · M3 Pro · 36 GB · 10 models
Qwen and Nemotron
| Model | Kapitsa | Ollama | MTPLX | MLX (mlx-lm / mlx-vlm) |
llama.cpp |
|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 703 / 120 KFlash |
600 / 67 MTP · 0.40.8 |
612 / 64 MTP · 2.12.2 |
642 / 56 MTP · mlx-vlm 0.7.8 |
512 / 50 MTP · b11804 |
Qwen3.5-9B · 9bdense · legacy 4-bit pack, 9.0 GB |
🟩 381 / 77 KFlash |
— | — | 353 / 27 mlx-lm 0.32.2 |
307 / 23 b11804 |
Qwen3.8-27B · 27bdense · 4-bit, 20.2 GB |
🟩 110 / 40 KFlash |
99 / 23 MTP · 0.40.8 |
99 / 22 MTP · 2.12.2 |
102 / 18 MTP · mlx-vlm 0.7.8 |
86 / 16 MTP · b11804 |
Qwen3.6-35B-A3B · 35bMoE, 3B active · 4-bit, 22.1 GB |
🟩 855 / 106 KFlash |
681 / 58 MTP · 0.40.8 |
671 / 53 MTP · 2.12.2 |
695 / 53 DFlash2 · mlx-vlm 0.7.8 |
578 / 53 MTP · b11804 |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 450 / 36 KFlash |
× | × | 344 / 30 mlx-lm 0.32.2.dev0 |
— |
Nemotron 3 Nano 4B · nano-4bhybrid Mamba-2 · FP8, 5.3 GB |
765 / 34 KFlash |
— | — | — | 🟩 413 / 35 Q4_K_M, b11804 |
Nemotron Nano 9B v2 · nano-9bhybrid Mamba-2 · NVFP4, 7.9 GB |
330 / 21 KFlash |
— | — | 🟩 25 4-bit, mlx-lm 0.32.2 |
— |
Nemotron 3.5 Lightning 30B-A3B · lightninghybrid MoE, 3B active · NVFP4, 22.9 GB |
🟩 788 / 75 KFlash |
— | — | 514 / 39 DSpark · mlx-vlm 0.7.8 |
— |
Nemotron 3.5 Bolt 74B-A9B · bolthybrid MoE, 9B active · 2/4/8-bit mix, 25.1 GB |
🟩 256 / 50 KFlash |
— | — | — | — |
Recursive Flint
| Model | Kapitsa | llama.cpp |
|---|---|---|
Recursive Flint 40B-A2.5B · flintMoE, 2.5B active · 4-bit, 22.6 GB |
🟩 801 / 74 KFlash |
772 / 51 b11804 |
macOS 14.1, on AC power: Kapitsa's macOS 14 kernels (macOS 15 and later run fused ones). mlx-serve, oMLX and Splash need a newer macOS (×); LM Studio was not installed; rec 0.1.0 refuses this Mac: it requires 48 GiB. Each cell but Flint's is one run of the M4 Pro's protocol (Flint's is the mean of two runs, #341), the other engines in the M4 Pro's setup (not re-tuned here). Nano 4B and 9B v2: Kapitsa runs NVIDIA's published checkpoints, which keep some layers in BF16/FP8, so it reads more per token than the 4-bit files: the 4B's FP8 is ~1 byte per weight against Q4_K_M's ~0.6, the 9B's NVFP4 ~6.11 GB per token against 4.67 GB for mlx-lm's 4-bit. Nano 9B v2 on mlx-lm: no prefill shown, because its template ignores enable_thinking and the timed first token is a thinking token.
MacBook Pro (14-inch, 2021) · M1 Pro · 16 GB · 7 models
Qwen and Nemotron
| Model | Kapitsa | mlx‑serve | oMLX | Ollama | MTPLX | MLX (mlx-lm / mlx-vlm) |
llama.cpp | LM Studio |
|---|---|---|---|---|---|---|---|---|
Qwen3.5-4B · 4bdense · 4-bit, 4.6 GB |
🟩 401 / 97 KFlash |
286 / 62 MTP · 26.10.2 |
281 / 55 MTP · 0.7.1rc1 |
298 / 55 MTP · 0.40.6 |
305 / 42 MTP · 2.12.2 |
308 / 46 mlx-lm 0.32.2 |
315 / 38 MTP · b11669 |
308 / 47 MLX runtime 1.13.1 |
Qwen3.5-9B · 9bdense · legacy 4-bit pack, 9.0 GB |
🟩 217 / 57 KFlash |
159 / 37 MTP · 26.10.2 |
— | — | — | 170 / 30 mlx-lm 0.32.2 |
— | — |
Qwen3.6-35B-A3B · 35b:16gbMoE, 3B active · 2-bit experts (unsloth's GGUF), 10.8 GB |
🟩 462 / 52 KFlash |
× | × | — | × | × | 38 b11669 |
— |
Nemotron Dory1.0 4B · dorylooped dense · NVFP4, 3.2 GB |
🟩 39 KFlash |
× | × | × | × | 30 mlx-lm 0.32.3.dev3 |
4 b11551 |
× |
Nemotron 3 Nano 4B · nano-4bhybrid Mamba-2 · FP8, 5.3 GB |
🟩 37 KFlash |
— | — | — | — | 21 BF16, version not recorded |
28 Q4_K_M, b11669 |
— |
Nemotron Nano 9B v2 · nano-9bhybrid Mamba-2 · NVFP4, 7.9 GB |
🟩 25 KFlash |
— | — | — | — | 18 mlx-lm 0.32.2 |
14 Q4_K_M, version not recorded |
— |
Recursive Flint
| Model | Kapitsa | llama.cpp |
|---|---|---|
Recursive Flint 40B-A2.5B · flint:16gbMoE, 2.5B active · 2-bit experts (unsloth's GGUF), 11.9 GB |
🟩 414 / 61 KFlash |
43 d772569 |
Other precisions: --model 35b:6bit is five times closer to bf16 than the 4-bit default (KL). All but Lightning, Dory, the two Nemotron Nanos, Flint, Clover, Ornith and the 35B's 16gb read images. What runs on a Mac of each size: Models. Every model's variants and draft models
Get release notices
Watch → Custom → Releases on nace-ai/kapitsa puts every new version in your notifications.
Star history
How KFlash works · Architecture · Contributing · Press kit · Apache 2.0, © 2026 Nace AI · Third-party notices
Explorer des projets similaires
codecrafters-io/build-your-own-x
Maîtrisez la programmation en recréant de zéro vos technologies préférées.
562,356 étoilespublic-apis/public-apis
Une liste collective d'API gratuites
498,808 étoilesmorluto/rea
Rétro-ingénierie de n'importe quoi avec des agents, du comportement des applications jusqu'aux binaires natifs.
457,825 étoilesopenclaw/openclaw
L'IA qui fait vraiment les choses. Tout système d'exploitation, toute plateforme. À la manière du homard. 🦞
394,403 étoiles