
THUSI-Lab/Hstar
THUSI-Lab/Hstar has 150 GitHub stars and 3 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-14 18:33 UTC. Last push 2026-09-21.
Progression mesurée des étoiles
- in 24h
- 0
- in 7 days
- Historique en cours
- in 15 days
- Historique en cours
- in 1 month
- Historique en cours
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
À propos
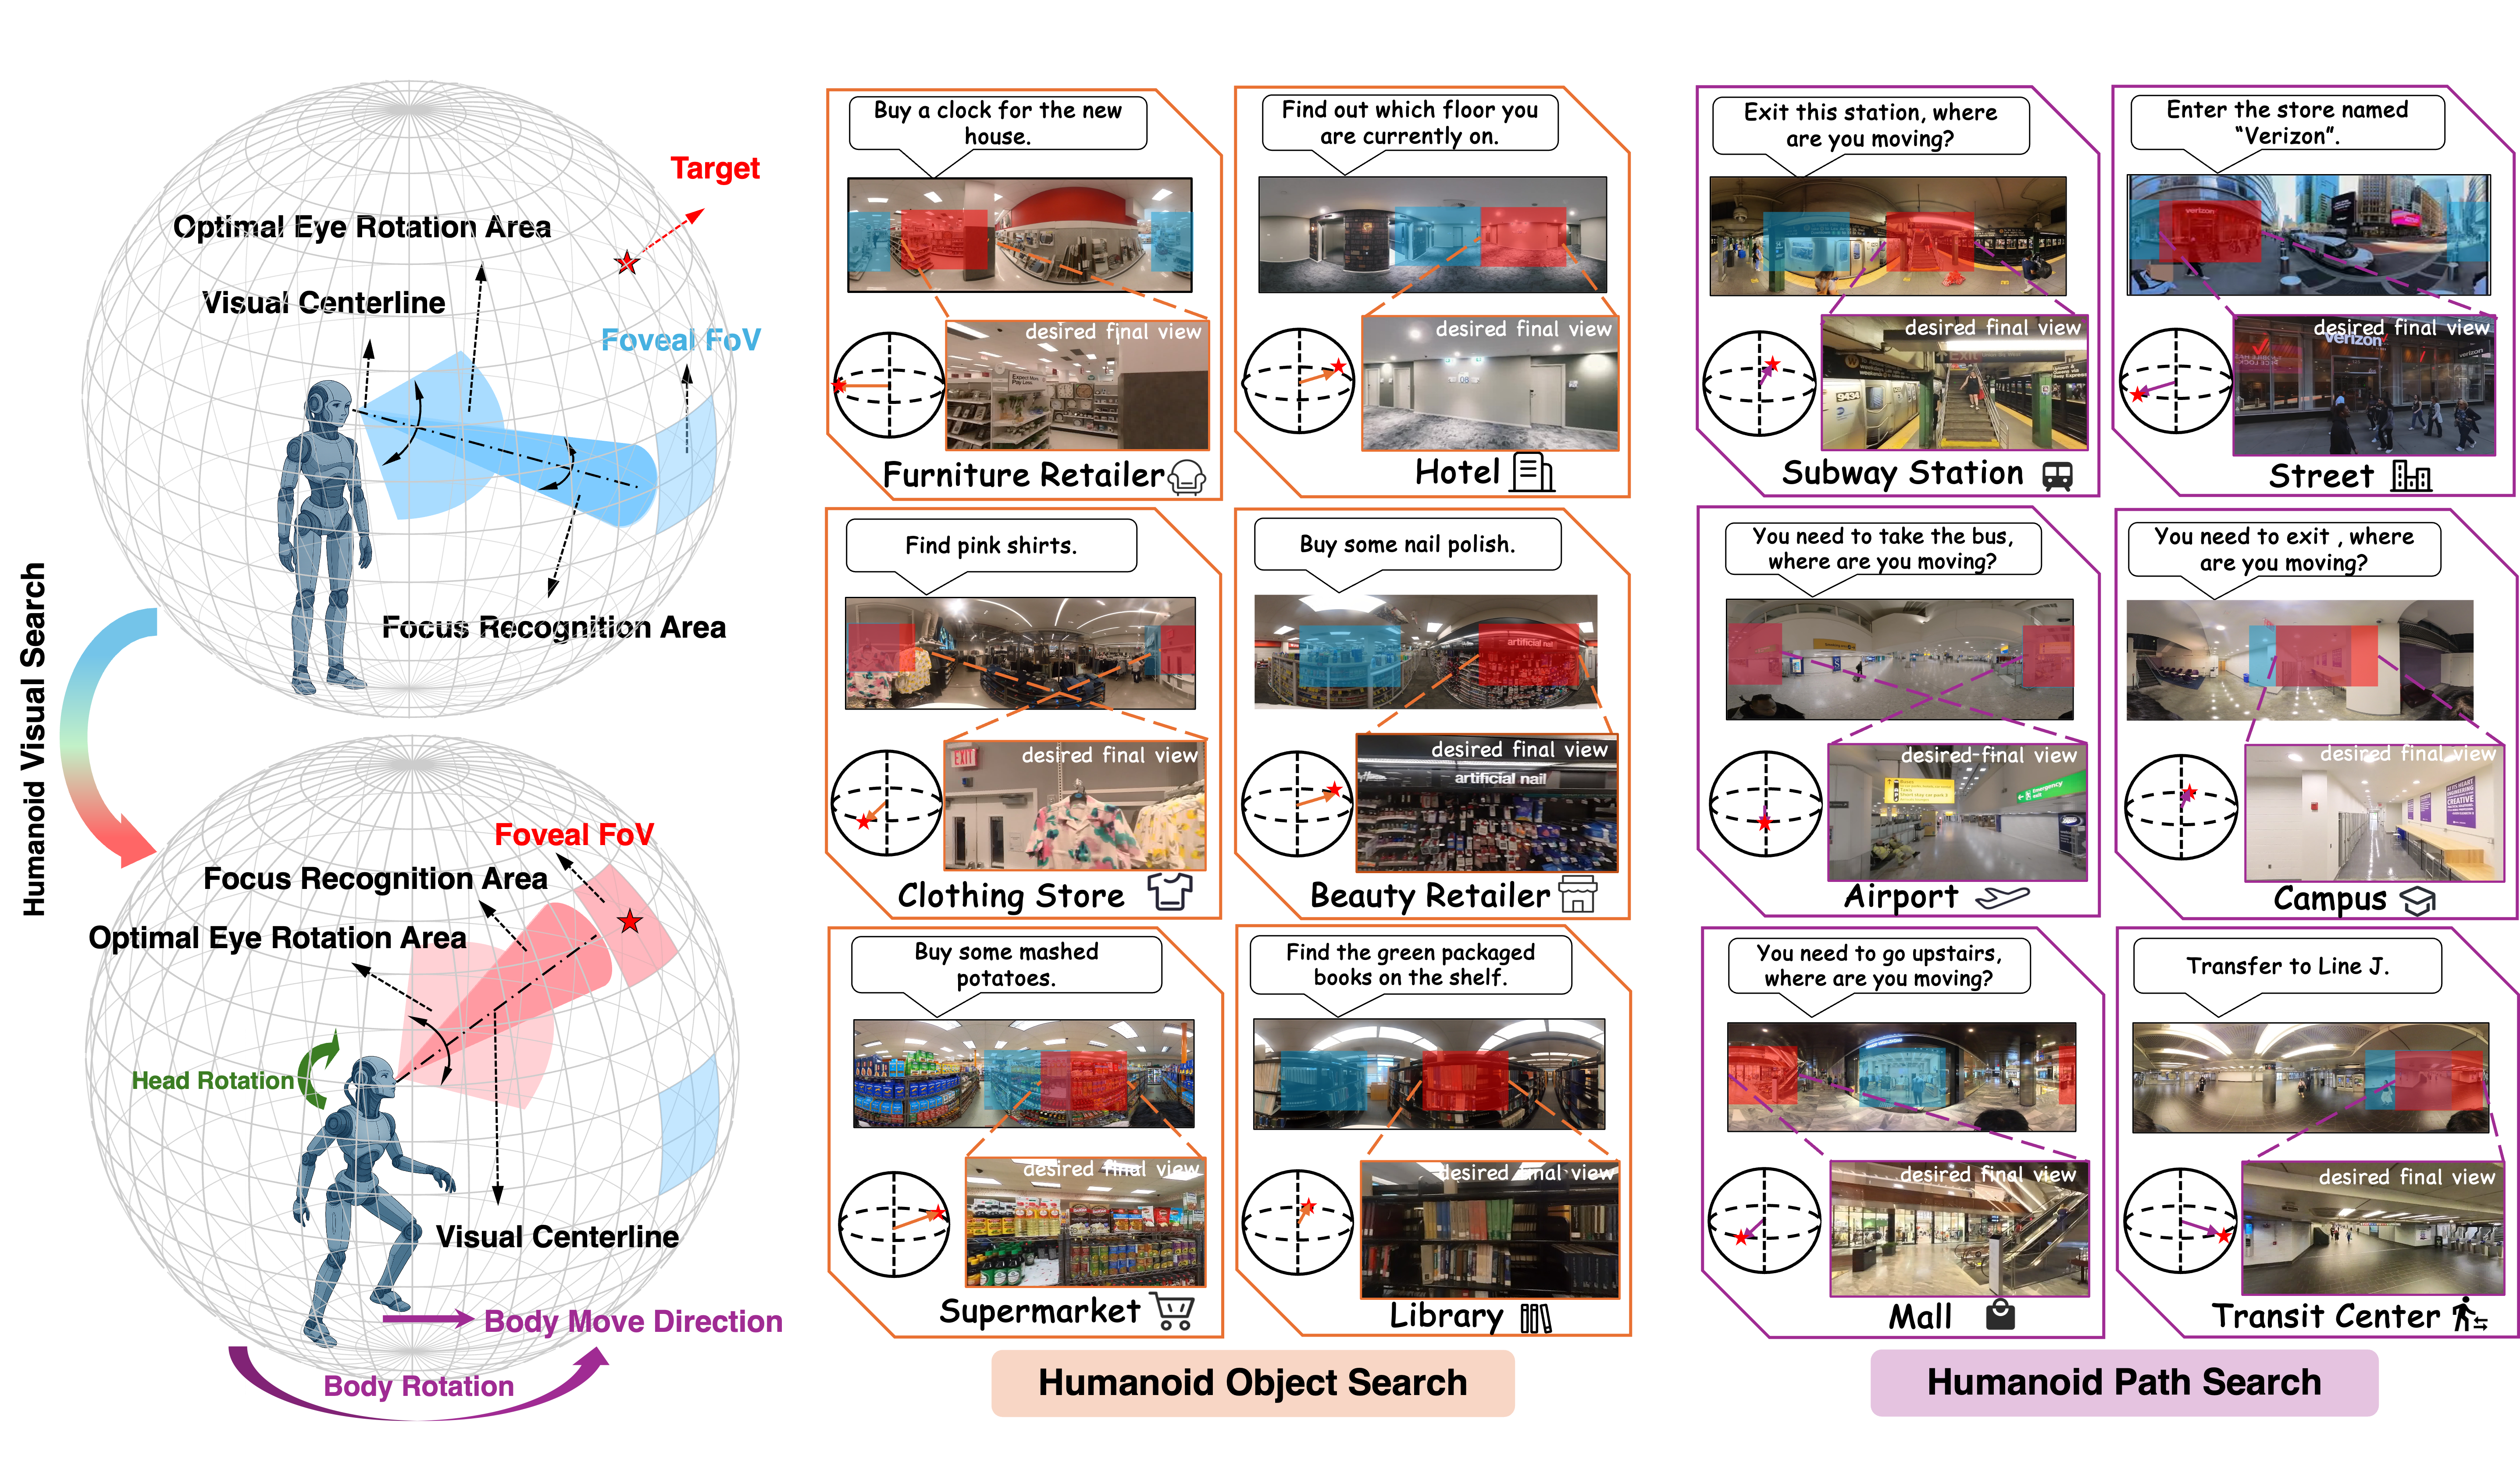
[CVPR 2026] Thinking in 360°: Humanoid Visual Search in the Wild
Outils de développementREADME.md
OriginalThinking in 360°: Humanoid Visual Search in the Wild



News
- [2026/2/21] Our paper is accepted by CVPR 2026!
- [2026/2/15] Updated benchmarking dataset with high-resolution .png files at here.
- [2025/11/26] Our paper is available on arXiv.
- [2025/11/26] We release our finetuend HVS-3B model on HuggingFace.
- [2025/11/26] We release our training datasets on HuggingFace.
- [2025/11/26] We release our benchmarking dataset on HuggingFace.
Getting Started
Installation
Set up the VAGEN environment for training.
conda create -n vagen python=3.10
conda activate vagen
git clone --recursive https://github.com/humanoid-vstar/hstar.git
cd hstar
cd verl && pip install -e .
cd ..
bash scripts/install.sh
For benchmarking, we need a different envrionment for later transformers and vllm version.
conda create -n hstar python=3.10
conda activate hstar
cd vagen/inference && pip install -r requirements.txt # This env is build for CUDA 12 and torch 2.7.1
# You need to adjust the environment to adapt your machine.
# for new models, use a vllm env to deploy
cd ../..
cd verl && pip install -e . --no-deps
cd .. && pip install -e .
In addition, if you want to train the model from scratch, you need to install LLaMA-Factory for SFT training.
Training
SFT
Use LLaMA-Factory and our SFT dataset hos_sft and hps_sft to train or directly download our fine-tuned model HVS-3B-sft-only.
RL
- Download our RL dataset hvs_rl (use mixed_rl.zip if you want to trained on the mixed dataset)
- Change your downloaded dataset path in the training config.
env1: env_name: hstar env_config: render_mode: vision prompt_format: free_think data_path: /path/to/your/dataset use_state_reward: false traj_success_reward: 0.5 traj_fail_penalty: 0 format_reward: 0.5 resolution: 720 train_size: 3200 test_size: 32 - Change your model path in
scripts/examples/masked_grpo/hstar/free_think/run_tmux.shor the tmux-free script and modify other hyperparameters.# ... actor_rollout_ref.model.path=/path/to/your/model \\ # ... critic.model.path=/path/to/your/model \\ # ... - Then run the experiment by:
# With tmux
bash scripts/examples/masked_grpo/hstar/free_think/run_tmux.sh
# Without tmux
bash scripts/examples/masked_grpo/hstar/free_think/run.sh
Benchmarking
- Download our hstar_bench dataset.
- Change your downloaded dataset path (2 task splits) in the
scripts/examples/masked_grpo/hstar/free_think/hos_val_config.yamlandscripts/examples/masked_grpo/hstar/free_think/hps_val_config.yaml.env1: env_name: hstar env_config: render_mode: vision prompt_format: free_think use_state_reward: false data_path: /path/to/your/dataset/split resolution: 1080 - Create test dataset seeds.
# Create one full dataset python vagen/env/create_dataset.py --yaml_path "scripts/examples/masked_grpo/hstar/free_think/hos_val_config.yaml" \ --train_path "data/hos_bench/train.parquet" \ --test_path "data/hos_bench/test.parquet" python vagen/env/create_dataset.py \ --yaml_path "scripts/examples/masked_grpo/hstar/free_think/hps_val_config.yaml" \ --train_path "data/hps_bench/train.parquet" \ --test_path "data/hps_bench/test.parquet" # Or dataset clips for better efficiency python vagen/env/create_dataset_clip.py \ --yaml_path "scripts/examples/masked_grpo/hstar/free_think/hos_val_config.yaml" \ --train_path "data/hos_bench_clip/train.parquet" \ --test_path "data/hos_bench_clip/test.parquet" \ --num_clip 10 python vagen/env/create_dataset_clip.py \ --yaml_path "scripts/examples/masked_grpo/hstar/free_think/hps_val_config.yaml" \ --train_path "data/hps_bench_clip/train.parquet" \ --test_path "data/hps_bench_clip/test.parquet" \ --num_clip 10 - Modify inference settings in
vagen/inference/inf_cfg.yamland model settings invagen/inference/model_cfg.yaml - Deploy your model using vllm OpenAI API Server on
localhost:8000, see examplevagen/inference/deploy.sh - Run the experiment
cd vagen/inference python -m vagen.server.server server.port=5000 & > ./inf_server.log & python run_inference.py \ --inference_config_path inf_cfg.yaml \ --model_config_path model_cfg.yaml \ --val_files_path /path/to/your/generated/seeds/path \ --wandb_path_name hstar_bench & [--output_dir /path/to/output/dir] # default ./temp_result [--save_all_results False] # save all the ouputs when set to True - View result
python show_result.py [--result_dir /path/to/output/dir] # default ./temp_result
References and Acknowledgement
LLaMA-Factory: Easy and Efficient LLM Fine-Tuning
VAGEN: VAGEN: Reinforcing World Model Reasoning for Multi-Turn VLM Agents
verl: Volcano Engine Reinforcement Learning for LLM
Citation
@misc{yu2025thinking360deghumanoidvisual,
      title={Thinking in 360°: Humanoid Visual Search in the Wild},
      author={Heyang Yu and Yinan Han and Xiangyu Zhang and Baiqiao Yin and Bowen Chang and Xiangyu Han and Xinhao Liu and Jing Zhang and Marco Pavone and Chen Feng and Saining Xie and Yiming Li},
      year={2025},
      eprint={2511.20351},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2511.20351},
}