
Strifee/arabic2english
Strifee/arabic2english has 29 GitHub stars and 6 forks. Star changes are not measured yet. Last checked 2026-11-14 13:09 UTC. Last push 2026-04-01.
Progression mesurée des étoiles
- in 24h
- Historique en cours
- in 7 days
- Historique en cours
- in 15 days
- Historique en cours
- in 1 month
- Historique en cours
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
À propos
Arabic to English machine translation with Transformers and Pytorch
Apprentissage automatiqueREADME.md
OriginalArabic2English - Arabic to English Translator
This is a PyTorch implementation of an Arabic to English Neural Machine Translation built using Transformers architecture (Attention Is All You Need)
Why Arabic→English is Hard
Arabic is morphologically rich — one word can express what takes a full sentence in English. It's also right-to-left with complex root-based derivation. Standard seq2seq models struggle with this — Transformers handle it better due to attention mechanisms capturing long-range dependencies.
Model Architecture
- Custom Transformer (Attention Is All You Need)
- 3 encoder + 3 decoder layers
- 8 attention heads
- Embedding size: 256
- Trained from scratch — no pretrained weights
Setup and Requirements
1. CUDA:
install CUDA before installing the required packages or check if it is already installed
2. Clone the Translate repo:
$ git clone https://github.com/Strifee/arabic2english.git
3. install requirements:
pip install -r requirements.txt
if you have problem with CUDA package try this:
conda install -q pytorch torchvision cudatoolkit=11 -c pytorch-nightly
Data
Arabic to English Translation Sentences :
Arabic to English Translation Sentences is a dataset for machine translation between English and Arabic.
Training
1. Clone the Translate repo:
$ git clone clone https://github.com/Strifee/arabic2english.git
2. Training
$ python translate.py
2. Regularization
Hyperparameters :
BATCH_SIZE = 16
learning_rate = 0.0001
num_epochs = 30

num_heads = 8
num_encoder_layers = 3
num_decoder_layers = 3

max_len= 230
dropout = 0.4
embedding_size= 256
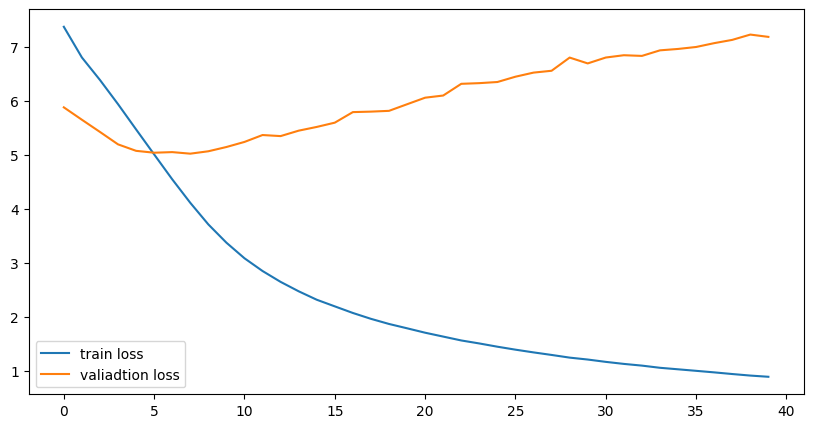
Before regularization :
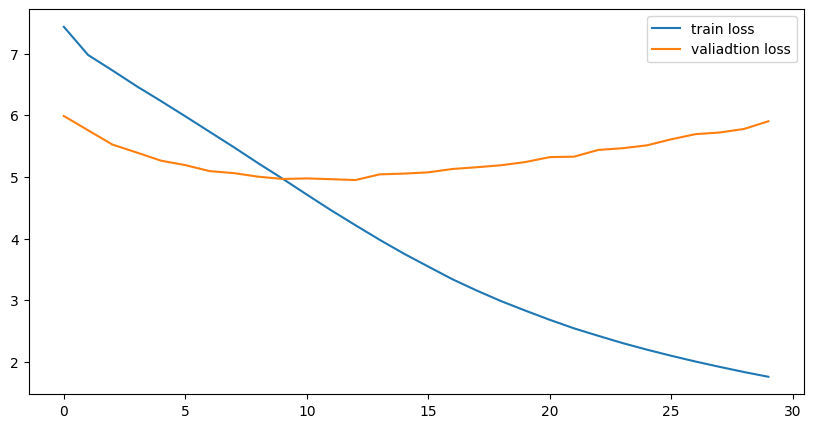
After regularization :
Results
"I'm ready" -> 'أنا مستعد'
"i'm lucky"  -> 'انا محظوظ'
"I'm sad" -> 'أنا حزين'