
NitinDatta8/realtime-data-streaming
NitinDatta8/realtime-data-streaming has 29 GitHub stars and 7 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-10 04:23 UTC. Last push 2023-11-03.
Comment ces chiffres sont mesurés
End-to-end data engineering pipeline with various technologies to ingest real time data.
Progression mesurée des étoiles
- in 24h
- 0
- in 7 days
- Mise à jour retardée
- in 15 days
- Mise à jour retardée
- in 1 month
- Mise à jour retardée
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
README.md
OriginalRealtime Data Streaming | End-to-End Data Engineering Project
Introduction
This project employs a multifaceted technological stack to establish an end-to-end data processing pipeline. The workflow commences by fetching data from the randomuser.me API to generate synthetic user data. This raw data is subsequently channeled through Apache Airflow for data orchestration and storage in a PostgreSQL database.
The data is then streamed through Apache Kafka in conjunction with Apache Zookeeper to facilitate real-time data movement from PostgreSQL to the processing engine. For streamlined management and monitoring of Kafka streams, Control Center and Schema Registry are employed to handle schema configurations and ensure effective oversight of the data streams.
Subsequently, Apache Spark is utilized to conduct data processing tasks, following which the processed data is persisted in a Cassandra database, providing a durable storage solution for the refined information.
The entire pipeline is encapsulated within Docker containers, affording a streamlined and portable deployment mechanism.
System Architecture
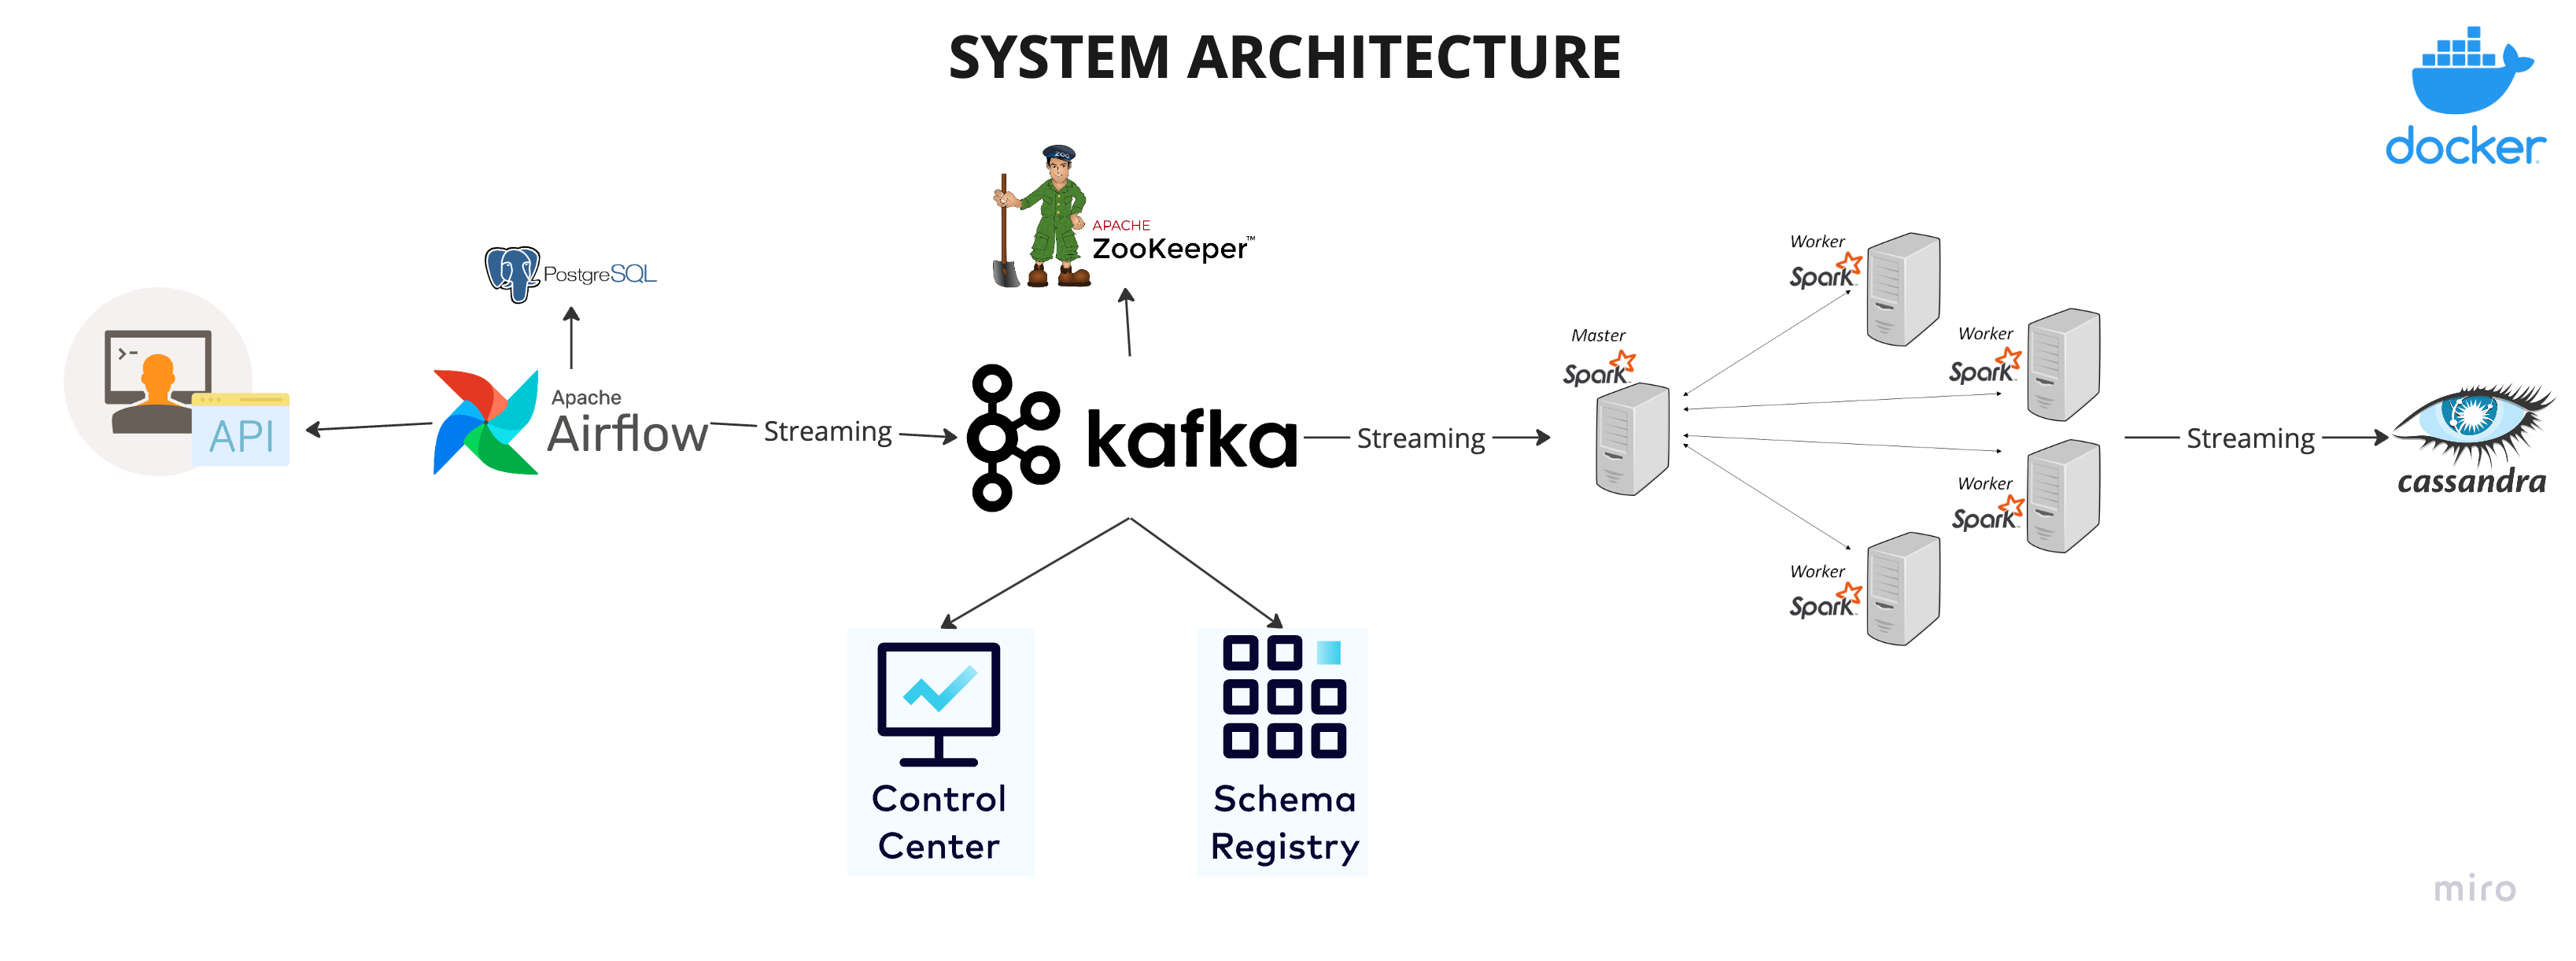
Technologies
- Data Source:
randomuser.meAPI is used to generate random user data for the pipeline. - Apache Airflow: Helps with orchestrating the pipeline and storing fetched data in a PostgreSQL database.
- Apache Kafka and Zookeeper: Used for streaming data from PostgreSQL to the processing engine.
- Control Center and Schema Registry: Helps in monitoring and schema management of the Kafka streams.
- Apache Spark: Responsible for data processing with master and worker nodes.
- Cassandra: Database to store the processed data.
- Docker: Containerize the entire pipeline.
Things to learn
- Establishing a data pipeline using Apache Airflow for workflow orchestration and data management.
- Implementing real-time data streaming through Apache Kafka to facilitate data transfer and processing in real-time.
- Enabling distributed synchronization using Apache Zookeeper for robust coordination and reliability in a distributed system.
- Employing data processing techniques powered by Apache Spark for efficient and scalable data transformation and analysis.
- Utilizing data storage solutions with PostgreSQL and Cassandra to securely store and manage structured and unstructured data, respectively.
- Containerizing the entire data engineering infrastructure with Docker to ensure portability and ease of deployment across various environments.
Acknowledgements
I would like to thank Yusuf Ganiyu for this amazing project.
Please follow the tutorial here to build this data engineering pipeline yourself. YouTube Video Tutorial
Explorer des projets similaires
Asabeneh/30-Days-Of-Python
Le défi de programmation 30 Days of Python est un guide pas à pas pour apprendre le langage de programmation Python en 30 jours. Ce défi peut prendre plus de 100 jours. Avancez à votre rythme. Ces vidéos peuvent aussi vous aider : https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 étoilesgrafana/grafana
Plateforme ouverte et composable d’observabilité et de visualisation de données. Visualise les métriques, les journaux et les traces issus de plusieurs sources, comme Prometheus, Loki, Elasticsearch, InfluxDB, Postgres et bien d’autres.
77,830 étoilesredis/redis
Pour les développeurs qui créent des applications en temps réel pilotées par les données, Redis est le cache, le serveur de structures de données et le moteur de requêtes documentaires et vectorielles préféré, le plus rapide et le plus riche en fonctionnalités.
77,395 étoilesapache/superset
Apache Superset est une plateforme de visualisation et d'exploration de données.
75,473 étoiles