
DataWithBaraa/sql-data-warehouse-project
DataWithBaraa/sql-data-warehouse-project has 1,066 GitHub stars and 748 forks. GitHot measured +2 stars in 24 hours and +8 in 7 days. Last checked 2026-11-08 21:13 UTC. Last push 2026-10-15.
Comment ces chiffres sont mesurés
A comprehensive guide to building a modern data warehouse with SQL Server, including ETL processes, data modeling, and analytics.
Progression mesurée des étoiles
- in 24h
- +2
- in 7 days
- +8
- in 15 days
- Mise à jour retardée
- in 1 month
- Mise à jour retardée
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
README.md
OriginalData Warehouse and Analytics Project




The materials of the data warehouse project: the source files, every script from the videos, and the docs.
You take raw files from two systems, a CRM and an ERP, and build one data warehouse in SQL Server. At the end, the data is clean and ready for analysis.
New here? Open the setup guide in the 00_setup folder. It walks you through installing SQL Server and creating the database, on Windows and Mac, with the fixes for the common errors.
sql-data-warehouse-project/
├── 00_setup/               the setup guide, and the one-click Docker start for Mac
├── 01_datasets/            the six source files the project loads
│   ├── source_crm/         three files from the CRM system
│   └── source_erp/         three files from the ERP system
├── 02_docs/                the requirements, the diagrams and the notes
├── 03_scripts/             the project scripts, in the order of the videos
│   ├── init_database.sql   creates the database: run it first
│   ├── bronze/             loads the raw files
│   ├── silver/             cleans and prepares the data
│   └── gold/               builds the tables for analysis
└── 04_tests/               checks the quality of the silver and gold data
The project reads the six files from C:\sql\dwh_project\01_datasets\. Put the folder there, or change the six paths in 03_scripts/bronze/proc_load_bronze.sql. The videos show the folders without numbers: datasets there is 01_datasets here, scripts is 03_scripts.
🏗️ Data Architecture
The data architecture for this project follows Medallion Architecture Bronze, Silver, and Gold layers:
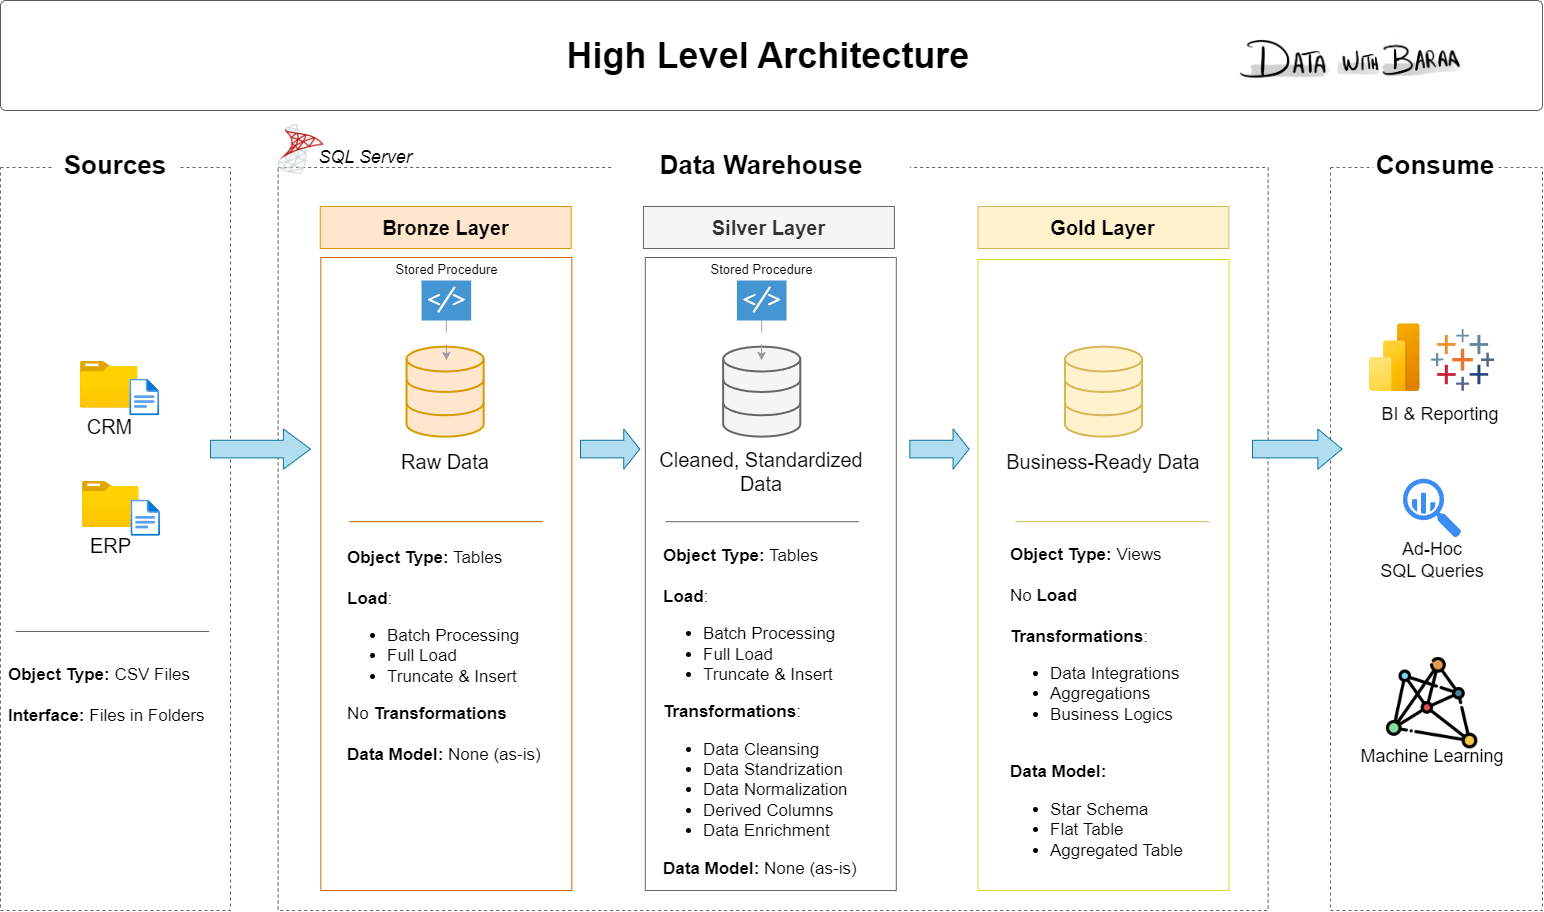
- Bronze Layer: Stores raw data as-is from the source systems. Data is ingested from CSV Files into SQL Server Database.
- Silver Layer: This layer includes data cleansing, standardization, and normalization processes to prepare data for analysis.
- Gold Layer: Houses business-ready data modeled into a star schema required for reporting and analytics.
📖 Project Overview
In this project, you:
- Design the architecture: a modern data warehouse with three layers, bronze, silver and gold.
- Build the ETL pipelines: load the source files and move the data through the layers.
- Model the data: facts and dimensions, ready for reports.
- Analyze it: answer business questions with SQL.
🛠️ Important Links & Tools
- SQL Server and SSMS: the setup guide in
00_setuphas the links and every step. - Git: a GitHub account, to save and share your project.
- draw.io: to draw the architecture and the data model.
- Notion template: the project plan, ready to copy.
- Notion project steps: every phase and task of the project.
🚀 Project Requirements
Building the Data Warehouse (Data Engineering)
Objective
Develop a modern data warehouse using SQL Server to consolidate sales data, enabling analytical reporting and informed decision-making.
Specifications
- Data Sources: Import data from two source systems (ERP and CRM) provided as CSV files.
- Data Quality: Cleanse and resolve data quality issues prior to analysis.
- Integration: Combine both sources into a single, user-friendly data model designed for analytical queries.
- Scope: Focus on the latest dataset only; historization of data is not required.
- Documentation: Provide clear documentation of the data model to support both business stakeholders and analytics teams.
BI: Analytics & Reporting (Data Analysis)
Objective
Develop SQL-based analytics to deliver detailed insights into:
- Customer Behavior
- Product Performance
- Sales Trends
These insights empower stakeholders with key business metrics, enabling strategic decision-making.
For more details, refer to 02_docs/requirements.md.
🎓 Learn with me
Watch on YouTube, or take the guided version with a certificate on my Academy or Udemy.
| Course | YouTube | My Academy | Udemy |
|---|---|---|---|
| SQL | Full course · Playlist | Full Package · Handbook | SQL Bootcamp · SQL for Analytics |
| Python | Full course · Playlist | Full Package · Handbook | Python Bootcamp |
| Tableau | Full course · Playlist | Full Package | Tableau Course · Chart Masterclass |
| Power BI | Full course | ||
| Databricks | Full course |
Materials on my website: SQL · Python · Tableau · Power BI
The SQL projects
| Project | YouTube | Materials | Udemy |
|---|---|---|---|
| Data Warehouse | Watch | this repository | Building a Modern Data Warehouse |
| Exploratory Data Analysis | Watch | Repository | SQL for Exploratory Data Analysis |
| Advanced Data Analytics | Watch | same repository |
More on YouTube: Data projects · Data careers
🤝 Connect


🛡️ License
MIT. Use it, change it, share it, with attribution.
🌟 About me
Hi, I'm Baraa Khatib Salkini. I spent years in enterprise data engineering and built one of the largest lakehouses at Mercedes-Benz. Today I teach data full-time at Data With Baraa: visually, step by step, from zero to hero.
Explorer des projets similaires
Asabeneh/30-Days-Of-Python
Le défi de programmation 30 Days of Python est un guide pas à pas pour apprendre le langage de programmation Python en 30 jours. Ce défi peut prendre plus de 100 jours. Avancez à votre rythme. Ces vidéos peuvent aussi vous aider : https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,423 étoilesgrafana/grafana
Plateforme ouverte et composable d’observabilité et de visualisation de données. Visualise les métriques, les journaux et les traces issus de plusieurs sources, comme Prometheus, Loki, Elasticsearch, InfluxDB, Postgres et bien d’autres.
77,763 étoilesredis/redis
Pour les développeurs qui créent des applications en temps réel pilotées par les données, Redis est le cache, le serveur de structures de données et le moteur de requêtes documentaires et vectorielles préféré, le plus rapide et le plus riche en fonctionnalités.
77,309 étoilesapache/superset
Apache Superset est une plateforme de visualisation et d'exploration de données.
75,453 étoiles