
ArroyoSystems/arroyo
ArroyoSystems/arroyo has 5,078 GitHub stars and 386 forks. GitHot measured +3 in 7 days. Last checked 2026-11-11 07:01 UTC. Last push 2026-11-10.
Comment ces chiffres sont mesurés
Distributed stream processing engine in Rust
Progression mesurée des étoiles
- in 24h
- Mise à jour retardée
- in 7 days
- +3
- in 15 days
- Historique en cours
- in 1 month
- Historique en cours
Variations nettes sur des périodes qui se chevauchent, pas des totaux quotidiens. Les mesures absentes restent vides. Les étoiles indiquent l’intérêt, pas la qualité.
README.md
Original
Getting started | Docs | Discord | Website


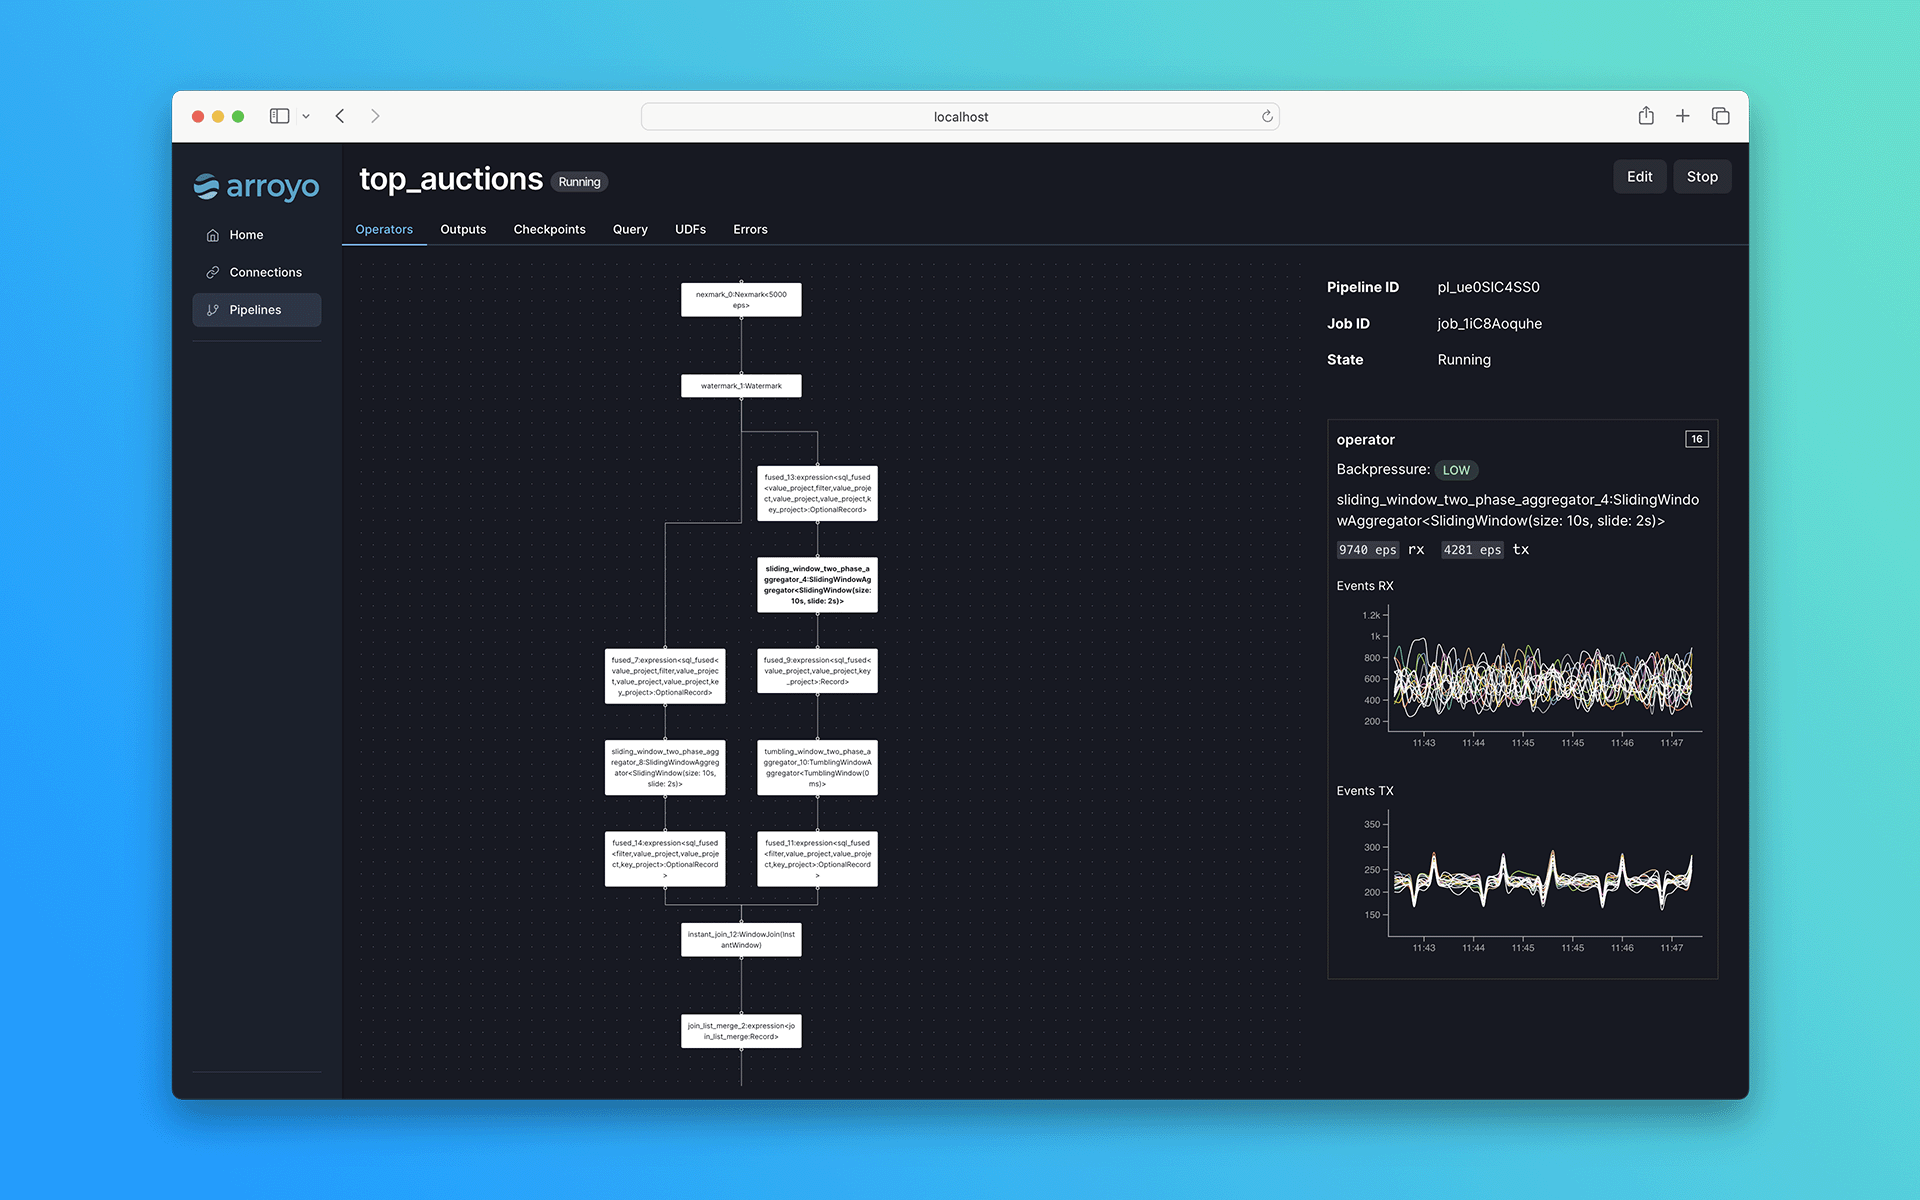
Arroyo is a distributed stream processing engine written in Rust, designed to efficiently perform stateful computations on streams of data. Unlike traditional batch processing, streaming engines can operate on both bounded and unbounded sources, emitting results as soon as they are available.
In short: Arroyo lets you ask complex questions of high-volume real-time data with subsecond results.
Features
🦀 SQL streaming pipelines
🚀 Scales up to millions of events per second
🪟 Stateful operations including windows and joins
🔥State checkpointing for fault-tolerance and recovery of pipelines
🕒 Time-oriented stream processing via the Dataflow model
🔌 A wide variety of connectors, including Kafka and Iceberg
Use cases
Some example use cases include:
- Detecting fraud and security incidents
- Real-time product and business analytics
- Real-time ingestion into your data warehouse or data lake
- Real-time ML feature generation
Why Arroyo
There are already a number of existing streaming engines out there, including Apache Flink, Spark Streaming, and Kafka Streams. Why create a new one?
- Serverless operations: Arroyo pipelines are designed to run in modern cloud environments, supporting seamless scaling, recovery, and rescheduling
- High performance SQL: SQL is a first-class concern, with consistently excellent performance
- Designed for non-experts: Arroyo cleanly separates the pipeline APIs from its internal implementation. You don't need to be a streaming expert to build real-time data pipelines.
Installing
Arroyo ships as a single binary. You can install it locally on MacOS using Homebrew
brew install arroyosystems/tap/arroyo
or on MacOS or Linux with this script:
curl -LsSf https://arroyo.dev/install.sh | sh
or you can download a binary for your platform from the releases page.
Once you have Arroyo installed, start a cluster with
$ arroyo cluster
You can also run a cluster in Docker, with
docker run -p 5115:5115 \
      ghcr.io/arroyosystems/arroyo:latest
Then, load the Web UI at http://localhost:5115.
For a more in-depth guide, see the getting started guide.
Once you have Arroyo running, follow the tutorial to create your first real-time pipeline.
Cloudflare Pipelines
If you don't want to self-host, Arroyo is available as a fully-managed solution on the Cloudflare Developer Platform: Cloudflare Pipelines, now available in beta. Currently, stateless pipelines ingesting into R2 are supported, and we'll be expanding to stateful pipelines in the near future.
Developing Arroyo
We love contributions from the community! See the developer setup guide to get started, and reach out to the team on discord or create an issue.
Community
- Discord — support and project discussion
- GitHub issues — bugs and feature requests
- Arroyo Blog — updates from the Arroyo team
Explorer des projets similaires
Asabeneh/30-Days-Of-Python
Le défi de programmation 30 Days of Python est un guide pas à pas pour apprendre le langage de programmation Python en 30 jours. Ce défi peut prendre plus de 100 jours. Avancez à votre rythme. Ces vidéos peuvent aussi vous aider : https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,560 étoilesgrafana/grafana
Plateforme ouverte et composable d’observabilité et de visualisation de données. Visualise les métriques, les journaux et les traces issus de plusieurs sources, comme Prometheus, Loki, Elasticsearch, InfluxDB, Postgres et bien d’autres.
77,830 étoilesredis/redis
Pour les développeurs qui créent des applications en temps réel pilotées par les données, Redis est le cache, le serveur de structures de données et le moteur de requêtes documentaires et vectorielles préféré, le plus rapide et le plus riche en fonctionnalités.
77,395 étoilesapache/superset
Apache Superset est une plateforme de visualisation et d'exploration de données.
75,473 étoiles