
deep-blind-watermark-removal
vinthony
258estrellas
[AAAI 2021] Split then Refine: Stacked Attention-guided ResUNets for Blind Single Image Visible Watermark Removal
Explora herramientas para entrenar, evaluar y ejecutar modelos, y compara el interés de la comunidad.
vinthony
[AAAI 2021] Split then Refine: Stacked Attention-guided ResUNets for Blind Single Image Visible Watermark Removal

violit-dev
Pure Python Web Framework. Streamlit simplicity, no reruns.

VIPL-Audio-Visual-Speech-Understanding
The state-of-art PyTorch implementation of the method described in the paper "LipNet: End-to-End Sentence-level Lipreading" (https://arxiv.org/abs/1611.01599)

vipshop

A PyTorch-native inference engine with cache, parallelism, quantization and cpu offload for DiTs.

vipstone
一款入门级的人脸、视频、文字检测以及识别的项目.

virajmavani
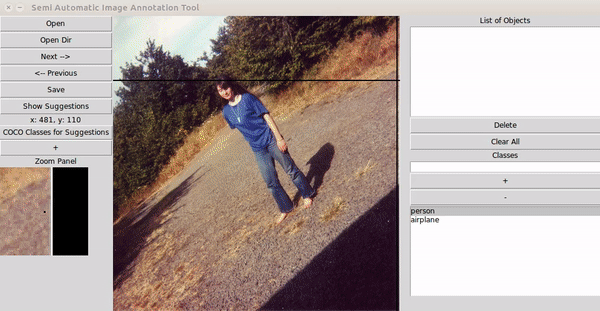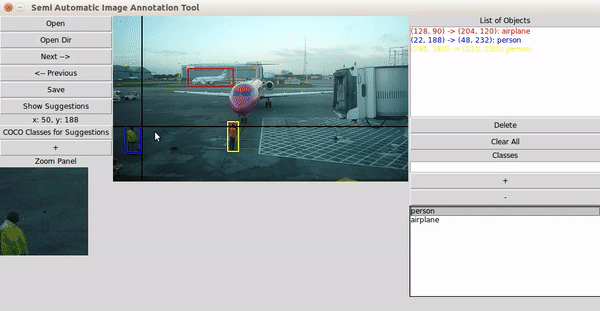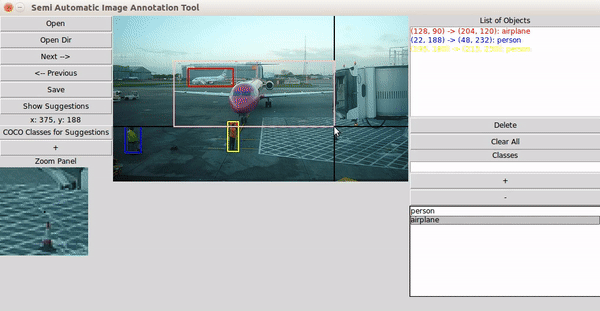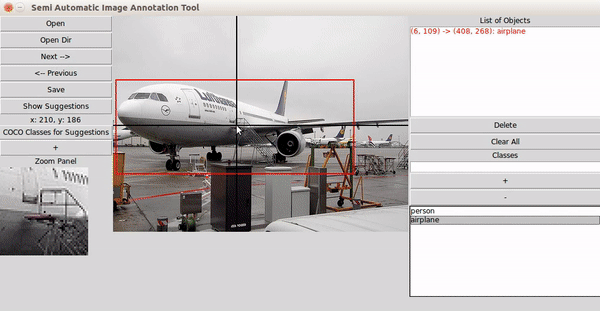
Anno-Mage: A Semi Automatic Image Annotation Tool which helps you in annotating images by suggesting you annotations using user-defined labels

virgili0
Tu nuevo mentor para el aprendizaje en línea de ciencia de datos.

Vision-CAIR
3DCoMPaT++: An improved large-scale 3D vision dataset for compositional recognition
Vision-CAIR
[ICML 2025] Official PyTorch implementation of LongVU

VisionDepth
Generates 3D from 2D videos in multiple output formats using AI-powered depth mapping.

visionpilot-project
Open-source modular autonomous driving simulation platform with computer vision, deep learning, and sensor fusion. Features lane detection, object recognition, various safety features, and adaptive control in BeamNG.tech, with real-time visualization via Foxglove.

VisionVerse
Deep learning in motion deblurring: current status, benchmarks and future prospects[J], The Visual Computer, 2024.

Visual-Attention-Network

Official Pytorch implementations for "SegNeXt: Rethinking Convolutional Attention Design for Semantic Segmentation" (NeurIPS 2022)

visual-layer

fastdup is a powerful, free tool designed to rapidly generate valuable insights from image and video datasets. It helps enhance the quality of both images and labels, while significantly reducing data operation costs, all with unmatched scalability.

visual-ml-notes
Machine Learning Conference & Summer School Notes. 🦄

Visualize-ML
Book_5_《统计至简》 | 鸢尾花书:从加减乘除到机器学习;上架!
Visualize-ML
Book_6_《数据有道》 | 鸢尾花书:从加减乘除到机器学习;欢迎大家批评指正!纠错多的同学会得到赠书感谢!
Visualize-ML
Book_7_《机器学习》 | 鸢尾花书:从加减乘除到机器学习;欢迎批评指正

viswanath-lab
RadQy is a quality assurance and checking tool for quantitative assessment of magnetic resonance imaging (MRI) and computed tomography (CT) data.

vita-epfl

A 3D vision library from 2D keypoints: monocular and stereo 3D detection for humans, social distancing, and body orientation.
vita-epfl
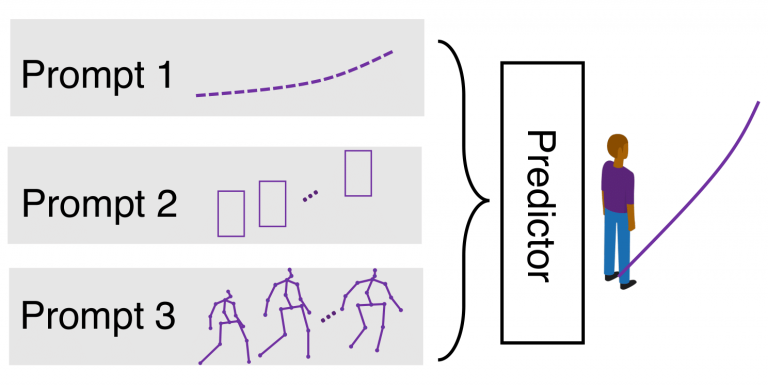
[ICLR 2024] Official implementation of "Social-Transmotion: Promptable Human Trajectory Prediction" in PyTorch.
vita-epfl
[ITS'21] Human Trajectory Forecasting in Crowds: A Deep Learning Perspective

VITA-Group

[ICCV 2019] "AutoGAN: Neural Architecture Search for Generative Adversarial Networks" by Xinyu Gong, Shiyu Chang, Yifan Jiang and Zhangyang Wang
VITA-Group
[InterSpeech 2020] "AutoSpeech: Neural Architecture Search for Speaker Recognition" by Shaojin Ding*, Tianlong Chen*, Xinyu Gong, Weiwei Zha, Zhangyang Wang