OmniShow
Correr-Zhou
477estrellas
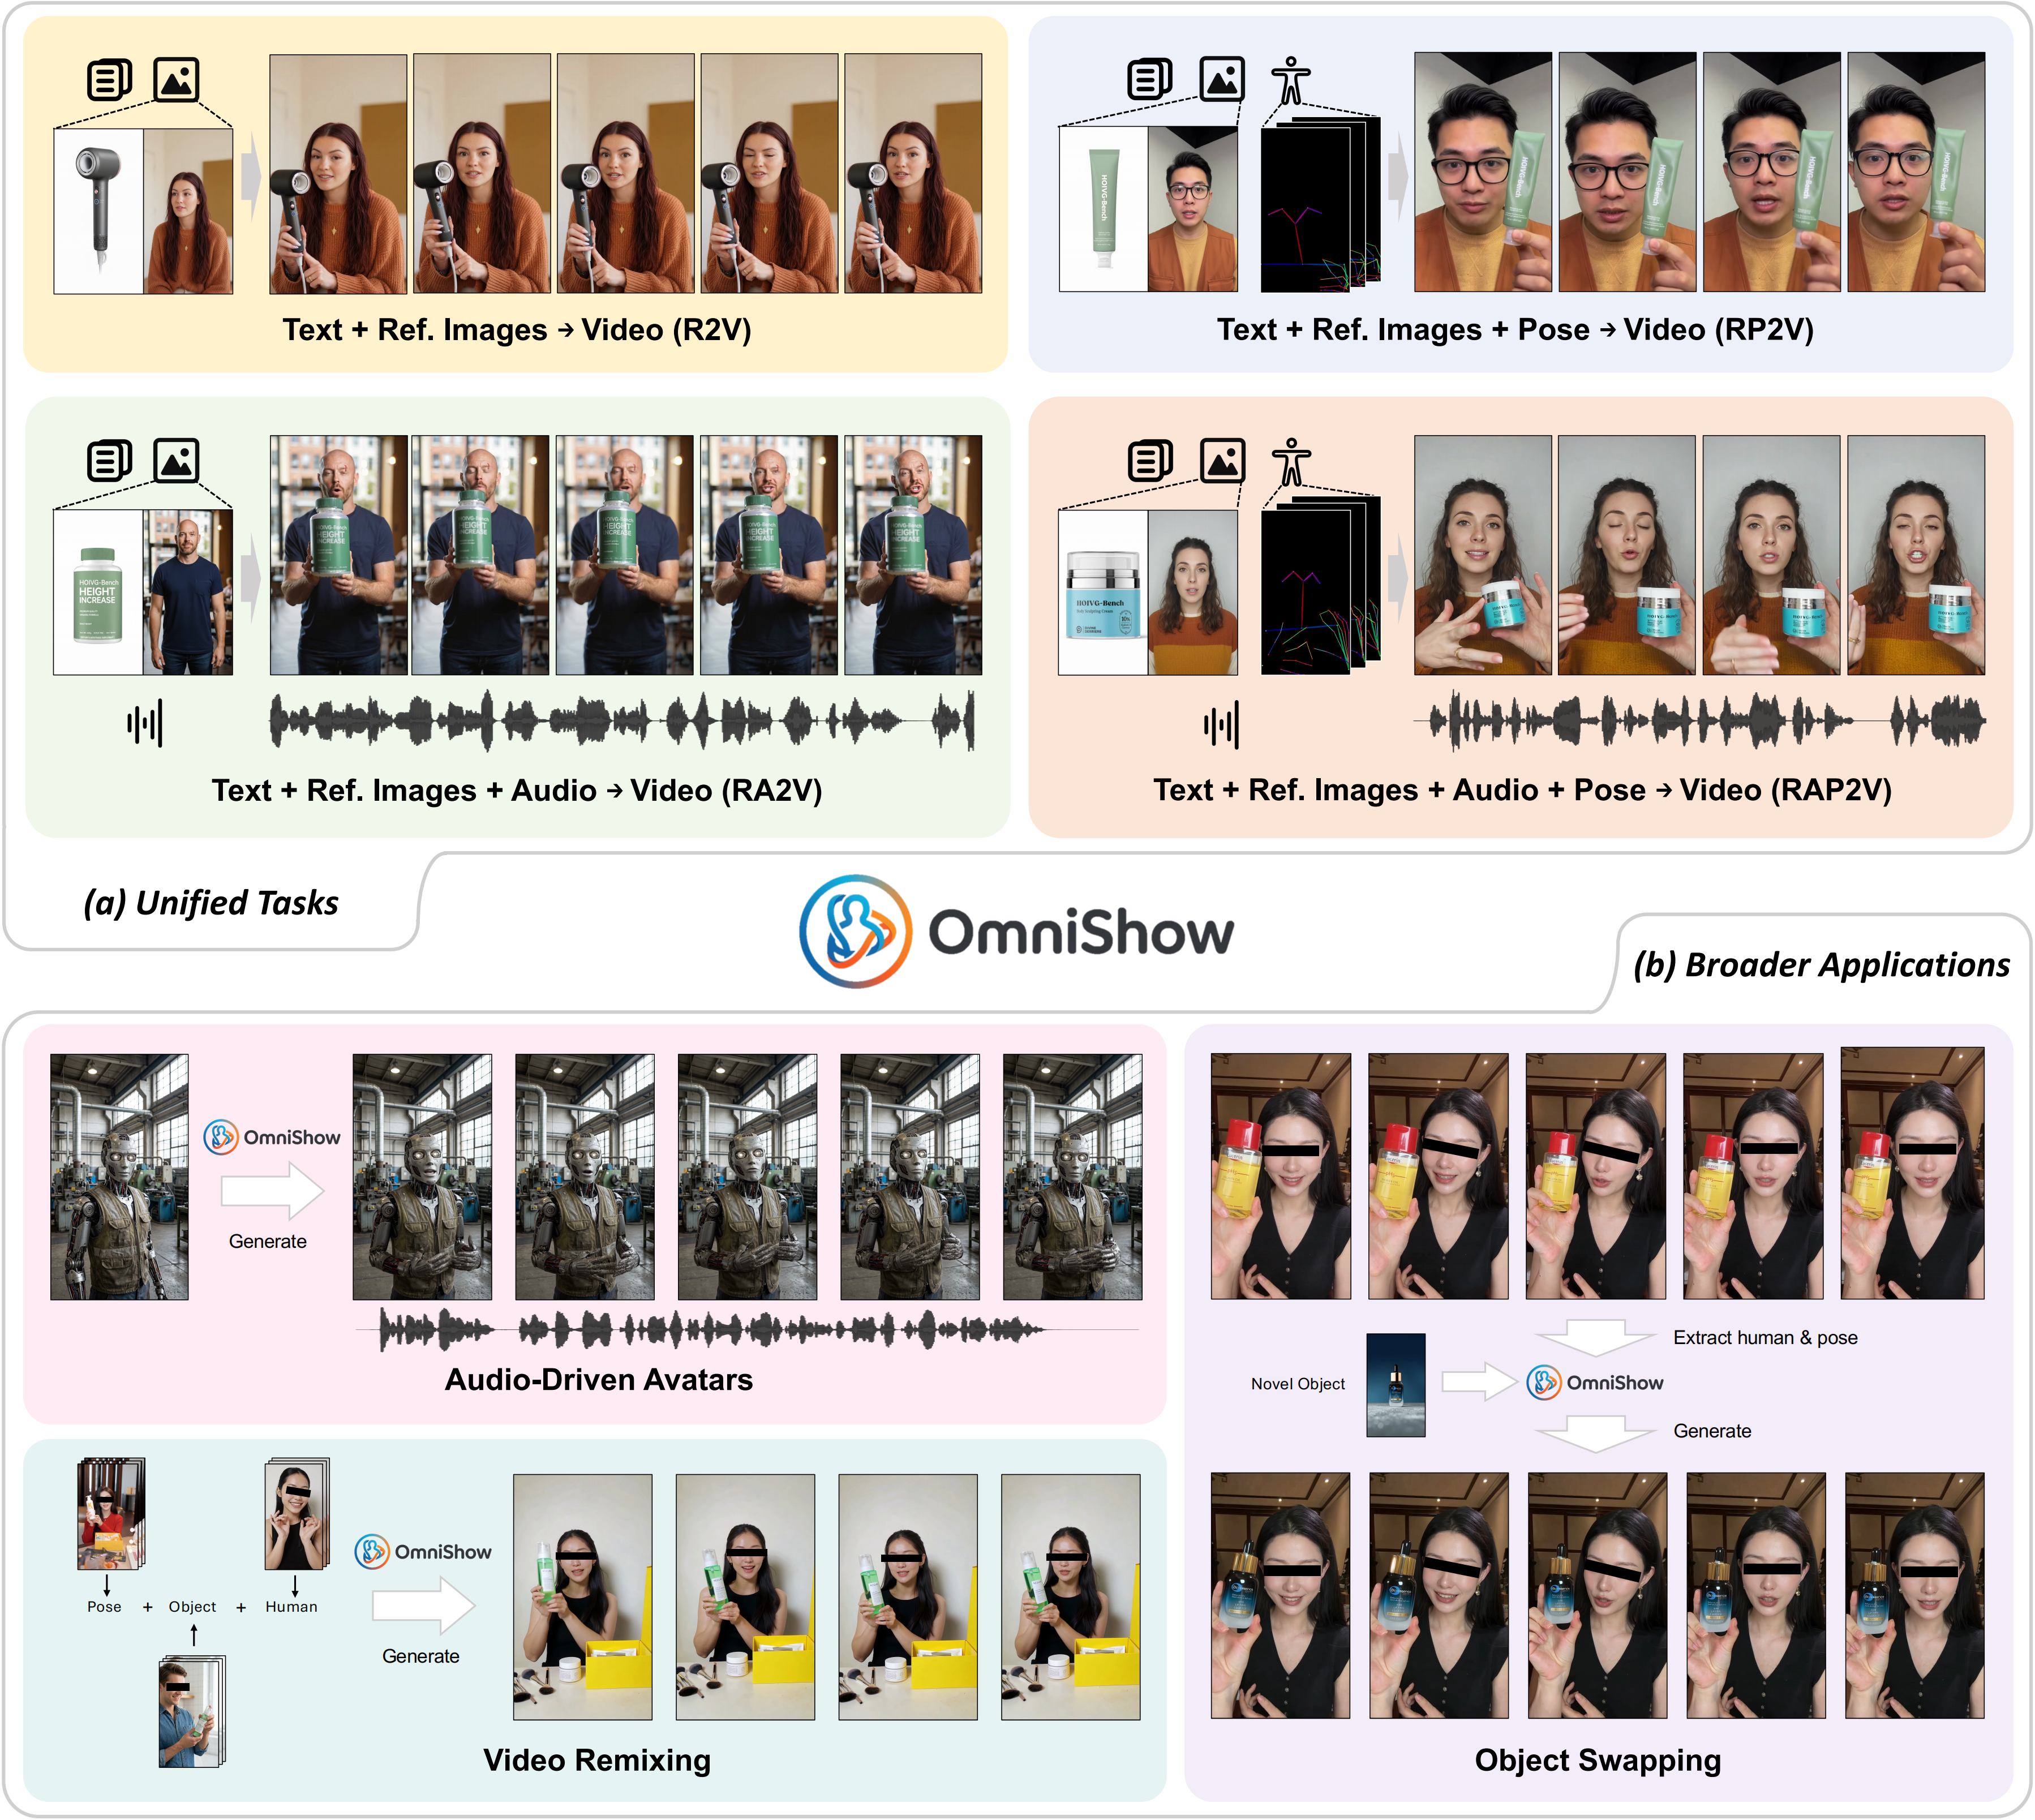
[ICML 2026] ByteDance's All-in-One Video Generation Model for Human-Object Interaction Video Generation
- Multimodal Controllable Model: OmniShow is the first all-in-one model for Human-Object Interaction Video Generation (HOIVG) with text, reference image, audio, and pose conditioning.
- Flexible Task Coverage: A single model supports R2V, RA2V, RP2V, and RAP2V generation within one coherent framework.