
free-data-science-books
chaconnewu
3,026estrellas

Free resources for learning data science
Compara bases de datos, análisis, SQL y proyectos de ingeniería de datos.
chaconnewu
Free resources for learning data science

chaisql
Modern embedded SQL database

change-metrics
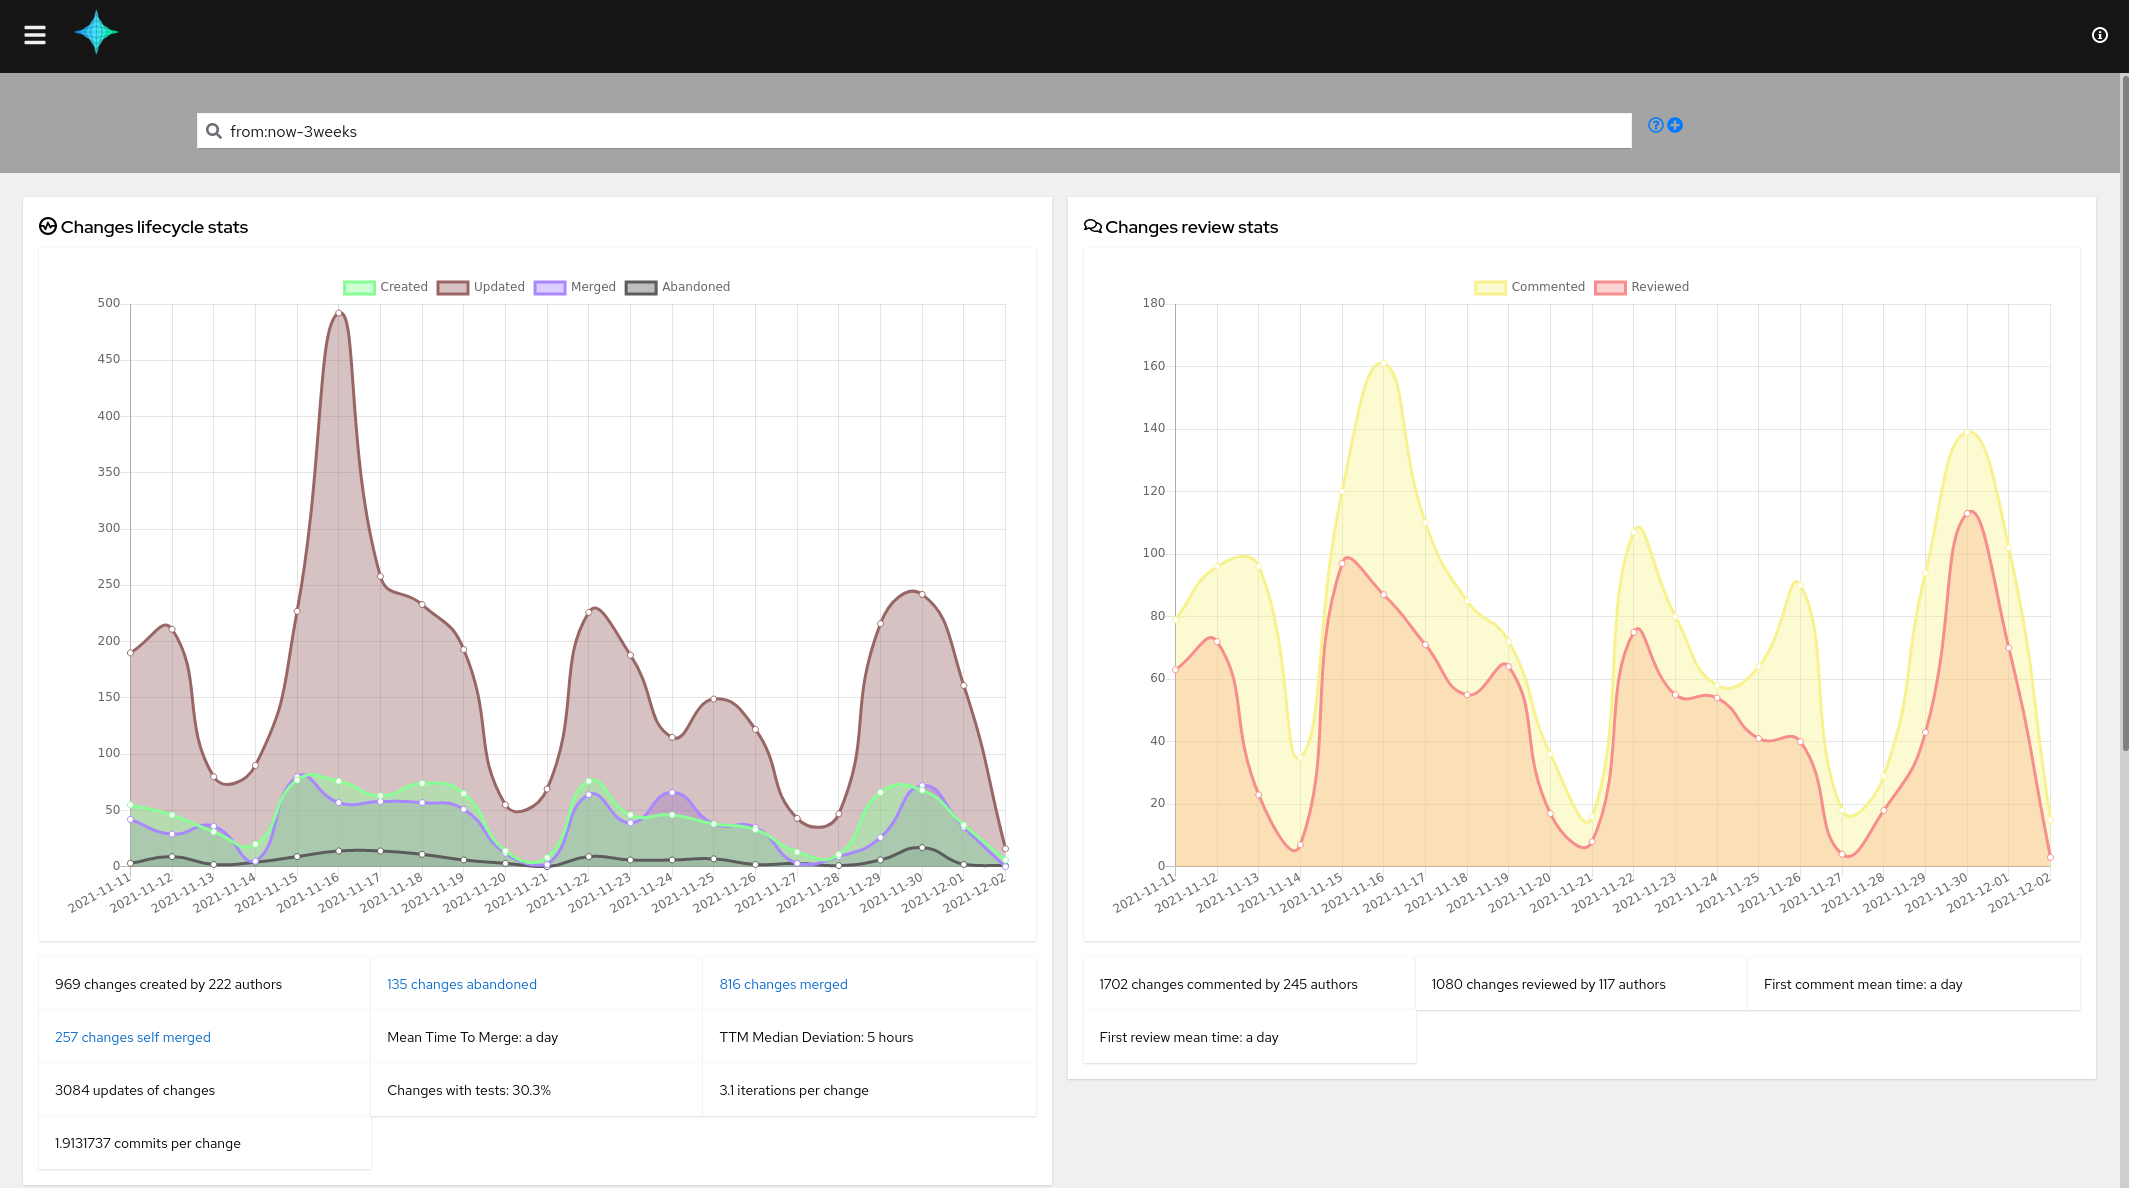
Monocle helps teams and individual to better organize daily duties and to detect anomalies in the way changes are produced and reviewed.

chapin666
Awesome Books

charles-001

Your single pane of glass for real-time analytics into MySQL/MariaDB & ProxySQL

chartbrew
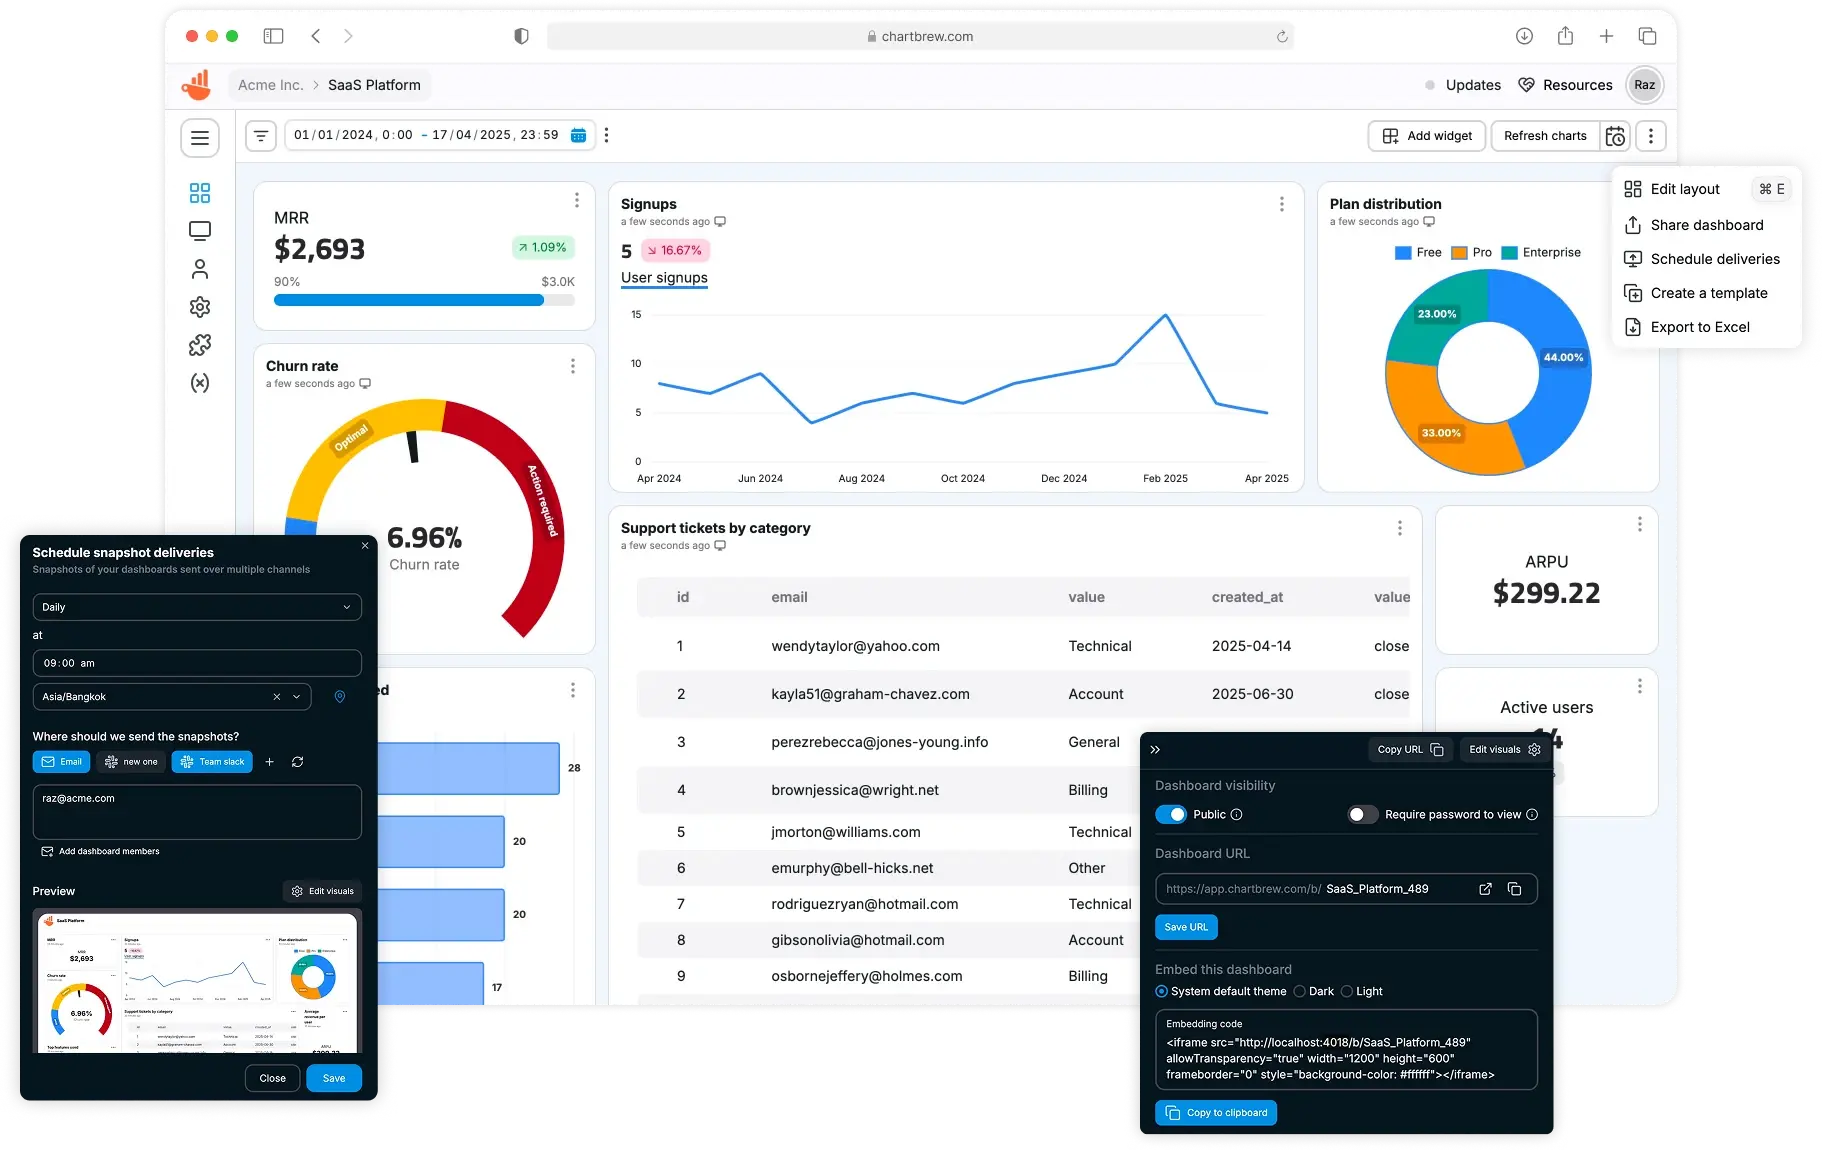
Open-source reporting platform to build and share live dashboards from APIs, SQL and NoSQL databases, with powerful AI assistant, scheduling, and embeddable charts 📈📊

chartdb
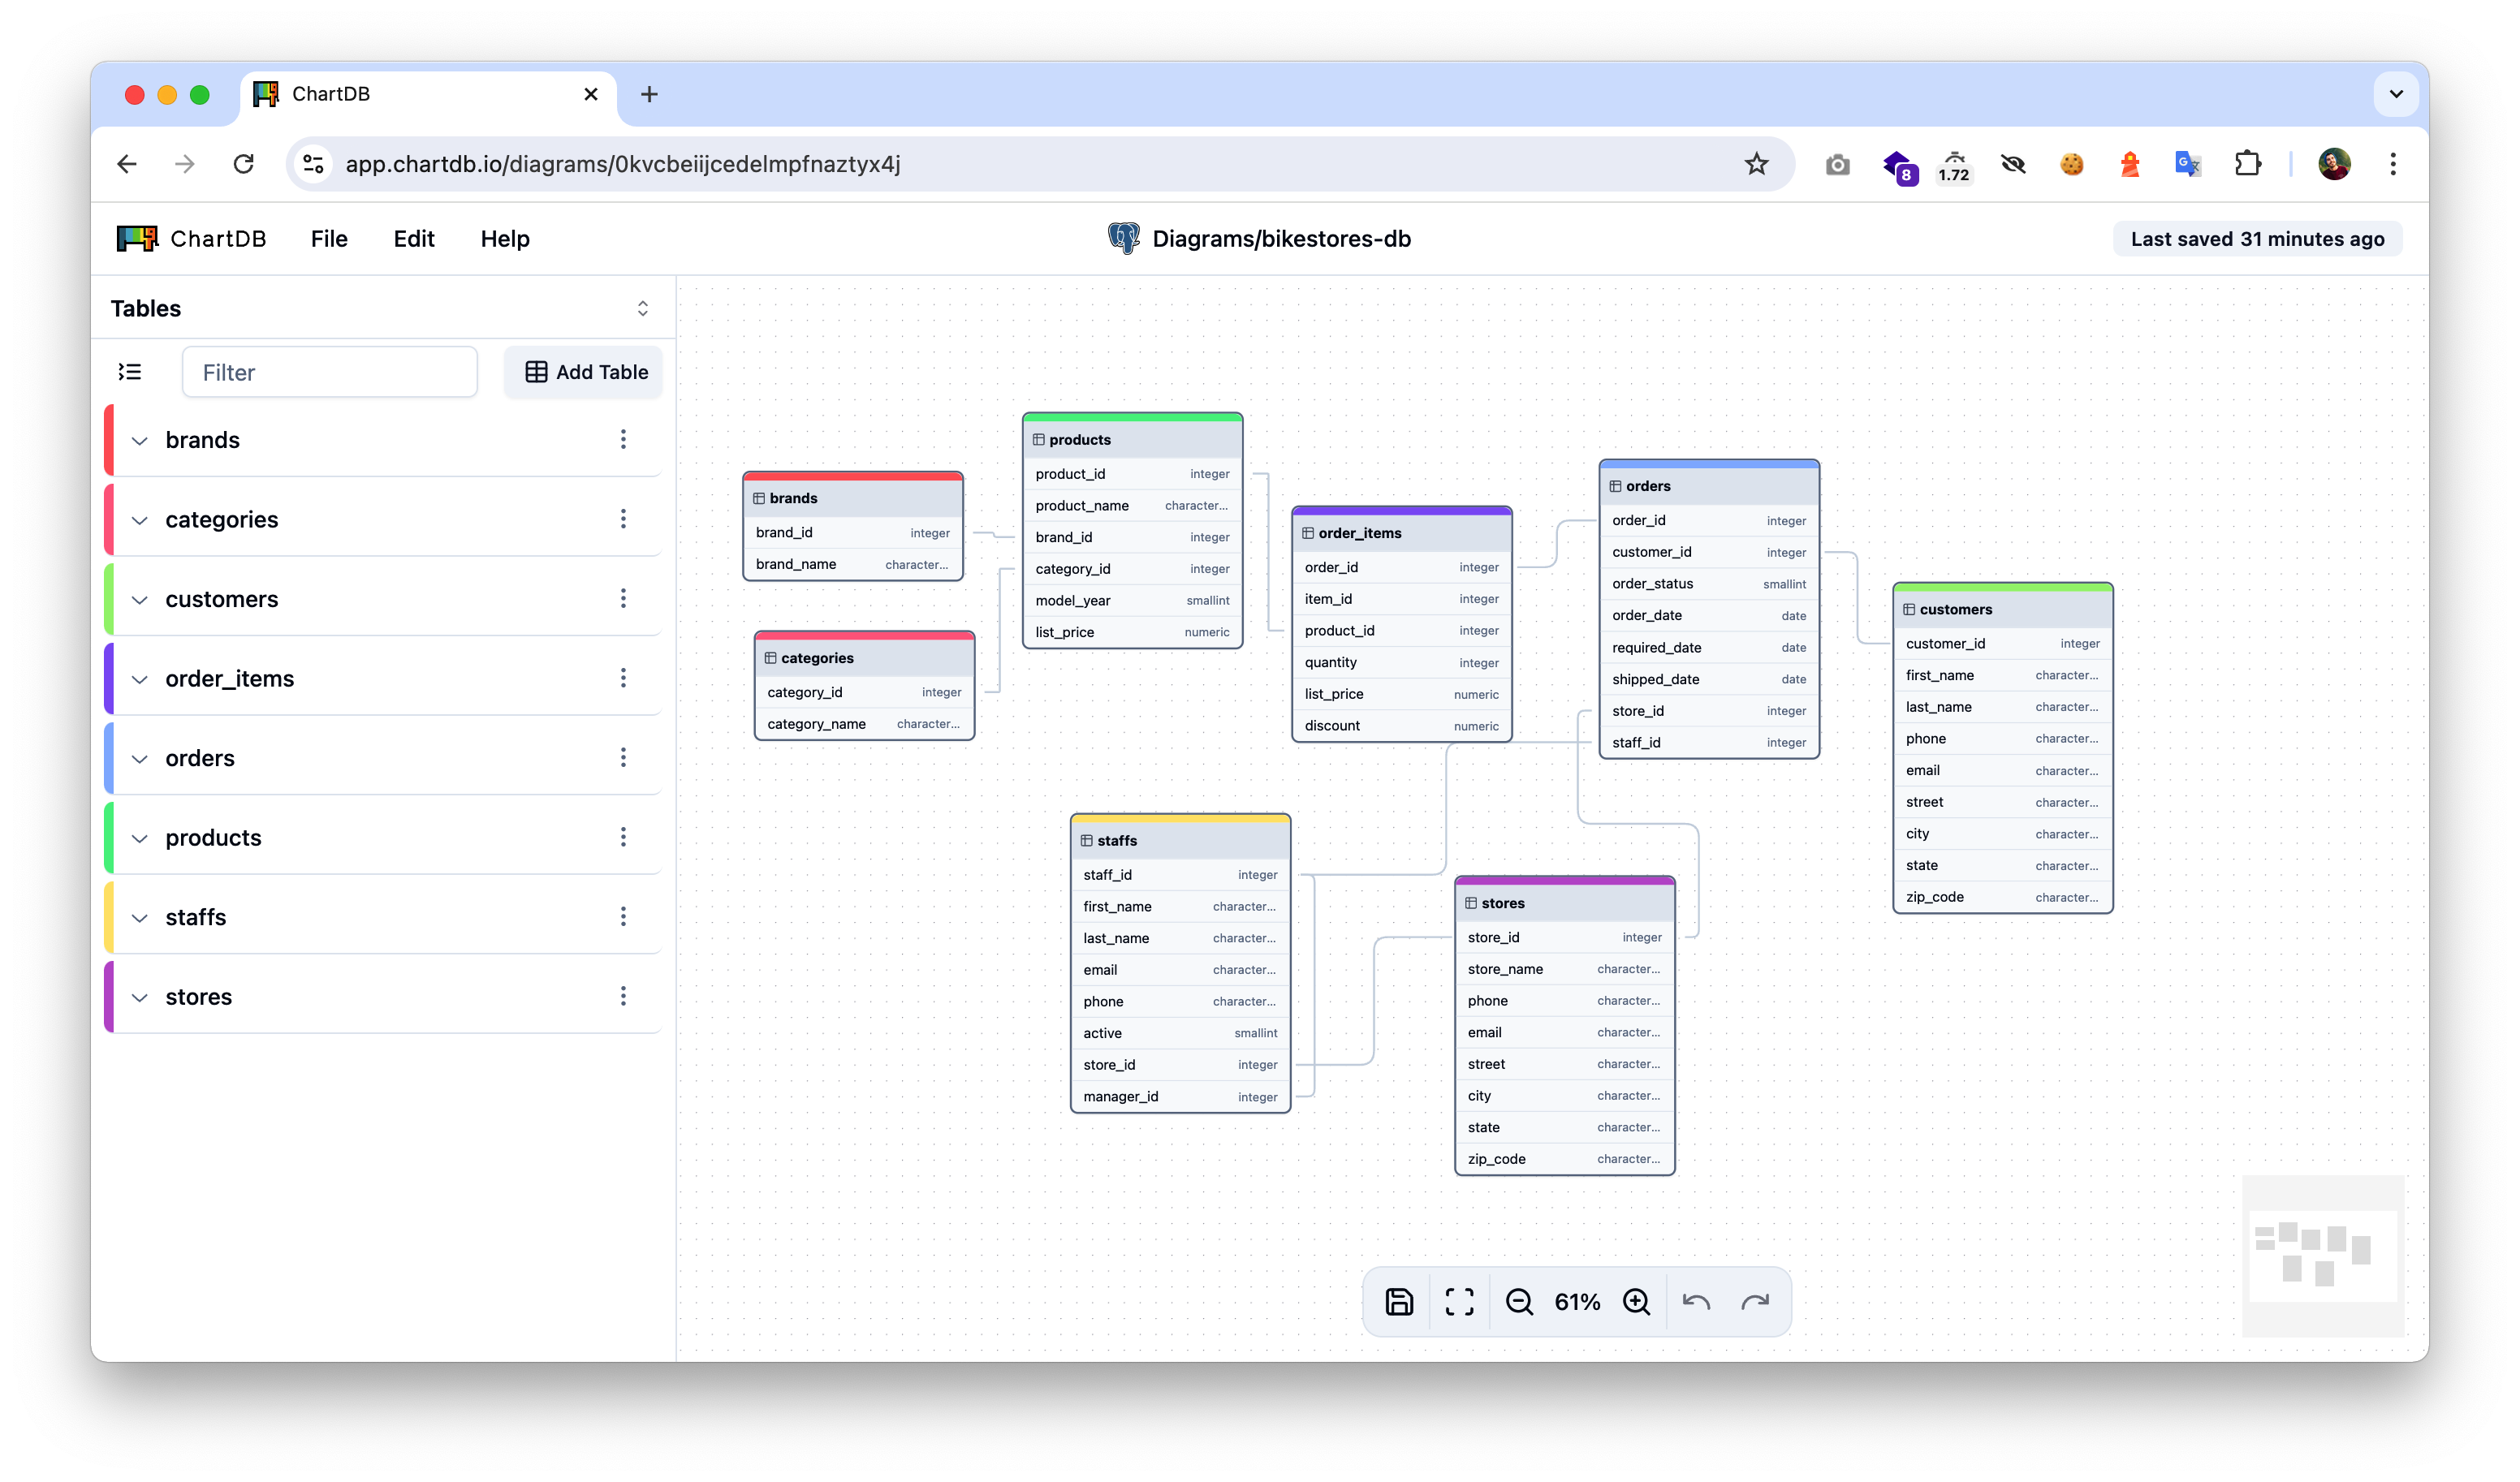
Editor de diagramas de bases de datos que permite visualizar y diseñar tu base de datos con una sola consulta.

ChawlaAvi
A collection of code snippets from the publication Daily Dose of Data Science on Substack: http://www.dailydoseofds.com/
This project demonstrates how to build and automate an ETL pipeline using DAGs in Airflow and load the transformed data to Bigquery. There are different tools that have been used in this project such as Astro, DBT, GCP, Airflow, Metabase.

chdb-io

chDB is an in-process OLAP SQL Engine 🚀 powered by ClickHouse

chennaione
Insanely easy way to work with Android Database.

ChimeHQ
Library for interacting with MetricKit

chinese-poetry

La base de datos más completa de poesía clásica china 🧶, con cerca de 14.000 poetas de las dinastías Tang y Song, casi 55.000 poemas Tang y 260.000 poemas Song. También incluye 1.564 poetas de ci y 21.050 poemas ci del periodo de las dos dinastías Song.

chinnonsantos
SQL de todos os Países e Nações (c/ Código do Portal do Comércio Exterior ou BACEN) + Estados e Federações Brasileiras (c/ DDD e Código do IBGE) + Cidades e Municípios Brasileiros (c/ Código do IBGE), incluindo as 31 regiões administrativas do DF, Ilhas e Áreas Remotas do Mundo.

chiphuyen
A booklet on machine learning systems design with exercises. NOT the repo for the book "Designing Machine Learning Systems", which is `dmls-book`
chiphuyen

Claude Code dashboard with usage stats, error analysis, and sharable feature

ChristianTremblay
Pyhaystack is a module that allow python programs to connect to a haystack server project-haystack.org. Connection can be established with Niagara Platform running the nhaystack, Skyspark and Widesky. For this to work with Anaconda IPython Notebook in Windows, be sure to use "python setup.py install" using the Anaconda Command Prompt in Windows. If not, module will be installed for System path python but won't work in the environment of Anaconda IPython Notebook. You will need hszinc 1.3+ for this to work.

chroma-core

Infraestructura de búsqueda para la IA

ChuckPa
Database repair utility for Plex Media Server databases

CHYbeta
Code-Audit-Challenges

ciaren-labs
Open-source, local-first visual ETL and data pipeline builder. Drag-and-drop data prep and ML workflows, preview every step, schedule runs, and export clean pandas or Polars Python code. Self-hosted, no lock-in.

cinemagoer
Cinemagoer is a Python package useful to retrieve and manage the data of the IMDb (to which we are not affiliated in any way) movie database about movies, people and characters

circuithub

Hey! Hey! Can u rel8?

citusdata
PostgreSQL distribuido como extensión
