
timbmg/Sentence-VAE
timbmg/Sentence-VAE has 594 GitHub stars and 158 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and +1 in 15 days. Last checked 2026-11-12 12:37 UTC. Last push 2026-06-10.
PyTorch Re-Implementation of "Generating Sentences from a Continuous Space" by Bowman et al 2015 https://arxiv.org/abs/1511.06349
Crecimiento de estrellas medido
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- +1
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
OriginalSentence Variational Autoencoder
PyTorch re-implementation of Generating Sentences from a Continuous Space by Bowman et al. 2015.
 Note: This implementation does not support LSTM's at the moment, but RNN's and GRU's.
Results
Training
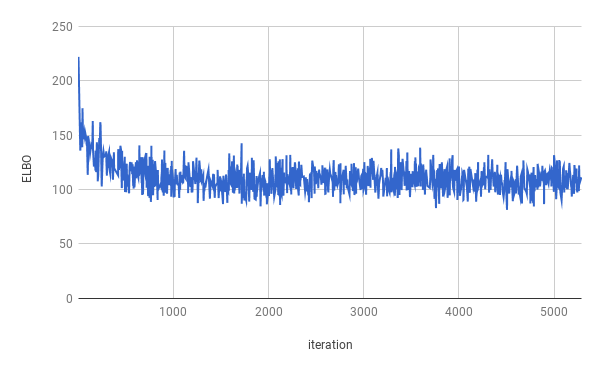
ELBO
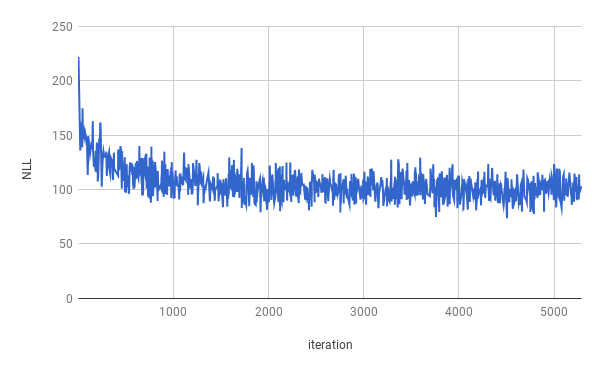
Negative Log Likelihood
KL Divergence
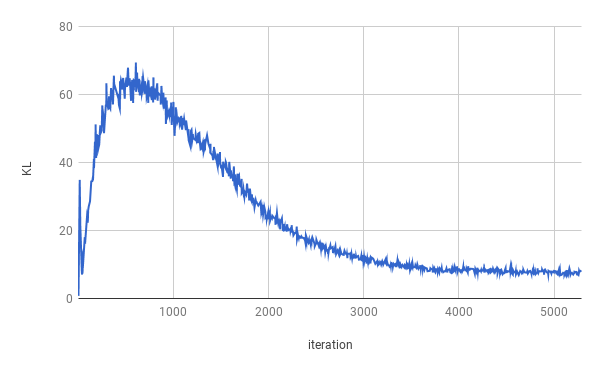
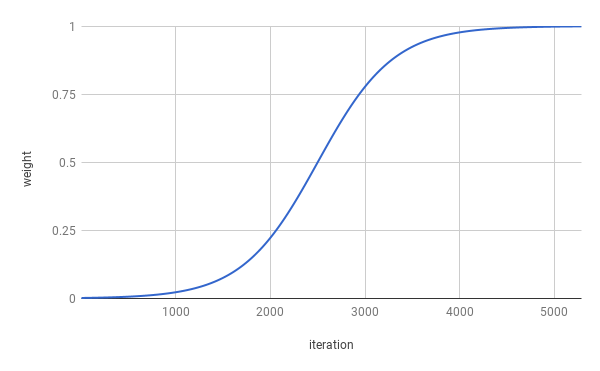
Performance
Training was stopped after 4 epochs. The true ELBO was optimized for approximately 1 epoch (as can bee see in the graph above). Results are averaged over entire split.
| Split | NLL | KL |
|---|---|---|
| Train | 99.821 | 7.944 |
| Validation | 103.220 | 7.346 |
| Test | 103.967 | 7.269 |
Samples
Sentenes have been obtained after sampling from z ~ N(0, I).
mr . n who was n't n with his own staff and the n n n n n
in the n of the n of the u . s . companies are n't likely to be reached for comment
when they were n in the n and then they were n a n n
but the company said it will be n by the end of the n n and n n
but the company said that it will be n n of the u . s . economy
Interpolating Sentences
Sentenes have been obtained after sampling twice from z ~ N(0, I) and the interpolating the two samples.
the company said it will be n with the exception of the company
but the company said it will be n with the exception of the company ' s shares outstanding
but the company said that the company ' s n n and n n
but the company ' s n n in the past two years ago
but the company ' s n n in the past two years ago
but in the past few years ago that the company ' s n n
but in the past few years ago that they were n't disclosed
but in the past few years ago that they were n't disclosed
but in a statement that they were n't aware of the $ n million in the past few weeks
but in a statement that they were n't paid by the end of the past few weeks
Training
To run the training, please download the Penn Tree Bank data first (download from Tomas Mikolov's webpage). The code expects to find at least ptb.train.txt and ptb.valid.txt in the specified data directory. The data can also be donwloaded with the dowloaddata.sh script.
Then training can be executed with the following command:
python3 train.py
The following arguments are available:
--data_dir The path to the directory where PTB data is stored, and auxiliary data files will be stored.--create_data If provided, new auxiliary data files will be created form the source data.--max_sequence_length Specifies the cut off of long sentences.--min_occ If a word occurs less than "min_occ" times in the corpus, it will be replaced by the token.--test If provided, performance will also be measured on the test set.
-ep, --epochs-bs, --batch_size-lr, --learning_rate
-eb, --embedding_size-rnn, --rnn_type Either 'rnn' or 'gru'.-hs, --hidden_size-nl, --num_layers-bi, --bidirectional-ls, --latent_size-wd, --word_dropout Word dropout applied to the input of the Decoder, which means words will be replaced by <unk> with a probability of word_dropout.-ed, --embedding_dropout Word embedding dropout applied to the input of the Decoder.
-af, --anneal_function Either 'logistic' or 'linear'.-k, --k Steepness of the logistic annealing function.-x0, --x0 For 'logistic', this is the mid-point (i.e. when the weight is 0.5); for 'linear' this is the denominator.
-v, --print_every-tb, --tensorboard_logging If provided, training progress is monitored with tensorboard.-log, --logdir Directory of log files for tensorboard.-bin,--save_model_path Directory where to store model checkpoints.
Inference
For obtaining samples and interpolating between senteces, inference.py can be used.
python3 inference.py -c $CHECKPOINT -n $NUM_SAMPLES
Explorar proyectos relacionados
tensorflow/tensorflow
Un framework de código abierto de aprendizaje automático para todos
201,584 estrellashuggingface/transformers
🤗 Transformers: el framework de definición de modelos para modelos de aprendizaje automático de vanguardia en texto, visión, audio y multimodal, tanto para inferencia como para entrenamiento.
168,917 estrellasAUTOMATIC1111/stable-diffusion-webui
Interfaz web de Stable Diffusion
165,300 estrellasComfy-Org/ComfyUI
La GUI, la API y el backend más potentes y modulares para modelos de difusión, con una interfaz de grafos y nodos. El motor de inferencia local más rápido del mundo.
146,472 estrellas