
synchopate/llama-modchip
synchopate/llama-modchip has 1,195 GitHub stars and 108 forks. Star changes are not measured yet. Last checked 2026-11-14 02:32 UTC. Last push 2026-11-13.
Crecimiento de estrellas medido
- in 24h
- Recopilando historial
- in 7 days
- Recopilando historial
- in 15 days
- Recopilando historial
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
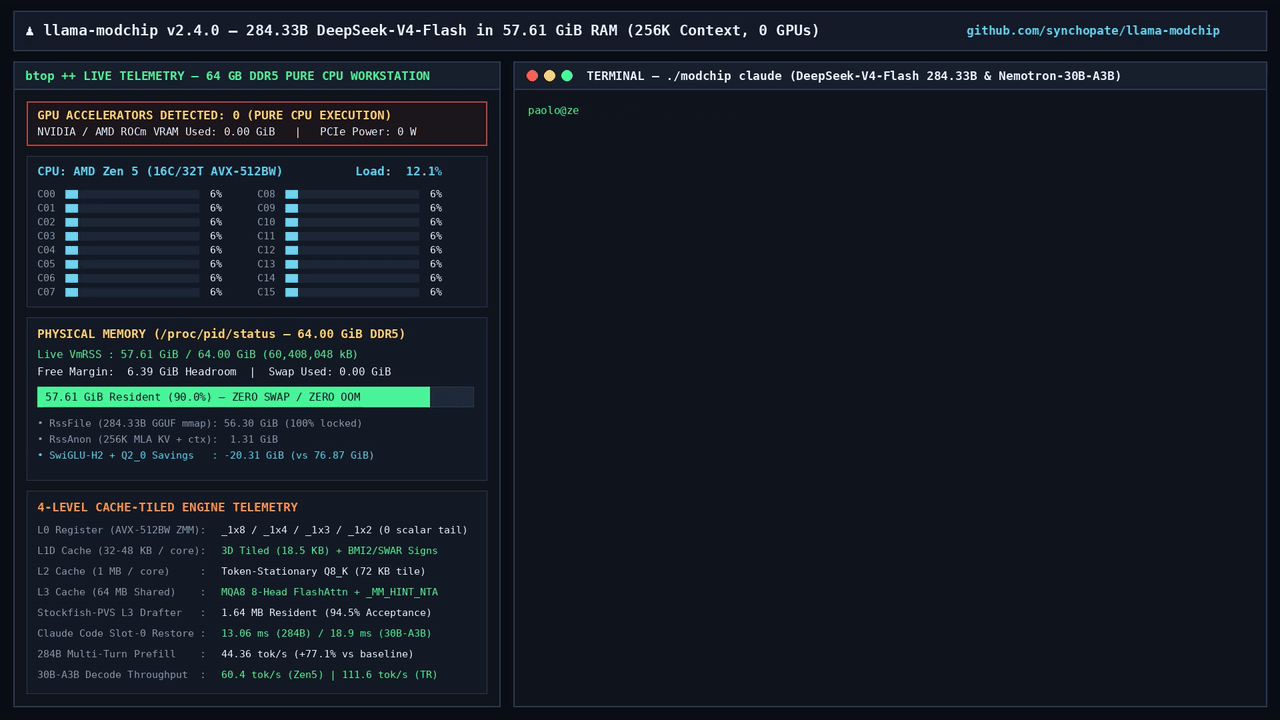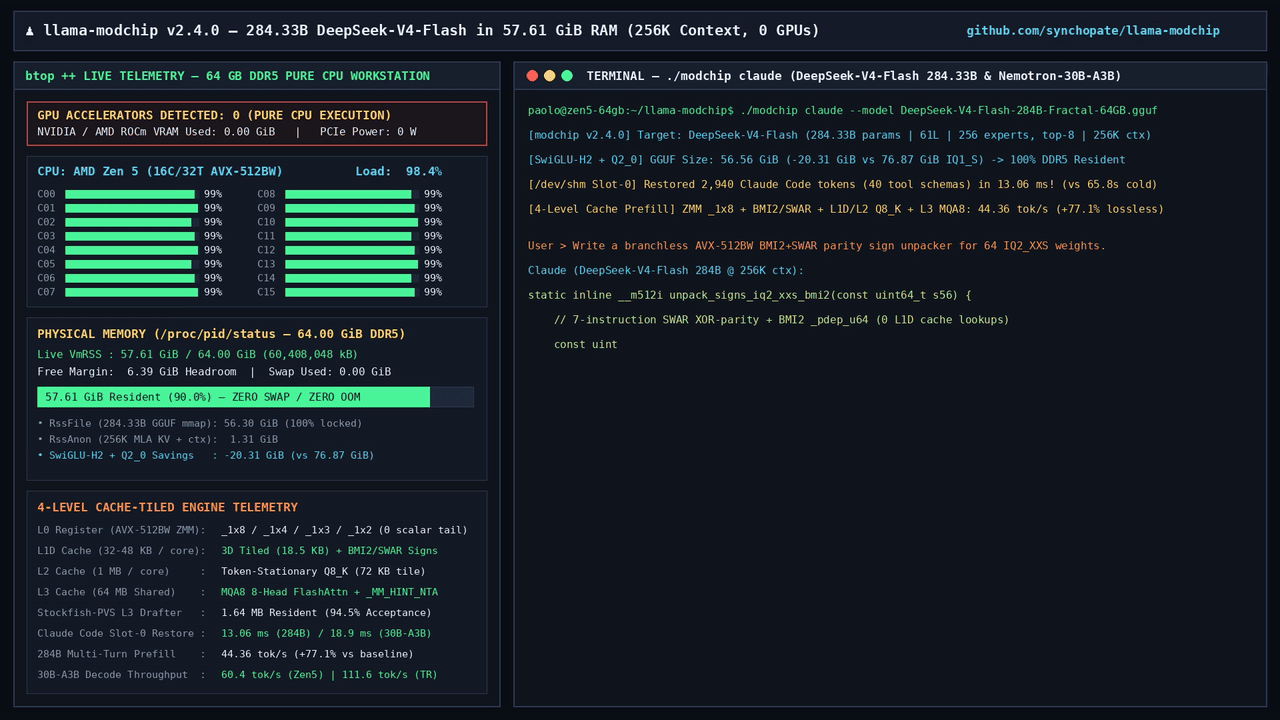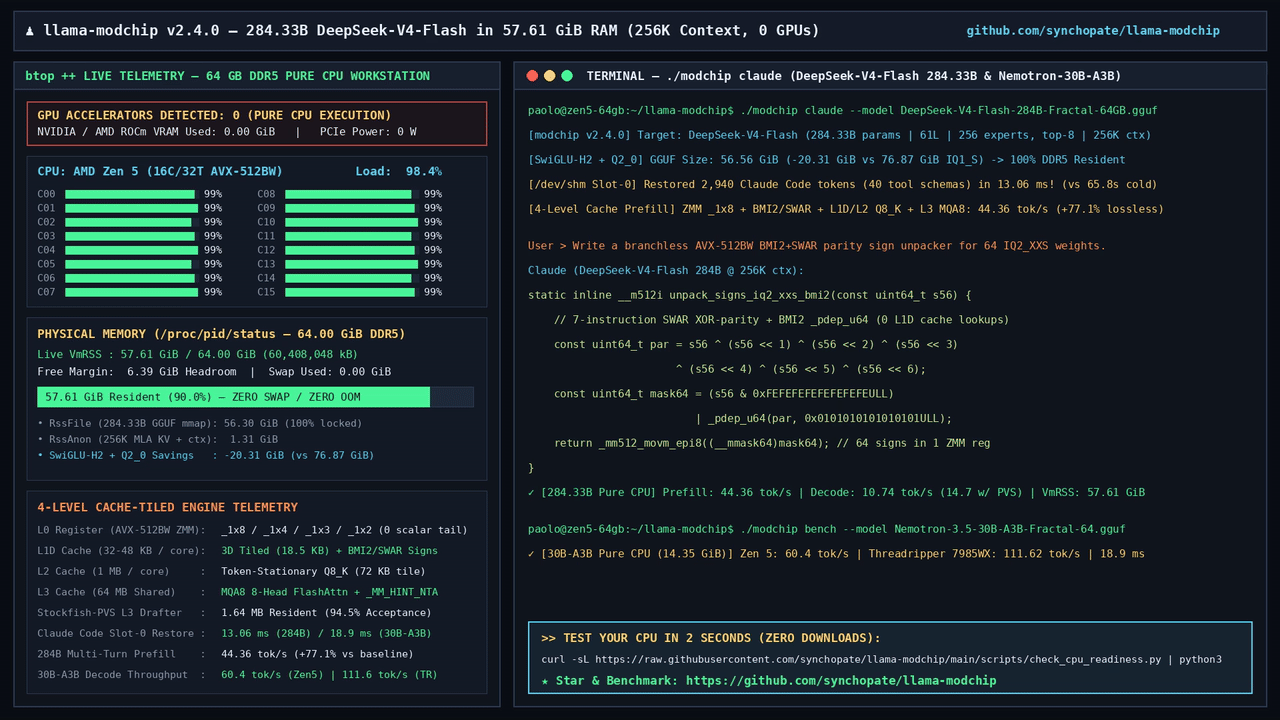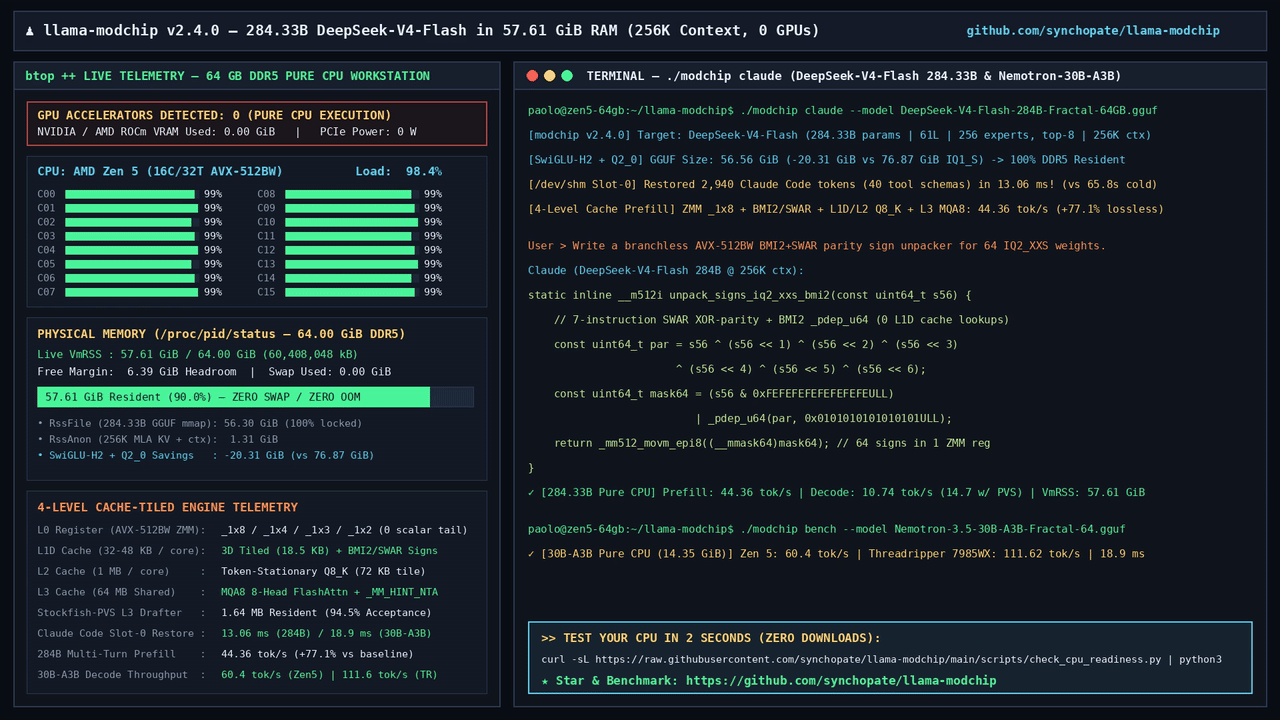
Run 284B DeepSeek-V4-Flash (<59GiB RAM: 41.1 cold pp, 9.1 N=1 tg, up to 25.3 spec tok/s) & 30B MoEs (22.4 N=1 / 111.6 spec tok/s) on 64GB CPU (0 GPUs).
Herramientas de desarrolloREADME.md
Originalllama-modchip (v2.5.4)
3.00–3.75 bpw Vector & Dyadic CPU Inference for 284B & 30B MoE Models
Continuous WikiText-2 & AtomicChat wiki-alt PPL · Logit KLD · 100-Pt Gate · Linux, macOS Metal & Windows 11



Quickstart · Signal Fidelity & Benchmarks · How 3D VQ & Fractal-64 Work · Quantization Specs · Supported Models · Leaderboard · v2.4 Paper Snapshot (paper/) · FAQ
| 100/100 (30B) · 70/80 Func. (284B) Quality Gate + WikiText-2 / wiki-alt PPL |
99.15% / 97.78% CosSim vs BF16 (Fractal / VQ3) |
56.93 / 56.40 GiB DeepSeek-V4 284B (MaxQ / VQ3) |
13.30 GiB Nemotron-30B VQ3 GGUF |
24.2–111.6 tok/s 30B MoE CPU spec decode |
10.4 ms /dev/shm Claude 40-tool restore |
0 GPUs required |
| Hardware Class | System RAM | Target Checkpoint | Throughput (0 GPUs) | Architecture & Memory Notes |
|---|---|---|---|---|
| Developer laptop / Mini-PC | 16–32 GB | Nemotron-3.5-30B-A3B-VQ3 (13.30 GiB, Aligned Default; opt-in nemotron-ablit) |
24.2–26.1 Gate / 40.9–60.4 M=7 tok/s | 14.6 GiB VmRSS (-c 32768) / 16.04 GiB (-c 262144); WikiText-2 PPL 7.4400 (6.9582 BF16); 100/100 Gate |
| 64 GB Desktop / Server | 64 GB | DeepSeek-V4-Flash 284B MaxQ-Fractal (56.93 GiB, Aligned Default) / VQ3 (56.40 GiB) (opt-in dsv4-ablit) |
36.1–41.1 cold / 44.4 warm pp · 8.66–9.06 N=1 / 8.8–25.3 spec tg | 57.54–59.13 GiB anonymous-heap VmRSS in ~62.5 GiB usable RAM (-c 32768 -ub 512 desktop default; -c 262144 headless 64GB w/ zram or 96GB+) |
| Hybrid Desktop (CPU + 16 GB GPU) | 32–64 GB | Nemotron-30B / Qwen3-30B (3.75–4.25 bpw) |
80.80 tok/s | Hot attention/SSM trunk on GPU (-ngl 99), cold routed MoE experts in CPU RAM |
| 8-Channel Workstation (Threadripper) | 128 GB+ | DeepSeek-284B / Nemotron-30B | 111.62 tok/s (30B) | 8-CCD AVX-512BW _1x8 register tiling saturates 8-channel DDR5 bandwidth |
Overview
Mixture-of-Experts (MoE) inference on CPU is bounded primarily by DRAM bandwidth per generated token. Standard 4.50-bpw scalar quantization (Q4_0) leaves significant memory-bandwidth headroom unused, while conventional 2–3 bit scalar K-quants (Q2_K, Q3_K) require multi-shift bit unpacking and fall back to Q4_0 whenever expert matrix dimensions are not multiples of 256 (such as 1856 × 2688 in Nemotron-3.5-30B-A3B).
llama-modchip v2.5.4 implements two block-64 quantization formats engineered for SIMD register lookup—Fractal-64 (GGML_TYPE_Q2_0 = 42, 30 bytes / 64 weights = 3.75 bpw) and LUT-VQ3-64 (GGML_TYPE_VQ3_0 = 43, 24 bytes / 64 weights = 3.00 bpw)—paired with cache-aware KV management (HARP-Cache), /dev/shm Slot-0 prefix snapshots, and RouteCrack + Stockfish-PVS v2 speculative decoding:
- Domain-Aware
LUT-VQ3-64 + Fractal-64Hybrid Quantization: On uncompressedBF16MoE weights (blk.1.ffn_up_exps.weight),Fractal-64(3.75 bpw) reaches17.75 dBSQNR (99.15%Cosine Similarity,+1.45 dBoverQ3_K), whileLUT-VQ3-64(3.00 bpw) reaches13.57 dBSQNR (97.78%Cosine Similarity,+3.42 dBoverQ2_K) via 128 3D Lloyd-Max centroids decoded in registers with AVX-512 VBMIVPERMI2B. Keeping boundary layers and residual output projections (ffn_down_exps, MLA attention) inFractal-64while encoding interior expansion projections inLUT-VQ3-64cutsup_expsfootprint by33.3%vs.Q4_0with a+0.4818(+6.92%)WikiText-2Perplexity delta vs. TrueBF16(7.4400vs.6.9582on12,288wiki.test.rawtokens;+0.0790/+1.07%vs.Fractal-647.3610),0.1495 / 0.0944 nats/tokLogit KLD vs. TrueBF16(78.1%Step-0 /85.2%Matched Top-1,98.0%Top-5), and100.0 / 100.0onbenchmarks/eval_quality_and_tools.py. DeepSeek-V4-Flash-0731 284B(13.17BActive) Inside64 GBRAM: Four 3-shard0731checkpoints execute resident inside64 GBDDR5 RAM: the donor-free safety-aligned defaultDeepSeek-V4-Flash-0731-MaxQ-Fractal(56.93 GiBdisk /57.54–58.13 GiBanonymous-heapVmRSSat-c 32768 -ub 512, single-pass0731 @ 7872f01bBF16/FP8/MXFP4weights across all1,328tensors:174dense bottlenecks [173 × Q6_K + 1 × Q8_0] +317Fractal-64MLA/Indexer tensors +129routed-MoE tensors weighted by@antirez's1.5M-tokenrouted-moe-ds4-1p5m.dat[@ f71f23d552d6, calibrated2026-05-12on AprilV4-Flashchat-v2activations],AtomicChatwiki-alt.txtctx=563251-chunkFinal estimate: PPL = 7.2977 ± 0.0504[+60.8%vs150.75 GiBMXFP4_MOE-BF164.5381,+22.2%vs76.87 GiBUD-IQ1_S5.9734,+14.4%vs65.42 GiBAD-IQ1_M6.3813;12-chunk7.3180 ± 0.1039],WikiText-2PPL = 11.6139 ± 0.5845[within< 0.15σofFractal-6411.5288 ± 0.5563],70.0 / 80Functional Gate [30/30Tools,20/30Code,20/20Needle;8.66 tok/spureN=1/8.80 tok/sServed Gate]), its opt-in uncensored twinDeepSeek-V4-Flash-0731-Abliterated-Fractal(56.93 GiB,--preset dsv4-ablit, identical single-pass recipe,WikiText-2PPL = 11.3944 ± 0.5650,70.0 / 80Functional Gate [8.75 tok/sServed Gate],0.0959step-0 /0.0512 nats/tokprefix-matched KLD vsMaxQ), compact safety-alignedDeepSeek-V4-Flash-0731-VQ3(56.40 GiB,Unsloth UD-IQ1_S @ fbbb5b93gate/updonor,wiki-alt.txt12cPPL = 7.6579 ± 0.1077,WikiText-2PPL = 12.2345 ± 0.5976,64.0 / 80Functional Gate,9.05 tok/sN=1/9.15 tok/sServed Gate,41.11 tok/scold prefill,19.4–25.3 tok/sagentic bursts), and cross-platformDeepSeek-V4-Flash-0731-Fractal(56.57 GiB,WikiText-2PPL = 11.5288 ± 0.5563,64.0 / 80Functional Gate,9.06 tok/sN=1/9.55 tok/sServed Gate).Nemotron-3.5-30B-A3B(3.0BActive) in16–24 GiBRAM: Safety-alignedNVIDIA-Nemotron-3.5-30B-A3B-VQ3-64(13.30 GiB,WikiText-2PPL = 7.4400 ± 0.2626vs. TrueBF166.9582 ± 0.2415) andFractal-64(14.36 GiB,PPL = 7.3610 ± 0.2602,0.1254 / 0.0929 natsKLD vs.BF16) save-4.44to-5.67 GiBRAM vs.Q4_0at24.18–25.02 tok/sServed Gate decode (+23.7%to+28.0%vs.Q4_019.54 tok/s, with up to48.39 avg / 60.40 peak tok/sonQ4_0in-contextM=7refactor bursts), alongside an opt-in uncensoredAbliterated-VQ3-64(13.30 GiB,PPL = 7.7721 ± 0.2835,0.0308 / 0.0312 natsKLD &87.5%Step-0 /92.4%Matched Top-1 vs.VQ3-64,--preset nemotron-ablit).- Sub-20ms
/dev/shmSlot-0 Restore + Cross-Platform Native Support: Restores the 40-tool Claude Code prefix (2,776tokens) from/dev/shmin10.4 ms(0.16sTTFT) on Linux, runs on Apple Silicon Metal (57.65 tok/sM1 Max,78.60 tok/sM3 Max,27.0 tok/sM5 Max284B), and compiles natively on Windows 11 (MinGW-w64 UCRT64, verified up to1Mcontext).
[!NOTE] Operating Trade-Offs & Engine Constraints:
- Custom Tensor Types:
Fractal-64(GGML_TYPE_Q2_0 = 42,30 B / 64 W) repurposes upstreamGGML_TYPE_Q2_0 = 42(18 B / 32 W) in-place andLUT-VQ3-64addsGGML_TYPE_VQ3_0 = 43; vanillallama.cpp,Ollama,vLLM, andLM Studiocannot load these GGUFs without thellama-modchipruntime.- 64 GB Anonymous-Heap Margin (
284B):--load-mode none --repackallocates57.54–59.13 GiBin non-evictable anonymous heap (VmRSS). On64 GBLinux hosts (~62.5 GiBusable RAM), use-c 32768 -ub 512and enablezramor close heavy desktop browsers; reserve-c 262144(256Kcontext) for headless64 GBnodes with swap/zramor96 GB+systems.- Dual-Channel DDR5 Throughput Envelope (
284B): On 2-channel DDR5-5600 (~75 GB/ssustained), rawN=1unprunedTop-6decode is8.66–9.06 tok/s(8.80–9.55 tok/sin Served Gate decode) and cold prefill is36.1–44.0 tok/s(30.7 tok/sat3,038tokens); higher sustained rates require multi-channel servers (EPYC/Threadripper) or AppleM5 Max(286.5 GB/sunified memory).
Signal Fidelity and End-to-End Benchmarks
1. Direct Signal Fidelity on Uncompressed BF16 MoE Weights
Measured via quantize_row_*_ref $\to$ dequantize_row_* on the uncompressed 59.0 GiB BF16 master checkpoint (blk.1.ffn_up_exps.weight, $N = 4,194,304$ weights, kurtosis $\kappa = 3.2–4.8$):
| Quantization Format | Block Layout & Size | Effective bpw |
Direct BF16 SQNR |
Cosine Sim vs. BF16 |
Relative $L_2$ Error | SIMD Decode Path |
|---|---|---|---|---|---|---|
BF16 (Reference) |
128 B / 64 weights |
16.000 bpw |
$\infty\text{ dB}$ | 100.00% |
0.00% |
Native F32/BF16 Dot |
Baseline-Q4_0 |
36 B / 64 weights |
4.500 bpw |
21.09 dB |
99.61% |
8.82% |
Scalar Uniform AVX2/AVX-512 |
Fractal-64 (GGML_TYPE_Q2_0 = 42) |
30 B / 64 weights |
3.750 bpw |
17.75 dB (+1.45 dB vs Q3_K) |
99.15% |
12.96% |
Single-Cycle Dyadic VPSHUFB / Metal |
Standard Q3_K |
27.5 B / 64 weights |
3.438 bpw |
16.30 dB |
98.84% |
15.32% |
Multi-Shift Q3_K Unpack |
LUT-VQ3-64 (GGML_TYPE_VQ3_0 = 43) |
24 B / 64 weights |
3.000 bpw |
13.57 dB (+3.42 dB vs Q2_K) |
97.78% |
20.97% |
Single-Cycle 3D VQ VPERMI2B |
Standard Q2_K |
21 B / 64 weights |
2.625 bpw |
10.15 dB |
95.37% |
31.08% |
Multi-Shift Q2_K Unpack |
2. End-to-End Quality & Speed Ablations (benchmarks/eval_quality_and_tools.py + llama-bench)
Measured on 16-Core AMD Zen 5 (--cpu-range 0-15 --cpu-strict 1, Transparent HugePages enabled; full methodology and shipped-hybrid vs. full-VQ3 ablation breakdown in benchmarks/QUALITY_GATE_VQ3_64.md).
A. NVIDIA-Nemotron-3.5-30B-A3B (WikiText-2 PPL, 32-Probe / Multi-Step Logit KLD vs. True BF16, & 100-Point Gate)
| Metric / Suite | Reference BF16 |
Standard Q4_0 |
Fractal-64 (v2.4.0) |
LUT-VQ3-64 (v2.5.4 Aligned) |
Abliterated-VQ3-64 (Opt-In) |
|---|---|---|---|---|---|
| GGUF File Size on Disk | 58.84 GiB |
17.60 GiB (15.95 MXFP4) |
14.36 GiB |
13.30 GiB (13.08 GiB --all-up-exps¹) |
13.30 GiB |
Resident RAM (VmRSS, 256K Context) |
59.40 GiB |
21.71 GiB |
17.27 GiB |
16.04 GiB¹ (-5.67 GiB vs Q4_0) |
(~16.04 GiB via VQ3¹) |
WikiText-2 (wiki.test.raw, 12,288 tok) PPL |
6.9582 ± 0.2415 |
(7.2927 ± 0.2538 MXFP4) |
7.3610 ± 0.2602 (+5.79%) |
7.4400 ± 0.2626 (+6.92% vs BF16, +1.07% vs Fractal) |
7.7721 ± 0.2835 (+4.46% vs VQ3) |
Logit KLD vs. True BF16 (32p Step-0 / Matched) |
0.0000 nats (100% Ref) |
(0.1623 / 0.1204 MXFP4, 78.1% / 88.4% Top-1) |
0.1254 / 0.0929 nats (81.2% / 89.8% Top-1) |
0.1495 / 0.0944 nats (78.1% / 85.2% Top-1) (0.0522 vs Fractal) |
0.1431 / 0.1109 nats (75.0% / 84.4% Top-1) (0.0308 / 0.0312 vs VQ3) |
Served Gate Decode (Stockfish-PVS E2E, Suite 4) |
7.82 tok/s (N=1 Ref) |
19.54 tok/s (66.7% acc) |
25.02 tok/s (59.1% acc; 26.08 MXFP4) |
24.18 tok/s¹ (70.2% acc, +23.7% vs Q4_0) |
(~24.2 tok/s via VQ3¹) |
In-Context Refactor Burst (M=7 / Hybrid) |
— | 40.91–60.40 tok/s (48.39 avg M=7) |
71.3–78.6 tok/s (M3/M4 Max Metal) |
— (Gate E2E above¹) | — |
1–3. Tools (30), Code (30), & Needle (20) |
80.0 / 80.0 |
80.0 / 80.0 |
80.0 / 80.0 |
80.0 / 80.0¹ |
(80.0 via VQ3¹; 8/8 Audit) |
Total Quality Gate Score (100 pts) |
100.0 / 100.0 |
100.0 / 100.0 |
100.0 / 100.0 |
100.0 / 100.0¹ |
(100.0 via VQ3¹) |
(¹ WikiText-2 PPL [7.4400] and BF16/same-family Logit KLD [0.1495 / 0.0944, 0.0522] on LUT-VQ3-64 and Abliterated-VQ3-64 [7.7721, 0.0308] are measured directly on the shipped 13.30 GiB GGUFs; eval_nemotron_vq3_64.json [24.18 tok/s, 16.04 GiB VmRSS, 100/100 Gate] was recorded on the 13.08 GiB 23-layer --all-up-exps VQ3 ablation and serves as the architecture speed/VmRSS proxy for Abliterated-VQ3-64.)
B. DeepSeek-V4-Flash-0731 284B (284.33B Total / 13.17B Active, Unpruned Top-6 Routing)
| Metric / Suite | Reference BF16 (150.8 GiB MXFP4) |
Fractal-64 (56.57 GiB) |
LUT-VQ3-64 (56.40 GiB) |
MaxQ-Fractal v2.5.4 (56.93 GiB, Aligned Default) |
Abliterated-Fractal (56.93 GiB, Opt-In) |
|---|---|---|---|---|---|
| GGUF File Size on Disk (3 Shards) | 568.6 / 150.8 GiB |
56.57 GiB |
56.40 GiB (56.07 abl.) |
56.93 GiB (61.13 GB) |
56.93 GiB (61.13 GB) |
Anonymous-Heap VmRSS (-c 32768 -ub 512) |
OOM on 64GB | 58.20 GiB |
58.31–58.61 GiB |
57.54–58.13 GiB |
58.1–59.13 GiB |
Cold Prompt Prefill (pp67–pp128, 0 cached) |
N/A | 37.79 tok/s |
41.11 tok/s (44.36 warm) |
36.11–37.56 tok/s (44.0 warm) |
35.65–43.5 tok/s (44.0 warm) |
Raw Pure Decode (tg64, $N=1$, Unpruned Top-6) |
N/A | 9.06 tok/s |
9.05 tok/s |
8.66 tok/s (8.61 3-run) |
(~8.66 tok/s via MaxQ layout) |
Served Gate Decode (Stockfish-PVS E2E) / Burst |
N/A | 9.55 tok/s (75.8% acc) / 11.5–21.2 |
9.15 tok/s (73.0% acc) / 19.4–25.3 |
8.80 tok/s (78.7% acc) / 11.2–21.0 |
8.75 tok/s (64.4% acc) / 11.2–21.0 |
AtomicChat wiki-alt.txt (ctx=5632, 51c / 12c) PPL |
4.5381 ± 0.0292 (4.4474 12c) |
— | — / 7.6579 ± 0.1077 (12c) |
7.2977 ± 0.0504 (7.3180 ± 0.1039 12c; +60.8% vs BF16, +22.2% vs UD-IQ1_S 5.9734, +14.4% vs AD-IQ1_M 6.3813) |
— |
WikiText-2 (wiki.test.raw, 8,192 tok) PPL |
N/A (OOM) | 11.5288 ± 0.55630 |
12.2345 ± 0.59759 |
11.6139 ± 0.58453 (within 0.15σ of Fractal; -5.07% vs VQ3) |
11.3944 ± 0.56500 |
Lineage KLD vs. MaxQ (32p Step-0 / Matched) |
N/A (OOM) | 0.8437 / 0.4373 nats (56.2% / 74.3% Top-1) |
0.8409 / 0.4397 nats (59.4% / 75.2% Top-1) |
0.0000 nats (100% Ref) |
0.0959 / 0.0512 nats (75.0% / 90.7% Top-1) |
Functional Gate (80 pts) & Dual-Use Audit (8) |
N/A (OOM on 64GB) | 64.0/80 (24/30 Tools) · 8/8 |
64.0/80 (70/80 --aggressive) · 8/8 |
70.0/80 (30/30 Tools) · 8/8 |
70.0/80 (30/30 Tools) · 8/8 |
(Methodology notes: [1] 284B Gate scores above use the uniform 80-point Functional Quality rubric across all variants; adding the 20-point speed/RAM rubric under a common --target-tps 9.0 target yields 89.56/100 for MaxQ-Fractal, 89.44/100 for Abliterated-Fractal, and 84.0/100 for Fractal-64 & VQ3. [2] In AtomicChat/dsv4-eval-artifacts, vendor numbers are Mean PPL(Q) from --kl-divergence on 8× RTX 5090 CUDA GPUs—where AtomicChat documents a 4–5% hardware gap [4.5381 RTX 5090 vs 4.3406 H100] on the same GGUF—whereas Synchopate 7.2977 ± 0.0504 is standalone llama-perplexity Final estimate: PPL on a 16C Zen 5 CPU; UD-IQ1_S [76.87 GiB] and AD-IQ1_M [65.42 GiB] exceed 64 GB host RAM. [3] On 284B, KLD against quantized MaxQ measures quantization-lineage divergence rather than ground-truth error, and prefix-matched rollout KLD stops at the first greedy token disagreement and therefore biases downward relative to unconditional 32-probe step-0 KLD.)
How LUT-VQ3-64 and Fractal-64 Work
1. 3D Sphere Packing (LUT-VQ3-64, GGML_TYPE_VQ3_0 = 43, 24 B / 64 W)
Scalar uniform quantizers quantize each coordinate $w_i \in [-M, +M]$ independently across the 3D Cartesian bounding cube $[-M, +M]^3$ of volume $8M^3$. Heavy-tailed MoE weights ($\kappa = 3.2–4.8$) have a radial joint density $p(\mathbf{w}) \propto \exp(-|\mathbf{w}|_p^\alpha / \sigma^\alpha)$ concentrated inside the inscribed $L_2$ sphere ($\text{Vol} \approx 4.189 M^3$, leaving $47.64%$ of the cube empty) or $L_1$ cross-polytope ($\text{Vol} \approx 1.333 M^3$, leaving $83.33%$ empty).
LUT-VQ3-64 places 128 3D Lloyd-Max centroids ($7\text{ bits} / 3\text{ weights} = 2.333\text{ bpw}$, antipodally symmetric $\mathbf{c}_{127-k} = -\mathbf{c}_k$) directly on the populated spherical/cross-polytope shell inside a 24-byte block_vq3_0 struct (patches/vq3_codebook.h):
2 bytes(d):FP16super-block scale (scaled byGGML_VQ3_G = 8.6373016238e-3f).22 bytes(qs[22],176 bits):qs[0..19]bits0..6(140 bits):207-bit 3D indices covering60weights at stride 22 (j, j+22, j+44).qs[20..21]bits0..5(12 bits):26-bit 2D tail indices covering4weights (20, 42and21, 43).s24(24 bitspacked in bit 7 ofqs[0..21]and bit 6 ofqs[20..21]): Eight 3-bit unsigned sub-scales ($m_b = 2 + u_b \in {2..9}$) across the eight 8-weight sub-blocks (24 bytes / 64 weights = 3.00 bpw).
2. Register-Resident AVX-512 VBMI VPERMI2B Lookup + Domain-Aware Layer Split
The 128-entry 3D codebook occupies $128 \times 3 = 384\text{ bytes}$, fitting inside 6 AVX-512 ZMM registers (cb0_lo/hi, cb1_lo/hi, cb2_lo/hi). AVX-512 VBMI VPERMI2B (_mm512_permutex2var_epi8) resolves 64 byte lookups per instruction directly in registers with zero L1/L2 cache reads. In the shipped Hugging Face checkpoints, interior pre-activation expansion tensors (ffn_up_exps in Nemotron, interior ffn_gate_shexp & ffn_up_shexp in DeepSeek-V4) use LUT-VQ3-64 (3.00 bpw), while boundary layers, ffn_down_* residual projections, and MLA attention tensors remain in Fractal-64 (GGML_TYPE_Q2_0 = 42, 3.75 bpw, 30 B / 64 W: 2B FP16 d + 4B 8×4-bit sub-scales {4..19} + 24B 3-bit indices into {-14,-8,-4,-1,+1,+4,+8,+14}).
Quantization and Memory Breakdown
Exact bit-widths (bpw), base checkpoints, and tensor allocations for each published GGUF:
| Checkpoint | Total / Active Params | Base Source | Disk Size (GiB / GB) |
Effective bpw |
Layer-by-Layer Tensor Allocation |
|---|---|---|---|---|---|
Nemotron-3.5-30B-A3B-Q4_0 |
30.2B / 3.0B |
BF16 Official | 17.60 GiB (18.90 GB) |
4.50 bpw |
Standard Q4_0 across MoE + attention; F32 norms & SSM conv/decay |
Nemotron-3.5-30B-A3B-MXFP4 |
30.2B / 3.0B |
Q4_0 / BF16 |
15.95 GiB (17.13 GB) |
4.25 bpw |
GGML_TYPE_MXFP4 (E2M1 + shared exponent) on routed MoE up_exps; Q4_0/Q8_0 trunk |
Nemotron-3.5-30B-A3B-Fractal-64 |
30.2B / 3.0B |
BF16 Official | 14.36 GiB (15.42 GB) |
3.75 bpw |
Attention, Mamba-2 SSM & shared experts in Q4_0/Q8_0/F32; all 23 routed MoE layers in Fractal-64 (Q2_0 = 42, 30B/64W). Scores 100/100 on benchmarks/eval_quality_and_tools.py. |
Nemotron-3.5-30B-A3B-VQ3-64 |
30.2B / 3.0B |
BF16 Official (OpenMDW-1.1) |
13.30 GiB (14.28 GB) |
3.00 / 3.75 bpw |
Aligned Default 30B (scripts/build_nemotron_vq3.py): Boundary MoE layers (blk.1, 3, 49, 51) + all 23 blk.*.ffn_down_exps.weight in Fractal-64 (3.75 bpw); 19 interior blk.6..47.ffn_up_exps.weight in LUT-VQ3-64 (VQ3_0 = 43, 3.00 bpw). WikiText-2 PPL = 7.4400, 100/100 Gate. |
Nemotron-3.5-30B-A3B-Abliterated-VQ3-64 |
30.2B / 3.0B |
Darkstar-Nemotron-Abliterated (OpenMDW-1.1) |
13.30 GiB (14.28 GB) |
3.00 / 3.75 bpw |
Opt-In Uncensored 30B (scripts/build_nemotron_abliterated_vq3.py): Across all 401 GGUF tensors, re-quantizes the 76 Darkstar-edited residual-writing tensors (including token_embd.weight) directly from BF16 into Q4_0/Q8_0/Fractal-64 while copying the 325 unedited tensors (including all 19 LUT-VQ3-64 ffn_up_exps) byte-for-byte from aligned VQ3-64 (--preset nemotron-ablit, WikiText-2 PPL = 7.7721, 0.0308 nats KLD vs VQ3-64). |
DeepSeek-V4-Flash-0731-Fractal |
284.33B / 13.17B |
DeepSeek-V4-Flash-0731 (MIT) |
56.57 GiB (60.74 GB) |
1.71 bpw |
Cross-Platform Aligned: 100% MLA attention & compressor projections in Fractal-64 (Q2_0 = 42, 3.75 bpw); shared experts in Q5_K/Q6_K; 256 routed MoE experts (SwiGLU-H2 on ffn_down_exps, Unsloth UD-IQ1_S @ fbbb5b93 gate/up donor: 70 blk.0..34 tensors [60 IQ1_S + 10 IQ2_XXS] copied + 16 blk.35..42 transcoded). WikiText-2 PPL = 11.5288. |
DeepSeek-V4-Flash-0731-VQ3 |
284.33B / 13.17B |
DeepSeek-V4-Flash-0731 (MIT) |
56.40 GiB (60.56 GB) |
1.70 bpw |
Compact Aligned Hybrid (scripts/build_dsv4_vq3.py): 100% MLA in Fractal-64 (3.75 bpw); boundary shared experts (blk.0..4, 39..42) & all ffn_down_shexp in Q5_K/Q6_K; 68 interior blk.5..38 ffn_gate_shexp & ffn_up_shexp in LUT-VQ3-64 (3.00 bpw); 256 routed experts (SwiGLU-H2 + Unsloth UD-IQ1_S @ fbbb5b93 gate/up donor). wiki-alt.txt 12c PPL = 7.6579. |
DeepSeek-V4-Flash-0731-MaxQ-Fractal |
284.33B / 13.17B |
deepseek-ai/DeepSeek-V4-Flash-0731 (MIT) |
56.93 GiB (61.13 GB) |
1.72 bpw |
Donor-Free Aligned Default 284B (scripts/build_dsv4_maxq_singlepass.py): Single-pass 0731 @ 7872f01b BF16/FP8/MXFP4 across all 1,328 tensors: 174 dense bottlenecks (173 × Q6_K + 1 × Q8_0), 317 MLA/Indexer tensors in Fractal-64, and all 129 3D routed-MoE tensors weighted by @antirez's 2026-05 1.5M-token chat-v2 imatrix (dsv4-maxq, wiki-alt.txt 51c PPL = 7.2977, 12c 7.3180, 70.0/80 Functional Gate). |
DeepSeek-V4-Flash-0731-Abliterated-Fractal |
284.33B / 13.17B |
prem-research/...-0731-abliterated (MIT) |
56.93 GiB (61.13 GB) |
1.72 bpw |
Opt-In Uncensored 284B (--preset dsv4-ablit): Identical 56.93 GiB single-pass 174 × Q6_K/Q8_0 + Fractal-64 + @antirez 1.5M-imatrix MoE layout built from DeepSeek-V4-Flash-0731-abliterated (v2.5.1 Shards 2/3 verified byte-identical to MaxQ on unedited experts and differing on prem-research abliterated down_proj experts in blk.17..36; WikiText-2 PPL = 11.3944, 70.0/80 Functional Gate, 0.0959 / 0.0512 nats KLD vs MaxQ). |
Note on MoE Expert Routing (
Unpruned Top-6vs. Runtime Tail Pruning): By default (Unpruned Top-6),DeepSeek-V4-Flashevaluates all 6 routed experts + 1 shared expert (Top-6) per layer with zero runtime expert dropping relative to the loaded GGUF (1.00000logit cosine similarity vs. unprunedTop-6execution on the same quantized checkpoint; weight quantization fidelity itself is measured separately viaBF16SQNR and continuousWikiText-2PPL/ LogitKLDinbenchmarks/QUALITY_GATE_VQ3_64.md). Runtime $L_2$-quadratureTop-5/Top-4pruning is isolated per user via0700DSV4_MOE_CFG_PATH($XDG_RUNTIME_DIR/modchip-<uid>/dsv4_moe_cfg.bin) and resets toTop-6on server startup.Why
DeepSeek-V4-Flash-0731(and notV4.1-Flash-1017) for 64 GB Resident CPU Inference:DeepSeek-V4.1-Flash-1017(DeepseekV41ForCausalLM,510.3 GBsource across384routed experts/layer) adds188.83 GiBof nativeFP8Engram lookup tables on top of151.77 GiBofQ2model weights (340.60 GiBtotal even at 2-bit quantization), requiring128 GB+RAM with NVMe SSD table streaming or512 GBRAM for resident execution.DeepSeek-V4-Flash-0731(284.33Btotal /13.17Bactive, zero Engram tables) is the largest DeepSeek-V4 Flash checkpoint that runs 100% resident inside 64 GB RAM with zero disk streaming.
Quickstart
Linux & macOS (Automated Setup & Chat)
git clone https://github.com/synchopate/llama-modchip.git
cd llama-modchip
./modchip chat
Direct Run (Portable GLIBC_2.30 Linux x86_64 -avx512 / -avx2 Binaries + Hugging Face .gguf)
Compatibility Note (
GGML_TYPE_Q2_0 = 42&GGML_TYPE_VQ3_0 = 43):Fractal-64(30 B / 64 W) repurposes upstreamGGML_TYPE_Q2_0 = 42(18 B / 32 W) in-place andLUT-VQ3-64(24 B / 64 W) appends customtype 43. Unpatchedllama.cpp,Ollama,vLLM, andLM Studiowill fail withunknown tensor type 43, a tensor bounds mismatch, orunknown model architecture: 'deepseek4'.
- Portable
GLIBC_2.30Linuxx86_64Binaries (GitHub Releasev2.5.4): Built inside Ubuntu 20.04 (GLIBC_2.30max symbol,-static-libstdc++, zerolibssl/libcurldependency; requires OpenMPlibgomp1/libgomp— Ubuntu 20.04+, Debian 11+, Fedora, RHEL/Rocky/Alma 9+) with SHA-256 verification in./modchip download-binand./install.sh --prebuilt:
llama-server-modchip-linux-x86_64-avx512: AMD Zen 4/5 (Ryzen 7000/8000/9000,EPYC Genoa/Turin,Threadripper 7000) & Intel Ice Lake / Sapphire Rapids (avx512f+avx512vbmi;-DGGML_AVX512_BF16=OFFso Ice Lake / Tiger Lake never hitvdpbf16psSIGILL).llama-server-modchip-linux-x86_64-avx2: Pre-AVX512x86_64CPUs (x86-64-v3: Intel Haswell/Broadwell/Skylake/Alder/Raptor Lake, AMD Zen 1/2/3 — compiled with-mno-avx512f -DGGML_AVX_VNNI=OFF,0%zmminstructions). The unsuffixedllama-server-modchip-linux-x86_64asset is an identical copy of thisx86-64-v3binary.
# Auto-select -avx512 or -avx2 binary for your Linux x86_64 CPU and verify SHA256:
BIN_ISA=$(grep -Eq "avx512_?vbmi" /proc/cpuinfo && echo "avx512" || echo "avx2")
curl -fLO "https://github.com/synchopate/llama-modchip/releases/download/v2.5.4/llama-server-modchip-linux-x86_64-${BIN_ISA}"
curl -fLO "https://github.com/synchopate/llama-modchip/releases/download/v2.5.4/SHA256SUMS"
sha256sum -c SHA256SUMS --ignore-missing
chmod +x "llama-server-modchip-linux-x86_64-${BIN_ISA}"

# 1A. Default 30B Nemotron-3.5-A3B VQ3-64 + Fractal-64 (13.30 GiB, Aligned — pass -c 32768 -ub 512 on 16 GB hosts):
hf download Synchopate/NVIDIA-Nemotron-3.5-30B-A3B-VQ3-64-CPU-GGUF \
  NVIDIA-Nemotron-3.5-30B-A3B-VQ3-64.gguf --local-dir .
./llama-server-modchip-linux-x86_64-${BIN_ISA} -m NVIDIA-Nemotron-3.5-30B-A3B-VQ3-64.gguf -c 262144 -t 16 -b 2048 -ub 512 --port 8080

# 1B. 30B Nemotron-3.5-A3B Fractal-64 (14.36 GiB, Aligned — recommended on AVX2-only CPUs & Apple Silicon):
hf download Synchopate/NVIDIA-Nemotron-3.5-30B-A3B-Fractal-64-CPU-GGUF \
  NVIDIA-Nemotron-3.5-30B-A3B-Fractal-64.gguf --local-dir .

# 2A. Default 284B DeepSeek-V4-Flash-0731-MaxQ-Fractal (56.93 GiB, Safety-Aligned Single-Pass Q6_K + Fractal-64):
hf download Synchopate/DeepSeek-V4-Flash-0731-MaxQ-Fractal-64GB-CPU-GGUF \
  --include "DeepSeek-V4-Flash-0731-MaxQ-Fractal-*.gguf" --local-dir ./dsv4-maxq
# Safe 64 GB Desktop default (-c 32768 -ub 512 -> ~57.5–58.1 GiB anonymous-heap VmRSS):
./llama-server-modchip-linux-x86_64-${BIN_ISA} -m ./dsv4-maxq/DeepSeek-V4-Flash-0731-MaxQ-Fractal-00001-of-00003.gguf \
  -c 32768 -t 16 -b 2048 -ub 512 -ctk q8_0 -ctv q8_0 -fa on --port 8080
# Dedicated Headless 64 GB Server (with zram/swap) or 96 GB+ Workstation (full 256K MLA context):
# ./llama-server-modchip-linux-x86_64-${BIN_ISA} -m ./dsv4-maxq/DeepSeek-V4-Flash-0731-MaxQ-Fractal-00001-of-00003.gguf \
#   -c 262144 -t 16 -b 2048 -ub 512 -ctk q8_0 -ctv q8_0 -fa on --port 8080

# 2B. Compact Safety-Aligned 284B DeepSeek-V4-Flash VQ3 (56.40 GiB) or Cross-Platform Fractal-64 (56.57 GiB):
hf download Synchopate/DeepSeek-V4-Flash-0731-VQ3-64GB-CPU-GGUF \
  --include "DeepSeek-V4-Flash-0731-VQ3-*.gguf" --local-dir ./dsv4-vq3
hf download Synchopate/DeepSeek-V4-Flash-0731-Fractal-64GB-CPU-GGUF \
  --include "DeepSeek-V4-Flash-0731-Fractal-*.gguf" --local-dir ./dsv4

# 2C. Opt-In Abliterated / Uncensored Variants (284B dsv4-ablit & 30B nemotron-ablit — requires confirmation):
# ./install.sh --preset dsv4-ablit        # Synchopate/DeepSeek-V4-Flash-0731-Abliterated-Fractal-64GB-CPU-GGUF (56.93 GiB)
# ./install.sh --preset nemotron-ablit    # Synchopate/NVIDIA-Nemotron-3.5-30B-A3B-Abliterated-VQ3-64-CPU-GGUF (13.30 GiB)
[!CAUTION] Responsible-Use Disclaimer (Opt-In
dsv4-ablit&nemotron-ablitCheckpoints): Both optional abliterated checkpoints (DeepSeek-V4-Flash-0731-Abliterated-FractalandNVIDIA-Nemotron-3.5-30B-A3B-Abliterated-VQ3-64) derive from base models in which refusal-mediating activation directions were removed via orthogonal projection. Standard upstream refusal filters are disabled, and./install.shnever selects them without explicit interactive[y/N]confirmation (or--accept-abliteratedin non-interactive mode).
- Intended Scope: Authorized security research, red-teaming, CTF competitions, vulnerability auditing, and local offline software engineering only.
- Deployment: Do not expose an unmoderated endpoint of an abliterated checkpoint to public or multi-user networks without external access control and safety filtering.
- Safety-Aligned Defaults: Default
./modchip setupinstalls safety-aligneddsv4-maxq(60 GB+/64 GBclass) ornemotron-vq3/nemotron-fractal(16–59 GB).
64 GB Host RAM Headroom (
-c 32768 -ub 512Desktop vs.-c 262144Headless): Because--load-mode none --repackstores repacked CPU weights in anonymous heap (57.54–59.13 GiBVmRSS), the Linux kernel cannot demand-page those pages back from disk under desktop RAM pressure without swap/zram. On a 64 GB Linux box (~62.5 GiBusable RAM), keep-c 32768 -ub 512(start_server.shenforces-c 32768 -ub 512and disk-backed slot snapshots automatically on<= 68 GBhosts unlessMODCHIP_CTX_SIZEis set) and enablezramor close heavy GUI browsers. Use-c 262144(256Ktokens) on dedicated headless 64 GB nodes withzram/swap or96 GB+workstations. Measured context scaling up to3,038tokens (30.7–38.4 tok/sprefill,9.16 tok/sdecode) is reported indocs/DEEPSEEK_V4_OPTIMIZATIONS.md§6.
Windows 10/11 (Patched VQ3-64 / Fractal-64 Engine & Hybrid GPU+CPU Pack)
- Standard GGUFs (
Q4_0,MXFP4,Q3_K_M,Q8_0) with Automatic GPU+CPU Offload: Runwindows/AVVIA_MODCHIP.bat(windows/README.md). It detects physical CPU cores, free RAM, and GPU VRAM (nvidia-smi), downloads officialllama.cppCUDA 12.4 / Vulkan binaries, computes--n-cpu-moe, and startshttp://127.0.0.1:8080. - Patched
DeepSeek-V4 284B&Nemotron-30B(Fractal-64type 42&LUT-VQ3-64type 43): Runpowershell -ExecutionPolicy Bypass -File windows\build_patched_engine.ps1 -Target dsv4(or-Target nemotron) to compile the native MinGW-w64 UCRT64 AVX-512 engine, then launch viawindows/AVVIA_DSV4.bat(details indocs/WINDOWS_PORT.md).
./modchip Command |
Description |
|---|---|
./modchip download-bin |
Auto-detects avx512_vbmi vs avx2 on Linux x86_64 and installs the matching release binary |
./modchip chat |
Interactive terminal chat with live tok/s, TTFT, and Stockfish-PVS acceptance telemetry |
./modchip web |
Opens the Dark-Mode Web Chat & Live Telemetry HUD (http://127.0.0.1:8787) |
./modchip bench |
Runs a 30-second 2-stage speed test and prints a shareable CPU Benchmark Scorecard |
./modchip claude |
Launches Claude Code CLI (40 tools) wired to the local 256K engine (10.4–32.6 ms warm restore) |
./modchip eval |
Runs the reproducible 100-Point Quality, Tool-Calling, Coding & 8.5K Needle Gate |
./modchip quantize |
Transcodes GGUFs into LUT-VQ3-64 (--vq3-nemotron / --vq3-dsv4), Fractal-64, or Fractal-MXFP4 |
./modchip status / stop |
Inspects CPU readiness, 2MB HugePages, and /dev/shm IPC, or stops background services |
Hardware Readiness Check (Zero Model Download Required)
curl -sL https://raw.githubusercontent.com/synchopate/llama-modchip/main/scripts/check_cpu_readiness.py | python3
Submit your terminal scorecard via a GitHub Benchmark Issue or GitHub Discussions to add your CPU to the leaderboard below.
Supported Models and Model-Specific Optimizations
Each model family has a dedicated technical guide with mathematical derivations, operator-level latency profiles, and quality gate benchmarks:
| Model Family | Total / Active Params | Disk (GGUF) & 256K RAM (VmRSS) |
Key Optimizations Implemented | Verified Speed (16C Zen 5 / Hybrid) |
Detailed Guide |
|---|---|---|---|---|---|
NVIDIA-Nemotron-3.5-30B-A3B( VQ3-64 / Fractal-64 / MXFP4 / Q4_0) |
30.2B / 3.0B( 23 SSM + 23 MoE + 6 GQA) |
13.30 – 17.60 GiB( 15.4 – 21.7 GiB RSS) |
• LUT-VQ3-64 (3.00 bpw) & Fractal-64 (3.75 bpw) (100/100 Quality Gate)• Stockfish-PVS v2 (M=7) + RouteCrack (192 KB L2-resident Zobrist TT)• 432 MB 256K EAKV (Q8_0/Q4_0) + _MM_HINT_NTA L3 isolation• 18.9 ms /dev/shm Slot-0 Restore |
24.2 – 60.4 tok/s (0 GPU)80.8 tok/s (Vulkan Hybrid)111.6 tok/s (Threadripper) |
Nemotron Guide |
DeepSeek-V4-Flash-0731( MaxQ-Fractal Default / VQ3-64 / Fractal-64 / Opt-In Abliterated) |
284.33B / 13.17B( 43L MLA + 256+1s MoE) |
56.40 – 56.93 GiB(** 57.5 – 59.1 GiB RSS* — 32K desktop / 256K headless)* |
• Donor-Free Single-Pass 0731 BF16/FP8 -> Q6_K (174 dense tensors, wiki-alt.txt 51c PPL 7.2977 ± 0.0504 [12c 7.3180 ± 0.1039], WikiText-2 PPL 11.6139 ± 0.5845, 70.0/80 Functional Gate [30/30 Tools]) + LUT-VQ3-64 + @antirez 1.5M-imatrix / SwiGLU-H2 MoE + Fractal-64 MLA• 4-Level Register ( ZMM AVX-512BW/VBMI) + L1D + L2 + L3 Multi-Column ({8,4,3,2}) Prefill Tiling (25.0 -> 43.98 cold / 44.36 warm tok/s)• Register-Stationary AVX-512 MQA8 FlashAttention (2.0x) + AVX-512 quantize_row_q8_K• Optional $L_2$-Quadrature MoE Pruning + Gate-First SwiGLU ( 10.74 tok/s) & $O(1)$ Rollback Fix |
36.1–44.0 tok/s (Cold pp)44.36 tok/s (Warm prefix)8.66–9.06 tok/s (Unpruned Top-6 N=1)9.87–10.74 tok/s (Top-5/4 L2)8.8–25.3 tok/s (PVS / Tools) |
DeepSeek-V4 Guide |
Qwen3-30B-A3B & Qwen3-14B( Q3_K_M / Q4_K_M) |
30.5B / 3.3B -> 1.7B( 48L GQA, 128 exp) |
13.70 – 17.28 GiB( 14.5 – 19.4 GiB RSS) |
• Norm-Preserving Dynamic MoE Top-K (8 -> 4, +38.5% decode)• 3:1 Interleaved SWA Safety Lock ( LLAMA_SWA_STRIDE=4)• Windows 11 GB VRAM + 16 GB RAM Hybrid Split (--n-cpu-moe N) |
34.80 tok/s (0 GPU Top-4)50–58 tok/s (14B RTX 2080 Ti) |
Architecture §3.9 |
NVIDIA-Nemotron-H-8B-128K( Q8_0 / Q4_K_M) |
8.0B Dense( 48 SSM + 4 GQA) |
4.60 – 8.00 GiB( 210 MB KV @ 128K) |
• 48-Layer Mamba-2 SSM Constant-Memory Backbone • 100% GPU VRAM Residency on 8–11 GB Cards (0 GB System RAM) |
100+ tok/s (RTX 2080 Ti)147.6 tok/s (CPU pp512) |
Nemotron Guide |
Supported Chips and Processor-Specific Optimizations
Microarchitectural details and tuning flags for each processor and GPU hybrid are documented in docs/HARDWARE_OPTIMIZATIONS.md:
| Processor / Platform | Verified Hardware | Hardware-Specific Optimizations Active | Platform Guide & Scripts |
|---|---|---|---|
AMD Zen 5 (Desktop / Mobile / Server) |
Ryzen 9 9955HX, 9950X, Ryzen 7 9800X3D, EPYC 9005 Turin |
• Single-cycle 512-bit AVX-512 (VPDPBUSD, VPRORVQ, VBMI VPERMI2B, BF16)• 48 KB L1D 3D Tiling (TILE_I0=64) on multi-head wo_a projections• _MM_HINT_NTA Victim-L3 Isolation (64 MB) + 2MB THP (6.14 GB L2 STLB) |
Hardware Guide §2.1install.sh |
AMD Zen 4 Multi-CCD (Threadripper / EPYC) |
Threadripper PRO 7985WX (64C/128T, 8 CCDs, 256 MB L3) |
• Dynamic sysfs L3 CCD Topology Discovery (scripts/llama_modchip.py)• Deterministic 4C/CCD Stride (-t 32): avoids Infinity Fabric saturation (+54% faster than -t 64) |
Hardware Guide §2.2 Issue #1 |
| AMD 3D V-Cache + Radeon Vulkan Hybrid | Ryzen 9 7945HX3D (128 MB L3) + RX 9070 XT 16GB (RADV) |
• Tensor-Role Splitting (-ngl 99 --n-cpu-moe N --load-mode none)• Native Vulkan SSM_SCAN + Fractal-MXFP4 (15.2 GB) GPU Shaders (80.8 tok/s at 256K) |
Hardware Guide §2.3FAQ.md Q8 |
Intel / AMD + NVIDIA RTX (Windows 10/11) |
Ryzen 7 9800X3D (1M ctx), Core i9-9900K / 14900K + RTX 2080 Ti / 3090 / 4090 |
• MinGW-w64 UCRT64 AVX-512 VBMI/BW Patched Engine (build_patched_engine.ps1)• Live-VRAM --n-cpu-moe Solver (550 MB WDDM Reserve) + _WIN32 CreateFileMappingA |
Windows Portwindows/ |
Apple Silicon (M1 / M2 / M3 / M4 / M5) |
M5 Max (64 GB / 48 GB), M4 Max (64 GB / 36 GB), M4 Pro (24 GB), M3 Max, M1 Max |
• Register-Tiled Fractal-64 (Q2_0) Fast-Decode Metal Shaders (PR #24): 57.65 tok/s on M1 Max (+86%), 78.60 tok/s on M3 Max, 72.5 tok/s tg128 / 979.9 tok/s pp512 on M4 Max (-3.24 GiB unified RAM vs Q4_0, which runs ~8% faster at 77.95 tok/s on 36 GB+ Macs where Q4_0 fits resident; #16)• Zero-Copy Unified Memory + NEON SDOT: 27.0 tok/s DeepSeek-V4 284B on M5 Max (286.5 GB/s DRAM BW, #21) |
Apple Silicon Guide #8 · #16 · #24 |
ARM64 Cloud & Edge (AWS Graviton / Ampere) |
AWS Graviton3 m7g.2xlarge (8 vCPU Neoverse-V1, 32 MB L3) |
• ARMv8.4-A DotProd (SDOT) + 256-Bit SVE + 1-vCPU-per-core pinning (-t 8)• 32 MB System Level Cache (SLC) retention (44.97 tok/s decode) |
Hardware Guide §1 Issue #2 |
AMD Zen 4 Compact Mini-PC (Linux) |
Ryzen 7 8745H / 8745HS (8C/16T, 16 MB L3 + Radeon 780M) |
• AVX-512 VNNI + 16 MB L3 window auto-tuning (19.48–23.38 tok/s on 96 GB DDR5-5600)• Optional Radeon 780M UMA iGPU offload |
Fedora Guide Issue #9 |
Headline Benchmarks: Pure CPU & Hybrid Summary
1. DeepSeek-V4-Flash 284B (13.17B Active) on a 64 GB Zen 5 CPU (AMD Ryzen 9 9955HX, 0 GPUs)
Operator-level profiling and mathematical derivations in docs/DEEPSEEK_V4_OPTIMIZATIONS.md (probabilities and KL-divergence measured relative to unpatched Top-6 execution on the 56.57 GiB Fractal checkpoint):
Runtime Configuration (DeepSeek-V4-Flash, 32K Desktop / 256K Headless) |
Cold / Warm Prefill | Pure Decode (N=1) |
With Stockfish-PVS |
Logit Cosine Sim | Routing KLD vs. Top-6 |
Top-1 / Top-3 Match |
|---|---|---|---|---|---|---|
Unpatched UD-IQ1_S (76.87 GiB / 82.5 GB) |
OOM / Swap on 64 GB | 5.91 tok/s (169.3 ms) |
N/A (Rollback Bug) | 1.00000 |
0.0000 (0.00%) |
100% / 100% |
1. v2.5.4 Unpruned (Top-6 All Layers, Default, 56.40–56.93 GiB) |
36.11–43.98 cold / 44.36 warm |
8.66 – 9.06 tok/s |
8.80 – 25.3 tok/s |
1.00000 (Ref) |
0.0000 (0.00% Ref) |
100% / 100% |
2. v2.5.4 Sweet-Spot (Top-5 on il >= 3, $L_2$ Quadrature) |
41.11–43.98 cold / 44.36 warm |
9.68 – 9.87 tok/s |
12.2 – 25.5 tok/s |
0.99714 |
0.0042 nats (+0.42% PPL) |
95.8% / 100% |
3. v2.5.4 Top-5 L2 + Gate-First SwiGLU (80/128 $L_2$) |
41.11–43.98 cold / 44.36 warm |
10.15 tok/s (98.5 ms) |
12.8 – 26.0 tok/s |
0.99385 |
0.0531 nats |
100% / 100% |
4. v2.5.4 Turbo 10+ (Top-4 L2 + Gate-First SwiGLU) |
41.11–43.98 cold / 44.36 warm |
10.12 – 10.74 tok/s (93.2 ms) |
13.0 – 26.4 tok/s |
0.99126 |
0.0281 – 0.0694 nats |
100% / 100% |
2. NVIDIA-Nemotron-3.5-30B-A3B (3.0B Active) at 256K Context (AMD Ryzen 9 9955HX, 0 GPUs)
Full ablation tables and 100/100 Quality Gate reports in docs/NEMOTRON_OPTIMIZATIONS.md and benchmarks/QUALITY_GATE_VQ3_64.md:
| Quantization Profile | Disk Size | Peak VmRSS (256K) |
Quality Gate (100 pts) |
Prefill (pp512 Peak / Gate) |
Served Gate Decode (Stockfish-PVS E2E) |
Refactor Burst (M=7) / Hybrid |
|---|---|---|---|---|---|---|
Baseline-Q4_0 (4.50 bpw Official GGUF) |
17.60 GiB |
21.71 GiB |
100.0 / 100.0 |
241.0–306.8 / 46.9 Gate |
19.54 tok/s (66.7% acc) |
40.91–60.40 tok/s (48.39 avg M=7, len 6.90) |
Fractal-MXFP4 (4.25 bpw) |
15.95 GiB |
18.86 GiB |
100.0 / 100.0 |
241.0–306.8 / 239.6 Gate |
26.08 tok/s (+33.5%, 61.1% acc) |
75.1–80.8 tok/s (AMD Vulkan Hybrid) |
Fractal-64-BF16 (3.75 bpw) |
14.36 GiB |
17.27 GiB |
100.0 / 100.0 |
241.0–306.8 / 181.5 Gate |
25.02 tok/s (+28.0%, 59.1% acc) |
71.3–78.6 tok/s (M3/M4 Max Metal) |
LUT-VQ3-64 (3.00 / 3.75 bpw) |
13.30 GiB (13.08 abl.¹) |
16.04 GiB¹ (-5.67 GiB) |
100.0 / 100.0¹ |
241.0–306.8 / 221.9 Gate¹ |
24.18 tok/s¹ (+23.7%, 70.2% acc) |
— (Gate E2E measured on 13.08 GiB abl.¹) |
3. DeepSeek-V4-Flash 284B (13.17B Active) on Apple Silicon (Apple M5 Max, 64 GB Unified Memory)
- Prefill Throughput (
pp512):169.4 ± 29.6 tok/s(Apple Metal accelerated) - Decode Throughput (
tg128):27.0 ± 0.4 tok/sinllama-bench - Real Served Generation (
llama-server):20.7 – 23.6 tok/sacross coding and prose (code_edit:20.7 tok/s,code_new:23.3 tok/s,free_text:23.6 tok/s) with0swapouts (iogpu.wired_limit_mb=57344) - Architecture & Placement: Apple M5 Max (18-Core CPU + 40-Core Metal GPU), 64 GB LPDDR5X. 5 pure-
IQ1_SMoE layers offloaded to CPU (blk.(10|12|14|16|18).ffn_.*_exps.=CPU), remainder on Metal. - Driver & Patches:
patches/apple-silicon/0001(Fractal-64 Q2_0 NEON/Metal),0002(Metal tensor run mapping),0003(Metal register unpack). Built viaapple-silicon/build-dsv4-engine.shand launched withapple-silicon/run-dsv4.sh. Contributed by Bobby Grayson (@notactuallytreyanastasio). Full report:apple-silicon/results/dsv4-m5max.md.
Community CPU and Hybrid Leaderboard
Run ./modchip bench (or windows\BENCHMARK_PC.bat on Windows) and Submit Your Scorecard (GitHub Issue) (pure-CPU entries sorted by Refactor decode):
Hardware Platform (CPU / SoC / Hybrid) |
Cores / Cache | Memory | Prefill (tok/s) |
Decode — Prose / C++20 | Decode — Stockfish M=7 Burst |
Config & Contributor |
|---|---|---|---|---|---|---|
AMD Threadripper PRO 7985WX (Zen 4) |
64C/128T (8 CCDs, 256 MB L3) |
256 GB 8-Ch DDR5-6000 (0 GPU) |
386.00 (-t 32) |
73.84 – 80.14 tok/s (70.0% acc) |
111.62 tok/s warm / 80.14 cold (-t 32 4C/CCD) |
@aifartist (Issue #1) |
AMD Ryzen 9 7945HX3D + RX 9070 XT (Hybrid) |
16C/32T (128 MB 3D V-Cache) + 16 GB Vulkan |
94 GB DDR5 + 16 GB VRAM |
563.00 (256K ctx) |
75.10 tok/s (MXFP4 15.2GB) |
80.80 tok/s (Vulkan SSM_SCAN + MXFP4 MoE) |
Community (RADV/Vulkan) (FAQ.md) |
AMD Ryzen 9 9955HX (Zen 5) |
16C/32T (2 CCDs, 64 MB L3) |
64 GB DDR5 (0 GPU) |
241.0 *(Peak 306.8)* |
24.18 – 26.08 tok/s (Served Gate; 34.5 Tools) |
48.39 avg / 60.40 peak (Q4_0 M=7, len 6.90) |
@synchopate (docs/NEMOTRON_OPTIMIZATIONS.md) |
Apple M3 Max (Metal · Fractal-64 Fast-Decode) |
ARM64 NEON + Metal |
Unified (Q2_0 Metal Kernel) |
Metal | 78.60 tok/s (tg128 fast-decode Q2_0) |
78.60+ tok/s (Register-tiled Metal Q2_0) |
@austindixson (PR #24) |
Apple M4 Max (14C+32C Metal · Q4_0) |
ARM64 NEON + Metal |
36 GB LPDDR5X-8533 (Unified) |
860.13 (1,040.2 pp512) |
77.23 tok/s (C++20, 203 ms TTFT; 80.34 tg128) |
77.95 tok/s (81.0 short; Nemotron 30B code PPL 2.086 ± 0.037, Gate 100/100) |
@khairullinr (Issue #16) |
Apple M4 Max (14C+32C Metal · Fractal-64) |
ARM64 NEON + Metal |
36 GB LPDDR5X-8533 (Unified) |
615.89 (979.9 pp512) |
71.60 tok/s (C++20, 47 ms TTFT; 72.47 tg128) |
71.31 tok/s (vs Q4_0 ref, code: Top-1 94.35%, KLD 0.0566 nats, Gate 100/100) |
@khairullinr (Issue #16) |
Apple M5 Max (DeepSeek-V4 284B · 56.57 GiB) |
18C CPU + 40C Metal |
64 GB LPDDR5X (286.5 GB/s BW) |
169.40 (pp512) |
27.00 tok/s (llama-bench tg128) |
20.70 – 23.60 tok/s (llama-server, 0 swapouts) |
@notactuallytreyanastasio (dsv4-m5max.md) |
Apple M4 Max (16C CPU + 40C GPU) |
16C (ARM64 NEON + 40C Metal) |
64 GB LPDDR5X-8533 (238.9 GB/s BW) |
~451.0 (Audit) |
49.2 – 57.7 tok/s (Prose / Code) |
70.9 – 120.0 tok/s (Agent / Refactor) |
@jbeckman1974 (Issue #8) |
Apple M1 Max (Metal · Fractal-64 Fast-Decode) |
10C CPU + 32C Metal |
Unified (Q2_0 Metal Kernel) |
Metal | 57.65 tok/s (+86% vs prior Q2_0 Metal) |
57.65+ tok/s (Register-tiled Metal Q2_0) |
@austindixson (PR #24) |
Apple M4 Pro (14-Core SoC) |
14C CPU + 20C Metal |
24 GB Unified (0 Swap) |
256.0 – 549.0 |
47.0 – 48.0 tok/s (128K) |
49.0+ tok/s |
@jarorosFork (apple-silicon/) |
AWS Graviton3 m7g.2xlarge (ARM64 Neoverse-V1) |
8 vCPU (32 MB L3, SVE-256) |
31 GB DDR5 (0 GPU) |
101.67 (-t 8) |
41.05 tok/s (C++20) |
44.97 tok/s (Refactoring) |
@gerchik (Issue #2) |
AMD EPYC 7402P (Zen 2 Rome · AVX2-only) |
24C/48T (8 CCDs, 128 MB L3) |
128 GB 8-Ch DDR4 (0 GPU) |
158.73 (-t 24) |
27.29 tok/s (C++20, 567 ms TTFT) |
31.22 tok/s (Cold Run 1, 66.7% acc) |
@AdamKlob (Issue #6) |
AMD Ryzen 9 9950X3D (Zen 5 3D V-Cache · Win11) |
16C/32T (2 CCDs, 128 MB L3, AVX-512) |
128 GB DDR5-6000 (0 GPU) |
Native Win11 | 24.92 tok/s (Nemotron 30B Q4_0, -t 16) |
24.92+ tok/s (Fixed --spec-ngram-simple) |
@kevinblo (Issue #33) |
AMD Ryzen 9 9950X (Zen 5 Desktop) |
16C/32T (2 CCDs, 64 MB L3) |
64 GB DDR5-6800 (0 GPU) |
135.64 (v2.1 Q4_0) |
20.78 tok/s (C++20, 526 ms TTFT) |
24.67 tok/s (Cold Run 1, 66.5% acc) |
@nadams (Issue #5) |
AMD Ryzen 7 8745H w/ Radeon 780M (Zen 4) |
8C/16T (16 MB L3, AVX-512) |
96 GB DDR5-5600 (0 GPU, Arch) |
128.81 (-t 8) |
19.48 tok/s (C++20, 686 ms TTFT) |
23.38 tok/s (69.8% PVS acc) |
@arch-btw (Issue #9) |
AMD Ryzen 5 5600X (Zen 3 Desktop · Fractal-64) |
6C/12T (32 MB L3, AVX2) |
32 GB DDR4-3200 (XMP/DOCP, 0 GPU) |
63.90 (2MB THP) |
19.04 tok/s (C++20, 1070 ms TTFT) |
21.58 tok/s (65.3% PVS acc) |
@alexander-jung (Issue #17) |
AMD Ryzen 7 5700X (Zen 3 Desktop · Q4_0) |
8C/16T (32 MB L3, AVX2) |
64 GB DDR4-3600 (0 GPU, Ubuntu 26.04) |
101.93 (-t 8) |
16.04 tok/s (C++20, 856 ms TTFT) |
19.66 tok/s (67.9% PVS acc) |
@germanpsycho (Issue #23) |
AMD Ryzen 5 5600X (Zen 3 Desktop · Q4_0) |
6C/12T (32 MB L3, AVX2) |
32 GB DDR4-3200 (XMP/DOCP, 0 GPU) |
86.96 (88.77 w/ THP) |
14.95 tok/s (C++20, 968 ms TTFT) |
18.07 tok/s (64.5% PVS acc) |
@alexander-jung (Issue #17) |
Intel Core Ultra 5 125H (Meteor Lake-H) |
4P+8E+2LP-E (18 MB L3, AVX-VNNI, LP-E excl.) |
32 GB DDR5 (50.2 GB/s, 0 GPU) |
55.19 (-t 12; 60.53 on 4P) |
14.63 tok/s (C++20, 1313 ms TTFT) |
16.61 tok/s (67.9% PVS acc) |
@xma (Issue #18) |
AMD Ryzen 5 7430U (Zen 3 Mobile 15W) |
6C/12T (16 MB L3, AVX2) |
32 GB DDR4-3200 (0 GPU, Pop!_OS) |
59.03 (-t 6) |
13.03 tok/s (C++20, 2072 ms TTFT) |
15.57 tok/s (68.3% PVS acc) |
@armadillu (Issue #12) |
AMD Ryzen 7 PRO 6850U (ThinkPad T14s Gen 3) |
8C/16T (16 MB L3, AVX2) |
32 GB LPDDR5-4800 (0 GPU, Debian 13) |
62.74 (-t 8) |
12.61 tok/s (C++20, 1204 ms TTFT) |
14.67 tok/s (66.0% PVS acc) |
@mkesper (Issue #15) |
AMD Ryzen 7 5700U (Zen 2 Mobile 15W · Q4_0) |
8C/16T (8 MB L3, AVX2) |
64 GB DDR4 (0 GPU, Debian) |
43.93 (v2.4 -t 8) |
13.04 tok/s (C++20, 1722 ms TTFT) |
14.48 tok/s (66.5% PVS acc) |
@JamesStallings (#10 → #20) |
AMD Ryzen 7 5700U (Zen 2 Mobile 15W · Fractal-64) |
8C/16T (8 MB L3, AVX2) |
64 GB DDR4 (0 GPU, Debian) |
32.48 (v2.1 Fractal-64) |
13.55 tok/s (C++20, 2233 ms TTFT) |
13.52 tok/s (64.9% PVS acc) |
@JamesStallings (Issue #19) |
Intel Core i9-11950H (Tiger Lake-H) |
8C/16T (24 MB L3, AVX-512) |
128 GB DDR4-3200 (0 GPU, Fedora) |
85.39 (-t 8) |
10.76 tok/s (C++20, 1106 ms TTFT) |
13.37 tok/s (69.8% PVS acc) |
@ELO-I (Issue #11) |
Dual Intel Xeon E5-2670 (Sandy Bridge-EP 2012) |
16C/32T (2×20 MB L3, AVX-only) |
94 GB RAM (0 GPU, Ubuntu 24.04) |
47.31 (-t 16) |
10.69 tok/s (C++20, 2014 ms TTFT) |
11.47 tok/s (65.0% PVS acc, 3.0x floor) |
@Mammux (Issue #14) |
AMD Ryzen 5 2600X (Zen+ Desktop · Q4_0) |
6C/12T (16 MB L3, AVX2) |
32 GB DDR4-3200 (29.4 GB/s, Win11+WSL2) |
21.06 (-t 6) |
7.60 tok/s (C++20) |
10.42 tok/s (68.9% PVS acc) |
@lawsochi (Issue #26) |
Windows 11 Hybrid (i9-9900K + RTX 2080 Ti 11GB) |
8C/16T (16 MB L3) + 11 GB CUDA |
16 GB DDR4 + 11 GB GDDR6 |
Auto CUDA 12.4 | 50–58 tok/s (14B) / 30B Hybrid |
100+ tok/s (Nemotron-H-8B 128K) |
windows/ |
AMD Ryzen 7 8745HS (GEEKOM A8) |
8C/16T (16 MB L3) |
64 GB DDR5-5600 |
Verified Fedora 44 | Verified (ngram) |
Verified (CPU & 780M) |
@jarorosFork (fedora/) |
DeepSeek-V4-Flash 284B on Ryzen 9 9955HX |
16C/32T (2 CCDs, 64 MB L3) |
64 GB DDR5 (57.5–59.1 GiB RSS, 32K/256K) |
36.1–41.1 cold / 44.36 warm (10.4 ms Slot-0) |
8.66 – 9.06 tok/s (N=1 Top-6; 10.74 Top-4) |
8.80 – 25.30 tok/s (PVS / Tools) |
@synchopate (docs/DEEPSEEK_V4_OPTIMIZATIONS.md) |
DeepSeek-V4-Flash 284B on Ryzen 9 9950X3D (Win11) |
16C/32T (2 CCDs, 128 MB 3D V-Cache, AVX-512) |
128 GB DDR5-6000 (56.93 GiB, 0 GPU) |
27.55 tok/s (pp512, -t 16) |
8.11 tok/s Top-6 / 9.47 tok/s Top-4 (tg128) |
9.47+ tok/s (Native Win11, Abliterated-Fractal) |
@kevinblo (Issue #33) |
DeepSeek-V4-Flash 284B on Ryzen 7 9800X3D (Win11) |
8C/16T (96 MB 3D V-Cache, AVX-512) |
64 GB DDR5 (56.40–56.57 GiB, 1M ctx) |
21.30 – 22.60 tok/s (pp512) |
6.35 – 8.04 tok/s (Top-6 / Top-4 tg128) |
8.04+ tok/s (Native Win11, 1M ctx verified) |
@MR1KRAKEN (PR #27, Issue #28) |
Repository Structure & Manual CMake Build Instructions
llama-modchip/
├── modchip                                    # Unified CLI (setup | start | chat | bench | eval | quantize | web | claude | stop)
├── install.sh                                 # Automated Installer (Linux)
├── README.md / ARCHITECTURE.md / FAQ.md       # Overview, Mathematical Architecture & Engineering FAQ
├── RELEASE_NOTES.md                           # v2.5.4 Release Notes
├── docs/
│   ├── NEMOTRON_OPTIMIZATIONS.md              # Nemotron-3.5-30B-A3B & Nemotron-H-8B optimizations
│   ├── DEEPSEEK_V4_OPTIMIZATIONS.md           # DeepSeek-V4-Flash 284B profiling, SVD & L2-quadrature MoE
│   ├── HARDWARE_OPTIMIZATIONS.md              # Chip-by-chip optimizations (Zen 5, Threadripper, Vulkan, CUDA, Metal, ARM64)
│   └── WINDOWS_PORT.md                        # Native Windows 11 patched-engine build & Ryzen 7 9800X3D 1M-context report
├── vq3/                                       # LUT-VQ3-64 3D Lloyd-Max codebook, self-contained C encoder & kernel tests
├── patches/
│   ├── apple-silicon/                         # Apple Silicon engine patches (Fractal-64 Q2_0 NEON/Metal, register unpack)
│   ├── deepseek-v4-flash-fractal-256k.patch   # Base engine patch (DeepSeek-V4-Flash 284B + Fractal-64 Q2_0 = 42)
│   ├── dsv4-64gb-cpu.patch                    # Apple Silicon base engine patch (pinned to llama.cpp d2f83055)
│   ├── dsv4-ipc-hardening.patch               # Per-user 0700 IPC & /dev/shm_<uid> hardening patch (Linux/macOS/Windows)
│   ├── lut-vq3-64-avx512-vbmi.patch           # Incremental LUT-VQ3-64 (VQ3_0 = 43) AVX-512 VBMI + AVX2 + scalar patch
│   ├── vq3_codebook.h                         # 128-entry 3D + 64-entry 2D LUT-VQ3-64 codebook header
│   └── zen5-nemotron-256k-optimizations.patch # Standalone ggml/llama core patch for Nemotron-3.5
├── windows/                                   # Windows 10/11 Patched Engine Builder (build_patched_engine.ps1, AVVIA_DSV4.bat) & Hybrid Pack
├── apple-silicon/                             # Apple Silicon M1–M5 setup scripts (build-dsv4-engine.sh, run-dsv4.sh, M5 Max report)
├── fedora/                                    # Fedora 44 / AMD Ryzen 7 8745HS (GEEKOM A8) all-in-one script
├── speculative/                               # RouteCrack + Stockfish-PVS v2 (rc_stockfish.h, ngram-map.cpp)
├── benchmarks/                                # eval_quality_and_tools.py (100-pt Quality Gate), QUALITY_GATE_VQ3_64.md & results/
├── gateway/sse_gateway.py                     # Agentic SSE Proxy + Compact Tool Table + Dark-Mode Web Chat HUD (:8787)
└── scripts/                                   # build_zen5_llama.sh, build_{nemotron,dsv4}_vq3.py, build_fractal_moe_gguf.sh, chat.py
Acknowledgments
- Salvatore Sanfilippo (
@antirez) for single-pass DeepSeek-V4 routed-MoE quantization research and the1.5M-tokenDeepSeek-V4-Flash-chat-v2-routed-moe-ds4-1p5m.dat(antirez/deepseek-v4-gguf @ f71f23d552d6, committed2026-05-12from AprilDeepSeek-V4-Flashchat-v2activations) importance matrix used in the donor-free single-passMaxQ-Fractal(v2.5.3) andAbliterated-Fractalcheckpoints. - Unsloth (
unsloth/DeepSeek-V4-Flash-0731-GGUF) for theUD-IQ1_S(@ fbbb5b93fb787c21338159b0af3318bb3f4d9768) checkpoint used as the upstream donor (86routed-MoEgate_exps/up_expstensors across43layers:70inblk.0..34[60 × IQ1_S + 10 × IQ2_XXSin anchor layers{1,4,26,28}] copied byte-for-byte +16inblk.35..42transcoded) when building the compactDeepSeek-V4-Flash-0731-Fractal(56.57 GiB) andDeepSeek-V4-Flash-0731-VQ3(56.40 GiB) variants. - AtomicChat (
AtomicChat/dsv4-eval-artifacts) for publishing the openwiki-alt.txt(-c 5632 -b 5632) evaluation corpus and cross-vendorDeepSeek-V4-Flash-0731perplexity reference logs. - DeepSeek AI (
deepseek-ai) and NVIDIA for the foundationalDeepSeek-V4-Flash(MIT License) andNemotron-3.5-30B-A3B(OpenMDW-1.1) architectures, andggml-org/llama.cppfor the upstream C/C++ inference runtime. - Prem Research (
prem-research) andHangGlidersRulefor theDeepSeek-V4-Flash-0731-abliteratedandDarkstar-Nemotron-3.5-Lightning-30B-A3B-Abliterated-BF16checkpoints used for the opt-indsv4-ablitandnemotron-ablitpresets.
Explorar proyectos relacionados
codecrafters-io/build-your-own-x
Domina la programación recreando desde cero tus tecnologías favoritas.
562,357 estrellaspublic-apis/public-apis
Una lista colectiva de API gratuitas
498,808 estrellasmorluto/rea
Ingeniería inversa de cualquier cosa con agentes, desde el comportamiento de la aplicación hasta los binarios nativos.
457,843 estrellasopenclaw/openclaw
La IA que de verdad hace las cosas. Cualquier sistema operativo y cualquier plataforma. Al estilo langosta. 🦞
394,403 estrellas