Proyectos Ver en GitHub
seungwonpark/melgan
seungwonpark/melgan has 651 GitHub stars and 113 forks. Star changes are not measured yet. Last checked 2026-11-18 06:10 UTC. Last push 2020-10-03.
What you can do
- MelGAN is lighter, faster, and better at generalizing to unseen speakers than WaveGlow.
- This repository use identical mel-spectrogram function from NVIDIA/tacotron2, so this can be directly used to convert output from NVIDIA's tacotron2 into raw-audio.
- Pretrained model on LJSpeech-1.1 via PyTorch Hub.
Crecimiento de estrellas medido
- in 24h
- Actualización retrasada
- in 7 days
- Actualización retrasada
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
MelGAN vocoder (compatible with NVIDIA/tacotron2)
Aprendizaje automáticoREADME.md
OriginalMelGAN
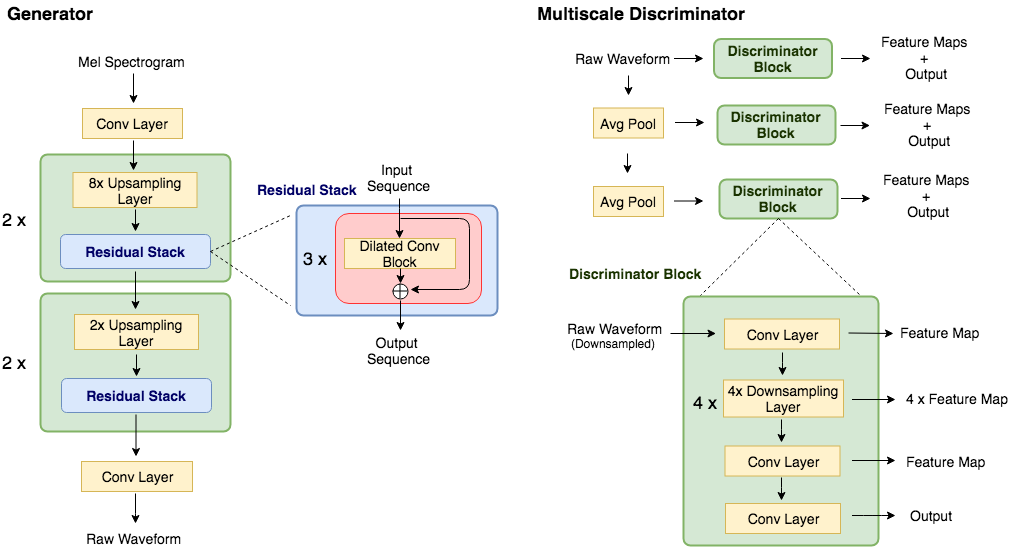
Unofficial PyTorch implementation of MelGAN vocoder
Key Features
- MelGAN is lighter, faster, and better at generalizing to unseen speakers than WaveGlow.
- This repository use identical mel-spectrogram function from NVIDIA/tacotron2, so this can be directly used to convert output from NVIDIA's tacotron2 into raw-audio.
- Pretrained model on LJSpeech-1.1 via PyTorch Hub.
Prerequisites
Tested on Python 3.6
pip install -r requirements.txt
Prepare Dataset
- Download dataset for training. This can be any wav files with sample rate 22050Hz. (e.g. LJSpeech was used in paper)
- preprocess:
python preprocess.py -c config/default.yaml -d [data's root path] - Edit configuration
yamlfile
Train & Tensorboard
python trainer.py -c [config yaml file] -n [name of the run]cp config/default.yaml config/config.yamland then editconfig.yaml- Write down the root path of train/validation files to 2nd/3rd line.
- Each path should contain pairs of
*.wavwith corresponding (preprocessed)*.melfile. - The data loader parses list of files within the path recursively.
tensorboard --logdir logs/
Pretrained model
Try with Google Colab: TODO
import torch
vocoder = torch.hub.load('seungwonpark/melgan', 'melgan')
vocoder.eval()
mel = torch.randn(1, 80, 234) # use your own mel-spectrogram here

if torch.cuda.is_available():
    vocoder = vocoder.cuda()
    mel = mel.cuda()

with torch.no_grad():
    audio = vocoder.inference(mel)
Inference
python inference.py -p [checkpoint path] -i [input mel path]
Results
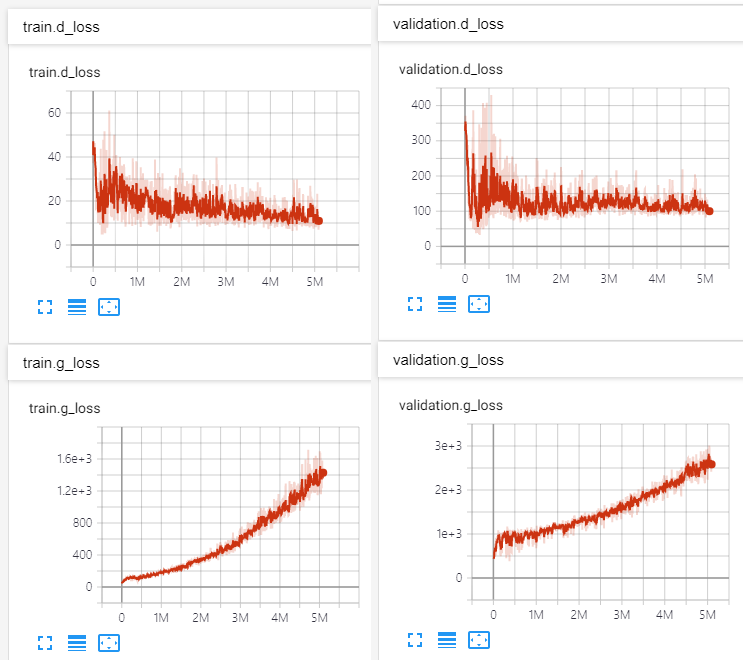
See audio samples at: http://swpark.me/melgan/. Model was trained at V100 GPU for 14 days using LJSpeech-1.1.
Implementation Authors
- Seungwon Park @ MINDsLab Inc. ([email protected], [email protected])
- Myunchul Joe @ MINDsLab Inc.
- Rishikesh @ DeepSync Technologies Pvt Ltd.
License
BSD 3-Clause License.
- utils/stft.py by Prem Seetharaman (BSD 3-Clause License)
- datasets/mel2samp.py from https://github.com/NVIDIA/waveglow (BSD 3-Clause License)
- utils/hparams.py from https://github.com/HarryVolek/PyTorch_Speaker_Verification (No License specified)
Useful resources
- How to Train a GAN? Tips and tricks to make GANs work by Soumith Chintala
- Official MelGAN implementation by original authors
- Reproduction of MelGAN - NeurIPS 2019 Reproducibility Challenge (Ablation Track) by Yifei Zhao, Yichao Yang, and Yang Gao
- "replacing the average pooling layer with max pooling layer and replacing reflection padding with replication padding improves the performance significantly, while combining them produces worse results"