
rilldata/rill has 2,987 GitHub stars and 206 forks. GitHot measured +2 stars in 24 hours. Last checked 2026-11-08 17:58 UTC. Last push 2026-11-02.
The fastest business intelligence tool for humans and agents.
Crecimiento de estrellas medido
- in 24h
- +2
- in 7 days
- Actualización retrasada
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
Original

Agent-first, human-friendly business intelligence


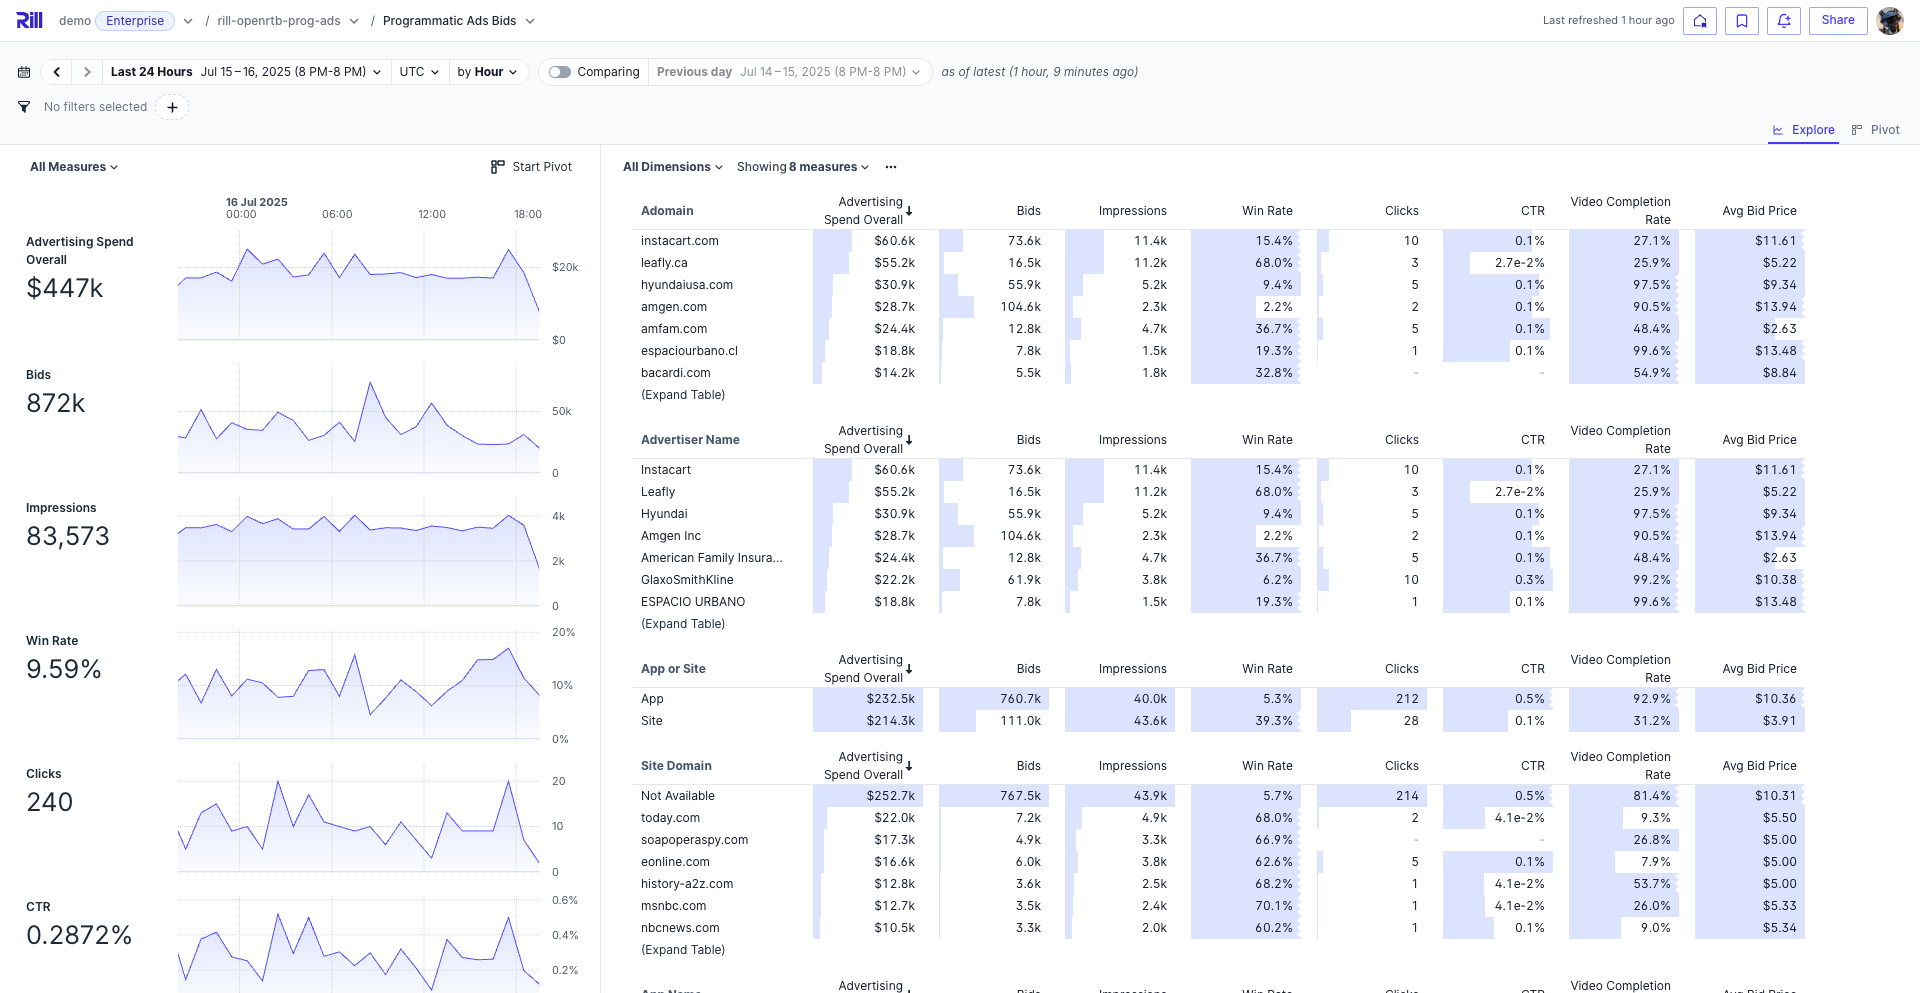
Rill is the fastest BI tool for humans and agents, powered by OLAP engines like ClickHouse and DuckDB.
Get Started
curl https://rill.sh | sh        # install
rill start my-project            # create a project and open the UI
Scaffold a project with agent context
Use rill init to scaffold a project interactively:
➜ rill init
? Project name my-rill-project
? OLAP engine duckdb
? Agent instructions claude

Created a new Rill project at ~/my-rill-project
Added Claude instructions in .claude and .mcp.json

Success! Run the following command to start the project:

  rill start my-rill-project
Why Rill?
- Build with agents — BI-as-code (YAML + SQL) means coding agents like Claude Code and Cursor can author projects, dashboards, and security policies end-to-end
- Semantic layer — Single source of truth for dimensions, measures, and time grains — defined in YAML, generating SQL at query time against your OLAP engine
- Explore with agents — Conversational BI lets business users query metrics in natural language; the MCP server connects AI agents directly to your semantic layer
- Real-time performance — Sub-second queries at any scale; ClickHouse for billions of rows, DuckDB for smaller datasets and fast iteration
- Embeddable — Dashboards, APIs, and agent interfaces you can ship in your product
Capabilities
Rill Developer (local)
- Connectors — S3, GCS, databases, and 20+ sources
- OLAP Engines — Managed ClickHouse or DuckDB included, or connect an external engine (ClickHouse Cloud, Druid, Pinot, MotherDuck)
- SQL Models — Transform raw data with SQL, join models together
- Data Profiling — Instant column stats and distributions
- Incremental Ingestion — Load only new data on each run to keep large datasets current without full refreshes
- Semantic Layer — Dimensions, measures, and time grains in YAML
- Row Access Policies — Per-user, per-group data access control
- Local Dashboards — Preview and explore dashboards locally
Rill Cloud
- Deploy — Git-backed, versioned deployments — push with
rill deployor connect a repo for automatic CI/CD - Explore & Canvas Dashboards — Interactive dashboards, embeddable in your product
- Conversational BI — Ask questions in natural language
- MCP Server — Connect Claude, ChatGPT, or any AI agent to your metrics
- Custom APIs & Embedding — Expose metrics via REST or embed dashboards
- Alerts & Reports — Threshold alerting, code-defined or UI-defined
How It Works
Define everything in code — models, metrics, dashboards — and Rill handles the rest.
1. Connect data — models/events.yaml
type: model
connector: duckdb
materialize: true

sql: |
  select * from read_parquet('gs://rilldata-public/auction_data.parquet')
2. Define metrics — metrics/events_metrics.yaml
version: 1
type: metrics_view
model: events
timeseries: timestamp

dimensions:
  - name: country
    column: country
  - name: device
    column: device_type

measures:
  - name: total_events
    expression: count(*)
  - name: revenue
    expression: sum(price * quantity)
    description: Total revenue
3. Create a dashboard — dashboards/events_explore.yaml
type: explore

display_name: "Events Dashboard"
metrics_view: events_metrics

dimensions: "*"
measures: "*"
4. Deploy
rill deploy # push to Rill Cloud
Your metrics view is immediately queryable on Rill Cloud — add YAML files to configure dashboards, alerts, and custom APIs.
Learn More
Getting Started with Rill Developer • Exploring Data with Rill • Data Talks on the Rocks • Agentic Analytics with Claude Code and Rill
Examples
| Example | Description | Links |
|---|---|---|
| Programmatic Ads | Bidstream data for pricing and campaign performance | GitHub · Demo |
| Cost Monitoring | Cloud infra merged with customer data | GitHub · Demo |
| GitHub Analytics | Contributor activity and commit patterns | GitHub · Demo |
Or explore a live embedded dashboard.
Community

Contributing
We welcome contributions! See our Contributing Guide to get started.
Explorar proyectos relacionados
Asabeneh/30-Days-Of-Python
El reto de programación 30 Days of Python es una guía paso a paso para aprender el lenguaje de programación Python en 30 días. Este reto puede llevar más de 100 días. Sigue tu propio ritmo. Estos vídeos también pueden ayudarte: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,423 estrellasgrafana/grafana
Plataforma abierta y componible de observabilidad y visualización de datos. Visualiza métricas, registros y trazas de múltiples fuentes, como Prometheus, Loki, Elasticsearch, InfluxDB, Postgres y muchas más.
77,763 estrellasredis/redis
Para los desarrolladores que crean aplicaciones en tiempo real basadas en datos, Redis es la opción preferida, la más rápida y la de más funciones como caché, servidor de estructuras de datos y motor de consultas de documentos y vectores.
77,309 estrellasapache/superset
Apache Superset es una plataforma de visualización y exploración de datos.
75,453 estrellas