
psmarter/mini-infer
psmarter/mini-infer has 220 GitHub stars and 12 forks. GitHot measured -1 stars in 24 hours. Last checked 2026-11-19 14:44 UTC. Last push 2026-04-24.
Crecimiento de estrellas medido
- in 24h
- -1
- in 7 days
- Recopilando historial
- in 15 days
- Recopilando historial
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
LLM inference engine from scratch — paged KV cache, continuous batching, chunked prefill, prefix caching, speculative decoding, CUDA graph, tensor parallelism, OpenAI-compatible serving
Aprendizaje automáticoREADME.md
Originalmini-infer
LLM inference engine built from scratch — paged KV cache, continuous batching, chunked prefill, prefix caching, speculative decoding, CUDA graph, tensor parallelism, and OpenAI-compatible HTTP serving. Each mechanism has a dedicated benchmark with quantitative results. Core serving path reaches 100% of HF baseline throughput at batch=8; concurrent HTTP throughput scales 3.9× (1→8 clients, 55.7→219.1 tok/s). Ships with dry-run mode (no model weights needed), /healthz, Docker, and CI.
从零实现的 LLM 推理引擎。核心 serving 路径(PagedAttention + Continuous Batching + OpenAI HTTP API)在 Qwen2.5-7B 达到 HF Transformers 100% 吞吐,支持
--dry-run无权重启动验证。


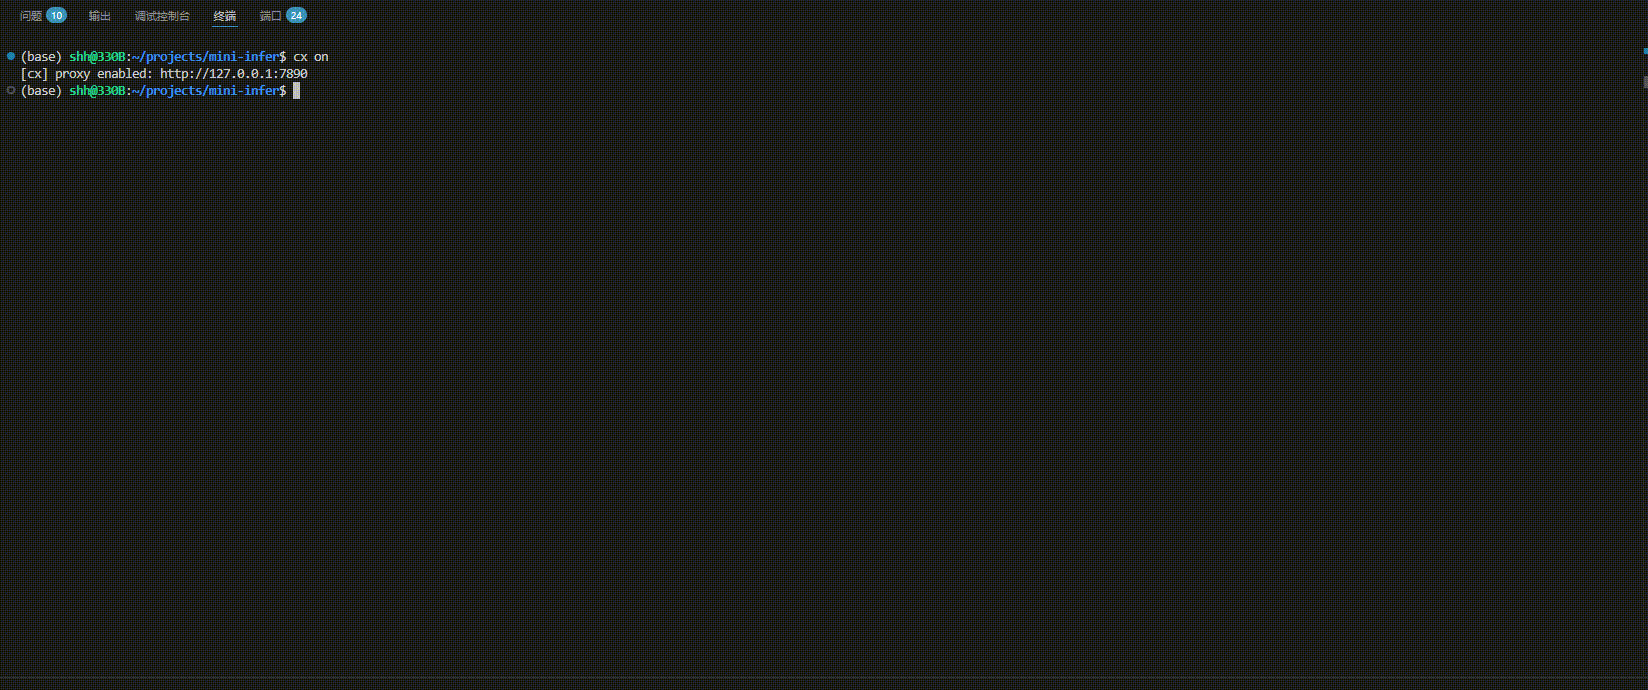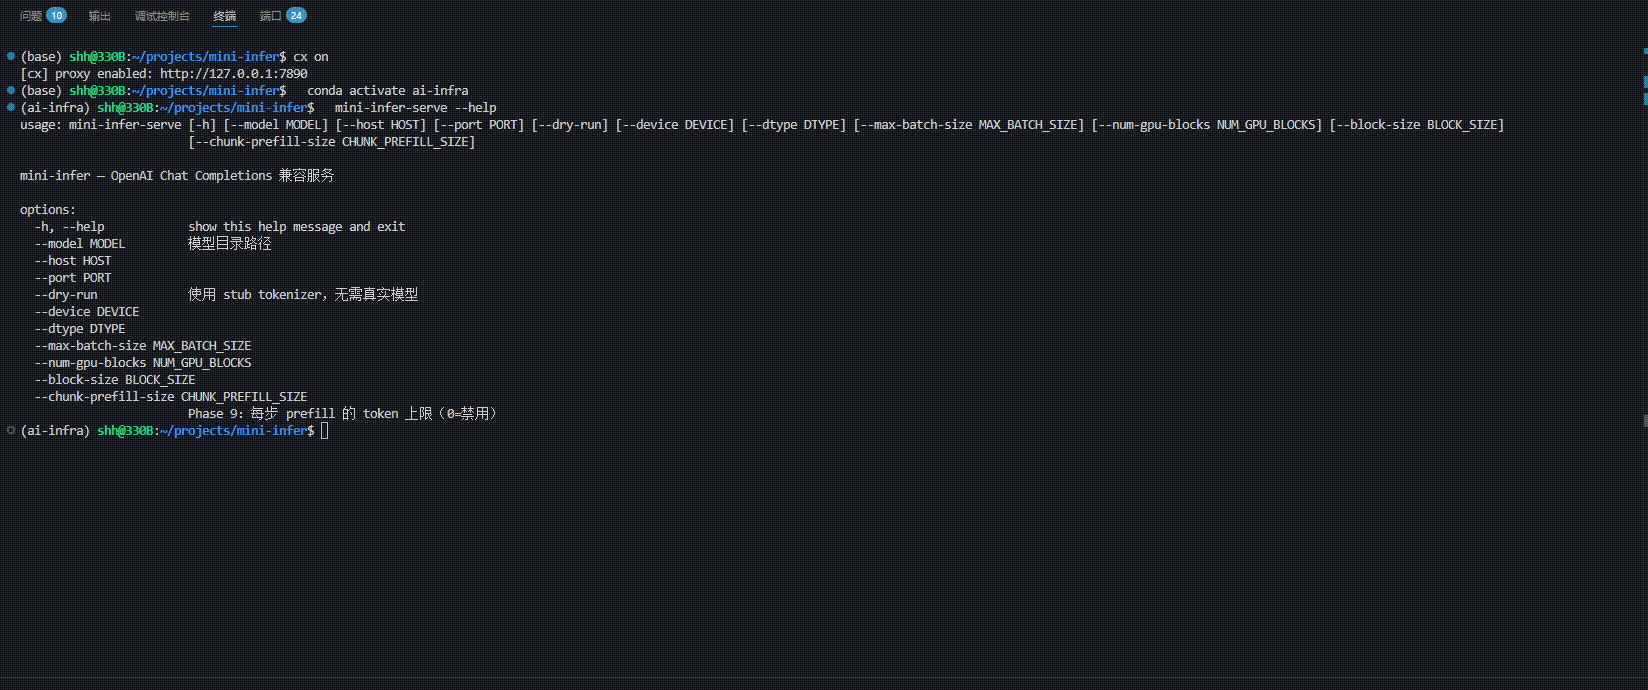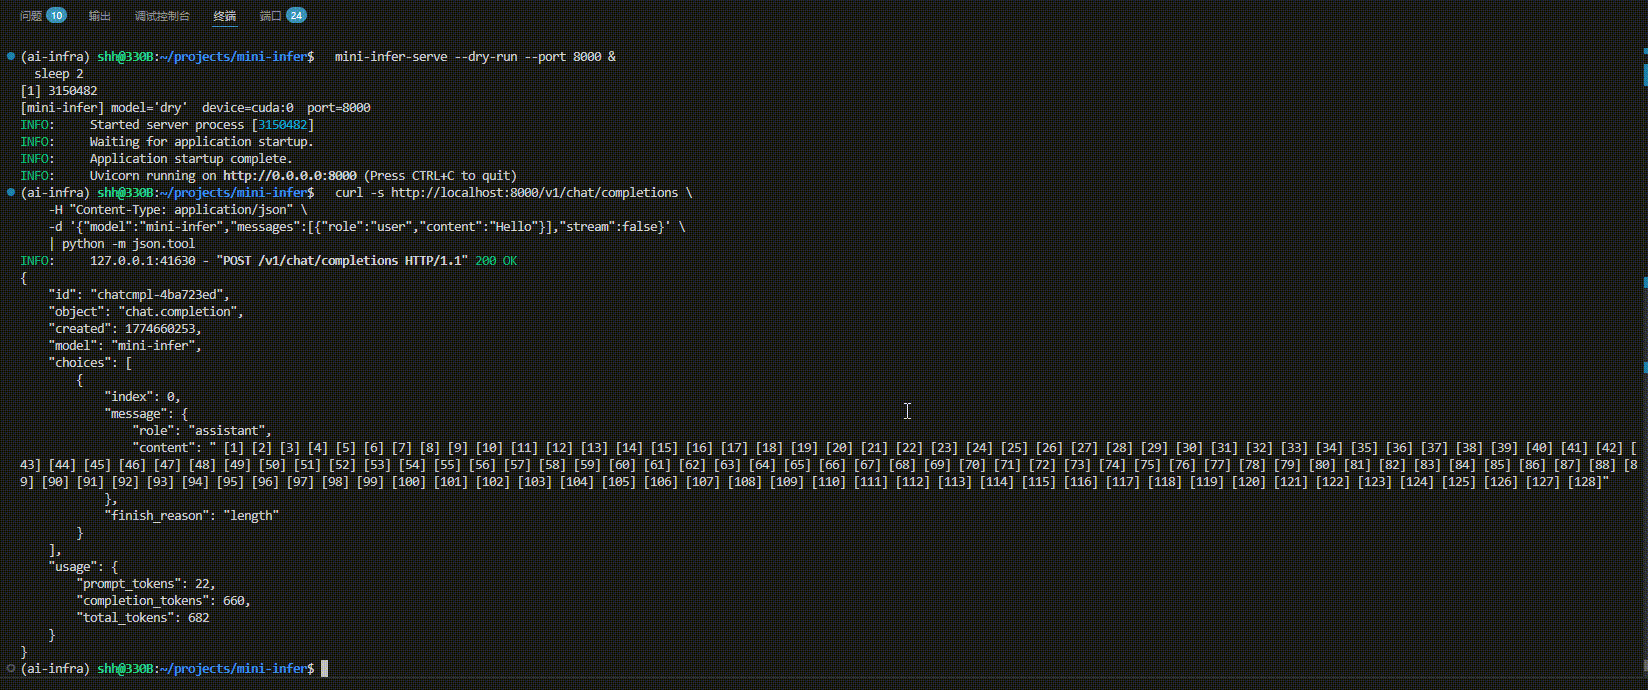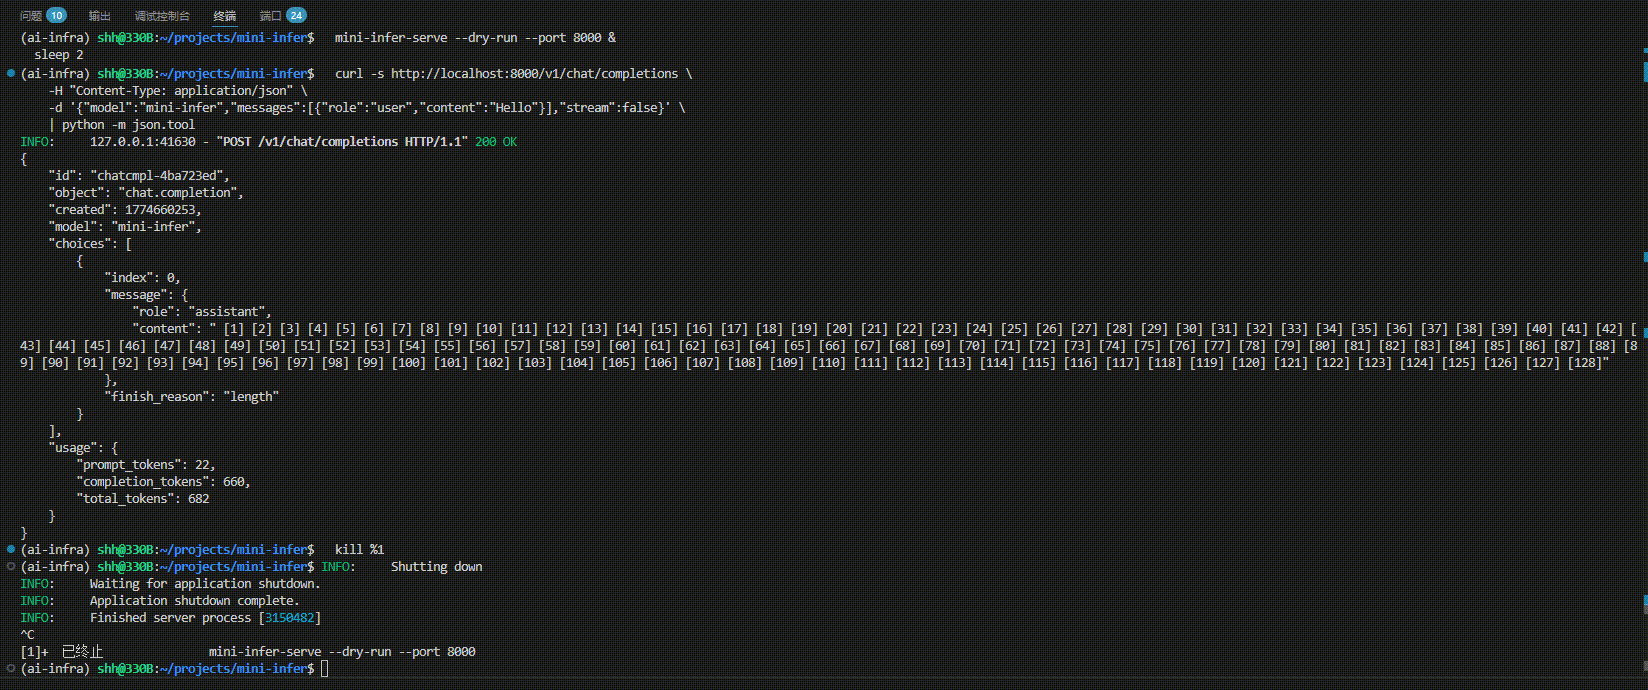
立即验证(无需模型权重)
pip install -e ".[serve,dev]"
mini-infer-serve --dry-run --port 8000
curl http://localhost:8000/healthz   # → {"status":"ok","model":"dry",...}
核心成果
主 serving 路径(mini-infer-serve 默认启动)
| 技术 | 关键数据 |
|---|---|
| Continuous Batching HTTP API(AsyncEngine + OpenAI 兼容) | 并发 1→8 吞吐 55.7→219.1 tok/s(3.9×,Qwen2.5-7B,RTX 4090) |
| True PagedAttention(flash_attn block_table) | batch=8 吞吐达到 HF Transformers 100%(406 tok/s) |
| Chunked Prefill | 混合 serving 场景 ITL spike 降低 57%–67% |
| Prefix Caching(block-level hash + LRU) | 共享前缀 TTFT −22% |
独立 benchmark 实验(功能完整,未接入默认 serving 路径)
| 技术 | 关键数据 |
|---|---|
| Speculative Decoding(0.5B draft + 7B target) | acceptance rate 55.85% |
| CUDA Graph(decode_batch 静态捕获) | 1.5B bs=1 decode 延迟 −28.9% |
| Flash Decoding(Triton split-K) | seq=4096 延迟 3.31× vs 标准 Triton,SM 利用率 9%→103% |
| Tensor Parallelism(NCCL all-reduce,Megatron-LM 风格) | TP=2 greedy 输出与单卡完全一致(见注 ¹) |
| PD 解耦(同机双进程) | TTFT 三段分解:prefill 12.3ms / transfer ≈14.7ms / decode 519ms |
原型实现(correctness-first,有明确边界限制)
完整 benchmark 数据与复现命令见 docs/benchmarks.md。
| 主线吞吐演进 | Chunked Prefill ITL |
|---|---|
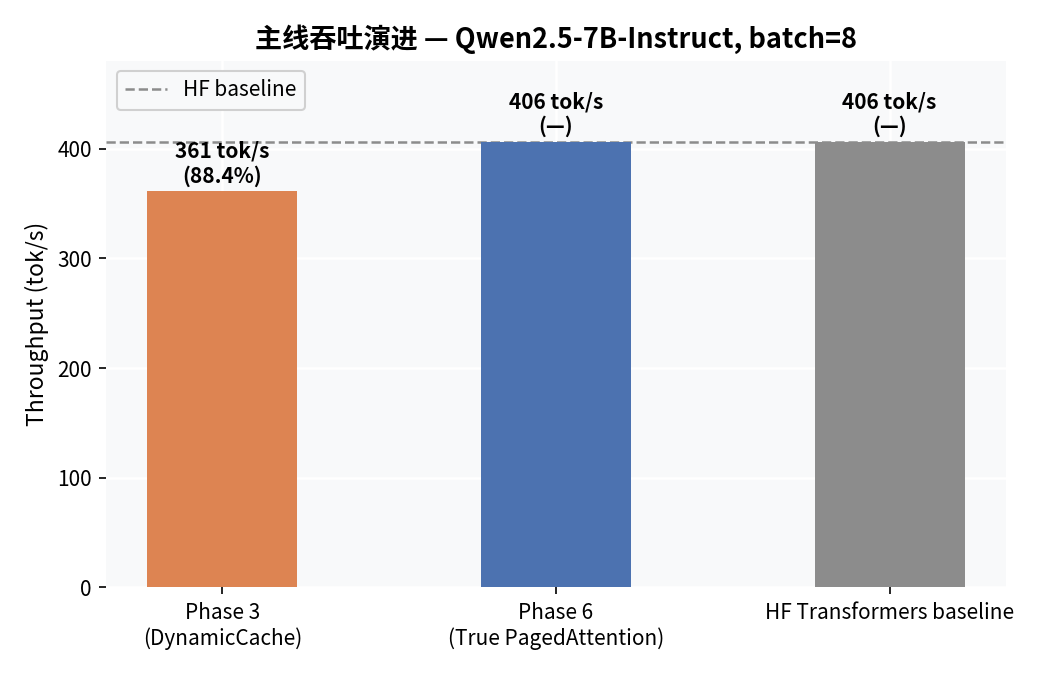 |
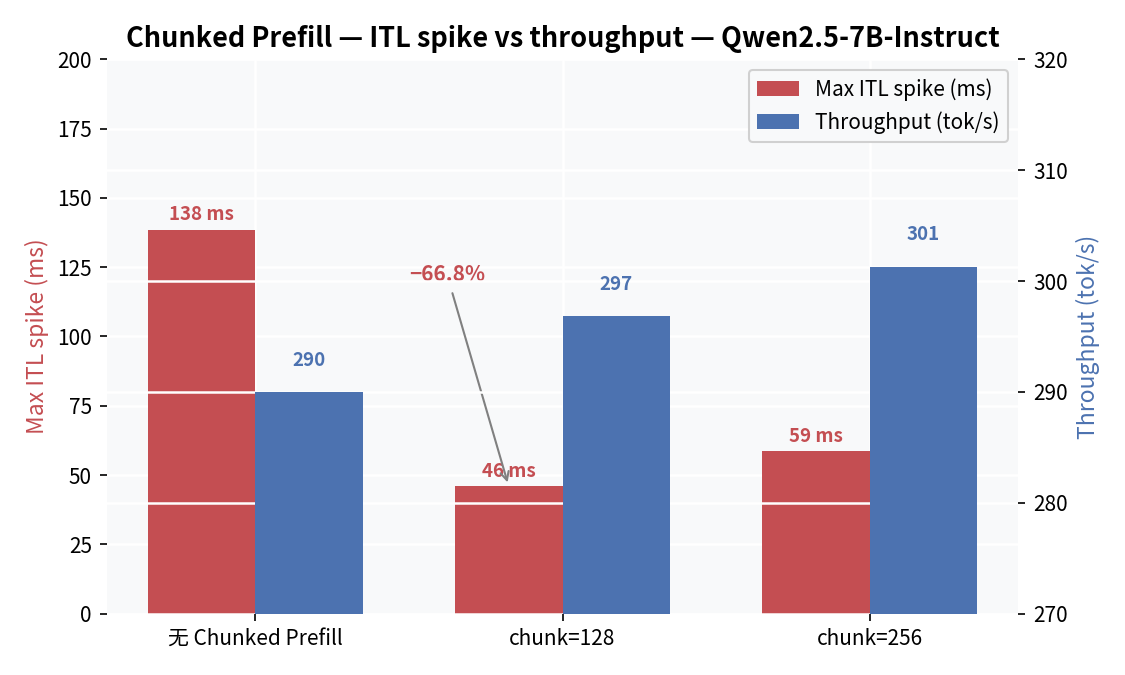 |
| Flash Decoding(seq_len sweep) | CUDA Graph decode 延迟 |
|---|---|
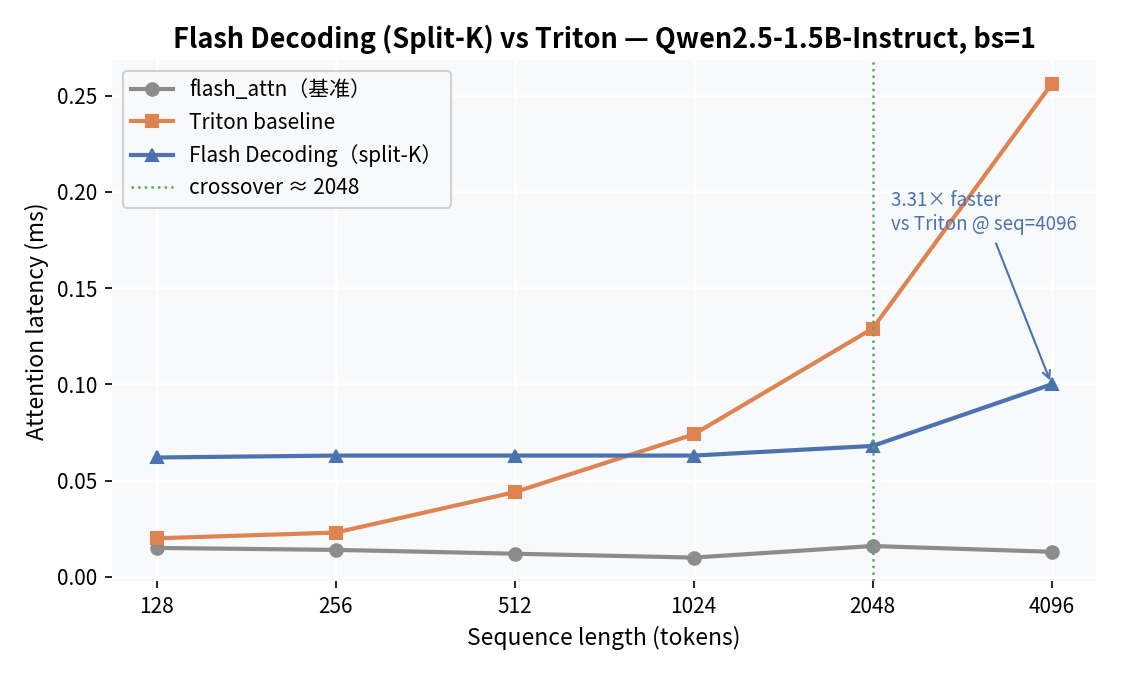 |
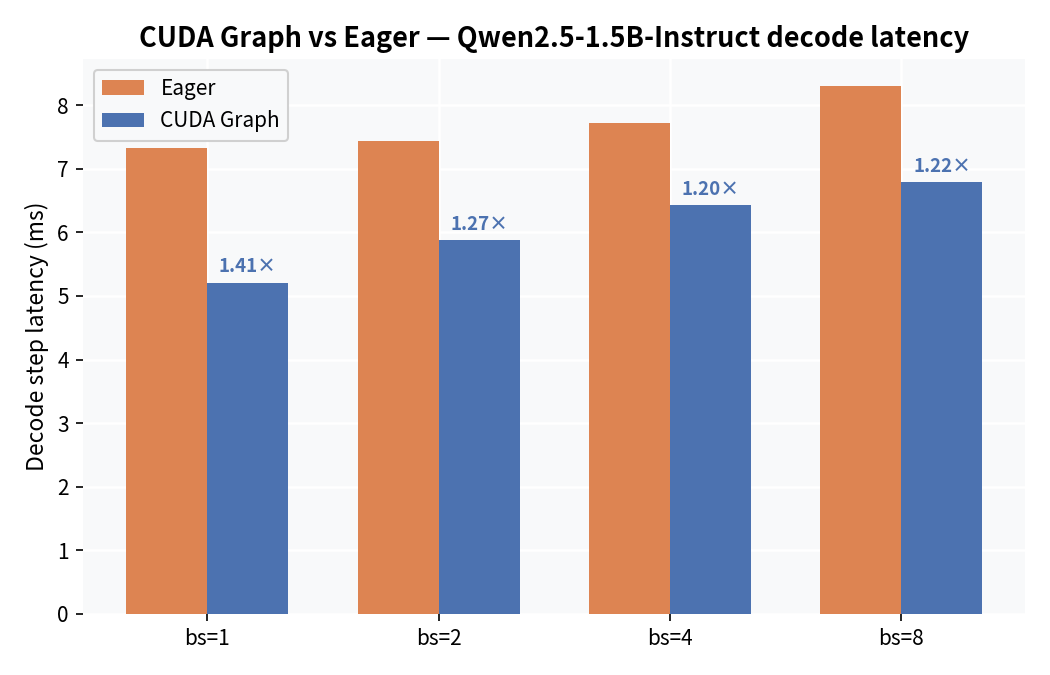 |
¹ TP 说明:1.5B 模型规模下,2 卡 NCCL all-reduce 通信开销超过计算节省,吞吐未提升;当前验收结论为 greedy 输出与单卡完全一致(正确性已验证)。TP 适用于单卡显存不足时的大模型横向扩展。
快速开始
git clone https://github.com/psmarter/mini-infer && cd mini-infer
pip install -e ".[serve,dev]"

# 无需模型权重,立即验证服务接口
mini-infer-serve --dry-run --port 8000

# 真实模型(需要 Qwen2.5-7B-Instruct)
mini-infer-serve --model /path/to/Qwen2.5-7B --port 8000

# 开启 CUDA Graph
mini-infer-serve --model /path/to/Qwen2.5-7B --use-cuda-graph  --port 8000
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model":"mini-infer","messages":[{"role":"user","content":"Hello"}],"stream":false}'
Python 完整示例(streaming / 多轮对话)见 examples/openai_client.py。
目录结构
mini_infer/
├─ core/        # EngineConfig、Request、SamplingParams
├─ runtime/     # LLMEngine、Scheduler、AsyncEngine、SpecEngine、PDEngine
├─ cache/       # KVCacheManager(BlockTable + Prefix Cache)
├─ modeling/    # ModelRunner
├─ kernels/     # PagedAttention、Triton decode、Flash Decoding
├─ parallel/    # TP、Replica、PP
└─ serving/     # FastAPI server、OpenAI schema

benchmarks/     # 每项能力对应一个 benchmark 脚本(21 个)
tests/          # 287 collected items(含参数化展开),大多数支持 dry_run,不依赖模型权重
make test-fast 跑 CPU dry-run 全量测试(约 10s);make test 含 GPU 专项。
文档
| 文档 | 内容 |
|---|---|
| docs/architecture.md | 包结构、模块说明、请求生命周期 |
| docs/benchmarks.md | 所有能力的 benchmark 数据与复现命令 |
| docs/faq.md | 常见问题:安装、环境、CUDA Graph |
| docs/roadmap.md | 后续扩展方向与已知 gap |
与 vLLM 的区别
| 维度 | mini-infer | vLLM |
|---|---|---|
| 目标 | 从零实现并测量关键推理机制 | 生产级:高吞吐、多模型、SLO 保障 |
| PagedAttention | 与 vLLM 同路线(flash_attn block_table) | 相同路线,更成熟 |
| 模型覆盖 | Qwen2.5 / DeepSeek-V2 | 数十种架构,自动适配 |
| 调度器 | 手工实现,四队列 + chunked prefill | 完整 SLO、KV 共享感知 |
| 部署 | 单机原型 | K8s、多机 RDMA、完整监控 |
环境
| 依赖 | 版本 |
|---|---|
| Python | 3.10+ |
| PyTorch | 2.1.2+cu121 |
| transformers | 4.43.4 |
| flash-attn | 2.5.9.post1(block_size 须为 256 的倍数) |
| CUDA | 12.1 / RTX 4090 |
License
MIT