
pixelooz/hinder-db
pixelooz/hinder-db has 69 GitHub stars and 3 forks. Star changes are not measured yet. Last checked 2026-11-13 04:06 UTC. Last push 2026-08-31.
An SQLite like relational database built for education using real database architectural patterns.
Crecimiento de estrellas medido
- in 24h
- Recopilando historial
- in 7 days
- Recopilando historial
- in 15 days
- Recopilando historial
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
OriginalHinderDb


👋 Hey there! I'm a 4th-year CS student looking for an internship or a full-time Software Engineering role. You can Connect with me on LinkedIn or reach out via Email.
HinderDb is an embedded relational database I wrote from scratch in Rust. I wanted to learn how databases worked internally, which led me to write this entire (7k loc) database with a custom slotted-page B+Tree storage engine, a Buffer Pool for in-memory cache (or more correctly 'frame') management, after a page/block is fetched from disk, a Write Ahead Log for ensuring Durability, a custom Lexer and Parser, and finally the Volcano-Iterator based execution pipeline.
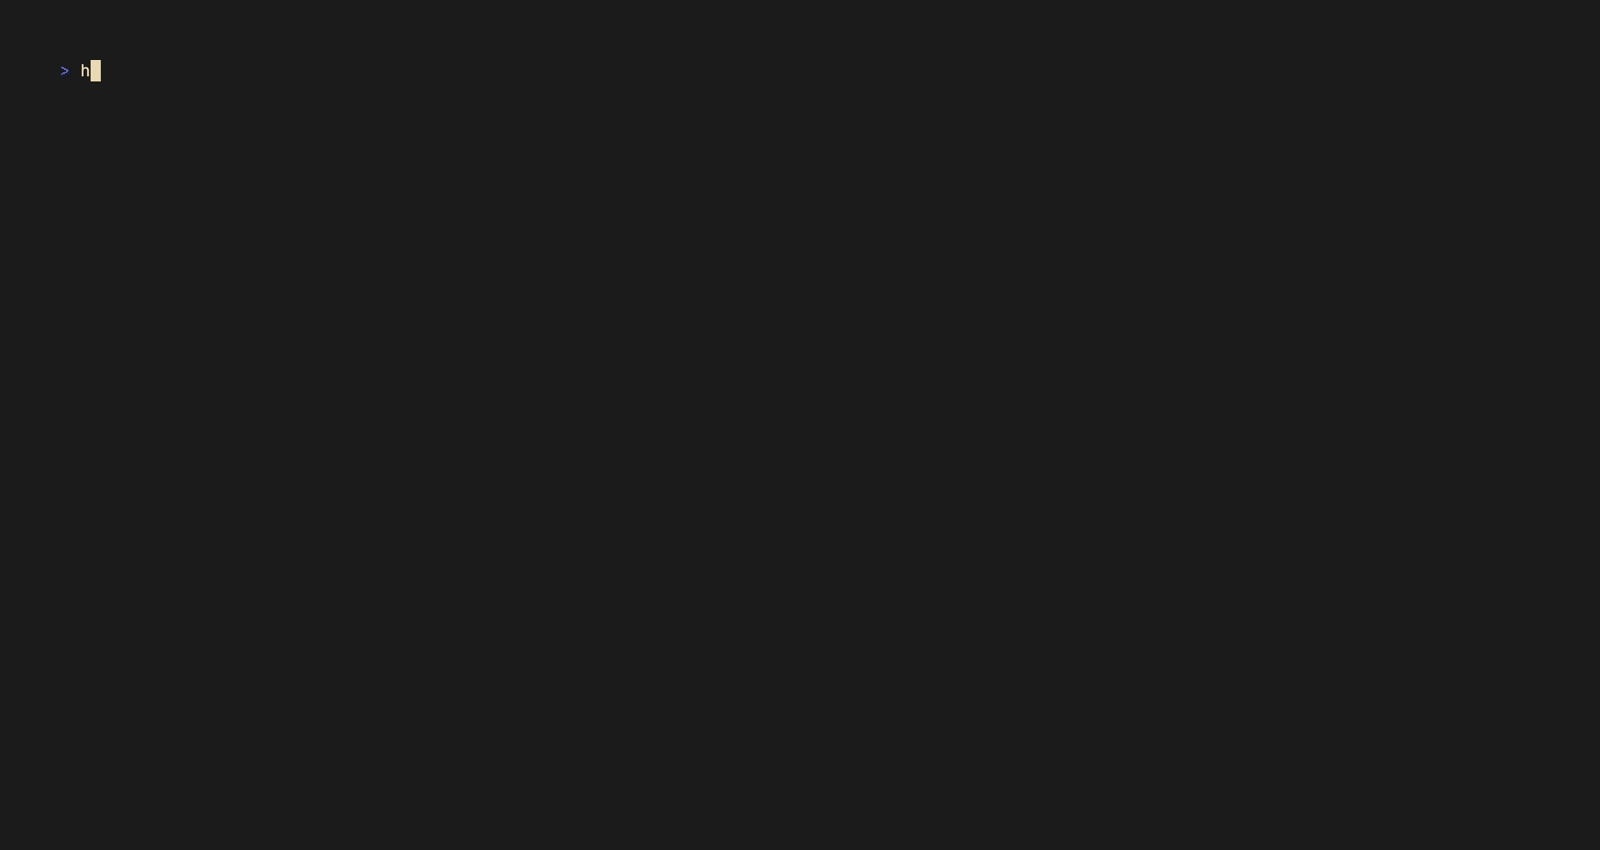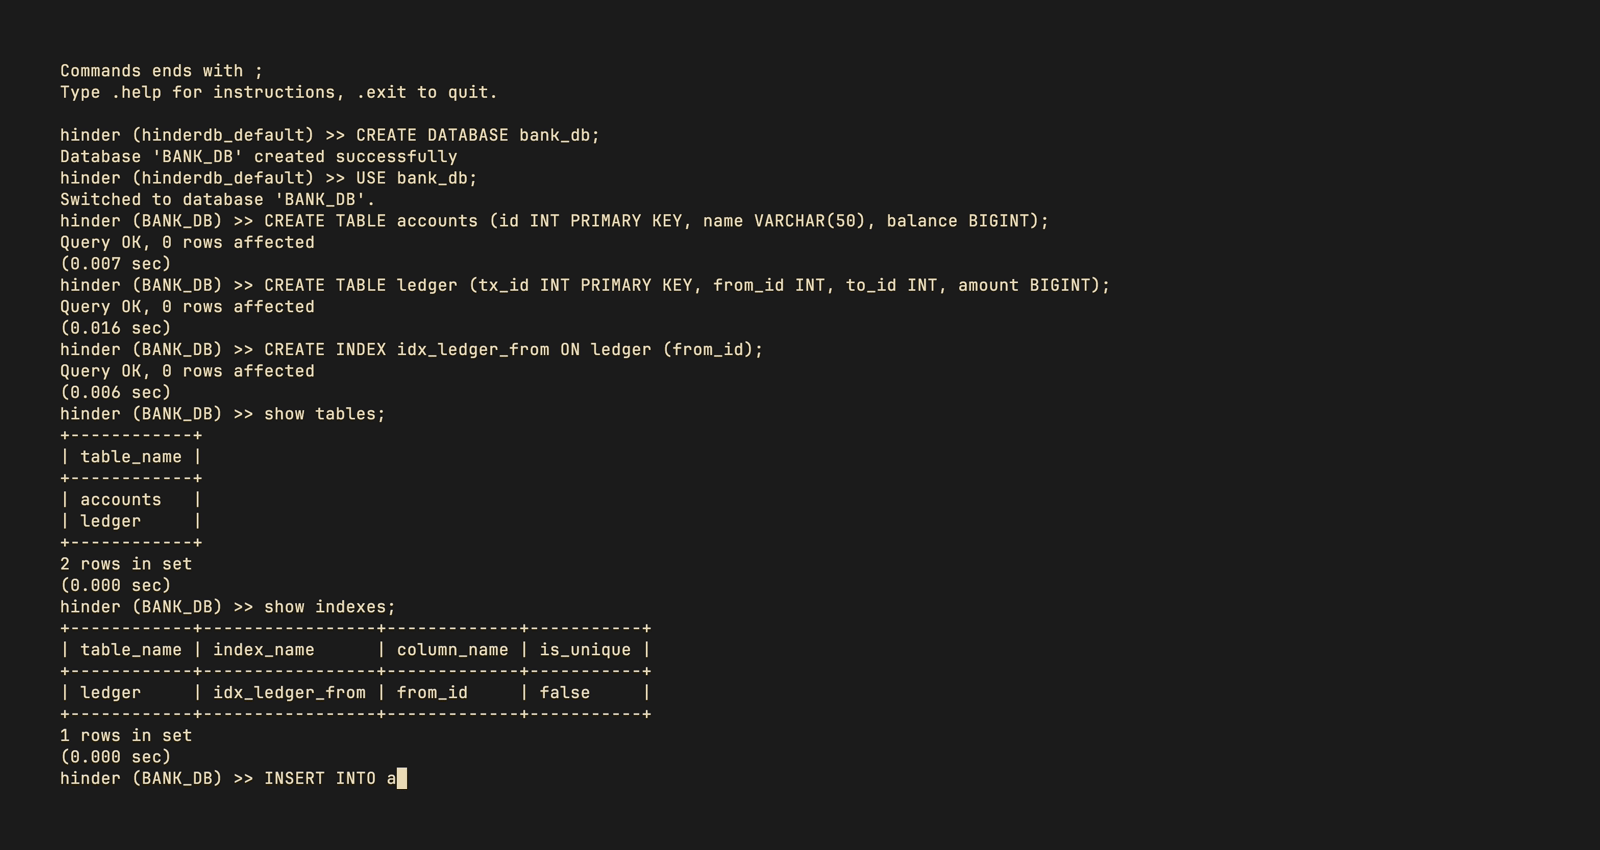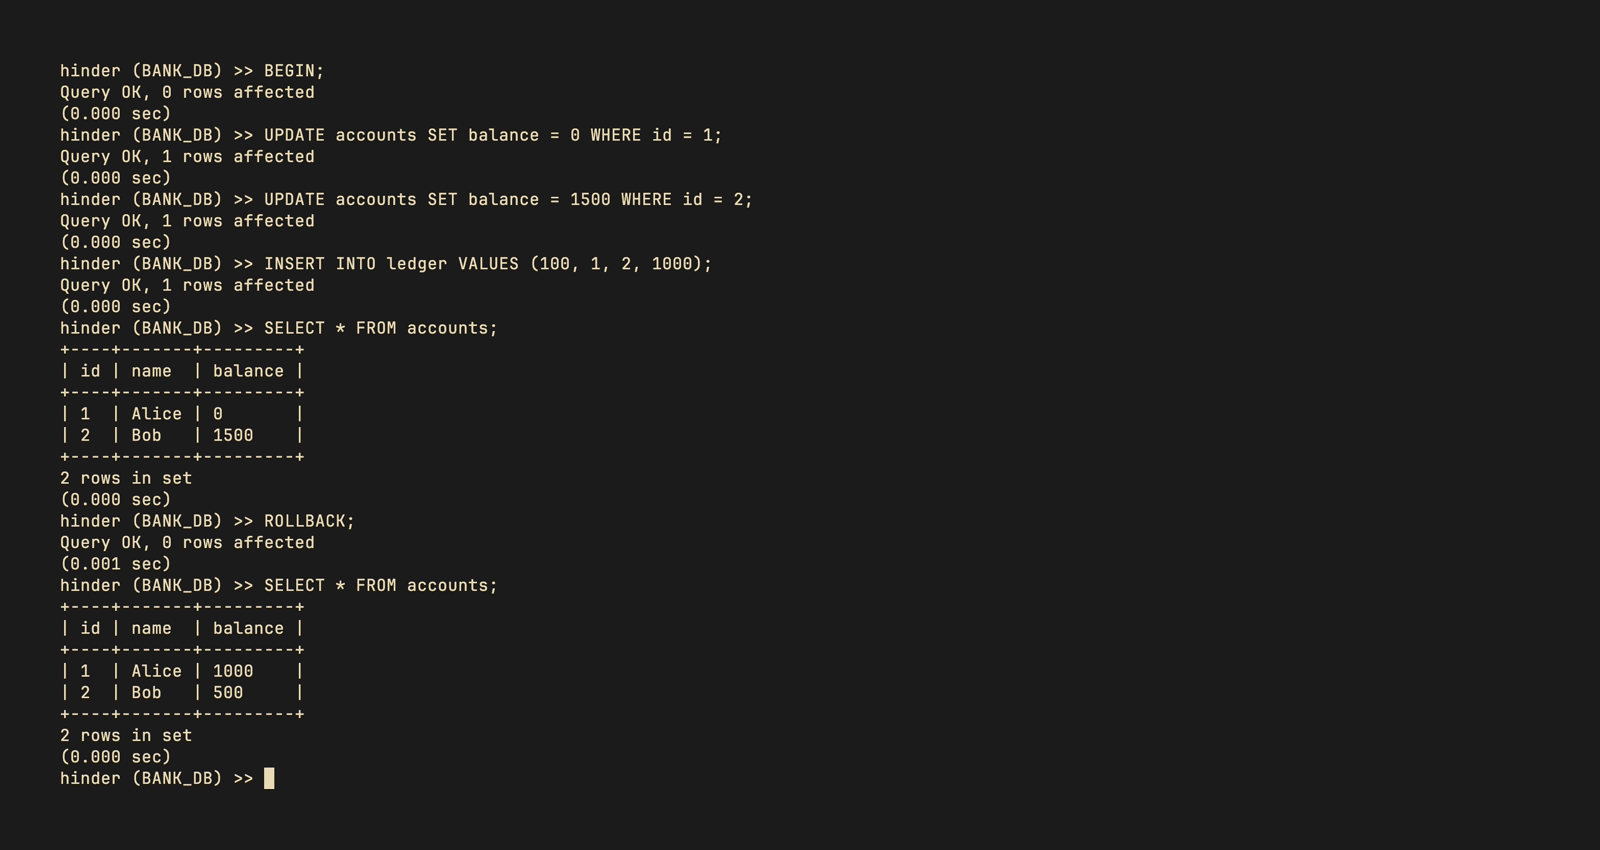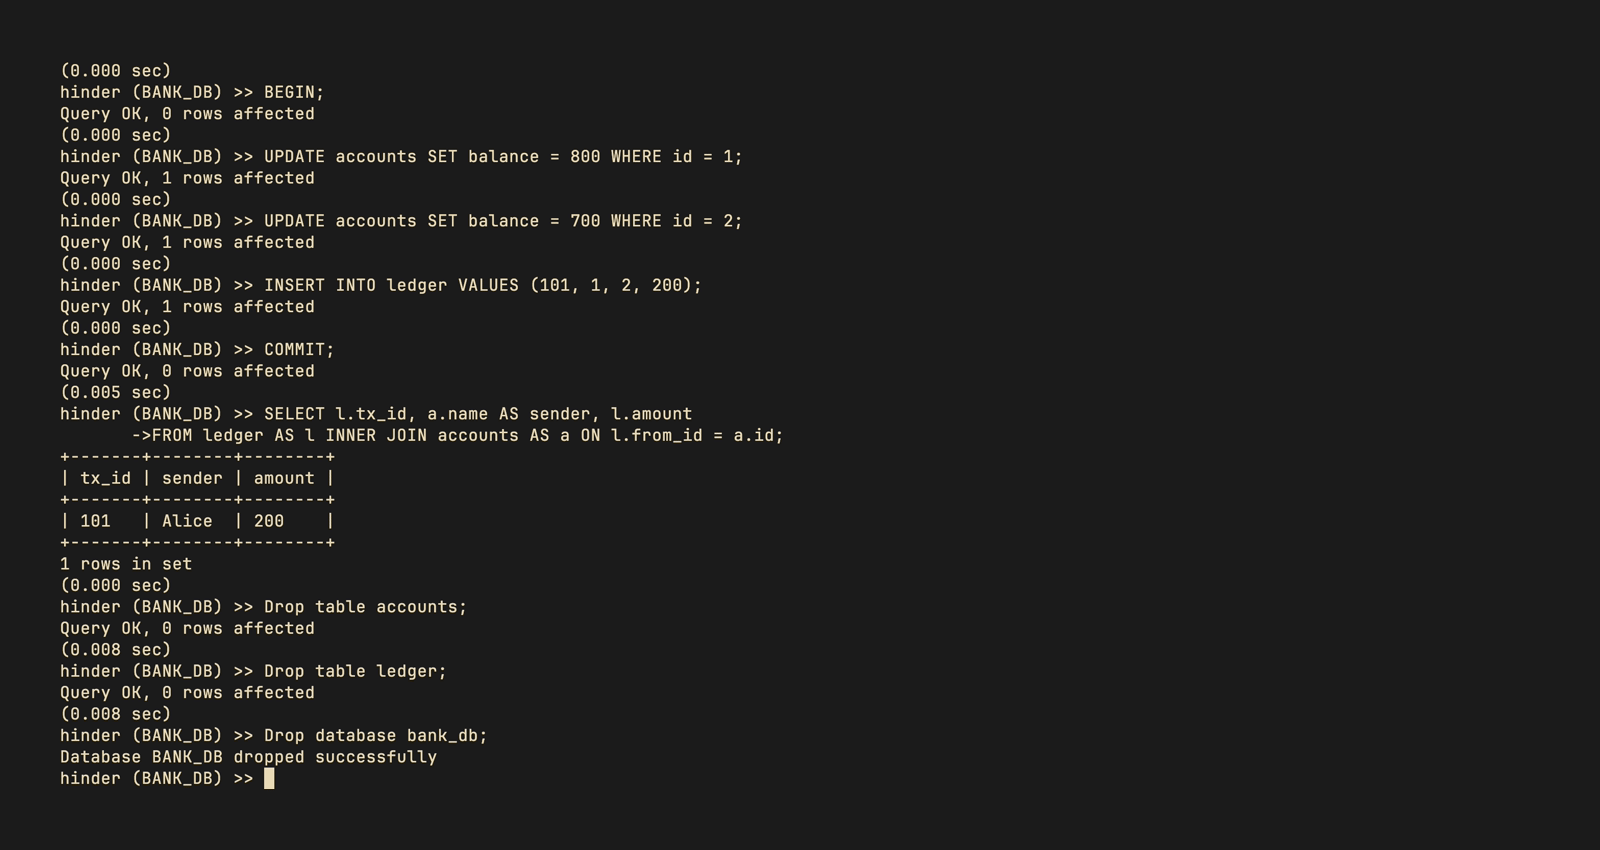
Some Examples
The messages of how many rows were affected only show rows affected with normal CRUD operations and not with rollbacks and other similar operations that are not basic CRUD (limitations, hehe).
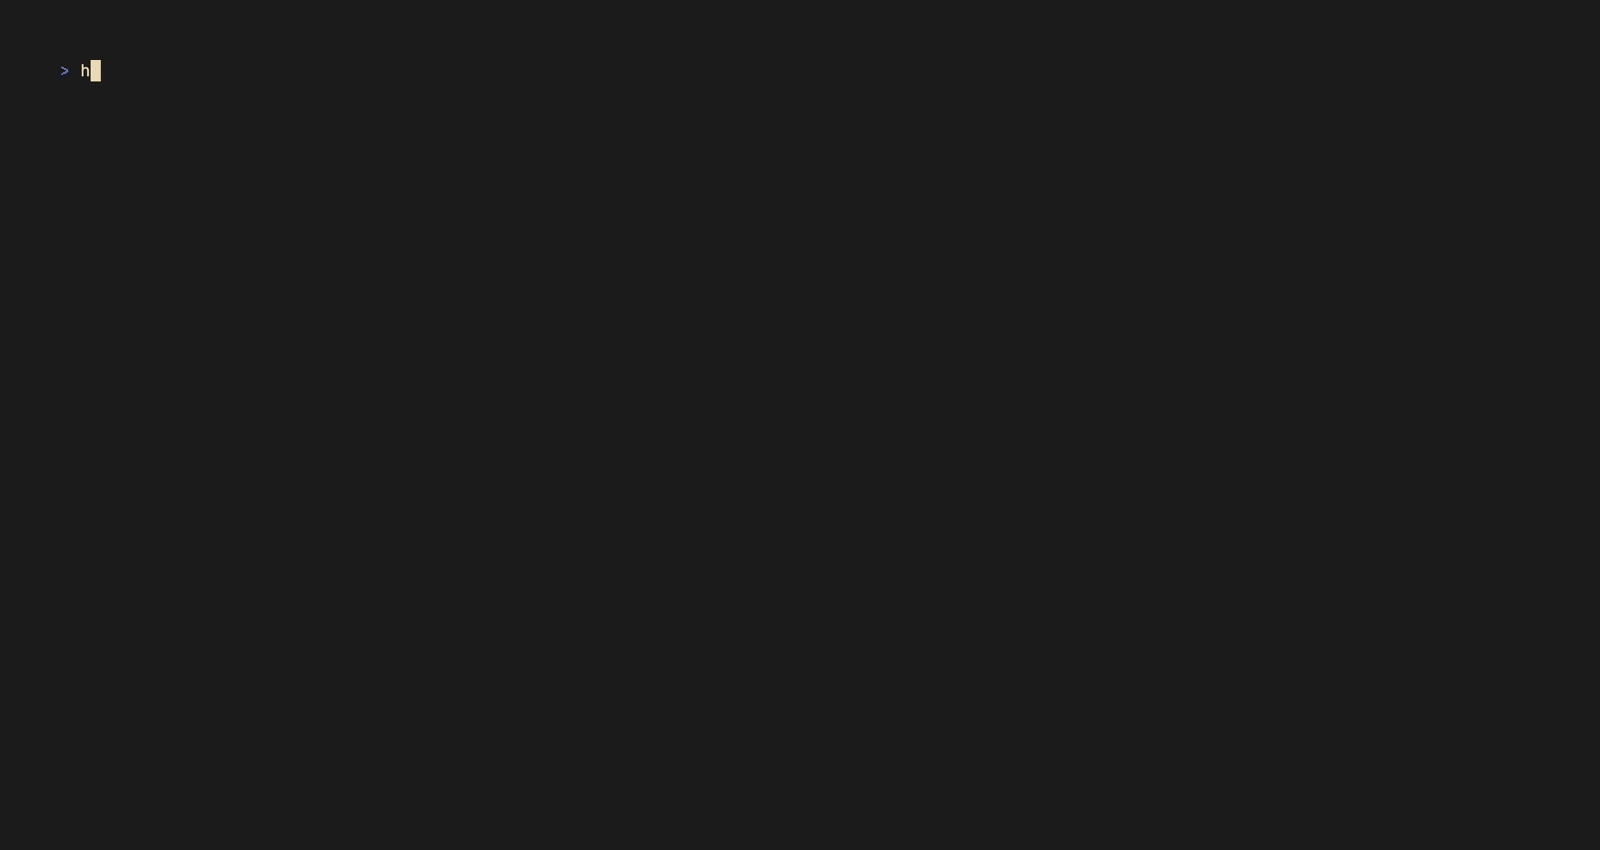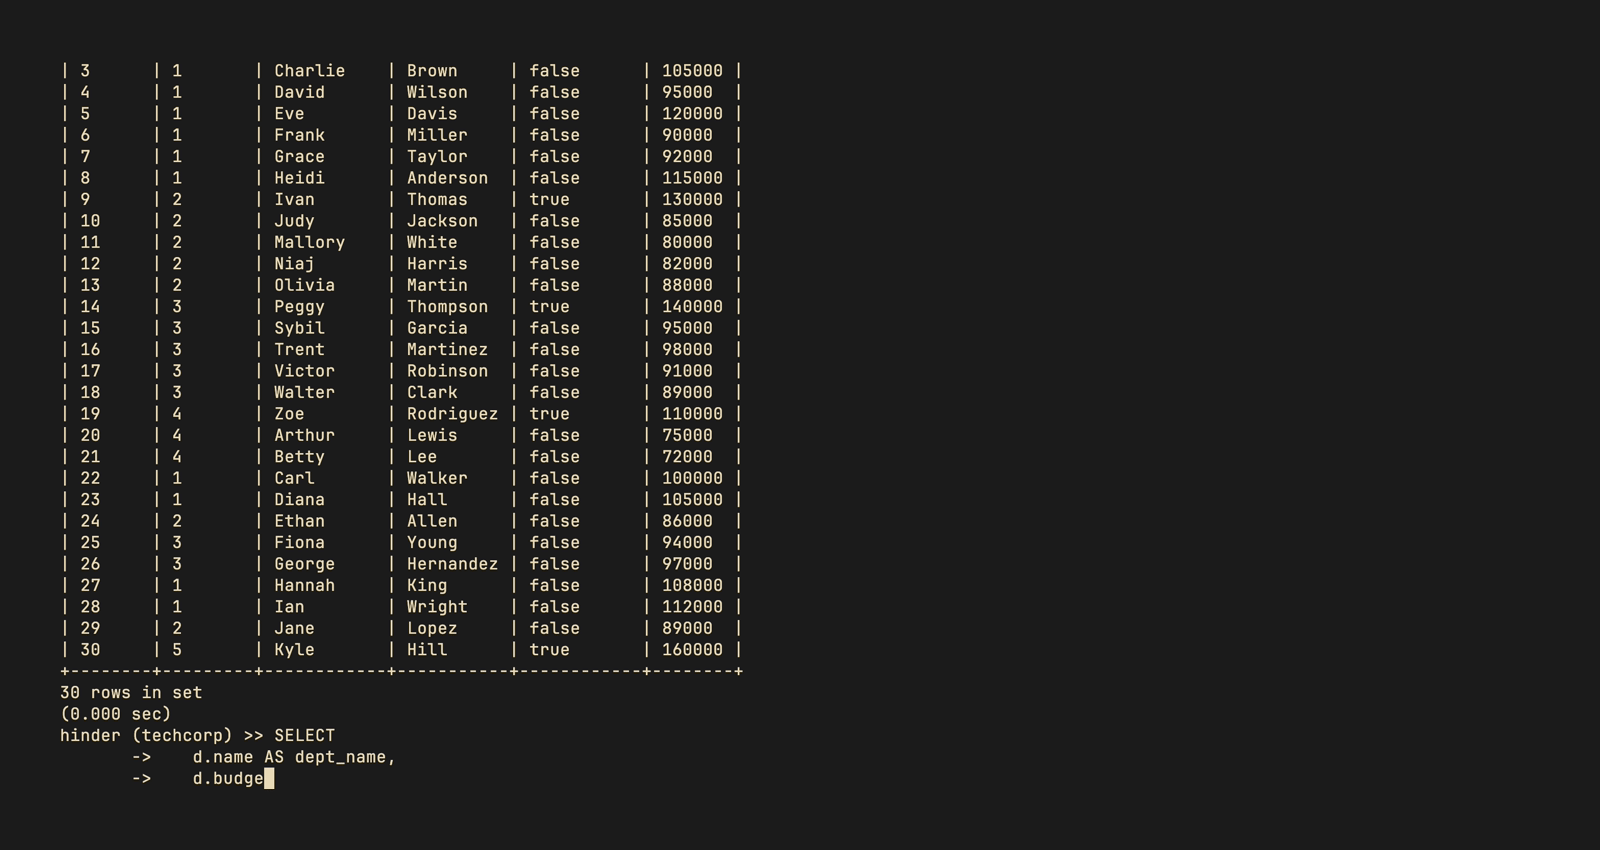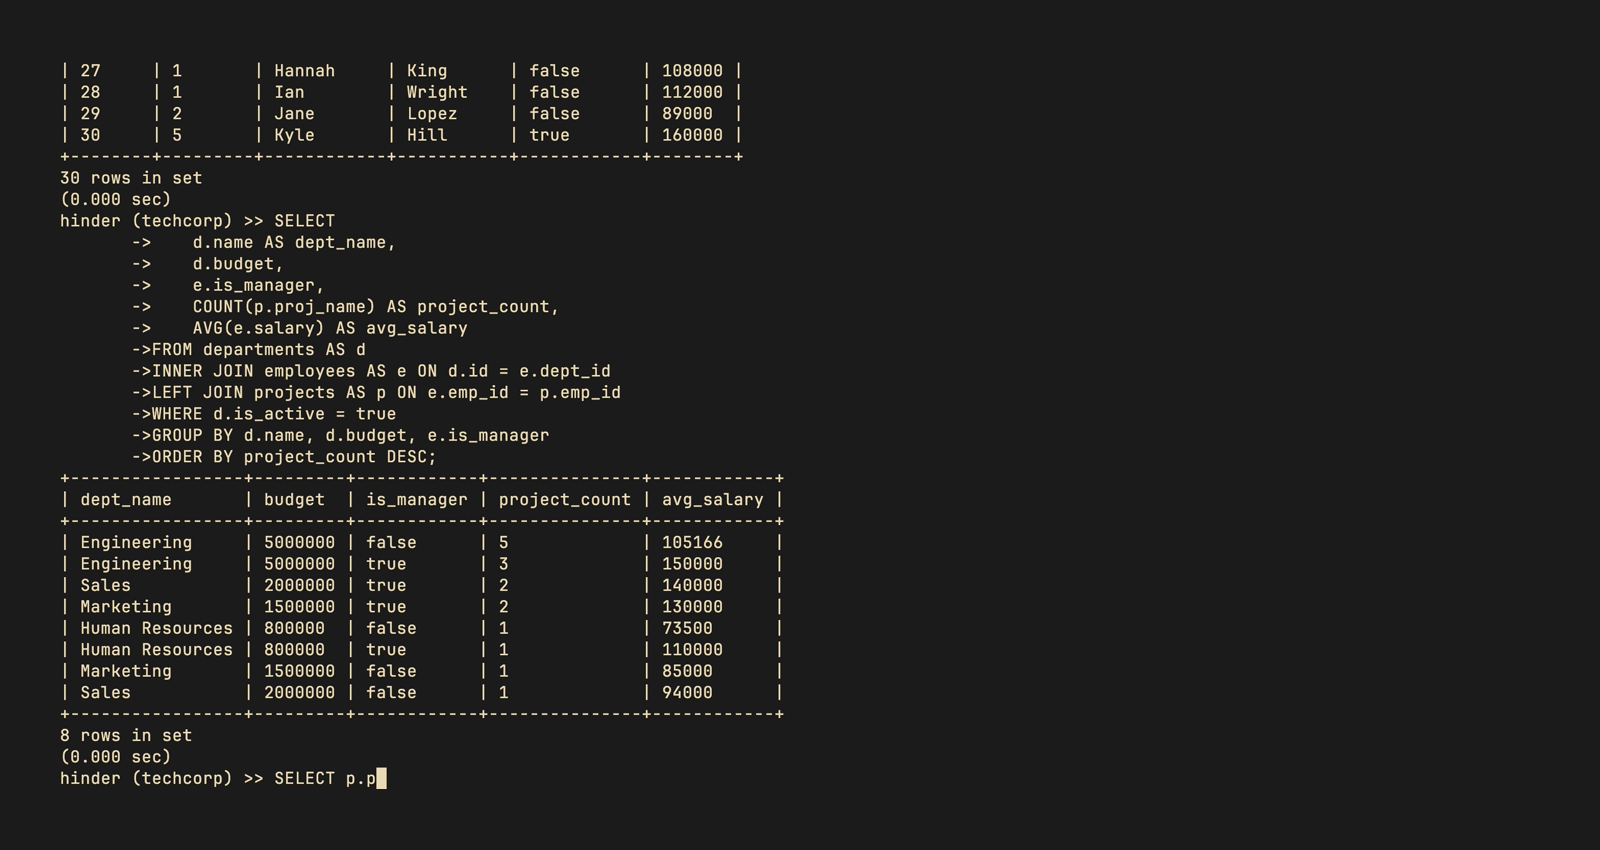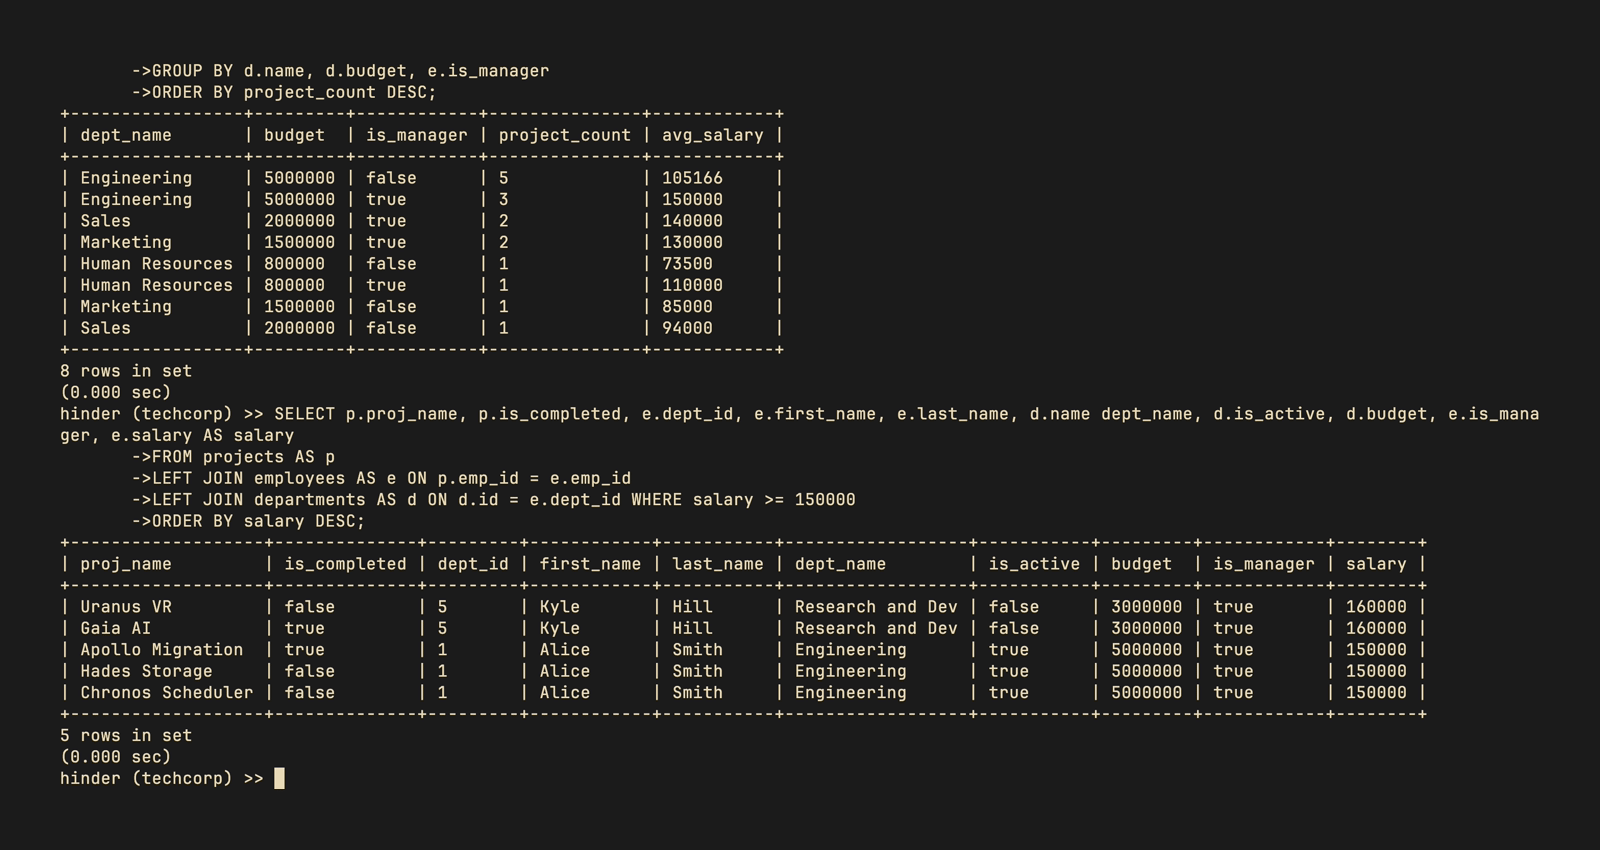
General Queries with JOINs and AGGREGATES
Crash Recovery
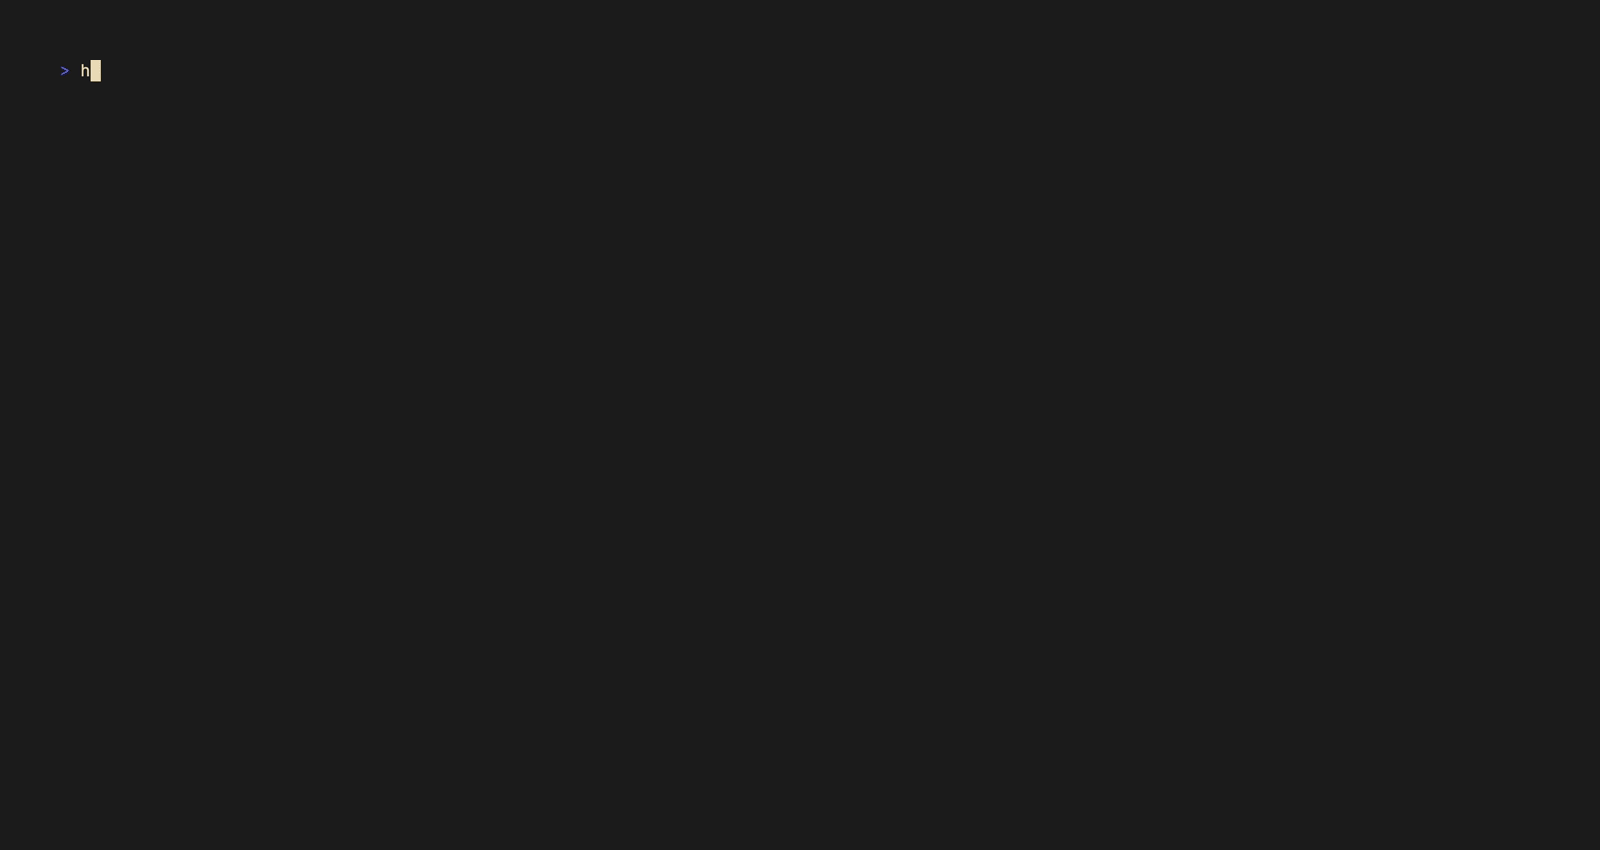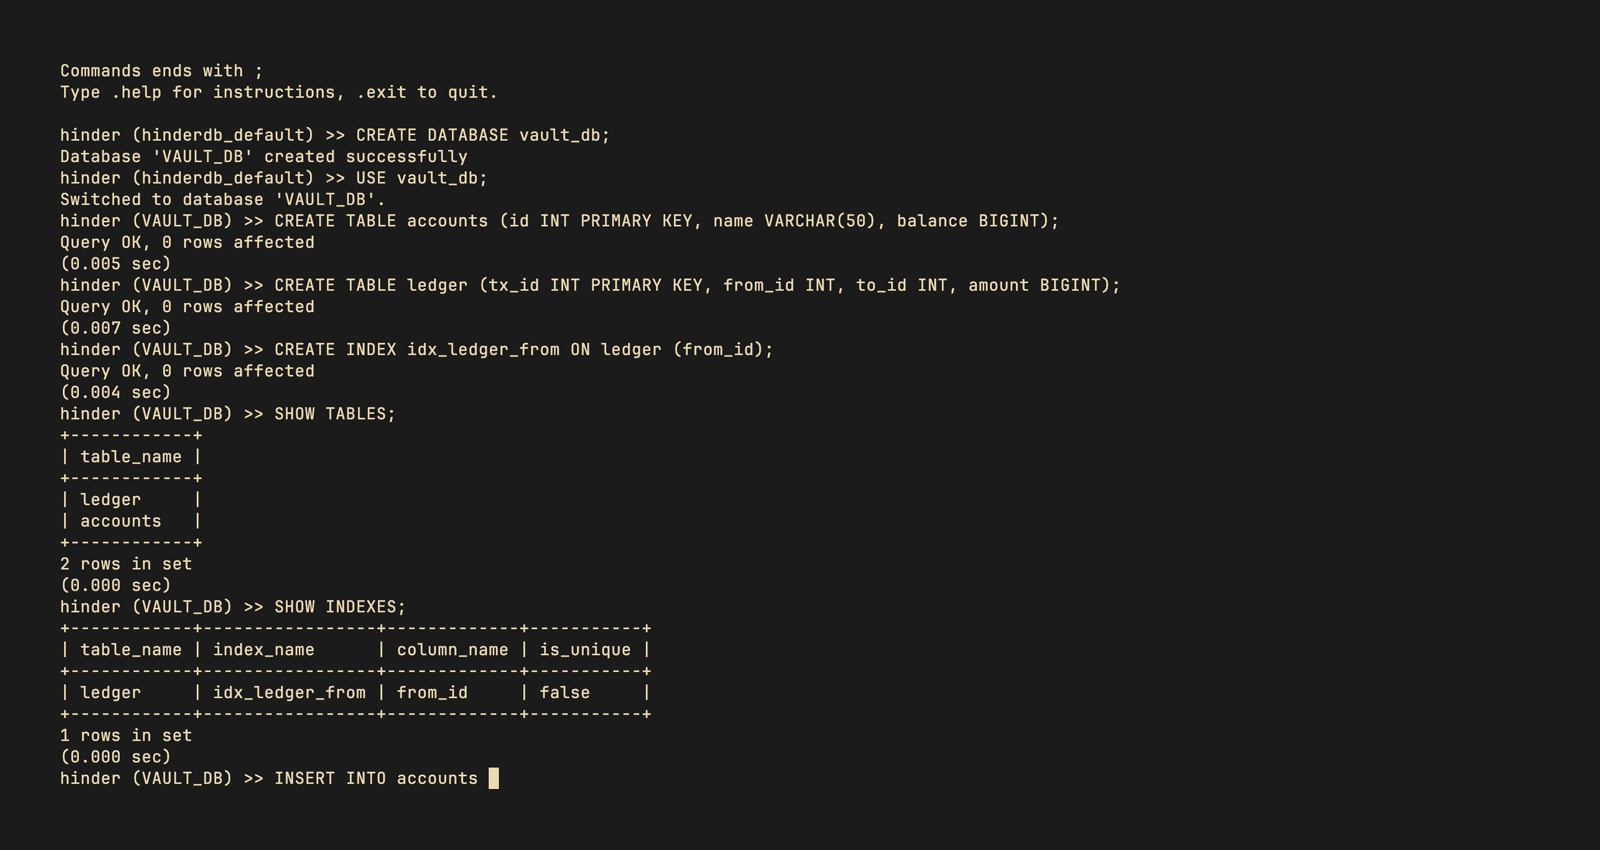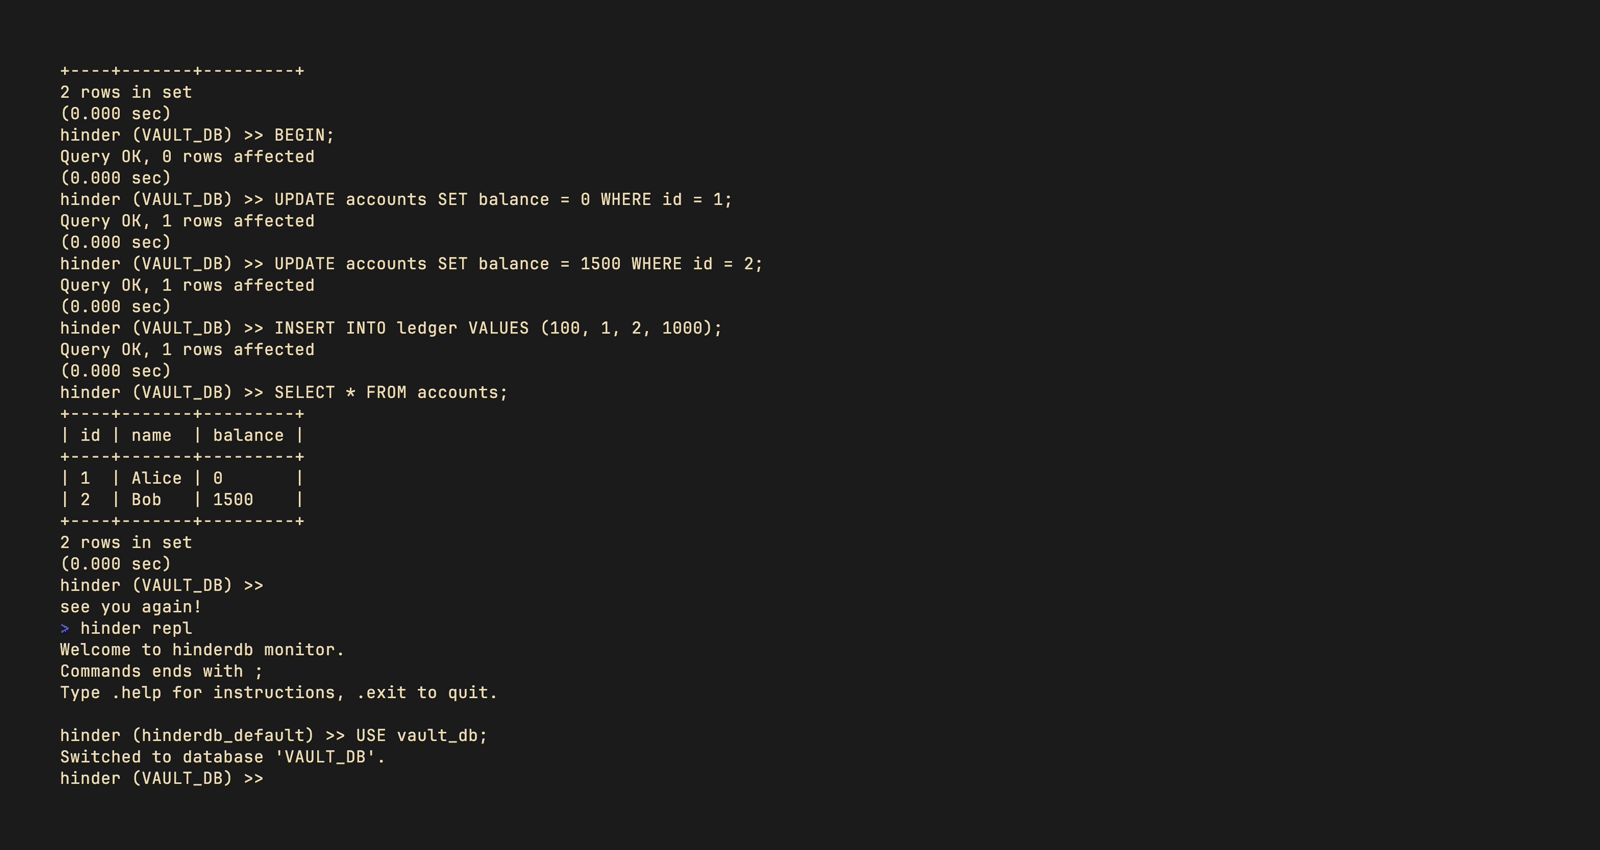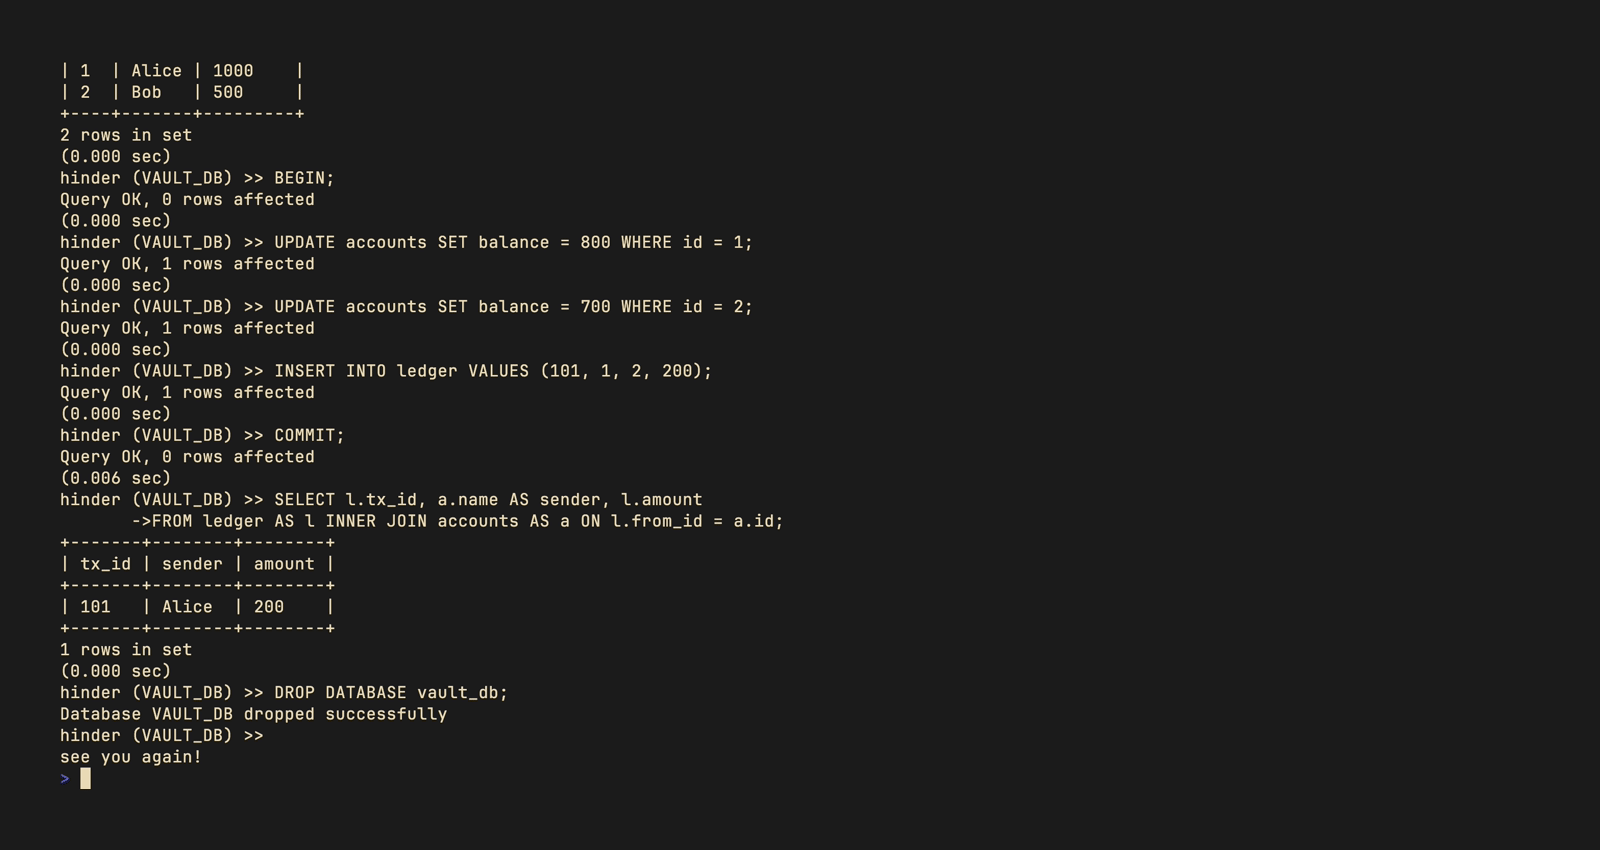
Transactions with ROLLBACK and COMMIT
A Small Behind The Scenes
So, if you were to create a table with: CREATE TABLE users (id INT, is_active BOOLEAN, account_balance BIGINT, username VARCHAR(40));
You could insert records like (only the data not the json, that's for the web app to add):
{
  "id": 42,                // 4 bytes
  "is_active": true,       // 1 byte
  "account_balance": 1500, // 8 bytes
  "username": "Alice"      // 9 bytes (4 for length + 5 for chars)
}
Add 4 bytes for null-indicators and 15 bytes for B-Tree routing overhead, and this entire row takes exactly 41 bytes on disk. We can add about 100 records (rows) like this in a single 8KiB leaf-page.
Internal nodes do not store anything beyond key-routing metadata, they only store 18 byte pointers: 8 byte key, 8 byte
PageId, and 2-byte slot space.
This means a single 8KiB internal page can hold about ~450 pointers, meaning:
Level-1 (RootNode): Stores about 450 pointers.
Level-2 (Internal): Stores about 450 * 450 = 202,500 pointers.
Level-3 (Internal): Stores about 202,500 * 450 = 91,125,000 pointers.
Level-4 (Leaf): Stores about 91,125,000 pages × 100 rows = 9.1 Billion Records.
So, to find a specific user out of 9 billion, the database only traverses 4 levels. Because the Root and Level 2 pages are almost always hot in the Buffer Pool's cache, a primary key lookup for 1 in 9 billion rows requires only 1 or 2 physical disk reads.
Furthermore because the leaf pages utilize binary search, and the structure is a B+Tree, an index lookup takes about 40-60 microseconds on a 500,000 row dataset. Not too bad for a project database.
Why I Built This
So, about a year ago I was learning a lot of new things, and then building them by learning from their open source equivalent codebases. Projects such as different types of caching, WAL, Interpreter, Compiler, etc. At the same time I started reading Designing Data Intensive Applications and that just made me want to learn more and more about databases and how they work, how they are built, etc; plus it seemed like the perfect concoction of everything I've been doing so far.
So I decided I'll look into it, learn more about them, and attempt to build one, and after giving up on 2 half-finished attempts, I finally sat down and built one from scratch without using a single dependency for the db stuff. And most importantly because it was always fun learning and attempting to write the database.
I also wanted other students like me, who are interested in learning more about databases, to have a good code reference when they are learning from sources like the book Database Internals, or lectures from CMU 15-445/645 Intro to Database Systems.
Brief Look at the Architecture
I built HinderDb accounting for High ROI, meaning I've chosen to stick with the actual architectural patterns for most of the things, however they have been relatively simplified so I don't lose my sanity while writing this project. An example of that would be: instead of using HashJoins which is the fastest method of handling joins (production databases do this), I've chosen Block Nested Loop Joins, which is the second fastest method of handling Joins (production databases do this too), but, it's all in-memory, an actual database would spill to disk if things go out of hand while running Joins, we don't (what is this? a real database?).
So these are the kinds of simplifications we are working with. Below you can see some brief architectural decisions, for a more detailed account, read Architecture.md(Will take some time writing this. After I'm finished with my prep most likely.):
Execution Engine (Volcano Iterator Model)
- Zero Allocation Scans: Iterators write raw bytes directly into a reusable
&mut Vec<u8>block_buffer to avoid heap allocation in the hot loop. - B+Tree Iterator: The lowest level iterator that fetches the tuples by asking for it from the buffer pool. Depending on whether the query is indexed or not, the iterator will initiate binary search for the lookup.
- Relational Algebra:
INNER JOIN,LEFT JOIN,WHEREfilters, and Projections (the select list). - Sorting & Pagination:
ORDER BY,LIMIT, andOFFSET. - Aggregations: In-memory Hash Aggregation for
GROUP BY,COUNT, andAVG.
Storage & Memory
- Slotted Pages: Fixed 8KiB pages. The slot-array and data grows inwards to prevent fragmentation.
- Buffer Pool: Arena-backed Lru eviction. This isolates disk I/O and caching from database logic.
- Index-Organized Tables: All tables are clustered by a monotonic
u64row_id. If you define a PRIMARY KEY, it acts as the alias to this internal ID at no extra cost. - Secondary Indexes: B+Trees that store arrays of primary row_ids for every secondary key like 'alice'. I used sign-bit flipping for the numeric types so that the B+Tree sorts them correctly; the strings are hashed.
Parser & Lexer
- Recursive Descent Parser: Wrote customer lexer and a LL(1) recursive descent parser to define custom syntax rules and provide exact syntax error messages.
- Single-Pass Planning: The parsed Ast is fed directly into the
Planner, which performs semantic validation, type-checking, and physical routing (Index vs. Seq Scan) in a single pass, outputting a ready-to-run Volcano execution pipeline.
Transactions and Durability
- Write-Ahead Log (Wal): Uses STEAL/NO-FORCE style logging protocol, and per page undo/redo mechanism like SQLite on COMMIT/ROLLBACKS and also on crash recovery.
- O(1) Rollbacks: The Buffer Pool caches wal byte-offsets in-memory. A
ROLLBACKis just seeks to that offset and overwrite the page on disk without having to scan the entire log. - RAII Transactions:
BEGIN,COMMIT, ANDROLLBACKis tied to Rust'sDroptrait. If the database panics or drops unexpectedly, ongoing transactions are aborted immediately and changes are rolled-back if any.
Quick Start
⚠️ It might not work properly on windows tho, as I built it on my mac and windows could have permission issues for directory and stuff, and I don't have windows to test it. Create an issue or a pr if you encounter something.
You need the Rust toolchain installed. You can install HinderDb globally using cargo.
git clone https://github.com/pixelooz/hinder-db.git
cd hinder-db
cargo install --path .

# Start the REPL by running:
hinder repl # This should open the default database.

# If you don't want to install and just run from the directory.
cargo run --bin hinder repl
... >> .help # Shows db usage patterns.

# Create a new database.
... >> CREATE DATABASE my_database;
... >> USE my_database;
Then paste all the commands below into your shell at once, hinderdb can handle multiple commands at once. You can write one by one also if you want.
CREATE TABLE users (id INT PRIMARY KEY, name VARCHAR(50), reputation INT);
CREATE TABLE posts (post_id INT PRIMARY KEY, author_id INT, title VARCHAR(100));

CREATE INDEX idx_posts_author ON posts (author_id);

BEGIN;
INSERT INTO users
    VALUES (1, 'Alice', 500), (2, 'Bob', 120);
INSERT INTO posts
    VALUES (101, 1, 'Building a Database in Rust'), (102, 1, 'B+ Tree Mechanics');
COMMIT;

SELECT u.name, COUNT(p.post_id) AS total_posts
FROM users AS u
LEFT JOIN posts AS p ON u.id = p.author_id
GROUP BY u.name
ORDER BY total_posts DESC;
What's the Future?
HinderDb is something I intend to develop actively and keep adding new features as I learn them. I don't intend to over complicate the implementation ever, so I'll still stick to the High-ROI principle, but somethings by their very nature are complex, like adding mvcc, distributed nodes, etc. So when that happens, there should be different branches for those. I'm currently looking into the codebase of toy-db, some online documentation and lectures on YT to learn and eventually add those things into this database. Since I'm gonna be busy with revisions, dsa, and applications for the next couple of months there is no fixed timeline when these additions happen.
Current Roadmap (In no particular order)
- Concurrency Control: Table-Level Two-Phase Locking (2PL) via the
LockManagerto support multithreaded clients. - Garbage Collection: Equivalent of the
VACUUMcommand to reclaim disk space from logical tombstones and rewrite the entire page anew. - ARCHITECTURE.md: Write a markdown file to break down the architecture in detail.
Explorar proyectos relacionados
Asabeneh/30-Days-Of-Python
El reto de programación 30 Days of Python es una guía paso a paso para aprender el lenguaje de programación Python en 30 días. Este reto puede llevar más de 100 días. Sigue tu propio ritmo. Estos vídeos también pueden ayudarte: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,673 estrellasgrafana/grafana
Plataforma abierta y componible de observabilidad y visualización de datos. Visualiza métricas, registros y trazas de múltiples fuentes, como Prometheus, Loki, Elasticsearch, InfluxDB, Postgres y muchas más.
77,876 estrellasredis/redis
Para los desarrolladores que crean aplicaciones en tiempo real basadas en datos, Redis es la opción preferida, la más rápida y la de más funciones como caché, servidor de estructuras de datos y motor de consultas de documentos y vectores.
77,485 estrellasapache/superset
Apache Superset es una plataforma de visualización y exploración de datos.
75,509 estrellas