
karpathy/micrograd
karpathy/micrograd has 18,765 GitHub stars and 2,992 forks. GitHot measured +25 stars in 24 hours. Last checked 2026-11-08 18:44 UTC. Last push 2026-08-03.
Un pequeño motor de diferenciación automática para valores escalares y una biblioteca de redes neuronales basada en él, con una API similar a la de PyTorch.
Crecimiento de estrellas medido
- in 24h
- +25
- in 7 days
- Actualización retrasada
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
Originalmicrograd
A tiny Autograd engine (with a bite! :)). Implements backpropagation (reverse-mode autodiff) over a dynamically built DAG and a small neural networks library on top of it with a PyTorch-like API. Both are tiny, with about 100 and 50 lines of code respectively. The DAG only operates over scalar values, so e.g. we chop up each neuron into all of its individual tiny adds and multiplies. However, this is enough to build up entire deep neural nets doing binary classification, as the demo notebook shows. Potentially useful for educational purposes.
Installation
pip install micrograd
Example usage
Below is a slightly contrived example showing a number of possible supported operations:
from micrograd.engine import Value

a = Value(-4.0)
b = Value(2.0)
c = a + b
d = a * b + b**3
c += c + 1
c += 1 + c + (-a)
d += d * 2 + (b + a).relu()
d += 3 * d + (b - a).relu()
e = c - d
f = e**2
g = f / 2.0
g += 10.0 / f
print(f'{g.data:.4f}') # prints 24.7041, the outcome of this forward pass
g.backward()
print(f'{a.grad:.4f}') # prints 138.8338, i.e. the numerical value of dg/da
print(f'{b.grad:.4f}') # prints 645.5773, i.e. the numerical value of dg/db
Training a neural net
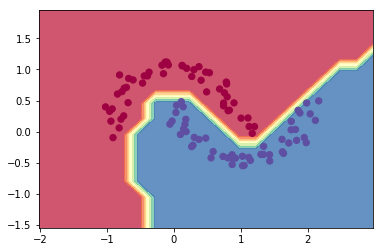
The notebook demo.ipynb provides a full demo of training an 2-layer neural network (MLP) binary classifier. This is achieved by initializing a neural net from micrograd.nn module, implementing a simple svm "max-margin" binary classification loss and using SGD for optimization. As shown in the notebook, using a 2-layer neural net with two 16-node hidden layers we achieve the following decision boundary on the moon dataset:
Training a GPT
For a more advanced example, see microgpt, which trains and samples from a full GPT-2-like transformer in pure, dependency-free Python. It builds on a more efficient and better version of the autograd engine here (storing local gradients at forward time instead of per-op backward closures), and is the complete algorithm in a single file — everything else is just efficiency. See also the accompanying explainer post for a detailed walkthrough.
Tracing / visualization
For added convenience, the notebook trace_graph.ipynb produces graphviz visualizations. E.g. this one below is of a simple 2D neuron, arrived at by calling draw_dot on the code below, and it shows both the data (left number in each node) and the gradient (right number in each node).
from micrograd import nn
n = nn.Neuron(2)
x = [Value(1.0), Value(-2.0)]
y = n(x)
dot = draw_dot(y)

Running tests
To run the unit tests you will have to install PyTorch, which the tests use as a reference for verifying the correctness of the calculated gradients. Then simply:
python -m pytest
License
MIT
Explorar proyectos relacionados
tensorflow/tensorflow
Un framework de código abierto de aprendizaje automático para todos
201,400 estrellashuggingface/transformers
🤗 Transformers: el framework de definición de modelos para modelos de aprendizaje automático de vanguardia en texto, visión, audio y multimodal, tanto para inferencia como para entrenamiento.
168,668 estrellasAUTOMATIC1111/stable-diffusion-webui
Interfaz web de Stable Diffusion
165,261 estrellasComfy-Org/ComfyUI
La GUI, la API y el backend más potentes y modulares para modelos de difusión, con una interfaz de grafos y nodos. El motor de inferencia local más rápido del mundo.
145,835 estrellas