
junxiaosong/AlphaZero_Gomoku
junxiaosong/AlphaZero_Gomoku has 3,640 GitHub stars and 1,017 forks. GitHot measured +2 in 7 days. Last checked 2026-11-16 00:18 UTC. Last push 2024-04-24.
Crecimiento de estrellas medido
- in 24h
- Actualización retrasada
- in 7 days
- +2
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
An implementation of the AlphaZero algorithm for Gomoku (also called Gobang or Five in a Row)
Aprendizaje automáticoREADME.md
OriginalAlphaZero-Gomoku
This is an implementation of the AlphaZero algorithm for playing the simple board game Gomoku (also called Gobang or Five in a Row) from pure self-play training. The game Gomoku is much simpler than Go or chess, so that we can focus on the training scheme of AlphaZero and obtain a pretty good AI model on a single PC in a few hours.
References:
- AlphaZero: Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm
- AlphaGo Zero: Mastering the game of Go without human knowledge
Update 2018.2.24: supports training with TensorFlow!
Update 2018.1.17: supports training with PyTorch!
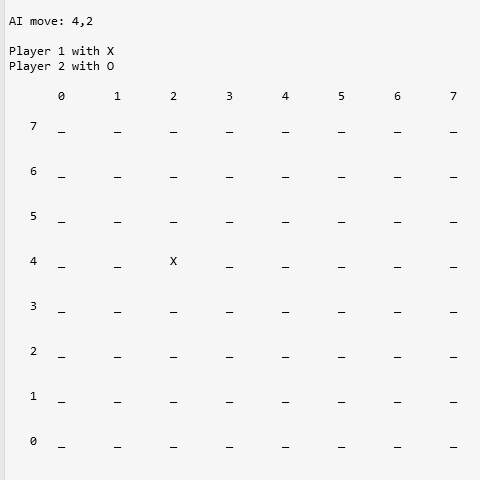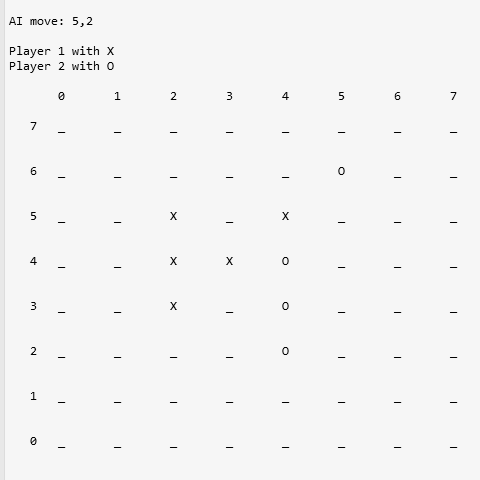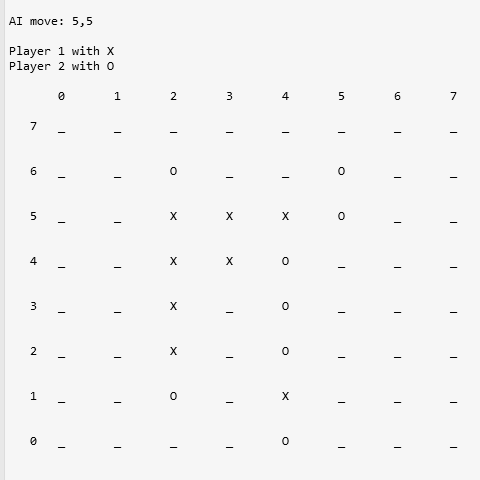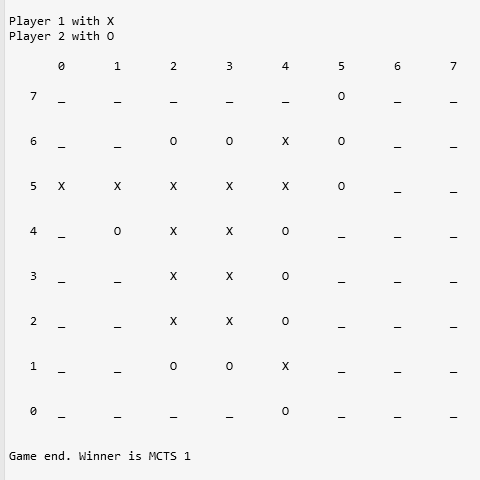
Example Games Between Trained Models
- Each move with 400 MCTS playouts:
Requirements
To play with the trained AI models, only need:
- Python >= 2.7
- Numpy >= 1.11
To train the AI model from scratch, further need, either:
- Theano >= 0.7 and Lasagne >= 0.1
or - PyTorch >= 0.2.0
or - TensorFlow
PS: if your Theano's version > 0.7, please follow this issue to install Lasagne,
otherwise, force pip to downgrade Theano to 0.7 pip install --upgrade theano==0.7.0
If you would like to train the model using other DL frameworks, you only need to rewrite policy_value_net.py.
Getting Started
To play with provided models, run the following script from the directory:
python human_play.py
You may modify human_play.py to try different provided models or the pure MCTS.
To train the AI model from scratch, with Theano and Lasagne, directly run:
python train.py
With PyTorch or TensorFlow, first modify the file train.py, i.e., comment the line
from policy_value_net import PolicyValueNet # Theano and Lasagne
and uncomment the line
# from policy_value_net_pytorch import PolicyValueNet  # Pytorch
or
# from policy_value_net_tensorflow import PolicyValueNet # Tensorflow
and then execute: python train.py (To use GPU in PyTorch, set use_gpu=True and use return loss.item(), entropy.item() in function train_step in policy_value_net_pytorch.py if your pytorch version is greater than 0.5)
The models (best_policy.model and current_policy.model) will be saved every a few updates (default 50).
Note: the 4 provided models were trained using Theano/Lasagne, to use them with PyTorch, please refer to issue 5.
Tips for training:
- It is good to start with a 6 * 6 board and 4 in a row. For this case, we may obtain a reasonably good model within 500~1000 self-play games in about 2 hours.
- For the case of 8 * 8 board and 5 in a row, it may need 2000~3000 self-play games to get a good model, and it may take about 2 days on a single PC.
Further reading
My article describing some details about the implementation in Chinese: https://zhuanlan.zhihu.com/p/32089487