
chaofengc/FeMaSR
chaofengc/FeMaSR has 244 GitHub stars and 16 forks. GitHot measured 0 stars in 24 hours. Last checked 2026-11-20 21:31 UTC. Last push 2023-10-18.
Crecimiento de estrellas medido
- in 24h
- 0
- in 7 days
- Recopilando historial
- in 15 days
- Recopilando historial
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
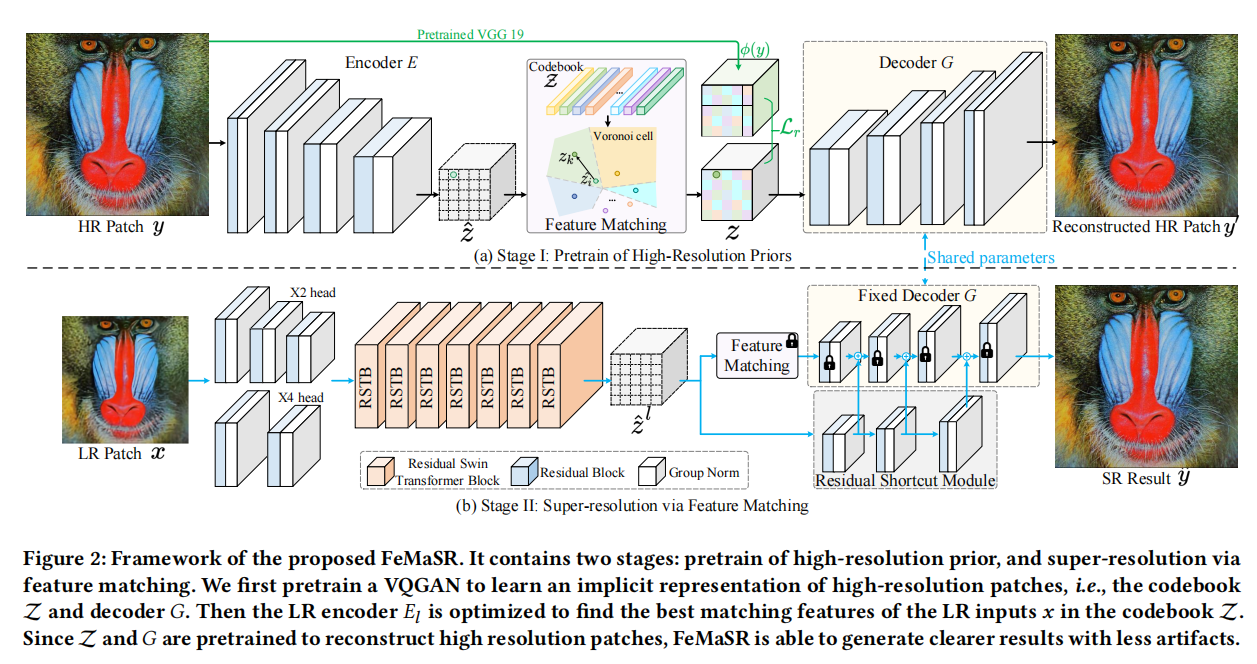
PyTorch codes for "Real-World Blind Super-Resolution via Feature Matching with Implicit High-Resolution Priors", ACM MM2022 (Oral)
Aprendizaje automáticoREADME.md
OriginalFeMaSR
This is the official PyTorch codes for the paper
Real-World Blind Super-Resolution via Feature Matching with Implicit High-Resolution Priors (MM22 Oral)
Chaofeng Chen*, Xinyu Shi*, Yipeng Qin, Xiaoming Li, Xiaoguang Han, Tao Yang, Shihui Guo
(* indicates equal contribution)


Update
- 2022.10.10 Release reproduce training log for SR stage in
LPIPS: 0.329 @415kfor div2k (x4). - 2022.09.26 Add example training log with 70k iterations
- 2022.09.23 Add colab demo
- 2022.07.02
- Update codes of the new version FeMaSR
- Please find the old QuanTexSR in thequantexsrbranch
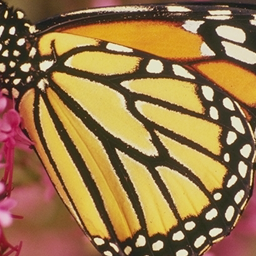
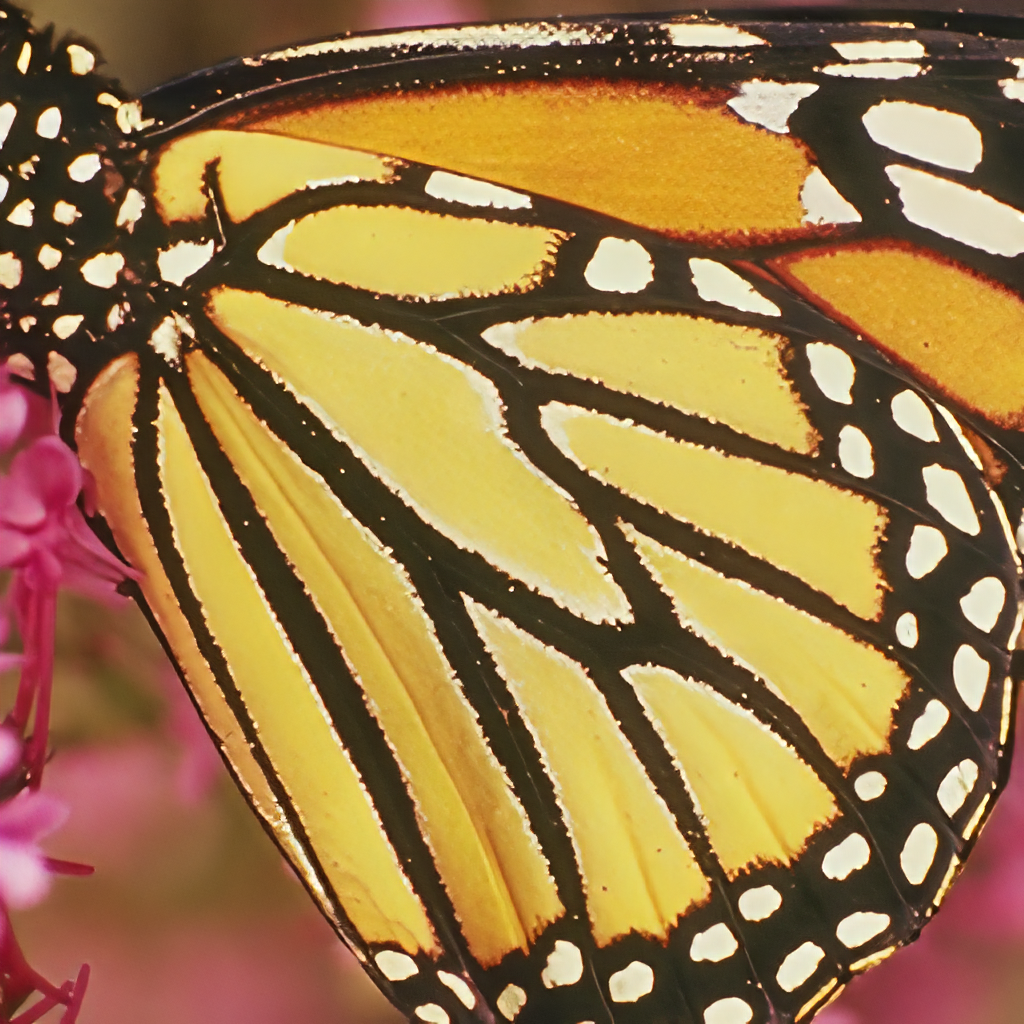
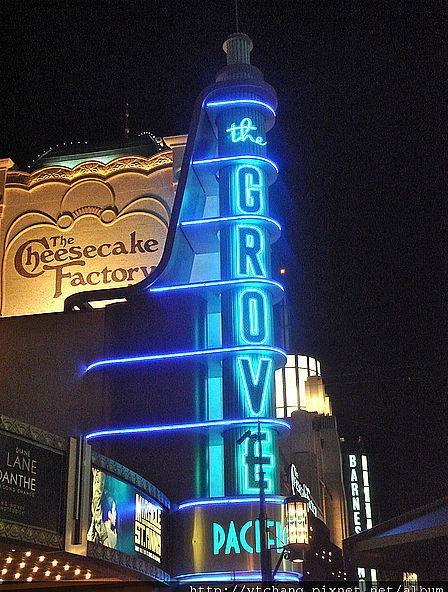
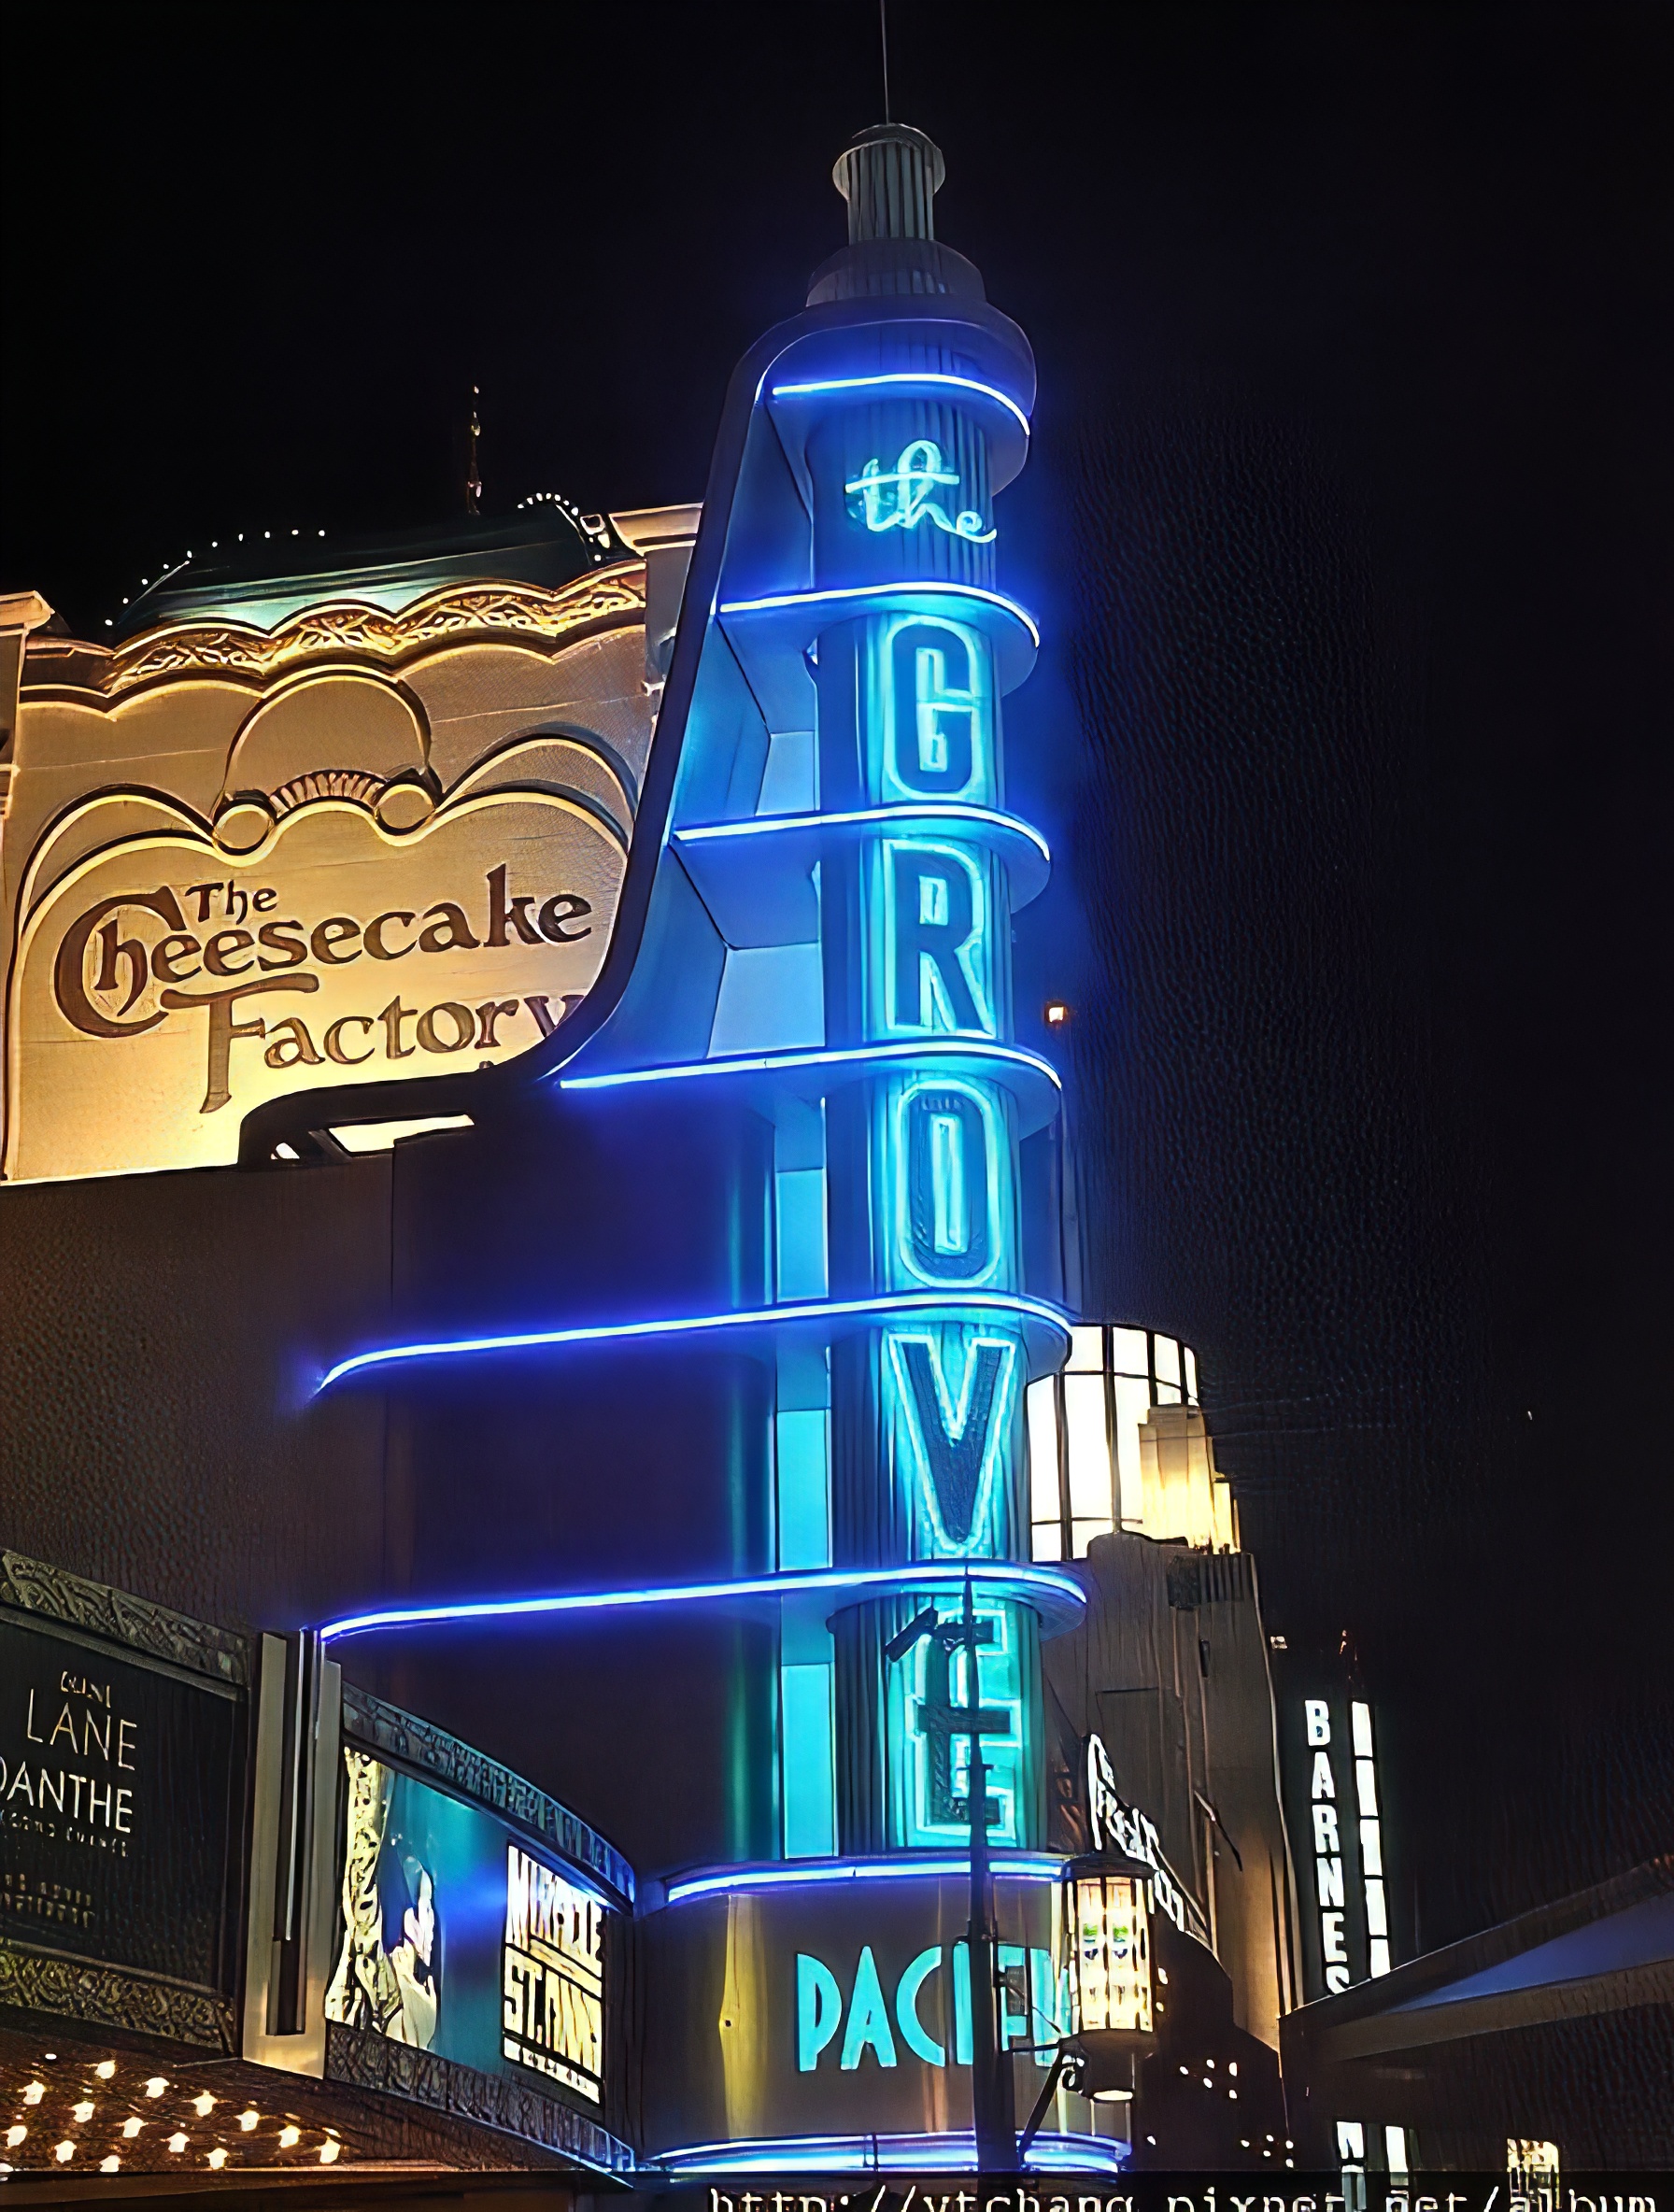
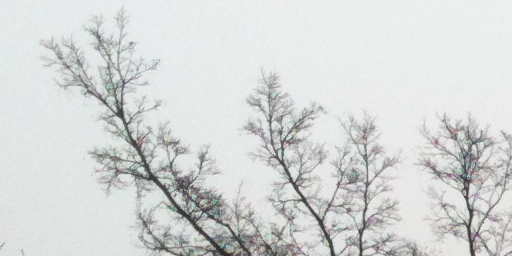
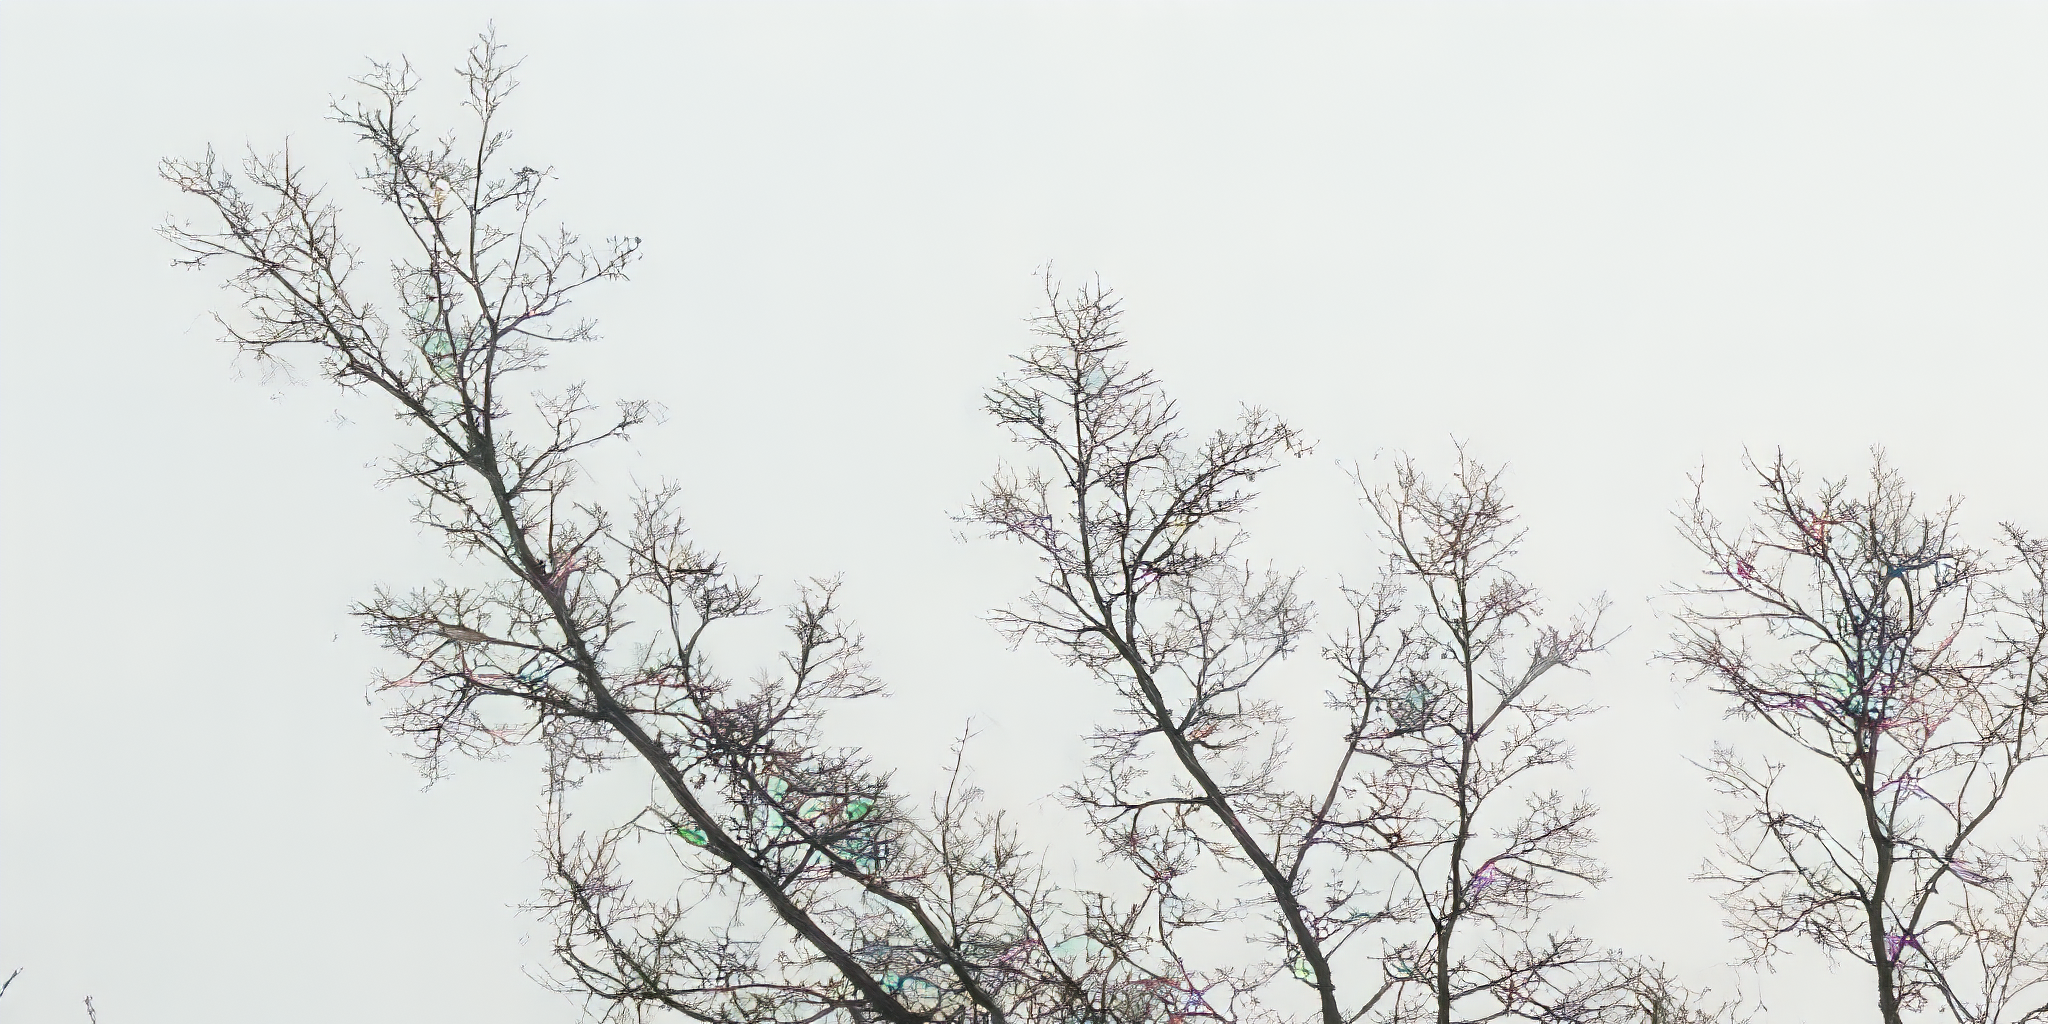
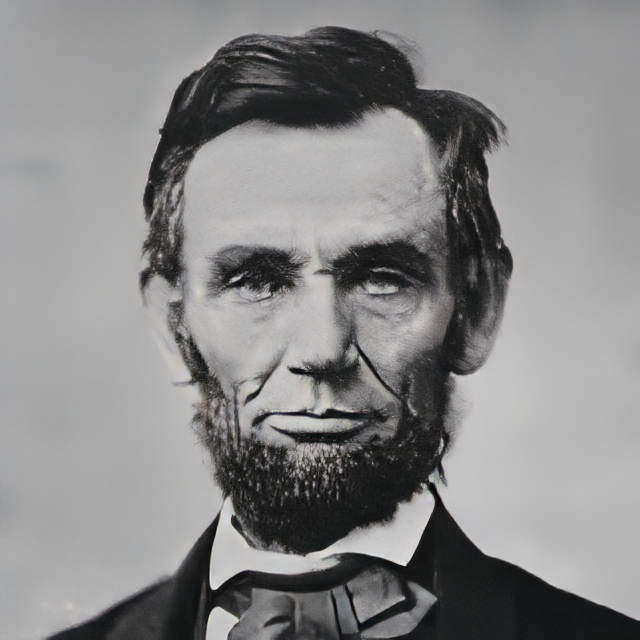
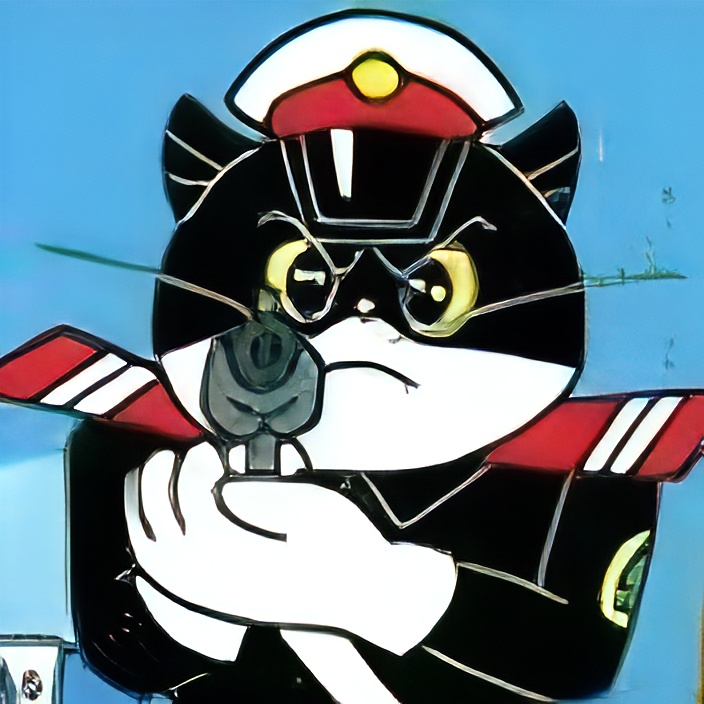
Here are some example results on test images from BSRGAN and RealESRGAN.
Left: real images | Right: super-resolved images with scale factor 4
Dependencies and Installation
- Ubuntu >= 18.04
- CUDA >= 11.0
- Other required packages in
requirements.txt
# git clone this repository
git clone https://github.com/chaofengc/FeMaSR.git
cd FeMaSR

# create new anaconda env
conda create -n femasr python=3.8
source activate femasr

# install python dependencies
pip3 install -r requirements.txt
python setup.py develop
Quick Inference
python inference_femasr.py -s 4 -i ./testset -o results_x4/
python inference_femasr.py -s 2 -i ./testset -o results_x2/
Train the model
Preparation
Dataset
Please prepare the training and testing data follow descriptions in the main paper and supplementary material. In brief, you need to crop 512 x 512 high resolution patches, and generate the low resolution patches with degradation_bsrgan function provided by BSRGAN. While the synthetic testing LR images are generated by the degradation_bsrgan_plus function for fair comparison.
Model preparation
Before training, you need to
- Download the pretrained HRP model: generator, discriminator
- Put the pretrained models in
experiments/pretrained_models - Specify their path in the corresponding option file.
Train SR model
python basicsr/train.py -opt options/train_FeMaSR_LQ_stage.yml
Model pretrain
In case you want to pretrain your own HRP model, we also provide the training option file:
python basicsr/train.py -opt options/train_FeMaSR_HQ_pretrain_stage.yml
Citation
@inproceedings{chen2022femasr,
      author={Chaofeng Chen and Xinyu Shi and Yipeng Qin and Xiaoming Li and Xiaoguang Han and Tao Yang and Shihui Guo},
      title={Real-World Blind Super-Resolution via Feature Matching with Implicit High-Resolution Priors},
      year={2022},
      Journal = {ACM International Conference on Multimedia},
}
License

This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
Acknowledgement
This project is based on BasicSR.