
airscholar/e2e-data-engineering
airscholar/e2e-data-engineering has 371 GitHub stars and 159 forks. GitHot measured +1 stars in 24 hours and +1 in 7 days. Last checked 2026-11-09 16:59 UTC. Last push 2025-02-14.
An end-to-end data engineering pipeline that orchestrates data ingestion, processing, and storage using Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. All components are containerized with Docker for easy deployment and scalability.
Crecimiento de estrellas medido
- in 24h
- +1
- in 7 days
- +1
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
OriginalRealtime Data Streaming | End-to-End Data Engineering Project
Table of Contents
- Introduction
- System Architecture
- What You'll Learn
- Technologies
- Getting Started
- Watch the Video Tutorial
Introduction
This project serves as a comprehensive guide to building an end-to-end data engineering pipeline. It covers each stage from data ingestion to processing and finally to storage, utilizing a robust tech stack that includes Apache Airflow, Python, Apache Kafka, Apache Zookeeper, Apache Spark, and Cassandra. Everything is containerized using Docker for ease of deployment and scalability.
System Architecture
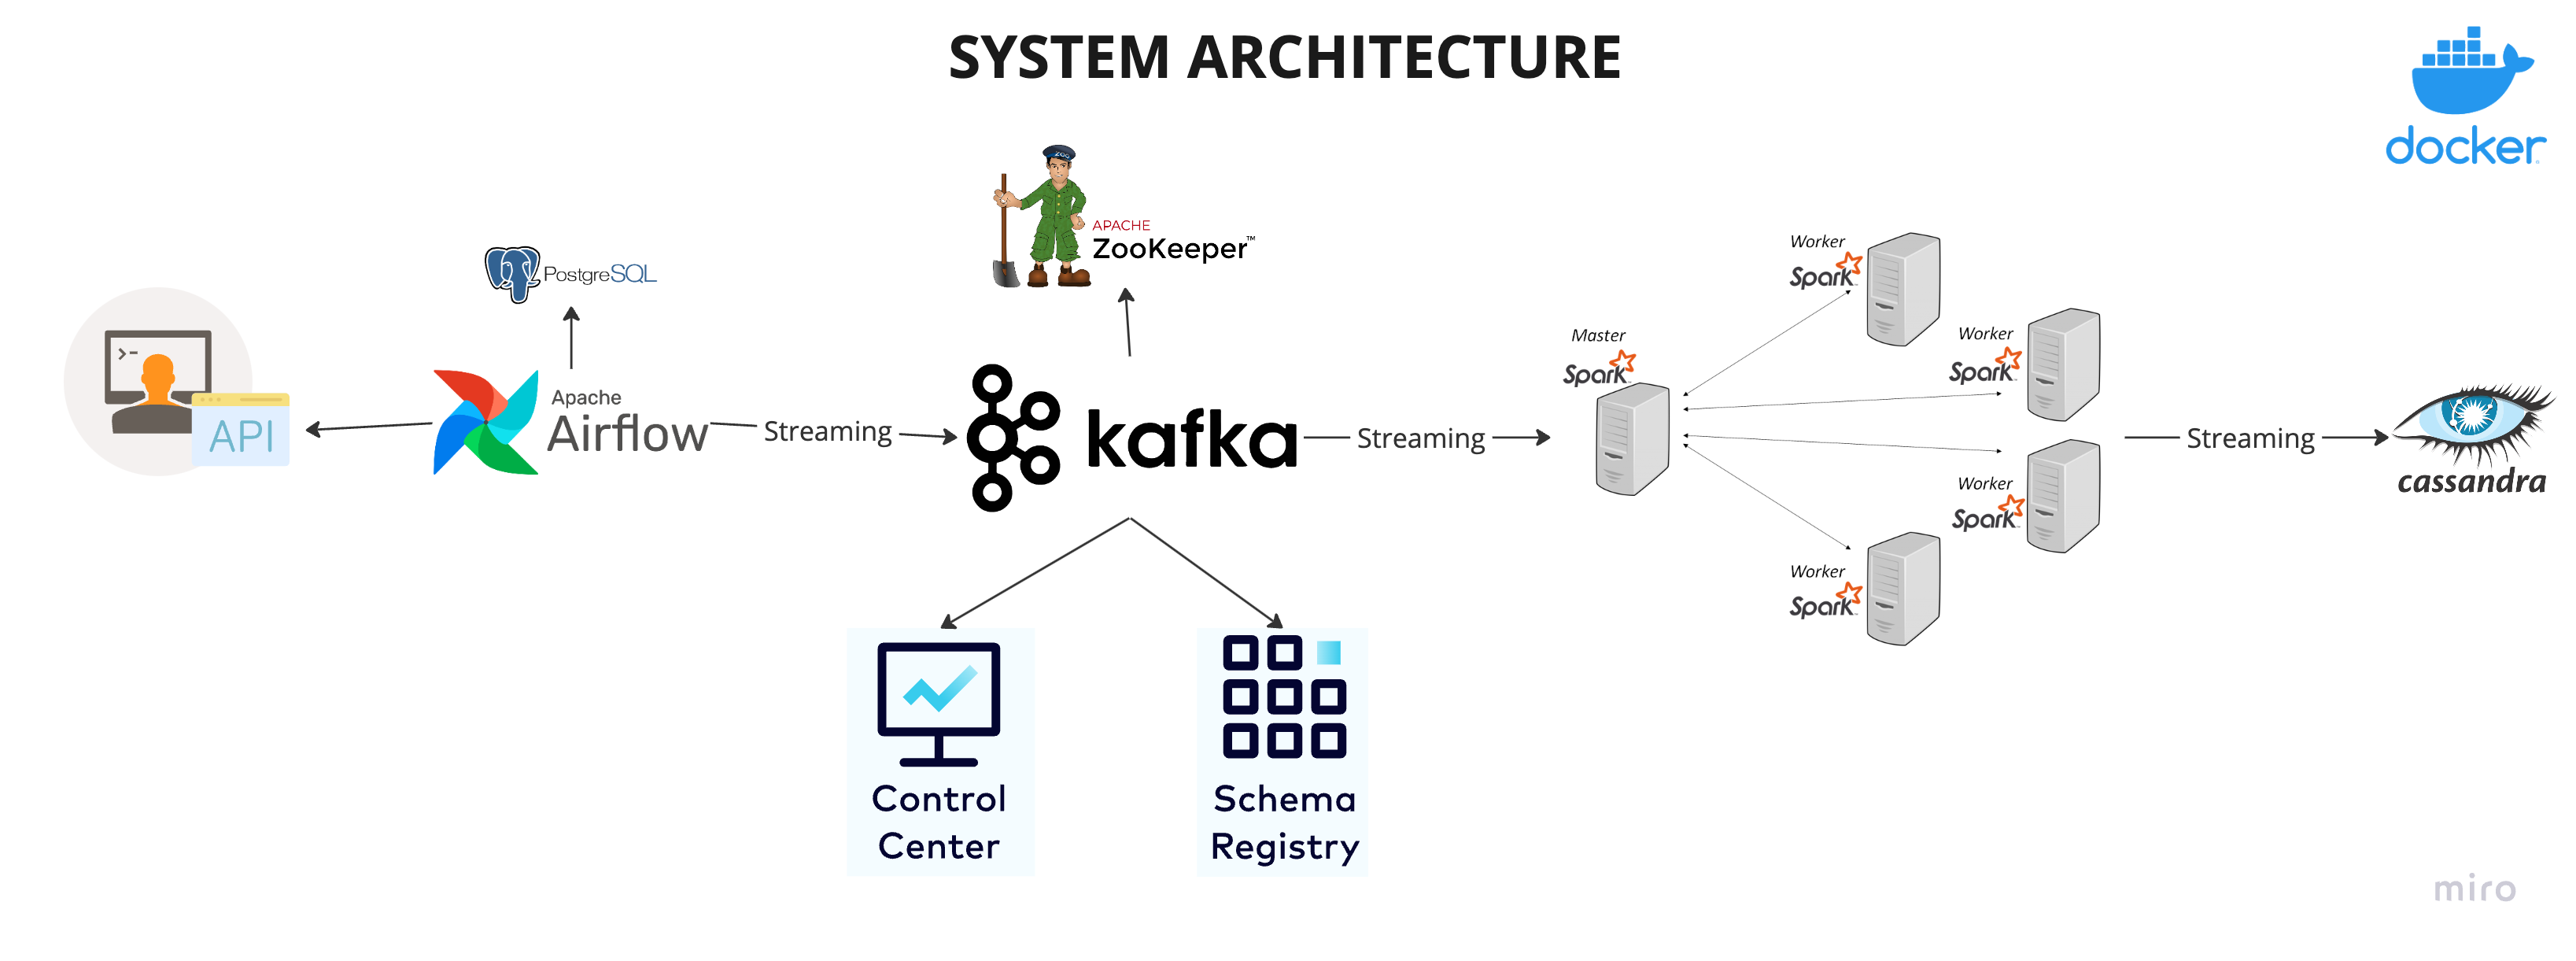
The project is designed with the following components:
- Data Source: We use
randomuser.meAPI to generate random user data for our pipeline. - Apache Airflow: Responsible for orchestrating the pipeline and storing fetched data in a PostgreSQL database.
- Apache Kafka and Zookeeper: Used for streaming data from PostgreSQL to the processing engine.
- Control Center and Schema Registry: Helps in monitoring and schema management of our Kafka streams.
- Apache Spark: For data processing with its master and worker nodes.
- Cassandra: Where the processed data will be stored.
What You'll Learn
- Setting up a data pipeline with Apache Airflow
- Real-time data streaming with Apache Kafka
- Distributed synchronization with Apache Zookeeper
- Data processing techniques with Apache Spark
- Data storage solutions with Cassandra and PostgreSQL
- Containerizing your entire data engineering setup with Docker
Technologies
- Apache Airflow
- Python
- Apache Kafka
- Apache Zookeeper
- Apache Spark
- Cassandra
- PostgreSQL
- Docker
Getting Started
Clone the repository:
git clone https://github.com/airscholar/e2e-data-engineering.gitNavigate to the project directory:
cd e2e-data-engineeringRun Docker Compose to spin up the services:
docker-compose up
For more detailed instructions, please check out the video tutorial linked below.
Watch the Video Tutorial
For a complete walkthrough and practical demonstration, check out our YouTube Video Tutorial.
Explorar proyectos relacionados
Asabeneh/30-Days-Of-Python
El reto de programación 30 Days of Python es una guía paso a paso para aprender el lenguaje de programación Python en 30 días. Este reto puede llevar más de 100 días. Sigue tu propio ritmo. Estos vídeos también pueden ayudarte: https://www.youtube.com/channel/UC7PNRuno1rzYPb1xLa4yktw
78,486 estrellasgrafana/grafana
Plataforma abierta y componible de observabilidad y visualización de datos. Visualiza métricas, registros y trazas de múltiples fuentes, como Prometheus, Loki, Elasticsearch, InfluxDB, Postgres y muchas más.
77,790 estrellasredis/redis
Para los desarrolladores que crean aplicaciones en tiempo real basadas en datos, Redis es la opción preferida, la más rápida y la de más funciones como caché, servidor de estructuras de datos y motor de consultas de documentos y vectores.
77,332 estrellasapache/superset
Apache Superset es una plataforma de visualización y exploración de datos.
75,455 estrellas