
a-r-j/CPDB
a-r-j/CPDB has 36 GitHub stars and 1 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and 0 in 15 days. Last checked 2026-11-22 01:05 UTC. Last push 2026-11-21.
Crecimiento de estrellas medido
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- 0
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
Cython implementation of PDB -> DataFrame parsing
Aprendizaje automáticoREADME.md
Original




CPDB
Cython implementation of PDB -> DataFrame parsing
See CHANGELOG.md for release history.
Performance
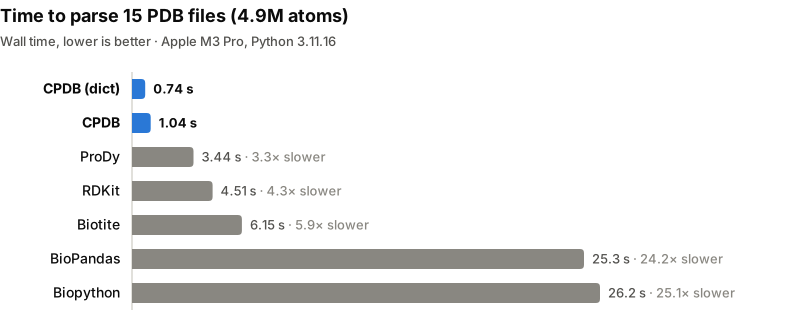
Reproduce with benchmark.ipynb, which also regenerates these charts.
Installation
From PyPI
pip install cpdb-protein
Development (with uv)
uv sync
This creates a virtual environment, installs the package in editable mode, and pulls in dev dependencies (tests, Jupyter).
Run tests:
uv run pytest tests/
Build a wheel:
uv build
CI
GitHub Actions runs tests on Python 3.10–3.13 and verifies package builds on every push to main and on pull requests. Pushing a tag matching v* (e.g. v0.2.2) publishes to PyPI via trusted publishing — configure a pypi environment and PyPI trusted publisher for a-r-j/CPDB before your first automated release.
Usage
The main entry point is parse() in cpdb. Provide one input source (fname, pdb_str, pdb_code, or uniprot_id); if more than one is given, later arguments override earlier ones.
from cpdb import parse

parse(
    fname=None,
    pdb_str=None,
    pdb_code=None,
    uniprot_id=None,
    df=True,
    af2_version=6,
)
| Argument | Type | Default | Description |
|---|---|---|---|
fname |
str, pathlib.Path, or os.PathLike |
None |
Path to a PDB file on disk. Plain .pdb files are parsed directly. Files ending in .pdb.gz or .ent.gz are decompressed with gzip before parsing. |
pdb_str |
str or list[str] |
None |
PDB contents as a single string or as a list of lines (e.g. from readlines()). Lists are joined before parsing. |
pdb_code |
str |
None |
Four-character PDB identifier (e.g. "3eiy"). The structure is downloaded from RCSB (files.rcsb.org) and then parsed. |
uniprot_id |
str |
None |
UniProt accession (e.g. "Q8W3K0"). The AlphaFold prediction is downloaded from AlphaFold DB and then parsed. |
df |
bool |
True |
If True, return a pandas.DataFrame. If False, return a dict mapping column names to numpy arrays. |
af2_version |
int |
6 |
AlphaFold DB model version used when uniprot_id is set (e.g. 6 for ...-model_v6.pdb). Ignored for other input modes. |
Returns: pandas.DataFrame when df=True, otherwise dict[str, numpy.ndarray] with keys such as record_name, atom_number, atom_name, residue_name, chain_id, x_coord, y_coord, z_coord, occupancy, b_factor, element_symbol, and model_idx.
Network fetches (pdb_code, uniprot_id) print an error message and may return empty results if the download fails.
To Dictionary
# To dictionary
from cpdb import parse

# From Disk
data = parse("path_to_pdb.pdb", df=False)
data = parse("path_to_pdb.pdb.gz", df=False)

# From str
with open("tests/test_data/1htq.pdb") as f:
    pdb_file = f.readlines()
data = parse(pdb_str=pdb_file, df=False)

# From PDB
data = parse(pdb_code="3eiy", df=False)

# From AF2
data = parse(uniprot_id="Q8W3K0", df=False)
{'record_name': array(['ATOM', 'ATOM', 'ATOM', ..., 'HETATM', 'HETATM', 'HETATM'],
      dtype=object), 'atom_number': array([   1,    2,    3, ..., 1773, 1774, 1775], dtype=int32), 'atom_name': array(['N', 'CA', 'C', ..., 'O', 'O', 'O'], dtype=object), 'alt_loc': array(['', '', '', ..., '', '', ''], dtype=object), 'residue_name': array(['GLY', 'GLY', 'GLY', ..., 'HOH', 'HOH', 'HOH'], dtype=object), 'chain_id': array(['A', 'A', 'A', ..., 'A', 'A', 'A'], dtype=object), 'residue_number': array([  30,   30,   30, ..., 2276, 2277, 2278], dtype=int32), 'insertion': array(['', '', '', ..., '', '', ''], dtype=object), 'x_coord': array([31.203, 32.02 , 33.358, ..., 44.665, 41.786, 38.498], dtype=float32), 'y_coord': array([26.31 , 27.046, 26.387, ..., 13.172, 10.059, 12.491], dtype=float32), 'z_coord': array([ 6.06 ,  5.069,  4.79 , ..., 18.445, 22.316, 15.004], dtype=float32), 'occupancy': array([0.5, 0.5, 0.5, ..., 1. , 1. , 1. ], dtype=float32), 'b_factor': array([26.27, 29.29, 30.21, ..., 24.67, 34.64, 41.14], dtype=float32), 'element_symbol': array(['N', 'C', 'C', ..., 'O', 'O', 'O'], dtype=object), 'charge': array(['', '', '', ..., '', '', ''], dtype=object), 'model_idx': array([1, 1, 1, ..., 1, 1, 1], dtype=int32)}
To Pandas DataFrame
from cpdb import parse

# From Disk
data = parse("path_to_pdb.pdb", df=True)
data = parse("path_to_pdb.pdb.gz", df=True)

# From str
with open("tests/test_data/1htq.pdb") as f:
    pdb_file = f.readlines()
data = parse(pdb_str=pdb_file, df=True)

# From PDB
data = parse(pdb_code="3eiy", df=True)

# From AF2
data = parse(uniprot_id="Q8W3K0", df=True)
     record_name  atom_number atom_name alt_loc residue_name chain_id  residue_number insertion    x_coord    y_coord    z_coord  occupancy   b_factor element_symbol charge  model_idx
0           ATOM            1         N                  GLY        A              30            31.202999  26.309999   6.060000       0.50  26.270000              N                 1
1           ATOM            2        CA                  GLY        A              30            32.020000  27.046000   5.069000       0.50  29.290001              C                 1
2           ATOM            3         C                  GLY        A              30            33.358002  26.386999   4.790000       0.50  30.209999              C                 1
3           ATOM            4         O                  GLY        A              30            33.810001  25.535999   5.552000       0.50  29.299999              O                 1
4           ATOM            5         N                  GLY        A              31            33.987000  26.789000   3.684000       0.50  31.889999              N                 1
...          ...          ...       ...     ...          ...      ...             ...       ...        ...        ...        ...        ...        ...            ...    ...        ...
1769      HETATM         1771         O                  HOH        A            2274            42.688999  61.925999  29.589001       1.00  39.950001              O                 1
1770      HETATM         1772         O                  HOH        A            2275            32.055000  62.648998  30.961000       0.66  15.680000              O                 1
1771      HETATM         1773         O                  HOH        A            2276            44.665001  13.172000  18.445000       1.00  24.670000              O                 1
1772      HETATM         1774         O                  HOH        A            2277            41.785999  10.059000  22.316000       1.00  34.639999              O                 1
1773      HETATM         1775         O                  HOH        A            2278            38.498001  12.491000  15.004000       1.00  41.139999              O                 1
Explorar proyectos relacionados
Cargando…