
Zehaos/MobileNet
Zehaos/MobileNet has 1,659 GitHub stars and 469 forks. GitHot measured 0 in 7 days. Last checked 2026-11-10 01:28 UTC. Last push 2017-11-06.
MobileNet build with Tensorflow
Crecimiento de estrellas medido
- in 24h
- Actualización retrasada
- in 7 days
- 0
- in 15 days
- Actualización retrasada
- in 1 month
- Actualización retrasada
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
README.md
OriginalMobileNet
A tensorflow implementation of Google's MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
The official implementation is avaliable at tensorflow/model.
The official implementation of object detection is now released, see tensorflow/model/object_detection.
News
YellowFin optimizer has been intergrated, but I have no gpu resources to train on imagenet with it. Call for training ~_~
Official implement click here
Base Module
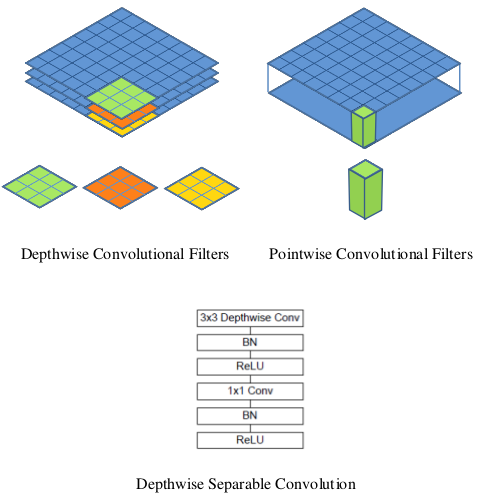
Accuracy on ImageNet-2012 Validation Set
| Model | Width Multiplier | Preprocessing | Accuracy-Top1 | Accuracy-Top5 |
|---|---|---|---|---|
| MobileNet | 1.0 | Same as Inception | 66.51% | 87.09% |
Download the pretrained weight: OneDrive, BaiduYun
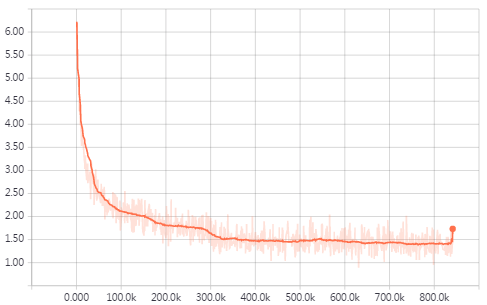
Loss
Time Benchmark
Environment: Ubuntu 16.04 LTS, Xeon E3-1231 v3, 4 Cores @ 3.40GHz, GTX1060.
TF 1.0.1(native pip install), TF 1.1.0(build from source, optimization flag '-mavx2')
| Device | Forward | Forward-Backward | Instruction set | Quantized | Fused-BN | Remark |
|---|---|---|---|---|---|---|
| CPU | 52ms | 503ms | - | - | - | TF 1.0.1 |
| CPU | 44ms | 177ms | - | - | On | TF 1.0.1 |
| CPU | 31ms | - | - | 8-bits | - | TF 1.0.1 |
| CPU | 26ms | 75ms | AVX2 | - | - | TF 1.1.0 |
| CPU | 128ms | - | AVX2 | 8-bits | - | TF 1.1.0 |
| CPU | 19ms | 89ms | AVX2 | - | On | TF 1.1.0 |
| GPU | 3ms | 16ms | - | - | - | TF 1.0.1, CUDA8.0, CUDNN5.1 |
| GPU | 3ms | 15ms | - | - | On | TF 1.0.1, CUDA8.0, CUDNN5.1 |
Image Size: (224, 224, 3), Batch Size: 1
Usage
Train on Imagenet
Prepare imagenet data. Please refer to Google's tutorial for training inception.
Modify './script/train_mobilenet_on_imagenet.sh' according to your environment.
bash ./script/train_mobilenet_on_imagenet.sh
Benchmark speed
python ./scripts/time_benchmark.py
Train MobileNet Detector (Debugging)
- Prepare KITTI data.
After download KITTI data, you need to split it data into train/val set.
cd /path/to/kitti_root
mkdir ImageSets
cd ./ImageSets
ls ../training/image_2/ | grep ".png" | sed s/.png// > trainval.txt
python ./tools/kitti_random_split_train_val.py
kitti_root floder then look like below
kitti_root/
                  |->training/
                  |     |-> image_2/00****.png
                  |     L-> label_2/00****.txt
                  |->testing/
                  |     L-> image_2/00****.png
                  L->ImageSets/
                        |-> trainval.txt
                        |-> train.txt
                        L-> val.txt
Then convert it into tfrecord.
python ./tools/tf_convert_data.py
- Mobify './script/train_mobilenet_on_kitti.sh' according to your environment.
bash ./script/train_mobilenetdet_on_kitti.sh
The code of this subject is largely based on SqueezeDet & SSD-Tensorflow. I would appreciated if you could feed back any bug.
Trouble Shooting
- About the MobileNet model size
According to the paper, MobileNet has 3.3 Million Parameters, which does not vary based on the input resolution. It means that the number of final model parameters should be larger than 3.3 Million, because of the fc layer.
When using RMSprop training strategy, the checkpoint file size should be almost 3 times as large as the model size, because of some auxiliary parameters used in RMSprop. You can use the inspect_checkpoint.py to figure it out.
- Slim multi-gpu performance problems
TODO
- Train on Imagenet
- Add Width Multiplier Hyperparameters
- Report training result
- Intergrate into object detection task(in progress)
Reference
MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
Explorar proyectos relacionados
tensorflow/tensorflow
Un framework de código abierto de aprendizaje automático para todos
201,427 estrellashuggingface/transformers
🤗 Transformers: el framework de definición de modelos para modelos de aprendizaje automático de vanguardia en texto, visión, audio y multimodal, tanto para inferencia como para entrenamiento.
168,711 estrellasAUTOMATIC1111/stable-diffusion-webui
Interfaz web de Stable Diffusion
165,289 estrellasComfy-Org/ComfyUI
La GUI, la API y el backend más potentes y modulares para modelos de difusión, con una interfaz de grafos y nodos. El motor de inferencia local más rápido del mundo.
146,271 estrellas