
MarcoForte/FBA_Matting
MarcoForte/FBA_Matting has 504 GitHub stars and 95 forks. GitHot measured 0 stars in 24 hours, 0 in 7 days, and +1 in 15 days. Last checked 2026-11-20 05:23 UTC. Last push 2023-06-22.
Crecimiento de estrellas medido
- in 24h
- 0
- in 7 days
- 0
- in 15 days
- +1
- in 1 month
- Recopilando historial
Cambios netos en períodos que se solapan, no totales diarios. Los datos no disponibles se dejan en blanco. Las estrellas indican interés, no calidad.
Acerca de
Official repository for the paper F, B, Alpha Matting
Aprendizaje automáticoREADME.md
OriginalFBA Matting 


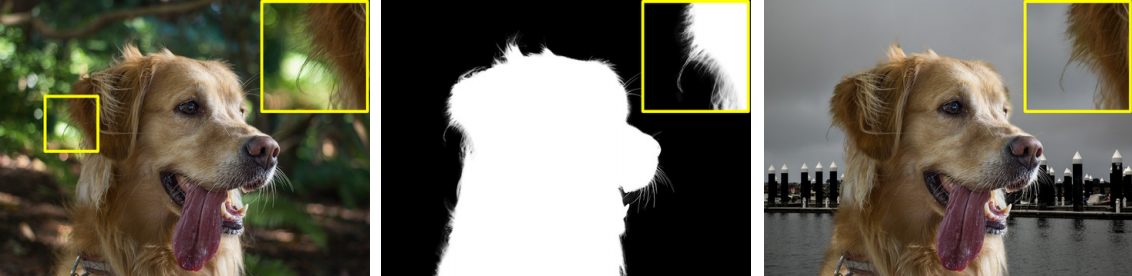
Official repository for the paper F, B, Alpha Matting. This paper and project is under heavy revision for peer reviewed publication, and so I will not be able to release the training code yet.
Marco Forte1, François Pitié1
1 Trinity College Dublin
Requirements
GPU memory >= 11GB for inference on Adobe Composition-1K testing set, more generally for resolutions above 1920x1080.
Packages:
- torch >= 1.4
- numpy
- opencv-python
Additional Packages for jupyter notebook
- matplotlib
- gdown (to download model inside notebook)
Models
These models have been trained on Adobe Image Matting Dataset. They are covered by the Adobe Deep Image Mattng Dataset License Agreement so they can only be used and distributed for noncommercial purposes.
More results of this model avialiable on the alphamatting.com, the videomatting.com benchmark, and the supplementary materials PDF.
| Model Name | File Size | SAD | MSE | Grad | Conn |
|---|---|---|---|---|---|
| FBA Table. 4 | 139mb | 26.4 | 5.4 | 10.6 | 21.5 |
Prediction
We provide a script demo.py and jupyter notebook which both give the foreground, background and alpha predictions of our model. The test time augmentation code will be made availiable soon.
In the torchscript notebook we show how to convert the model to torchscript.
In this video I demonstrate how to create a trimap in Pinta/Paint.NET.
Training
Training code is not released at this time. It may be released upon acceptance of the paper. Here are the key takeaways from our work with regards training.
- Use a batch-size of 1, and use Group Normalisation and Weight Standardisation in your network.
- Train with clipping of the alpha instead of sigmoid.
- The L1 alpha, compositional loss and laplacian loss are beneficial. Gradient loss is not needed.
- For foreground prediction, we extend the foreground to the entire image and define the loss on the entire image or at least the unknown region. We found this better than solely where alpha>0. Code for foreground extension
Citation
@article{forte2020fbamatting,
  title   = {F, B, Alpha Matting},
  author  = {Marco Forte and François Pitié},
  journal = {CoRR},
  volume  = {abs/2003.07711},
  year    = {2020},
}